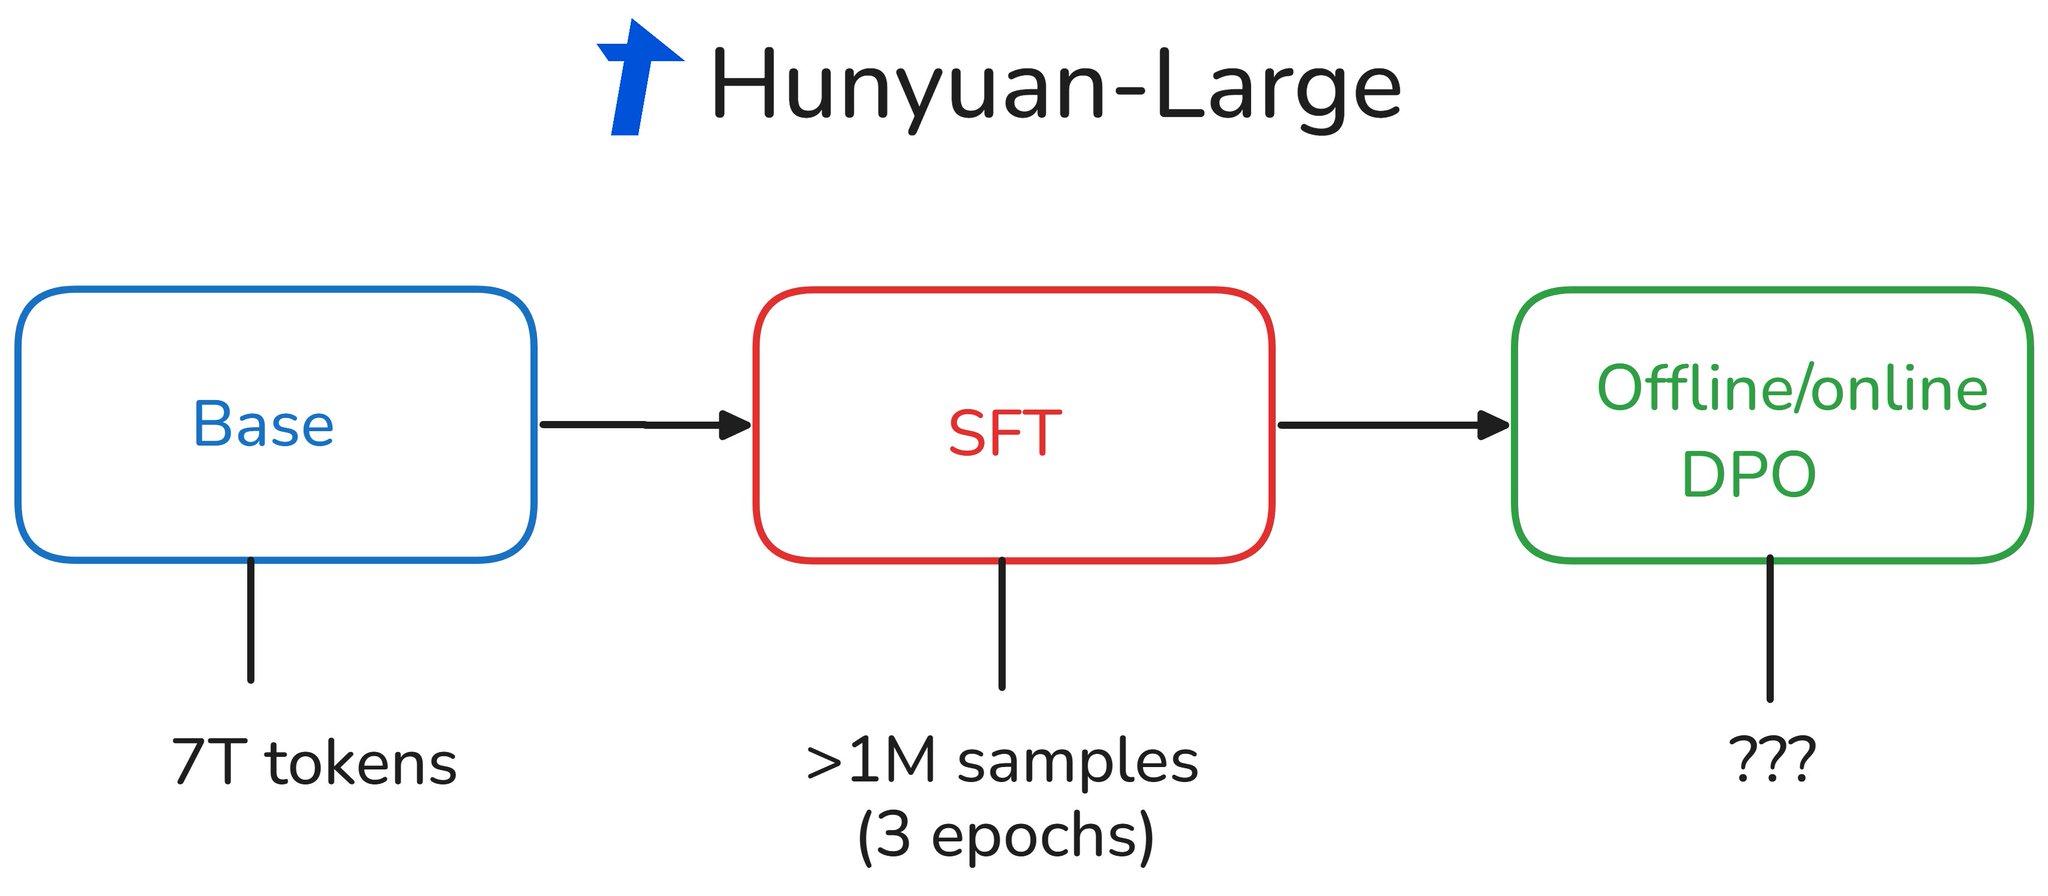
Interestingly, Hunyuan-Large follows a traditional post-training pipeline with SFT and DPO. SFT data is sourced from public sources and evolved to increase complexity Data quality is ensured through 3 stages: rules → 70B critique model → human review If I understood
MACHINE LEARNING
-
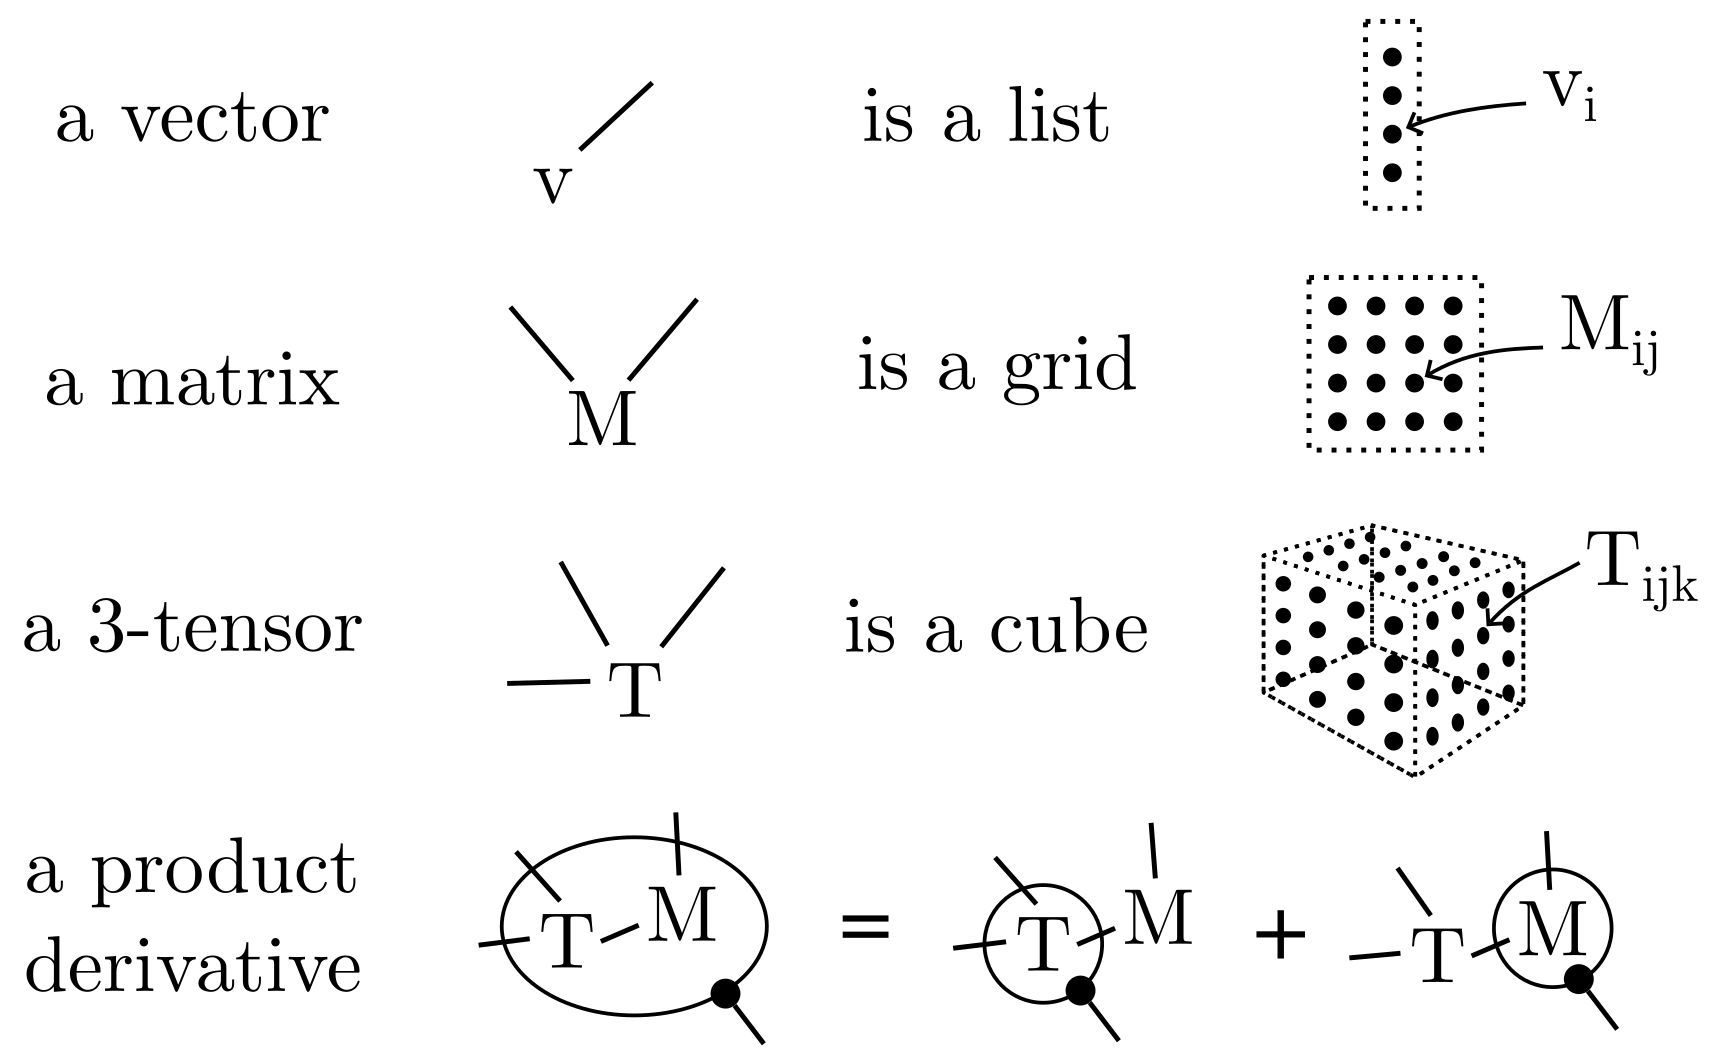
The Tensor Cookbook: Essential Resource for Machine Learning Deep Learning
By
–
The Tensor Cookbook https://
bit.ly/3zx8UQx
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Hunyuan-Large: 389B Parameter Open-Source MoE Model
By
–
introduc ing Hunyuan-Large, which is currently the largest open-source Transformer-based mixture of experts model, with a total of 389 billion parameters and 52 billion activation parameters, capable of handling up to 256K tokens.
-
Google Trends Search: TensorFlow vs PyTorch Comparison
By
–
This is the exact search I did https://
trends.google.com/trends/explore
?date=today3-m&geo=US&q=tensorflow,pytorch&hl=en
… -
Uncertainty about search trends between TensorFlow and Keras
By
–
I don't know. I was guessing 50-50. Maybe people are searching for Keras instead?
-

ML Engineering Open Book: Comprehensive Machine Learning Resource Guide
By
–
GitHub – stas00/ml-engineering: Machine Learning Engineering Open Book https://
bit.ly/3SP0qtv
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Microsoft and NUS introduce GenXD for 3D and 4D generation
By
–
Microsoft and NUS introduce GenXD, a joint model for 3D and 4D generation pic.twitter.com/dp4lYf3pcV
— Chubby♨️ (@kimmonismus) 5 novembre 2024Microsoft and NUS introduce GenXD, a joint model for 3D and 4D generation
-

Comprehensive Data Scientist Handbook: Essential Learning Resources
By
–
GitHub – andresvourakis/data-scientist-handbook: This is a repo with links to everything you'd ever want to learn about data science https://
bit.ly/3N6nZvo
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Meta Adaptive Caching Accelerates Diffusion Transformer Video Generation
By
–
Meta presents Adaptive Caching for Faster Video Generation with Diffusion Transformers pic.twitter.com/RY03zsLmHL
— AK (@_akhaliq) 5 novembre 2024Meta presents Adaptive Caching for Faster Generation with Diffusion Transformers
-
Layer Selection Method: Random or Similarity-Based Approach
By
–
Interesting! How did you select these layers? Was this a random selection or did you sort them by input/output similarity?