Technique 2: Multi-Shot with Failure Cases Everyone uses examples. Engineers show the model what NOT to do. This creates boundaries that few-shot alone can't establish. Template: Task: [what you want] Good example:
[correct output] Bad example:
[incorrect output]
Reason it
MACHINE LEARNING
-
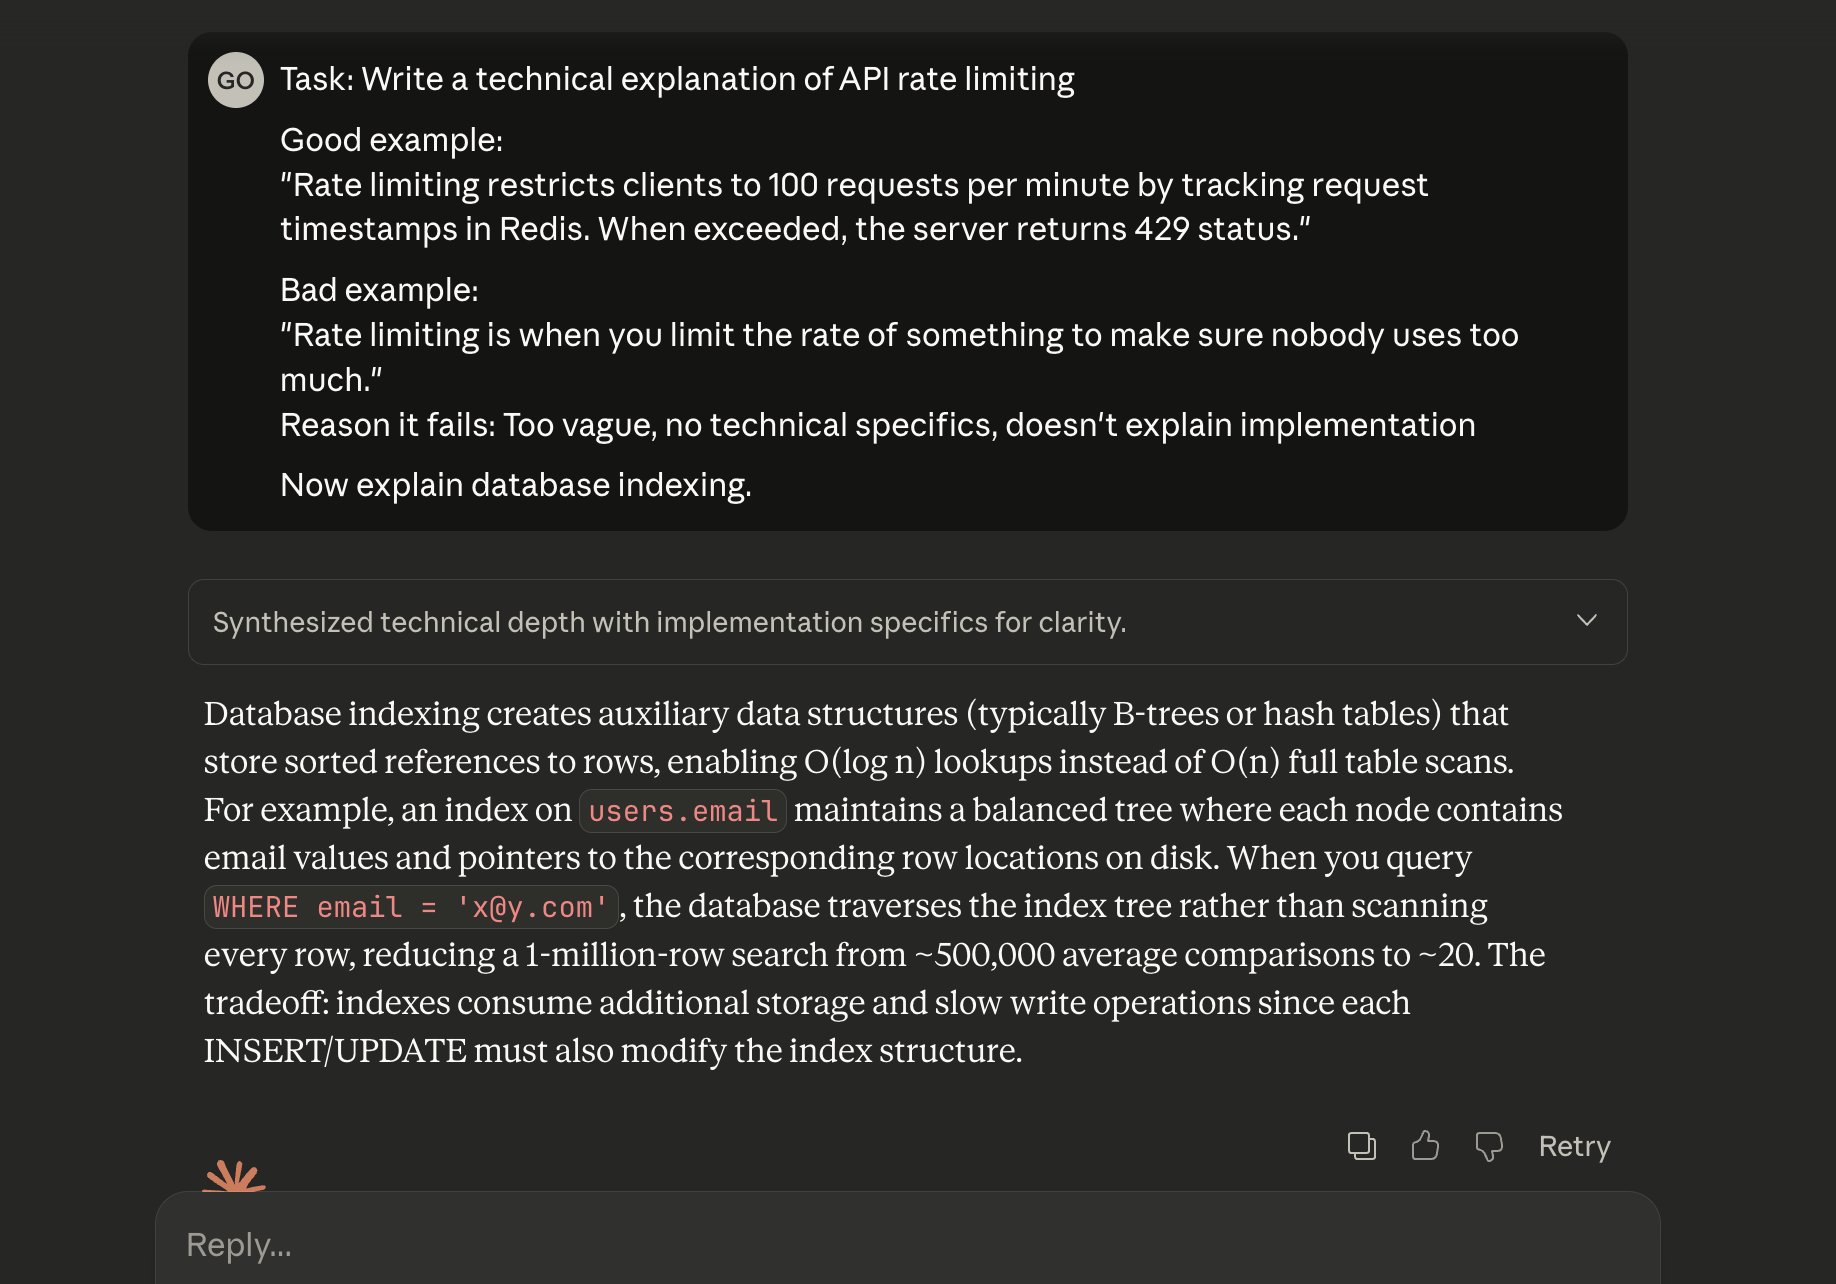
Multi-Shot Technique with Failure Cases
By
–
-

ORF AI Tool Helps Children Learn with Personalized Confidence
By
–
Every child learns differently. Our ORF tool is: Shaped by classrooms Guided by teachers Built to help young learners progress with confidence #WadhwaniAI #AIforGood #EdTech #EducationEquity #MachineLearning #DataForGood #SocialImpact #EducationInIndia
-
Coding Skills as a Path to AI-Generated Income
By
–
Coding skills unlock Ai income pic.twitter.com/R3neDP8ktl
— Satya Mallick (@LearnOpenCV) 10 décembre 2025Coding skills unlock Ai income
-
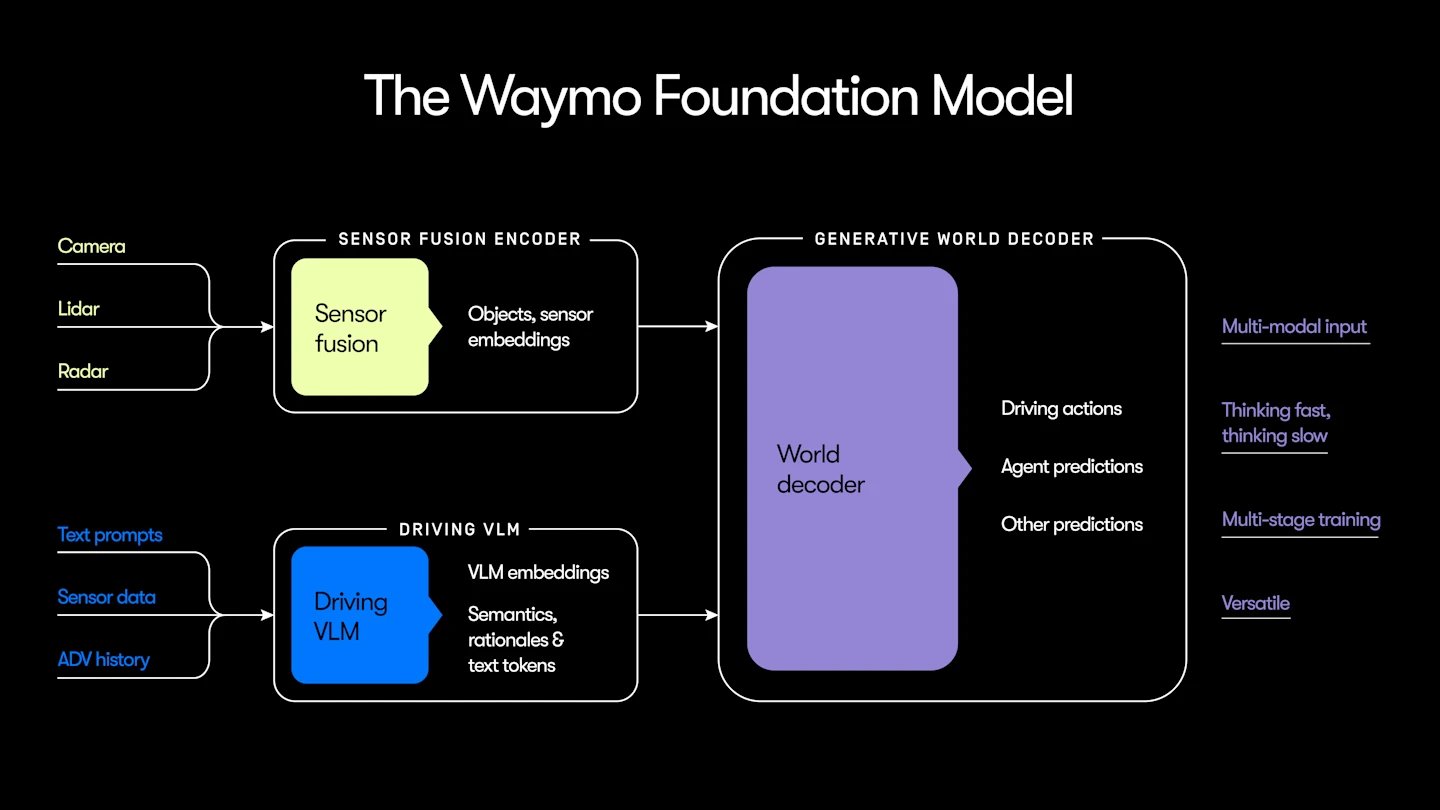
Waymo’s Use of Large Models and GOFE in Autonomous Driving
By
–
My sense is that @Waymo has been using large models for awhile (plus lots of GOFE for sensor pre-processing, system bootstrapping, data avalanching, and ongoing safety). One clue is the “thinking fast and slow” note on the image.
-
VLM on Edge Part 3: Frameworks Setup and Inference Guide
By
–
VLM on Edge Part 3: VLM Frameworks Setup and Inference
— Satya Mallick (@LearnOpenCV) 9 décembre 2025
The ultimate guide to deploying Vision Language Models on resource constrained hardware!
In this video we break it down further with the following.
✅Complete CUDA Math Library tailored for NVIDIA Jetson Orin Nano
✅Fail… pic.twitter.com/JVMviNbdICVLM on Edge Part 3: VLM Frameworks Setup and Inference
The ultimate guide to deploying Vision Language Models on resource constrained hardware! In this video we break it down further with the following.
Complete CUDA Math Library tailored for NVIDIA Jetson Orin Nano
Fail -
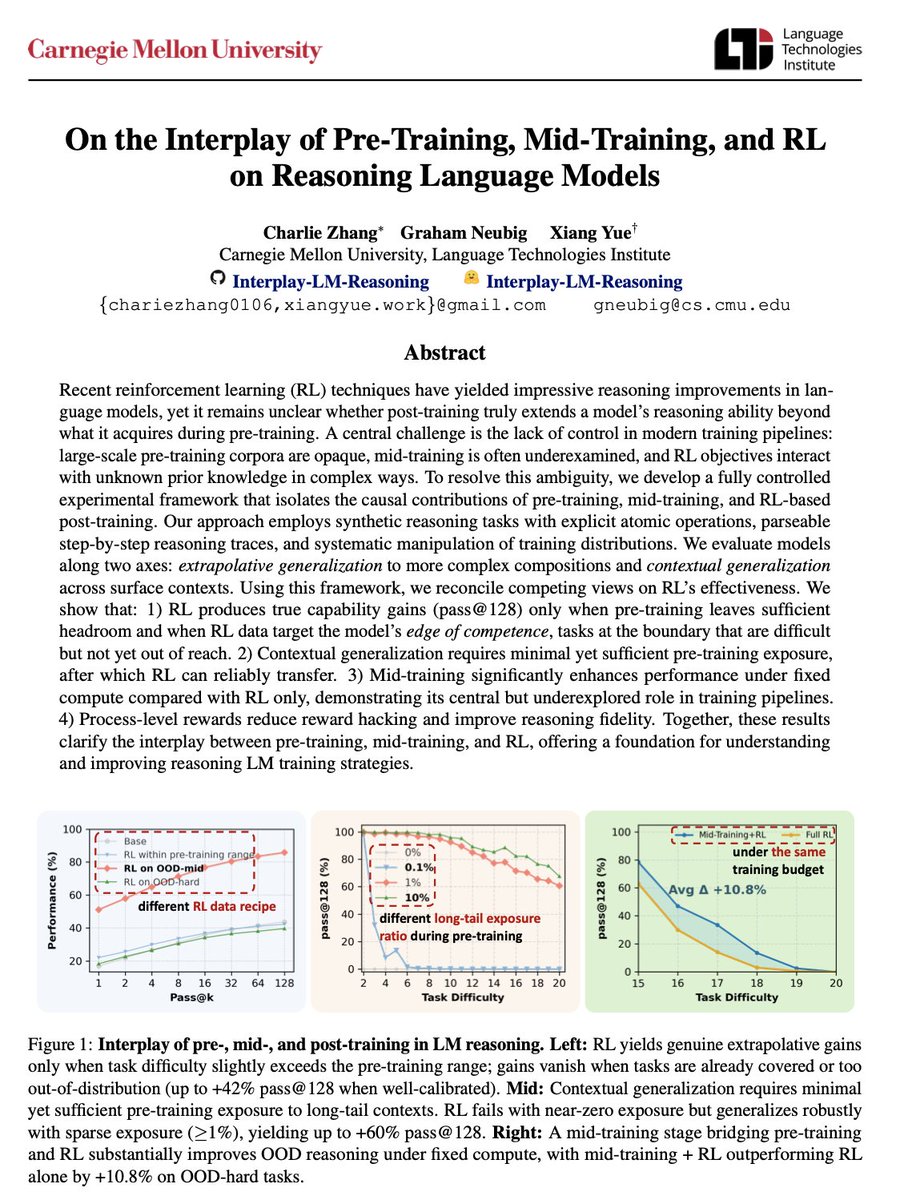
RL Impact on Base Model Performance: Pre-training and Mid-training Interplay
By
–
There are competing views on whether RL can genuinely improve base model's performance (e.g., pass@128). The answer is both yes and no, largely depending on the interplay between pre-training, mid-training, and RL. We trained a few hundreds of GPT-2 scale LMs on synthetic GSM-like reasoning data from scratch. Here are what we found: 🧵
-
AI model coding performance on SWE benchmark
By
–
ca veut dire que c'est un model qui code très bien . SWE c'est le benchmark, 68 le score 🙂
-
Dense Models Beat MoE: Western AI Companies Strategic Shift
By
–
It's a big macro trend shift as they revert back to old dense models, while still comparable or better than MoE baselines. "Leak" because the big Western companies figured it out a while ago, letting the OSS community & China go down the MoE path — notably more complex + ~worse
-

Virtual beings offer lifeline for lonely and special needs individuals.
By
–
With virtual beings coming, more of us will be talking to AI's. For the lonely they can offer a lifeline. My special needs son, for instance, doesn't have any interest in talking with people, but loves talking with ChatGPT. There's a new raft of AI companions that adapt to
-
Resemble AI’s DETECT-3B Omni: Multimodal Deepfake Detector
By
–
Calling it now, this will be the industry standard Deepfake Detector. @resembleai AI released the first multimodal deepfake detector “DETECT-3B Omni” yesterday.
— AI Breakfast (@AiBreakfast) 9 décembre 2025
Audio, video, images. 98% accuracy.
$13M strategic funding, backed by Google. pic.twitter.com/AxLyZ7dQCLCalling it now, this will be the industry standard Deepfake Detector. @resembleai AI released the first multimodal deepfake detector “DETECT-3B Omni” yesterday. Audio, video, images. 98% accuracy. $13M strategic funding, backed by Google.