Efficiently Scaling Transformer Inference Pope et al.: https://
arxiv.org/abs/2211.05102 #ArtificialIntelligence #DeepLearning #MachineLearning
LLMS
-

Efficiently Scaling Transformer Inference Techniques
By
–
-
Hybrid AI Systems More Practical Than Full LLM Retraining
By
–
I love the dramatic futurism here! But it's more likely they will be hybrid systems. You don't want to retrain a LLM everytime a Wikipedia page is changed, or a news item is published. (Plus, Google would be in the best place to deliver this new system, incrementally.)
-
When We Realize We’re Just Stochastic Parrots
By
–
what happens when we realize we were just stochastic parrots all along?
-
LangChain 0.0.12 Release with AI21Labs and Manifest Integrations
By
–
LangChain version 0.0.12 Two super exciting integrations! @AI21Labs integration (from a friend of @YuvalinTheDeep
) Integration with @HazyResearch
's manifest library (with help from @laurel_orr1
) -
Build Train Evaluate GPT Models NVIDIA NeMo Megatron
By
–
Learn how to construct, train, and evaluate a GPT model using NVIDIA NeMo with Megatron on Jupyter Notebooks in a new free, hands-on lab from NVIDIA LaunchPad. Get started: https://
nvda.ws/3tm9ABs -

Model Capabilities Emerge with Scale: Sentiment Classification Study
By
–
This is a wonderful study on the emergence of model capabilities with scale. It is remarkable to see sentiment classification working with 1 data point, and fascinating to see the effectiveness of chain of thought prompting growing with scale.
-
AGI Parameter Count vs Brain Synapses: Current Models Scale
By
–
A common view is that human level AGI will require a parameter count in the order of magnitude of the brain’s 100 trillion synapses. The large language models and image generators are only about 1/1000 of that, but they already contain more information than a single human
-
Multiple prompts and fine-tunes serve different AI purposes
By
–
Depends! We have many prompts and fine-tunes in place, each with a different purpose, some working together.
-
Training Transformers at Scale for Scientific Applications
By
–
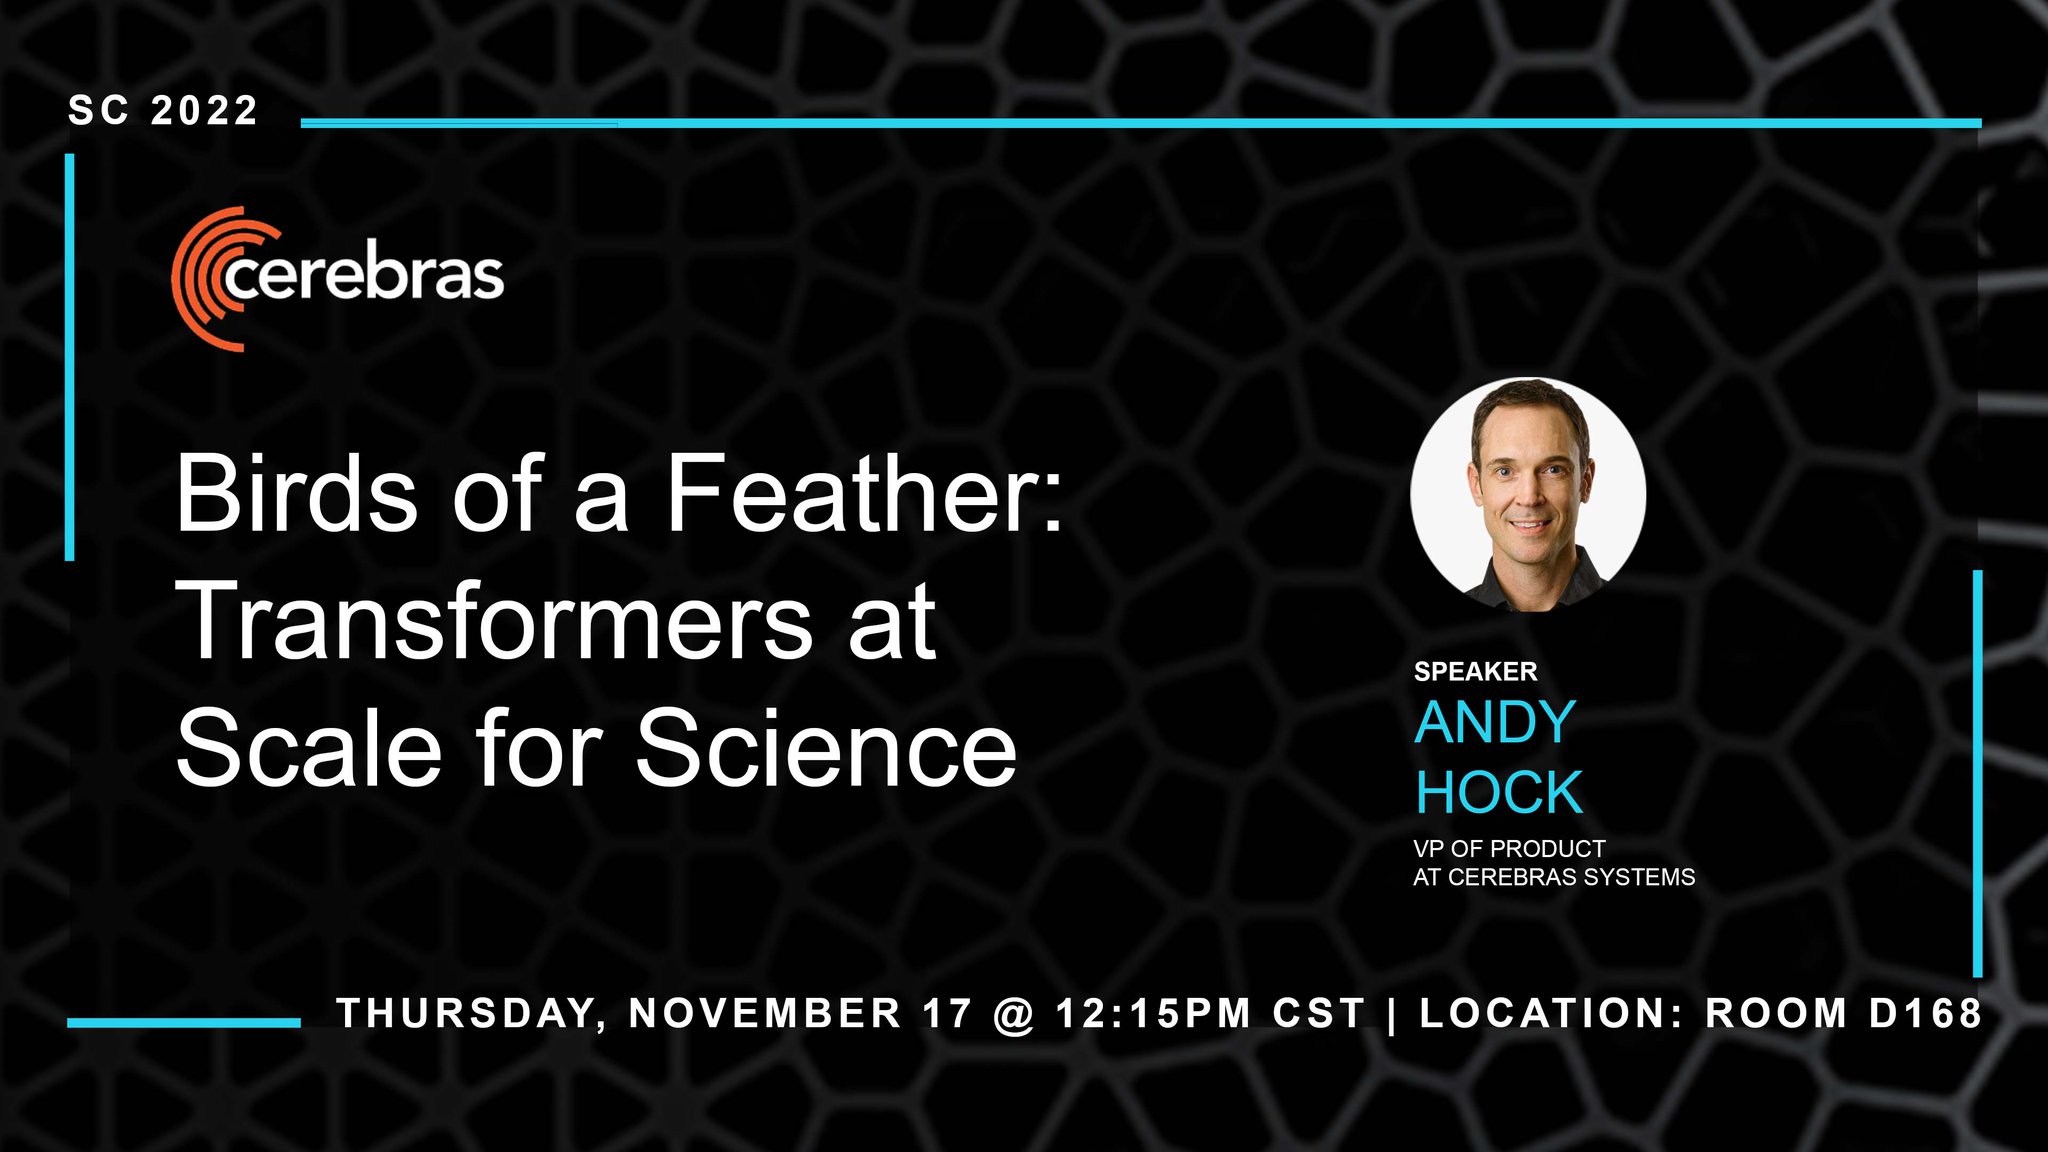
Transformers and other large language models have shown impressive capabilities as foundation models for domains such as NLP and CV. Join Andy Hock, our VP of Product, at #SC22, as he discusses new algorithms, software, and hardware for training transformers at scale for science
-
GPT performance varies significantly by use case
By
–
Like most things with GPT, it’s super case by case