The key insight most people miss: DeepSeek replacing Claude entirely is the wrong move. DeepSeek as a $0.14 second opinion running alongside Claude is the right move. Same thinking system. Dramatically different API bill.
LLMS
-
DeepSeek V4 integrated with Claude Code, reduced cost, parallel usage
By
–
DeepSeek V4 now speaks Claude Code natively. $0.14 per million tokens vs $5.00 for Claude Opus 4.7. Here's the exact setup that runs DeepSeek as a second opinion alongside your main Claude session, without replacing it: ———————————-
DEEPSEEK PARALLEL
— -
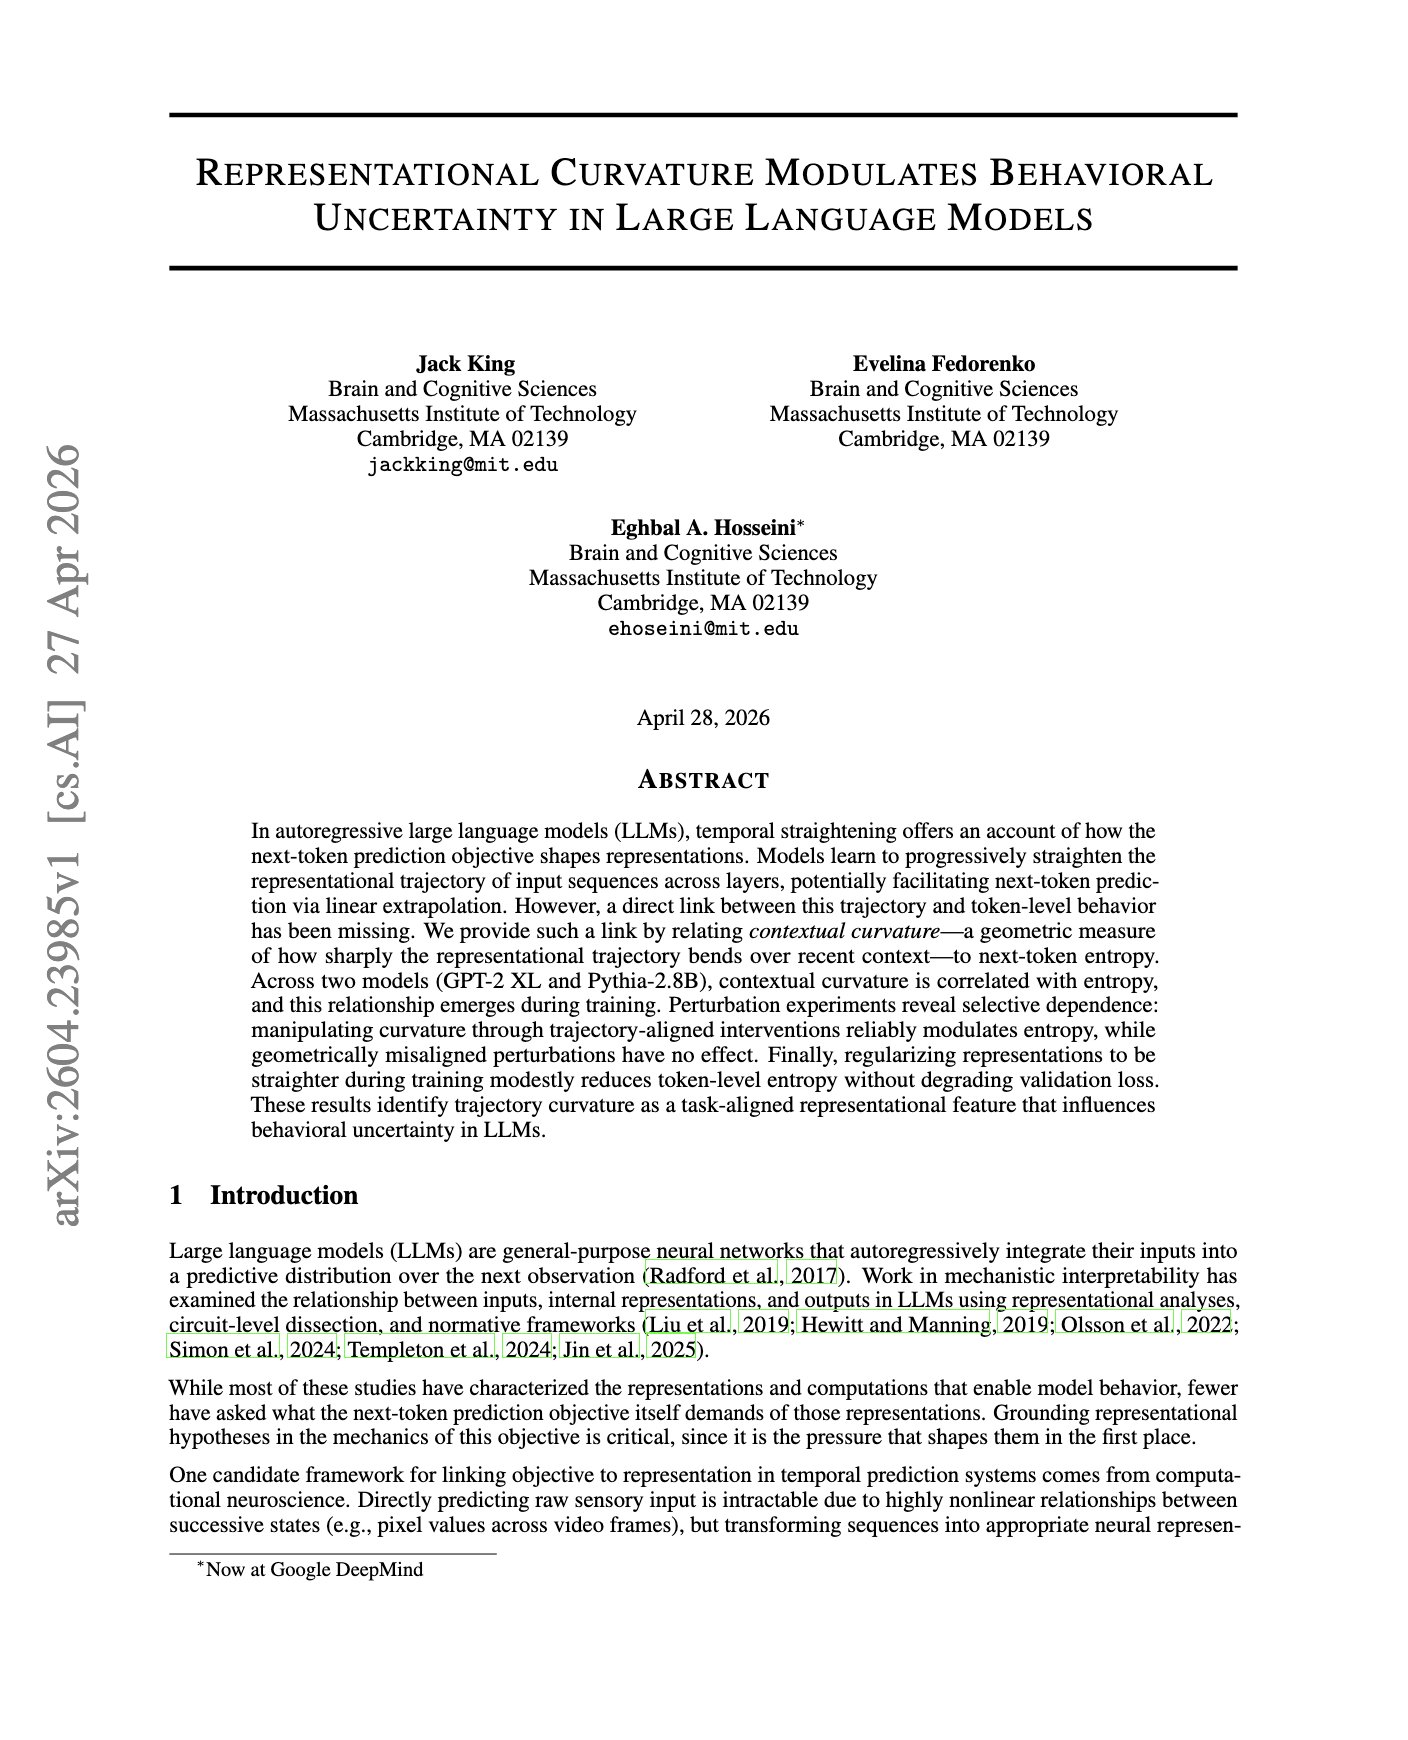
Representational Geometry Influences Uncertainty in Large Language Models
By
–
"Representational Curvature Modulates Behavioral Uncertainty in LLMs" Most interpretability work studies what features live inside LLMs. But this paper studies something deeper, which is the geometry of the whole evolving representation. The key result is that representational
-
LangChain adds API support for AI due diligence research agents
By
–
.
@p0
's API suite is now supported in LangChain, and they wrote a cookbook for a due diligence agent. We're part of the recipe:
• Deep Agents for orchestrating dedicated research track subagents
• @p0
’s Task API for research, findings, confidence scores, and follow-ups Full -
Team’s Success with Devin 3.0 and Devin Desktop Highlighted
By
–
i'm just an advisor, cant take credit. team is doing great with devin 3.0 and devin desktop
-
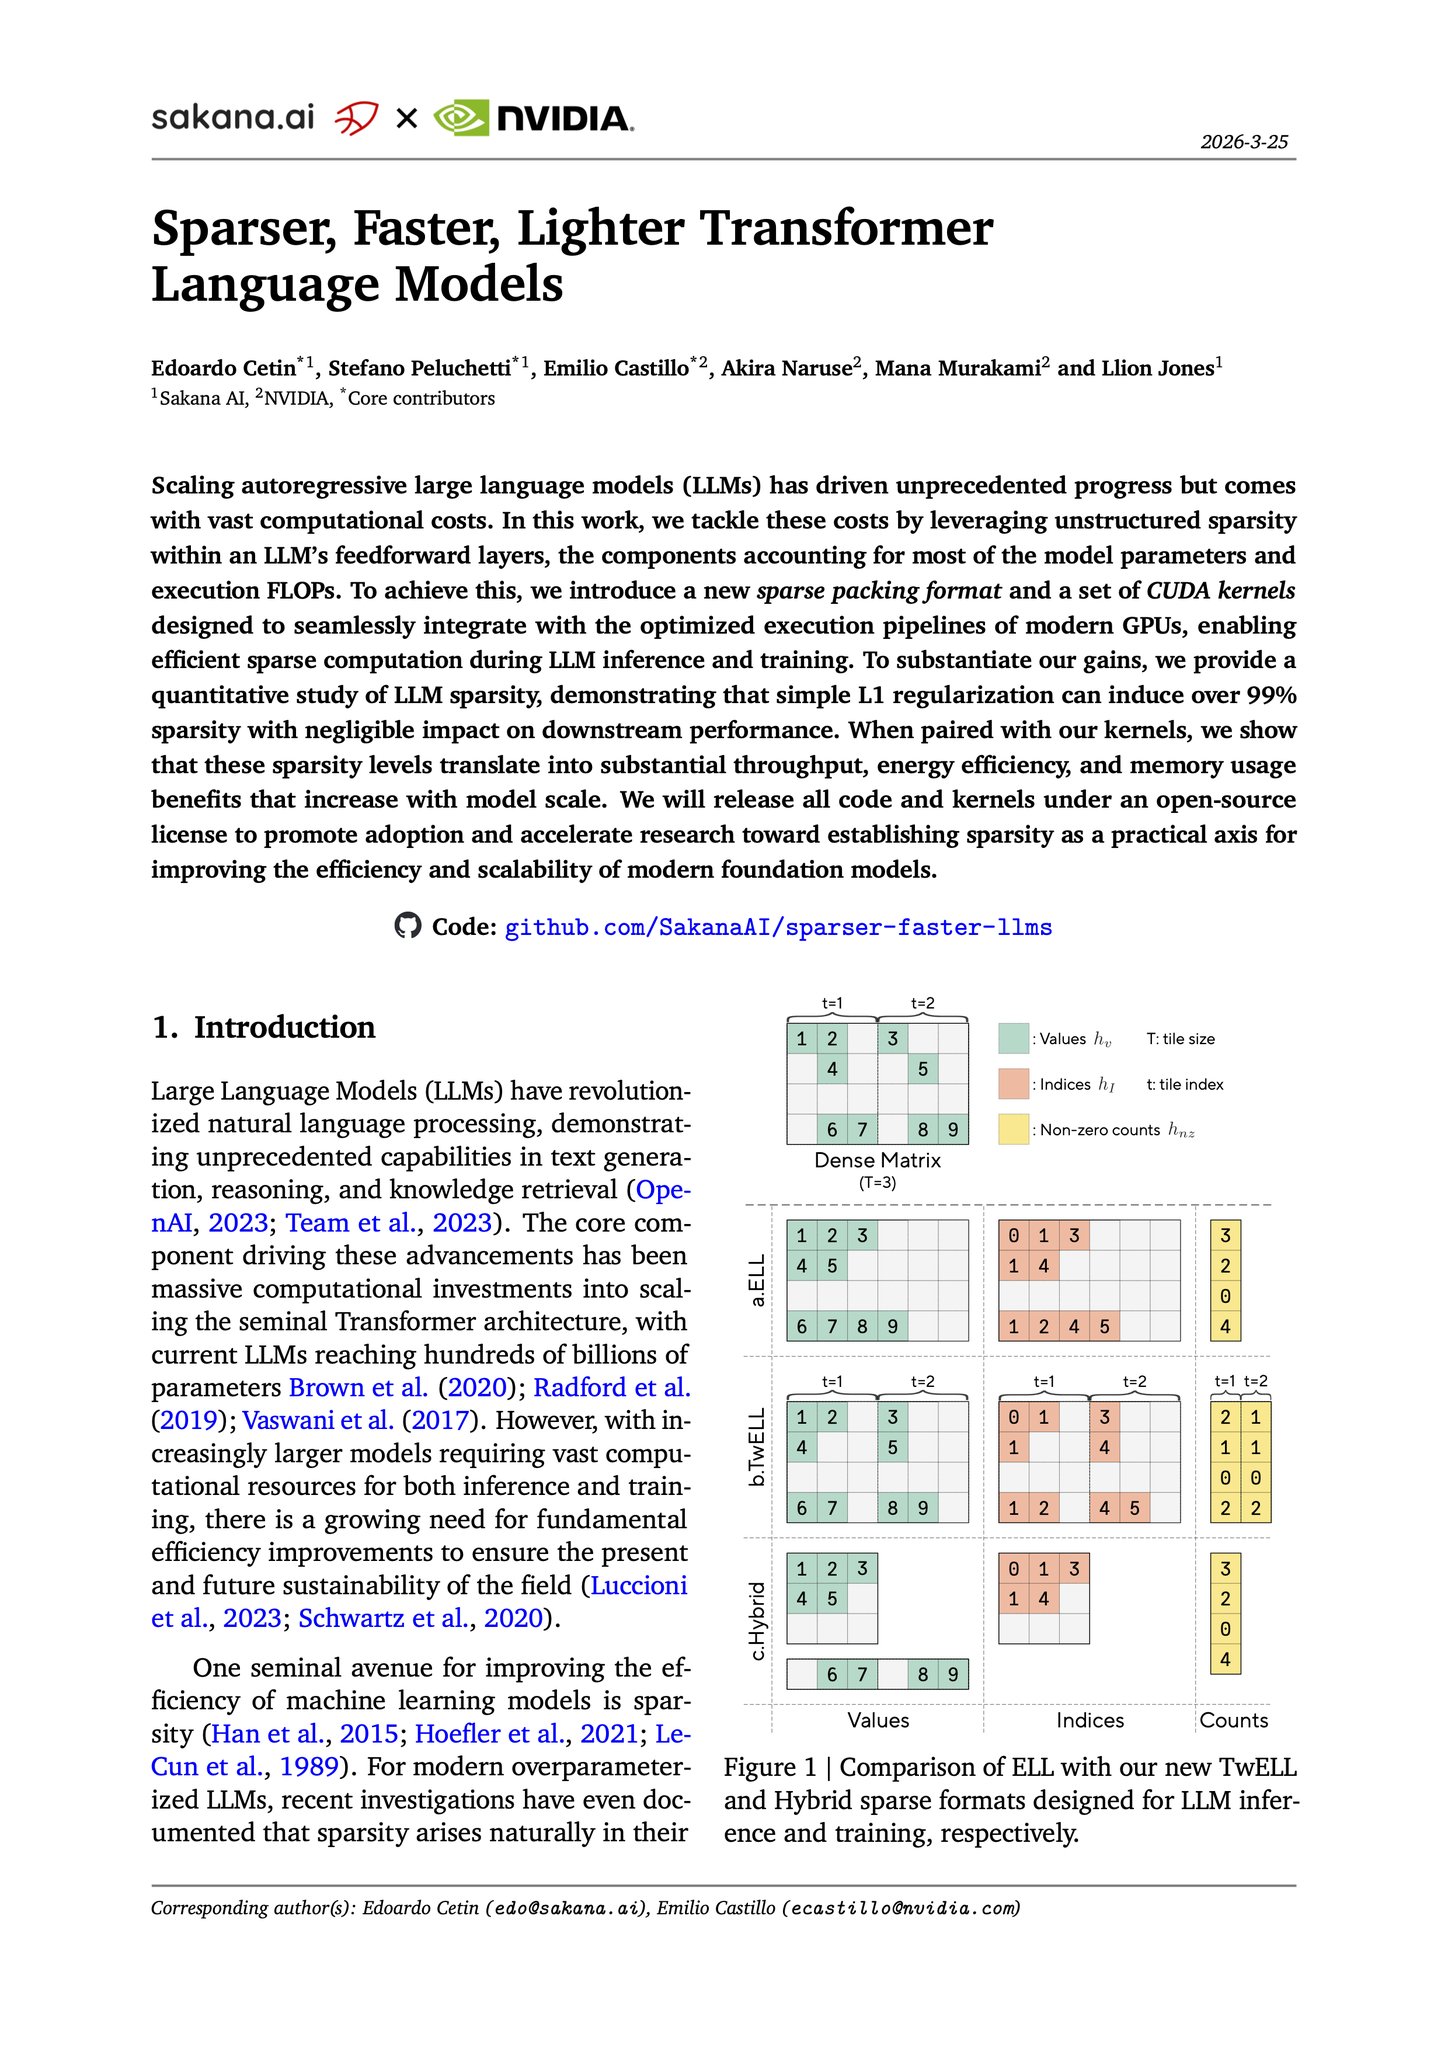
Hardware limitations on sparse neural activation in LLMs
By
–
The human brain is incredibly efficient because it only activates the specific neurons needed for a thought. Modern LLMs naturally try to do this too (> 95% of neurons in feedforward layers stay silent for any given word), but our hardware punishes them for it. One of the most
-
Using AI Models to Optimize Prompt Routing and API Budget
By
–
using a 1T parameter model to parse a 3-line JSON is a crime 😅@OrcaRouter just dropped.
— Charly Wargnier (@DataChaz) 8 mai 2026
It automatically routes prompts based on complexity to protect your API budget 👀
CFOs after reading this: https://t.co/bSrxIcukLZ pic.twitter.com/5YG9swOHUCusing a 1T parameter model to parse a 3-line JSON is a crime @OrcaRouter just dropped. It automatically routes prompts based on complexity to protect your API budget CFOs after reading this:
-
Optimiser les LLM avec la sparsité adaptée au GPU
By
–
How do we make LLMs faster and lighter? Don’t force the GPU to adapt to sparsity. Reshape the sparsity to fit the GPU! ⚡️
— Sakana AI (@SakanaAILabs) 8 mai 2026
Excited to share our new #ICML2026 paper in collaboration with @NVIDIA: "Sparser, Faster, Lighter Transformer Language Models". This work introduces new… pic.twitter.com/ehByWHIh6IHow do we make LLMs faster and lighter? Don’t force the GPU to adapt to sparsity. Reshape the sparsity to fit the GPU! Excited to share our new #ICML2026 paper in collaboration with @NVIDIA
: "Sparser, Faster, Lighter Transformer Language Models". This work introduces new -
Internal Manual for Building AI Agent Skills Published
By
–
We've published our internal manual for building agent skills. Skills require a new way of thinking for developers.