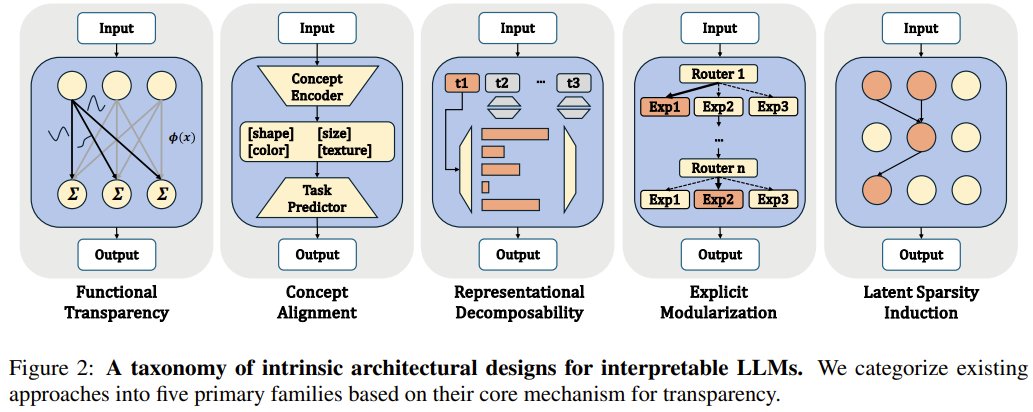
Can we finally trust what LLMs are really thinking? Yutong Gao and researchers from Peking University, Purdue, and Nanjing University present a new survey on intrinsic interpretability — building transparency directly into model architecture rather than relying on post-hoc
LLMS
-
OrcaRouter optimizes AI model selection to reduce prompt costs
By
–
Stop paying frontier model prices for prompts that could run on something lighter.
— AI Highlight (@AIHighlight) 8 mai 2026
OrcaRouter reads the request, picks the right model, and the savings stay in your pocket. https://t.co/SQ22HFpm1LStop paying frontier model prices for prompts that could run on something lighter. OrcaRouter reads the request, picks the right model, and the savings stay in your pocket.
-
OpenAI closes cyber capability gap with GPT-5.5 Cyber in weeks
By
–
The surprising part is not just that Claude Mythos is powerful. It is that OpenAI seems to have closed much of the cyber-capability gap with GPT-5.5 Cyber in weeks, not years. On AISI’s expert cyber tasks, GPT-5.5 Cyber was roughly on par with Mythos and even slightly ahead on
-
LangSmith Launches as a Remote MCP Server for AI Assistants
By
–
LangSmith is now a remote MCP server. Point any MCP-capable client at it, sign in with your LangSmith account, and your assistant can read: Traces Projects Datasets Prompts Billing No local server or API keys necessary. Try it today.
-
Improving Claude’s Safe Behavior via Training and Response Rewriting
By
–
We experimented with training Claude on examples of safe behavior in scenarios like our evaluation. This had only a small effect, despite being similar to our evaluation. We got further by rewriting the responses to portray admirable reasons for acting safely.
-
Training Claude to Understand and Correct Misaligned AI Behavior
By
–
We found that training Claude on demonstrations of aligned behavior wasn’t enough. Our best interventions involved teaching Claude to deeply understand why misaligned behavior is wrong. Read more:
-
Anthropic Research Eliminates Harmful Behavior in Claude 4
By
–
New Anthropic research: Teaching Claude why. Last year we reported that, under certain experimental conditions, Claude 4 would blackmail users. Since then, we’ve completely eliminated this behavior. How?
-

Codex: A Transformative Tool for All Computer Work, Not Just Coding
By
–
codex is for everyone — a transformative tool for all work done with a computer, not just coding
-
Codex Goal Feature for Long-Running Tasks
By
–
/goal in Codex is wild!
— Vaibhav (VB) Srivastav (@reach_vb) 8 mai 2026
Give Codex the mission.
Tell it what “done” looks like.
Let it keep going until it hits the end state.
Perfect for big refactors, migrations, retry loops, long-running experiments, and all the “don’t stop until this works” tasks.
Enable it in… pic.twitter.com/6VZKGHt7Ch/goal in Codex is wild! Give Codex the mission.
Tell it what “done” looks like.
Let it keep going until it hits the end state. Perfect for big refactors, migrations, retry loops, long-running experiments, and all the “don’t stop until this works” tasks. Enable it in -
Routing tasks to cheapest model that meets quality bar
By
–
What changed in May 2026: > Before: you picked one model and committed.
> After: you route tasks to the cheapest model that meets the quality bar. DeepSeek V4-Pro scores within 7-8 points of Claude Opus 4.7 on SWE-bench. At 1/7th the cost during promo. The prompting skill