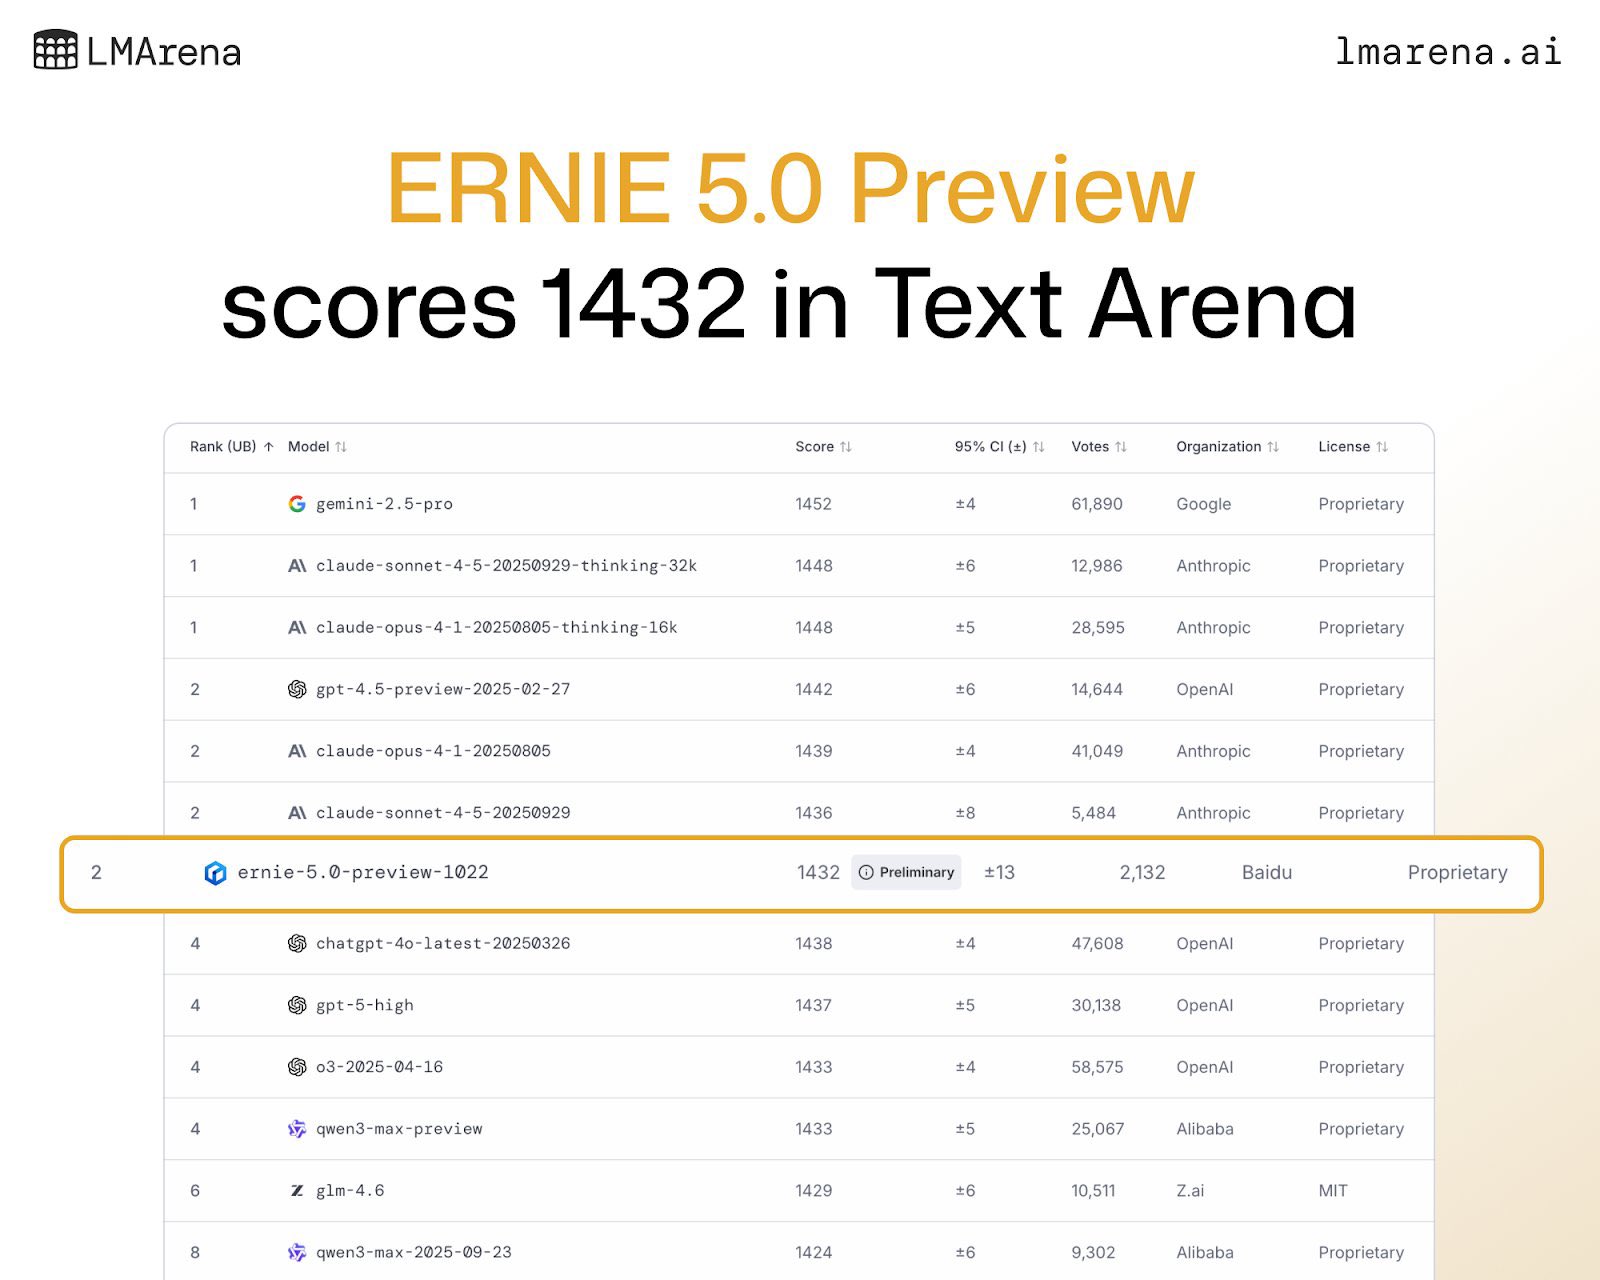
ERNIE-5.0-Preview-1022 from Baidu got a preliminary high ranking on LMArena and scored 1432 points. Feels like the gap is getting very small
By
–
ERNIE-5.0-Preview-1022 from Baidu got a preliminary high ranking on LMArena and scored 1432 points. Feels like the gap is getting very small
By
–
Fine-tune DeepSeek-OCR on your own language!
— Akshay 🚀 (@akshay_pachaar) 8 novembre 2025
(100% local)
DeepSeek-OCR is a 3B-parameter vision model that achieves 97% precision while using 10× fewer vision tokens than text-based LLMs.
It handles tables, papers, and handwriting without killing your GPU or budget.
Why it… pic.twitter.com/SfBXY4Is8o
Fine-tune DeepSeek-OCR on your own language! (100% local) DeepSeek-OCR is a 3B-parameter vision model that achieves 97% precision while using 10× fewer vision tokens than text-based LLMs. It handles tables, papers, and handwriting without killing your GPU or budget. Why it
By
–
I’m wondering if I accidentally flipped some feature flag or something (or maybe I’m in a beta test), because it definitely feels different. The results are way better, but having the “thinking” phase appear first makes it feel slower, even if the actual response time hasn’t
By
–
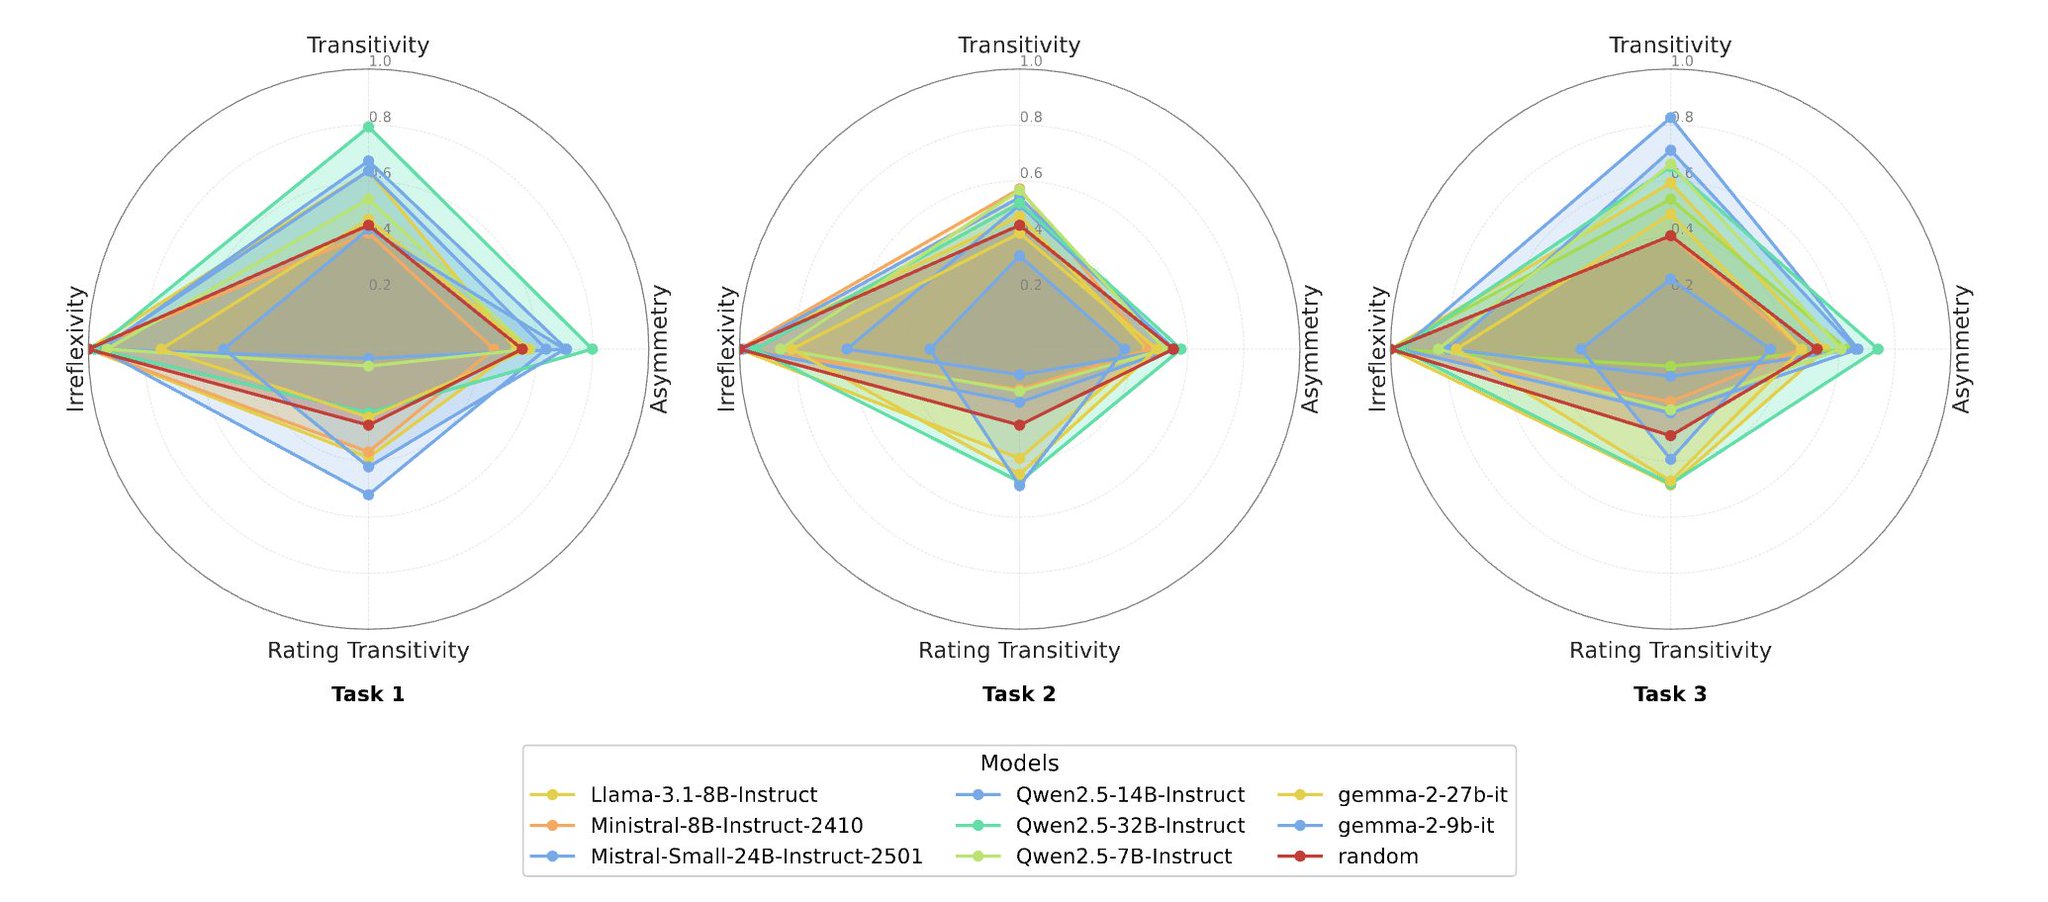
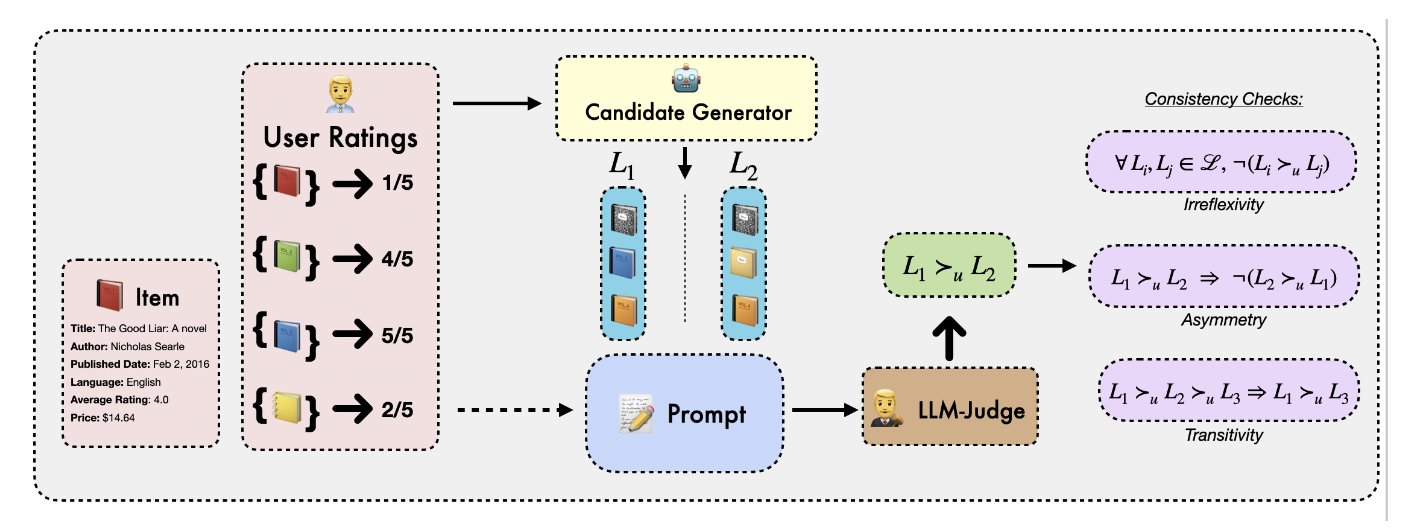
This figure visualizes the mental stability of models. LLMs like Qwen2.5 and Llama-3 stay consistent across all preference axioms transitivity, asymmetry, rating coherence proving they reason in structured, human-like ways. Even without training on user data, they infer what
By
–
This pipeline replaces traditional simulators with a simple idea: 1. Feed the model a short user history
2. Show two candidate slates
3. Ask: which one would this user prefer?
4. Aggregate responses across multiple LLMs That’s the “LLM-as-a-Judge” world model in action
By
–
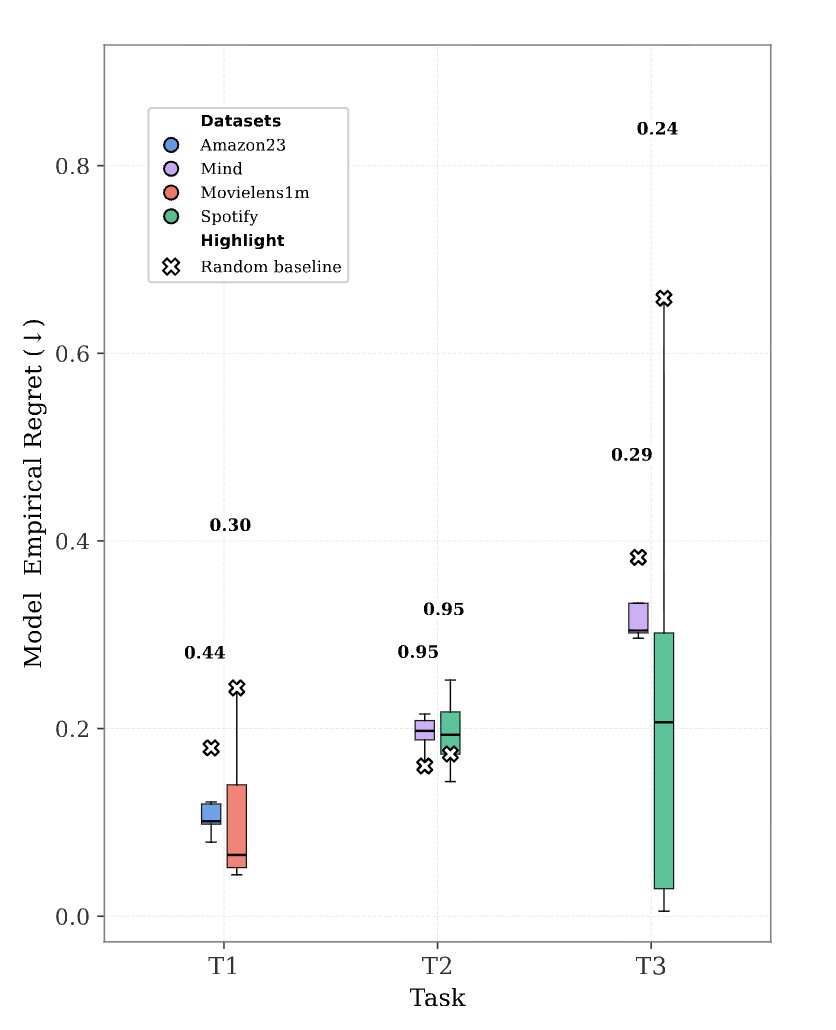
This figure shows how well different LLMs judge slates (ordered recommendations) across datasets like Amazon, Spotify, MIND, and MovieLens. Lower “regret” = closer alignment with real user preferences. Turns out, LLMs consistently outperform random baselines when slates differ
By
–
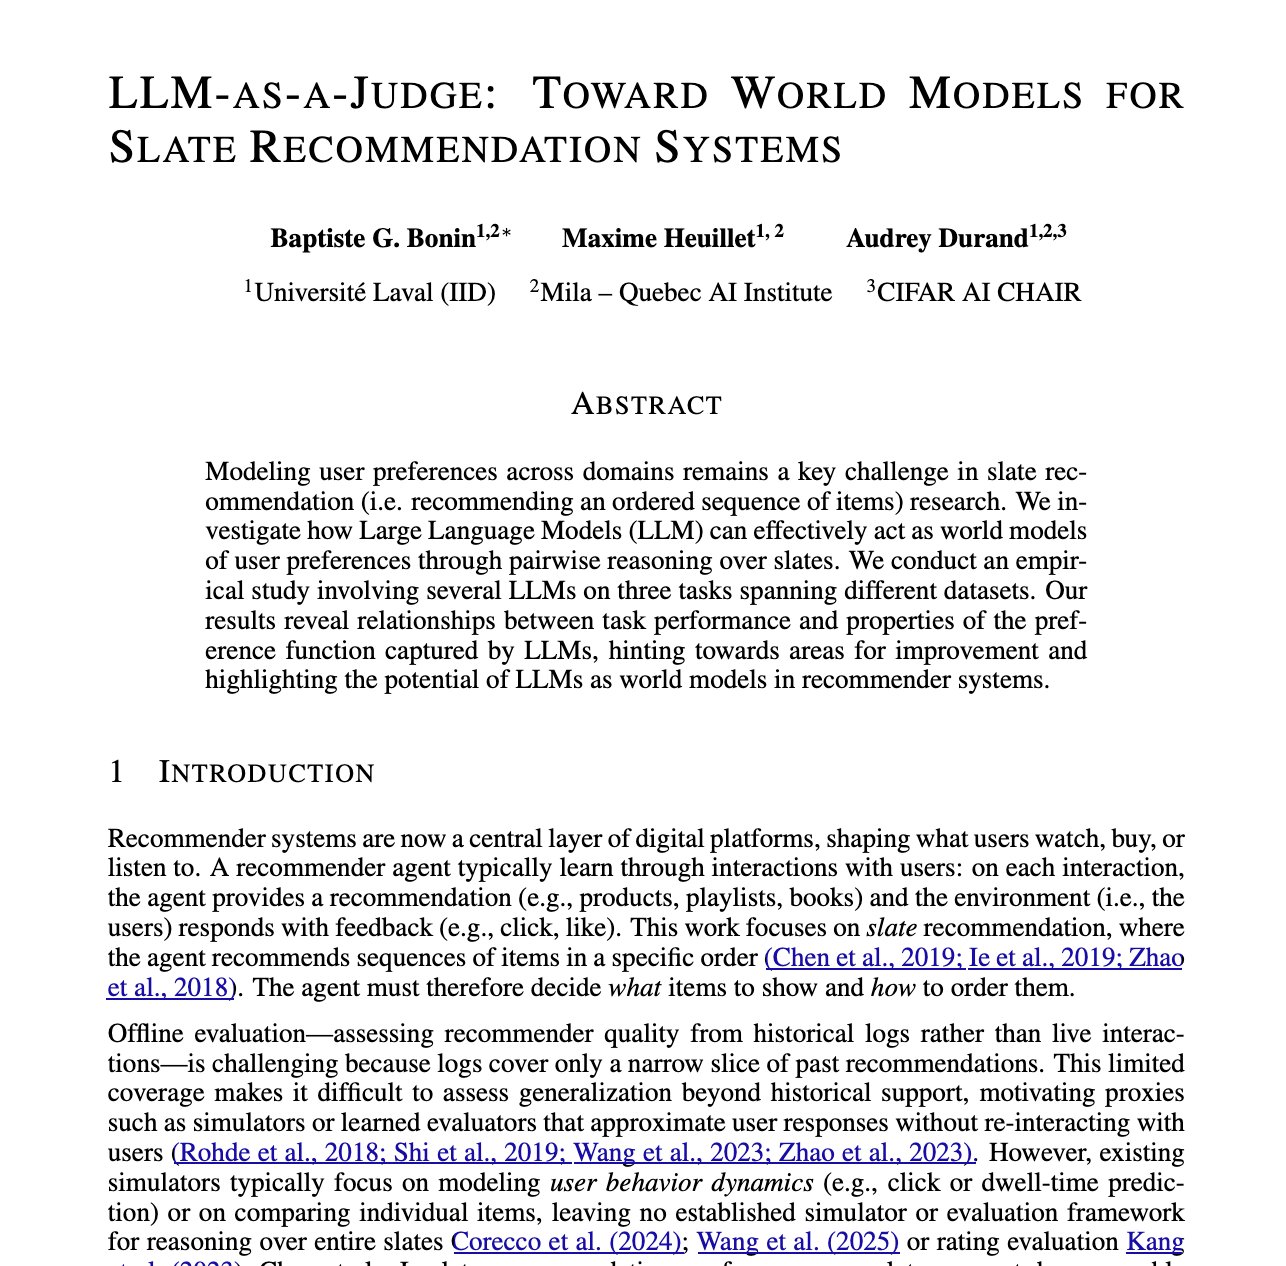
Holy shit… LLMs just learned how to judge your taste and they’re freakishly good at it A new paper, “LLM-as-a-Judge: Toward World Models for Slate Recommendation Systems,” just flipped recommender research on its head. Instead of simulating every click or dwell time, these

By
–
What if LLMs could tune their own decoding—no more guesswork with temperature and top‑p? Enter AutoDeco: the first architecture that makes LLM decoding truly end-to-end. By adding lightweight heads, the model predicts its own context-aware temperature and top‑p at every token
By
–
i feels like GPT-5’s routing accuracy and overall performance have improved a lot. Is it just me?
By
–
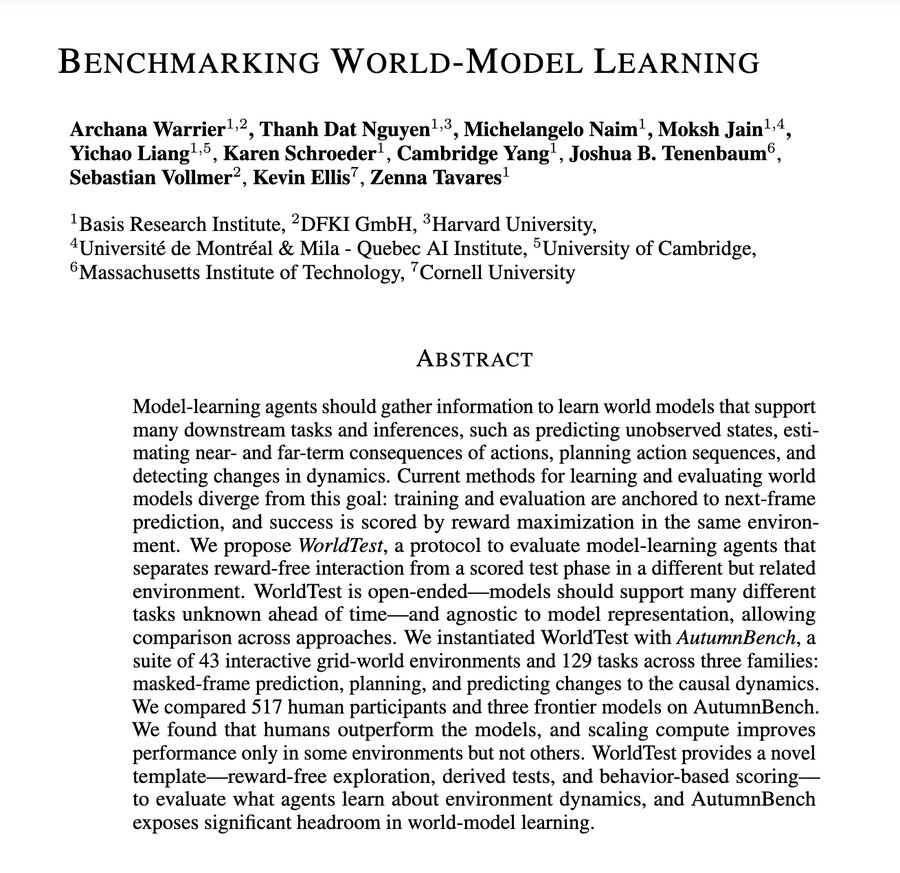
MIT just quietly humbled every major AI lab — and almost nobody’s talking about it. They built a new benchmark called WorldTest to see if AI actually understands the world. The results are brutal.
Even the top models — Claude, Gemini 2.5 Pro, OpenAI o3 — got crushed by