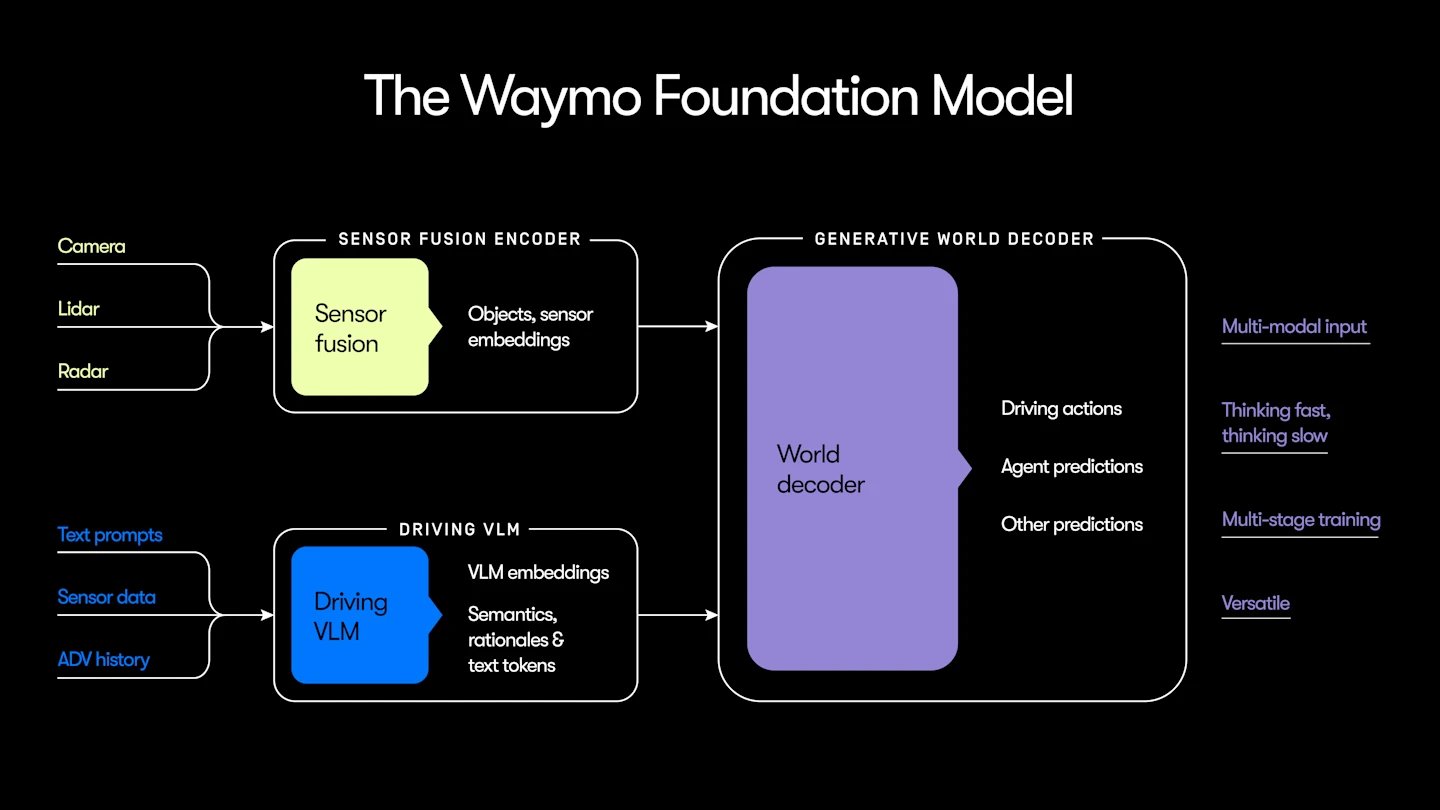
My sense is that @Waymo has been using large models for awhile (plus lots of GOFE for sensor pre-processing, system bootstrapping, data avalanching, and ongoing safety). One clue is the “thinking fast and slow” note on the image.
LLMS
-
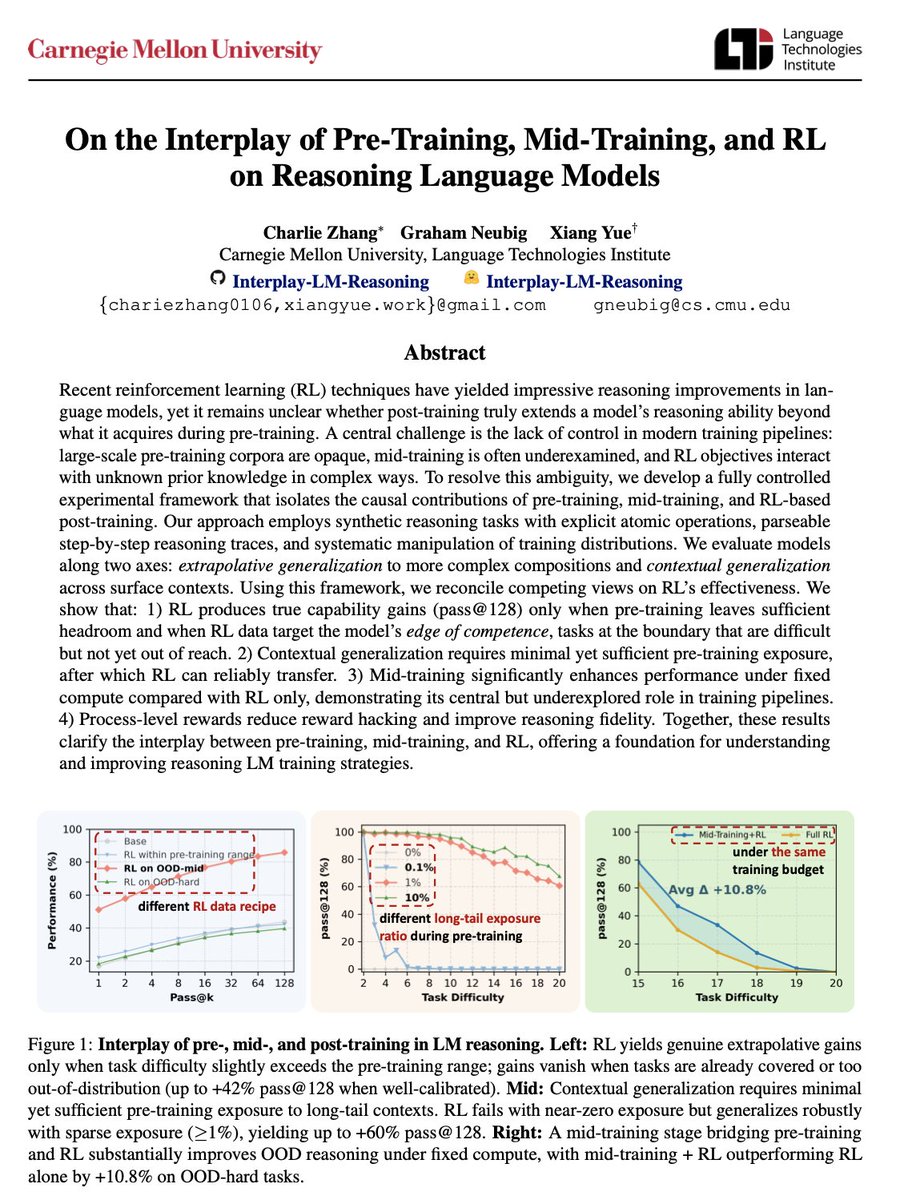
RL Impact on Base Model Performance: Pre-training and Mid-training Interplay
By
–
There are competing views on whether RL can genuinely improve base model's performance (e.g., pass@128). The answer is both yes and no, largely depending on the interplay between pre-training, mid-training, and RL. We trained a few hundreds of GPT-2 scale LMs on synthetic GSM-like reasoning data from scratch. Here are what we found: 🧵
-
AI model coding performance on SWE benchmark
By
–
ca veut dire que c'est un model qui code très bien . SWE c'est le benchmark, 68 le score 🙂
-
Top AI Models for Different Tasks: A Practical Guide
By
–
ChatLLM model picks we keep coming back to: Everyday → GPT- 5.1 Coding → Sonnet 4.5 / Opus 4.5
Images → Nano Banana Pro, Midjourney → Sora 2, Seedance Pro
TTS → ElevenLabs, Hume
Fast tasks → Gemini Flash
Reasoning → GPT-5.1 Thinking Model switching handled -

Offline AI Coding Model Achieving 68 SWE Performance
By
–
MAIS WWWWWWWWWWHAAAAAAT !!! Mais purée, si c’est vrai, vous n’imaginez même pas le BANGER ASTRONOMIQUE !! Genre pouvoir utiliser une IA qui code à 68 SWE en OFFLINE !!!! Dans l’avion, ou quand t’as pas de réseau dans le train… Je vais tester ça tout de suite, mais ma hype est
-

Notion Testing GPT-5.2 Internally
By
–
BREAKING : Notion might be testing GPT-5.2 internally under the "olive-oil-cake" codename. The codename is abstracted by Notion. Soon or not soon?
-

Fireworks AI Achieves Top Performance with Kimi K2 Blackwell
By
–
Fireworks AI hits top performance on the Artificial Analysis leaderboard with Kimi K2 on NVIDIA GB200 NVL72 systems. @FireworksAI_HQ CEO Lin Qiao explains why Blackwell NVL72 transforms massive MoE serving. Learn more https://
nvda.ws/48rJ4Mm -
Dense Models Beat MoE: Western AI Companies Strategic Shift
By
–
It's a big macro trend shift as they revert back to old dense models, while still comparable or better than MoE baselines. "Leak" because the big Western companies figured it out a while ago, letting the OSS community & China go down the MoE path — notably more complex + ~worse
-

OpenAI Joins Agentic AI Foundation and Donates AGENTS MD Standard
By
–

OpenAI is joining Agentic AI Foundation too and donating AGENTS MD standard to the organisation.
-

New OpenAI image model spotted on LM Arena
By
–


BREAKING : A new image model from OpenAI has been spotted on LM Arena. Chestnut and Hazelnut