New release from @PacktDataML @PacktPublishing "Agentic Architectural Patterns for Building Multi-Agent Systems: Proven design patterns and practices for GenAI, agents, RAG, LLMOps, and enterprise-scale AI systems" See it at http://
amzn.to/3MaHy8T 𝕋𝕒𝕓𝕝𝕖 𝕠𝕗
LLMS
-

Book: Agentic Architectural Patterns for Multi-Agent GenAI Systems
By
–
-
Sonnet 4.6 Makes AI Browser Extensions Finally Usable
By
–
AI Chrome extensions felt largely unusable because of how slow they were. Sonnet 4.6 is the first one that changes that for me. While in meetings, I am kicking off browser tasks and unlike Opus 4.5, it actually finishes before the meeting is done.
-
How AI is Disrupting the Traditional SaaS Business Model
By
–
How AI is breaking the SaaS business model https://
youtu.be/cxcb55zr2Q8?si
=7LnQ1WqfOTt0I3D0
… via @YouTube #SaaS #ArtificialIntelligence #AI #Tech #TechRevolution #LLM #genai @PawlowskiMario @chidambara09 @Ym78200 @CurieuxExplorer @efipm @bigfundu @sayedflah @Ronald_vanLoon @cyngn @belindabeibi -

Sonnet 4.6 Launch: Opus-Level Intelligence at Sonnet Prices
By
–
Sonnet 4.6 is live on ChatLLM by Abacus A Pretty big launch.
Feels very close to Opus-level intelligence, but at Sonnet prices.
Honestly, a great pick for simple coding tasks. -
Multilingual Data Curation Pipeline and Cross-Lingual Transfer Insights
By
–
Excellent work, execution, and report :). In our recent work https://
arxiv.org/abs/2508.07414, we also released a multilingual data curation pipeline for 39 languages. Training models on the data, we share the same insights, mainly cross-lingual transfer, adding multilingual data does not -

Sonnet-4.6 Dominates Latest AI Model Benchmarks and Evaluations
By
–
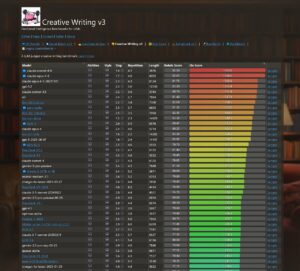

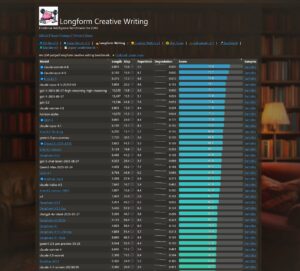
Sonnet-4.6 takes top place on all my evals: EQ-Bench, Creative writing, Longform writing & Judgemark. Opus 4.6 within margin of error. GLM-5 and Qwen3.5-397B nipping at their heels.
→ View original post on X — @maximelabonne, 2026-02-18 21:33 UTC
-
Amical launches an open-source AI dictation app
By
–
Amical launched a new open-source AI dictation app, reinforcing its position as a local-first alternative to subscription tools like Wispr Flow and Granola.
— 🚨 AI News | TestingCatalog (@testingcatalog) 18 février 2026
It runs entirely on your machine and includes context-aware formatting.
It uses Whisper and open-source LLMs to… pic.twitter.com/esmsX2NEa5Amical launched a new open-source AI dictation app, reinforcing its position as a local-first alternative to subscription tools like Wispr Flow and Granola. It runs entirely on your machine and includes context-aware formatting. It uses Whisper and open-source LLMs to
-
Tool Discipline Improves AI Reasoning Better Than Scale
By
–
Key insight: tool discipline > scale. Instead of complex multi-table training, we reinforced reliable tool use on simple queries — and saw transfer to 12-step reasoning tasks (59.7% Pass@1).
-
Snorkel Releases Agentic RL Eval Environment and Finance Reasoning Benchmark
By
–
Snorkel contributed: • An agentic RL eval environment • FinQA-Reasoning dataset • Finance Reasoning benchmark Full technical breakdown from the rLLM team + our enterprise takeaways here:
-

4B Model Outperforms 235B on Financial Reasoning Tasks
By
–
A 4B model > 235B on financial reasoning. We partnered with @rllm_project to fine-tune Qwen3-4B-Instruct-2507 — and it outperformed Qwen3-235B-A22B on expert-curated financial benchmarks.