
This is why you can't use your max sub outside of claude code
LLMS
-
Gemini 3.1 Pro Preview Introduces Medium Thinking Level for Enhanced Reasoning
By
–
Key changes compared to Gemini 3 Pro Preview Gemini 3.1 Pro Preview adds support for the MEDIUM thinking level, similar to support in Gemini 3 Flash Preview: – Low: Minimizes latency and cost. Best for simple instruction following or chat.
– Medium: Balances reasoning depth and -

OpenAI Reportedly Developing ‘Adult Mode’ with New ‘Sensitive Content’ Warnings
By
–

OpenAI is reportedly working on the Adult Mode as new "Sensitive Content" warnings were spotted in the code. This is an example of a conversation sharing h/t @SiveEmergentAI
-
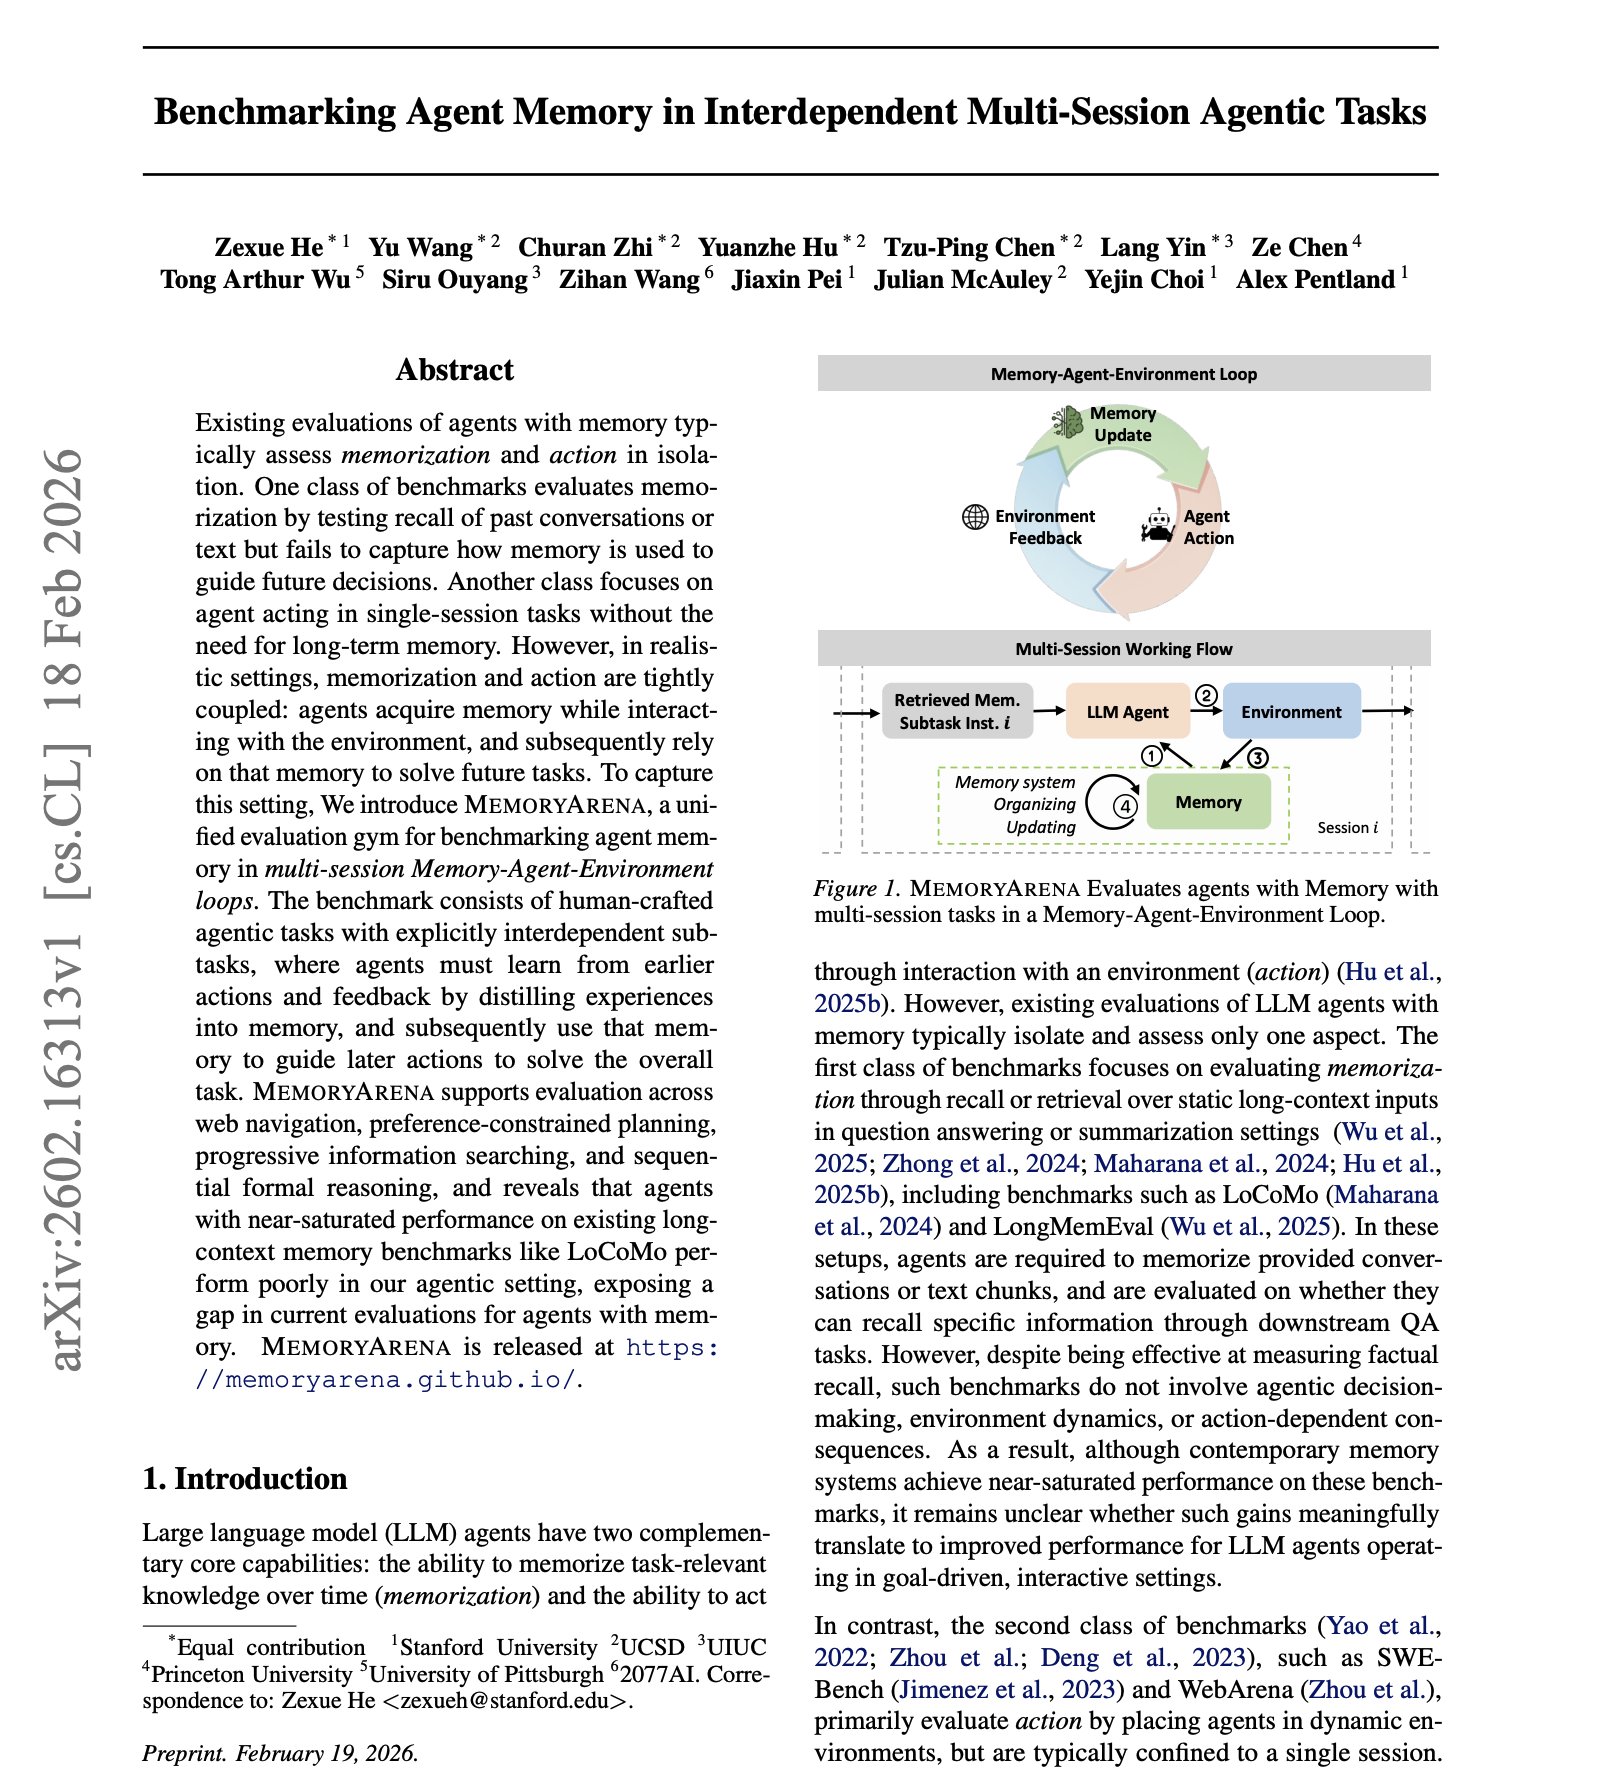
Agent Memory Benchmarks Don’t Predict Real-World Performance
By
–
Agent memory benchmarks are misleading. Scoring well on memory recall doesn't mean an agent can actually use that memory to take correct actions across sessions. Models that achieve near-saturated performance on existing long-context memory benchmarks like LoCoMo perform poorly
-
LLM Intelligence and Human Cognitive Abilities
By
–
Not that odd if you really understand how *human* intelligence works. We’ve known about the existence of the “g-factor” for about a century now. If *all* of the LLM training data is downstream from human cognitive abilities, then it’s intuitively unsurprising that these abilities
-

Connecting support email to private Codex AI server
By
–
OMG !!!!!! But the craziness, listen to what we’ve done please, it’s too much. We just connected our support email to a private server where we’re running Codex (AI that codes). When a customer sends a support email, from an identified user, linked to a bug on the platform,
-
AI Voice System Evaluation: Realism, Speed, and Tone Variations
By
–
It is still very clearly AI, though unsophisticated-on-AI users might be convinced it’s real. It’s quite fast as responding (much faster than say ChatGPT live voice mode) but not as fast as a human. It changes its tone very naturally but sometimes a bit exaggerated.
-
LLM Reasoning Traces and Bug Detection Capabilities
By
–
Did you look at the reasoning trace? I'm curious whether it did a wide scan and saw that suspicious line, or whether it reasoned from the symptoms to that as a cause. A lot of bugs can be proven incorrect locally, and LLMs are great at that
-
AI Soulja Boy Phone Demo Impresses with Responsive Conversation
By
–
Not only do I kind of love this ad, but I just had a 3min conversation with AI Soulja Boy at that phone number, and it actually made me laugh out loud twice.
— Allie K. Miller (@alliekmiller) 19 février 2026
Very responsive, perfect demonstration of the tech, passed my initial QA testing. https://t.co/OwhULR0OfiNot only do I kind of love this ad, but I just had a 3min conversation with AI Soulja Boy at that phone number, and it actually made me laugh out loud twice. Very responsive, perfect demonstration of the tech, passed my initial QA testing.
-
LLM-assisted development risks and prevention strategies
By
–
Mate I'm well aware of that risk, you can read some my thoughts about LLM-assisted development here: https://
honnibal.dev/blog/llm-style
-tips
…. Deleting my home directory would definitely be inconvenient so I'd like to take steps to prevent it.