What are the latest AI models to explore? any recs?
LLMS
-
MaxRL: One-Line GRPO Improvement for Better Training Scaling
By
–
MaxRL is a slick one line change to GRPO that optimizes a maximum likelihood objective instead of expected reward
— alphaXiv (@askalphaxiv) 19 février 2026
Scaling advantages with 1/μ as opposed to traditional REINFORCE or GRPO’s 1/σ allows the model to make better progress from low initial pass rates and better… pic.twitter.com/sJCAlsezeqMaxRL is a slick one line change to GRPO that optimizes a maximum likelihood objective instead of expected reward Scaling advantages with 1/μ as opposed to traditional REINFORCE or GRPO’s 1/σ allows the model to make better progress from low initial pass rates and better
-

Automatic Prompt Caching API Feature Eliminates Manual Cache Points
By
–
Huge quality of life upgrade for devs: We've added automatic prompt caching to the API which means you no longer have to set cache points in your requests!
-
Gemini 3.1 Pro Doubles Reasoning Capability on ARC-AGI-2
By
–
Introducing Gemini 3.1 Pro 🚀
— Google AI (@GoogleAI) 19 février 2026
3.1 Pro represents a major step forward in core reasoning. It scored 77.1% (more than doubling 3 Pro’s score) on ARC-AGI-2, the benchmark that evaluates a model's ability to solve new logic patterns and work through challenges it hasn’t encountered… pic.twitter.com/8HOPoji7i5Introducing Gemini 3.1 Pro 3.1 Pro represents a major step forward in core reasoning. It scored 77.1% (more than doubling 3 Pro’s score) on ARC-AGI-2, the benchmark that evaluates a model's ability to solve new logic patterns and work through challenges it hasn’t encountered
-

Repeating Prompts Boosts Non-Reasoning Model Performance
By
–
now trending on alphaXiv when using non-reasoning model, simply repeating your prompt improves performance. basically 1-10% absolute improvement, depending on prompt ordering or the model. And this applies to every model, it wouldn't create extra latency or generated
-
Three Ways to Optimize LangSmith Agent Memory and Performance
By
–
LangSmith Agent Builder uses memory to improve with feedback. Three practical ways to get the most out of memory: → Tell your agent to remember what works
→ Use skills to give it specialized context when needed
→ Edit its instructions directly when that's faster Full -
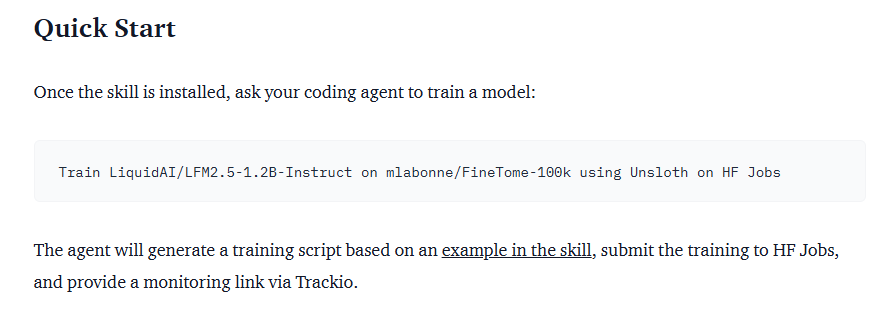
Fine-tune AI Models Without GPU Using Claude Code and Unsloth
By
–
Great application of skills: post-train models directly from Claude Code or Codex. No code, no GPU required. We fine-tuned LFM2.5-1.2B-Instruct with just a prompt 👀 Ben Burtenshaw (@ben_burtenshaw) You can finetune AI models with Unsloth + Hugging Face, and right now it’s free! We're giving away GPU credits on HF Jobs + Unsloth. Train a 1.2B model like @liquidai LFM2.5-1.2B with one command. Ship it to your phone, laptop, or API. No infra. No setup. Just prompt your coding agent and go. — https://nitter.net/ben_burtenshaw/status/2024552060558229858#m
→ View original post on X — @maximelabonne, 2026-02-19 18:47 UTC
-

Google drops Gemini 3.1 Pro with 77.1% ARC-AGI-2 score
By
–
BREAKING: Google just dropped Gemini 3.1 Pro. 77.1% on ARC-AGI-2. More than double the reasoning of 3 Pro. This changes everything. Here's what you need to know: First, what is ARC-AGI-2? It's the hardest AI benchmark on the planet. It tests whether a model can solve
-
Zai API reliability concerns following GLM5 launch
By
–
This is a benchmark-specific timeout, I terminate them if they get stuck with no sign of making progress. The Zai API has not been so reliable since GLM5 launch, but much better in the past 24h-36h.

