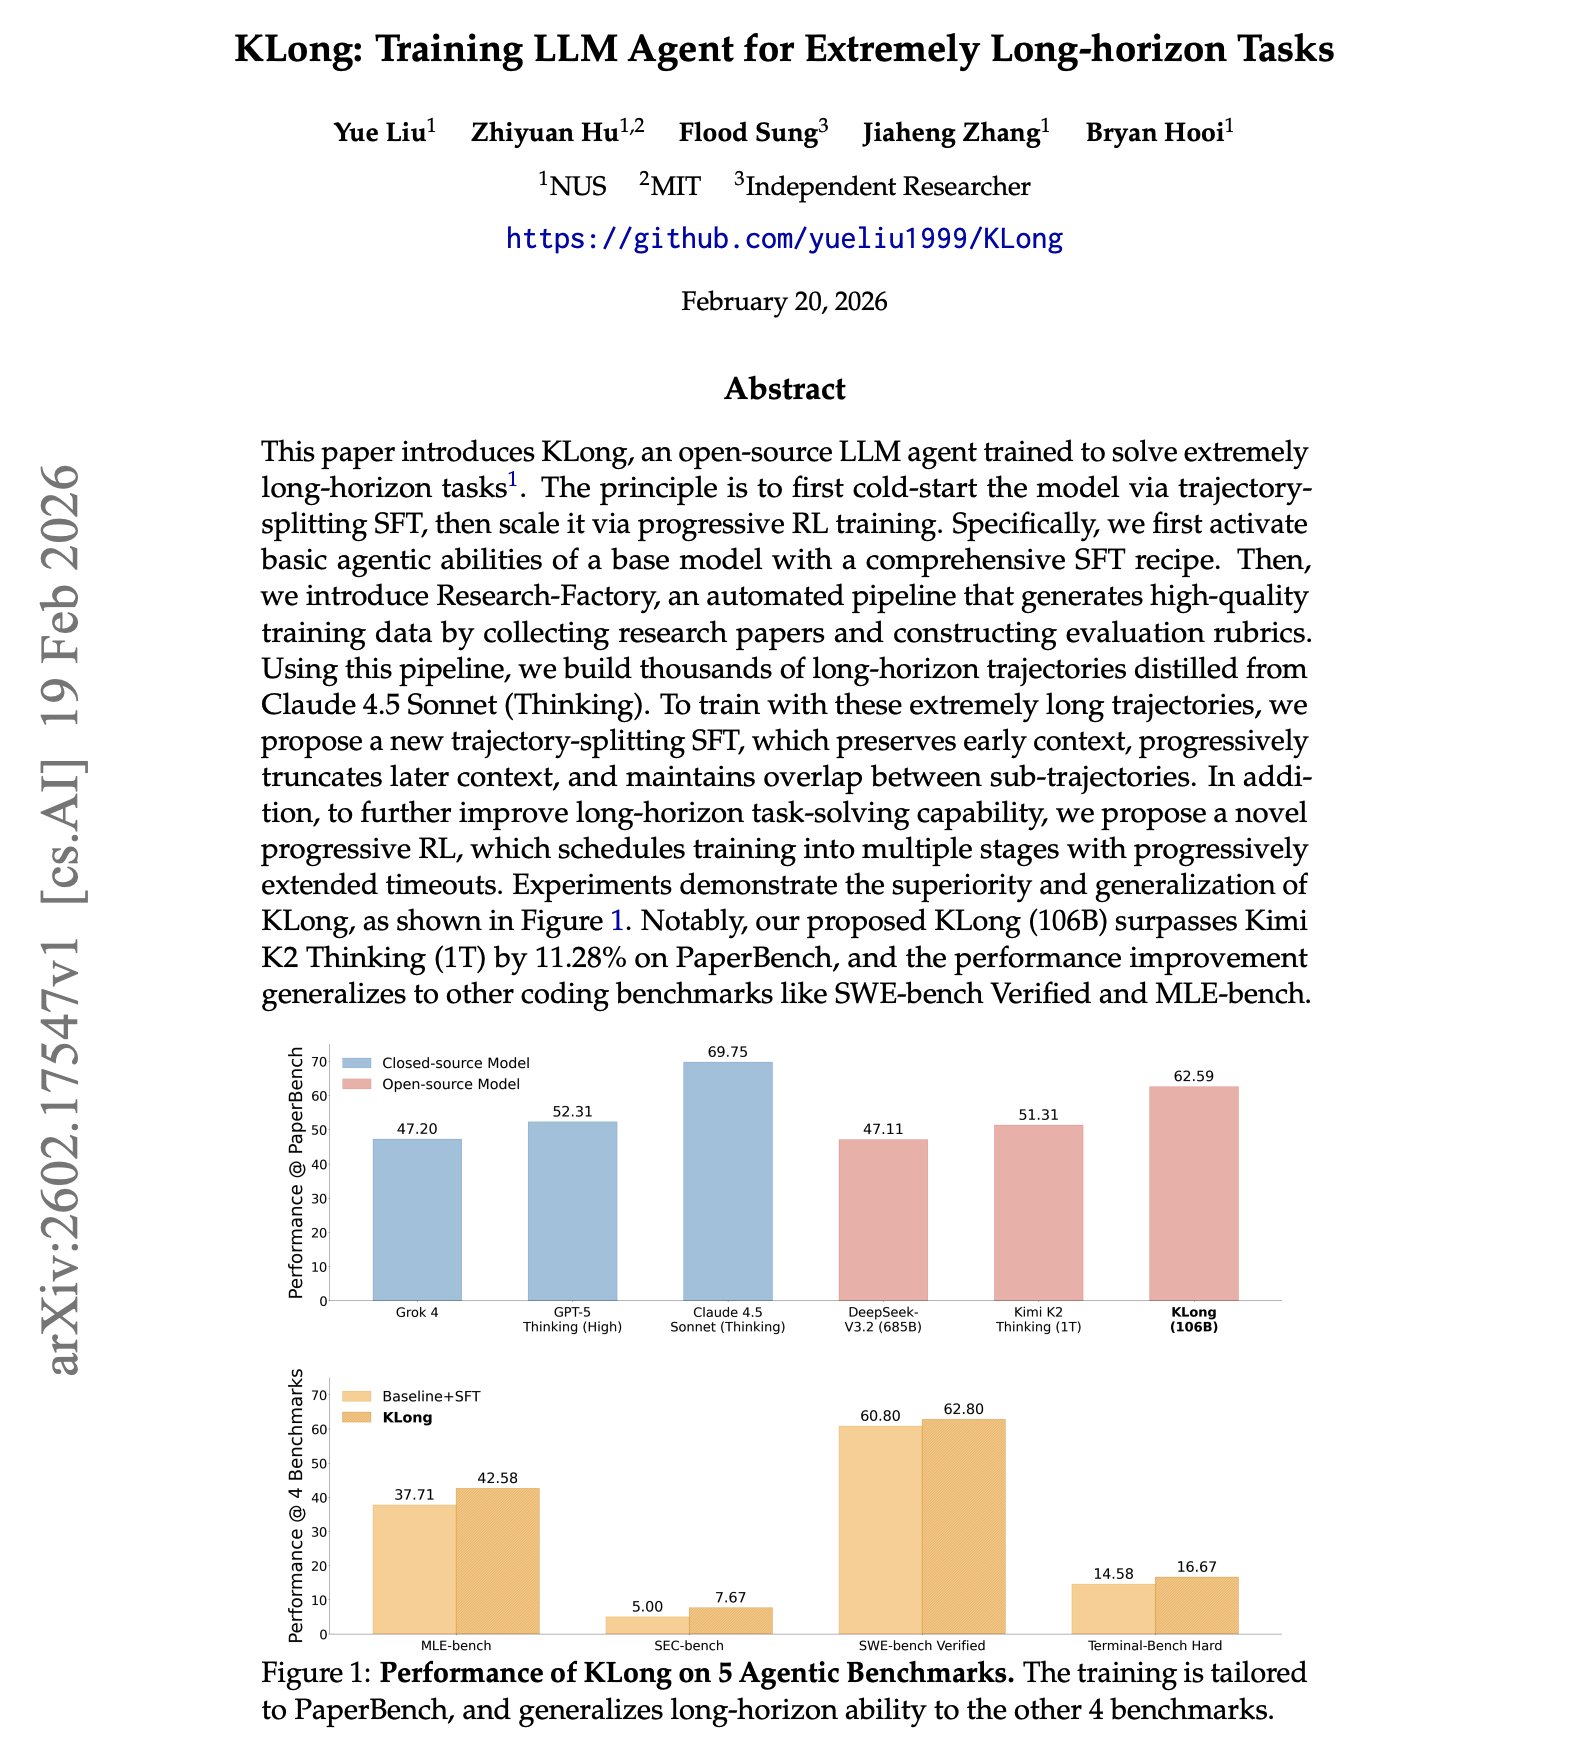
Training LLM agents for extremely long-horizon tasks remains an open challenge. Most agent training pipelines struggle with extended-duration trajectories. Context gets lost, rewards are sparse, and the learning signal degrades over long sequences. KLong tackles this with a
LLMS
-
AI Impact on Professional Roles and Developer Growth Trends
By
–
Do you extend that same rationale to, say, marketing roles? Science? Education? Is there a line of expertise that goes away? And what is your data for not having more builders (your last statement) – all codex and Claude code and openclaw signs are pointing in the opposite
-

GGML joins Hugging Face platform
By
–
Thrilled to have GGML with us going forward! Read the announcement blog https://
huggingface.co/blog/ggml-join
s-hf
… -

India AI Impact Summit: Cohere Launches Tiny Aya and Ethical AI Commitments
By
–


The India AI Impact Summit was a week of critical conversations – from scaling frontier AI responsibly to advancing language accessibility. With Tiny Aya’s launch and the New Delhi commitments, Cohere is committed to driving inclusive, ethical enterprise AI forward.
-
Using domain knowledge to improve LLM model outputs
By
–
The domain knowledge does help steer the models because they don’t go to the best solutions by default
-
Using Claude, Codex, and Gemini for an AI-powered development workflow
By
–
I usually use Claude to ideate and drive – then usually a few codex sessions to implement, and Gemini for long context reviews and spatial tasks codex struggles with
-
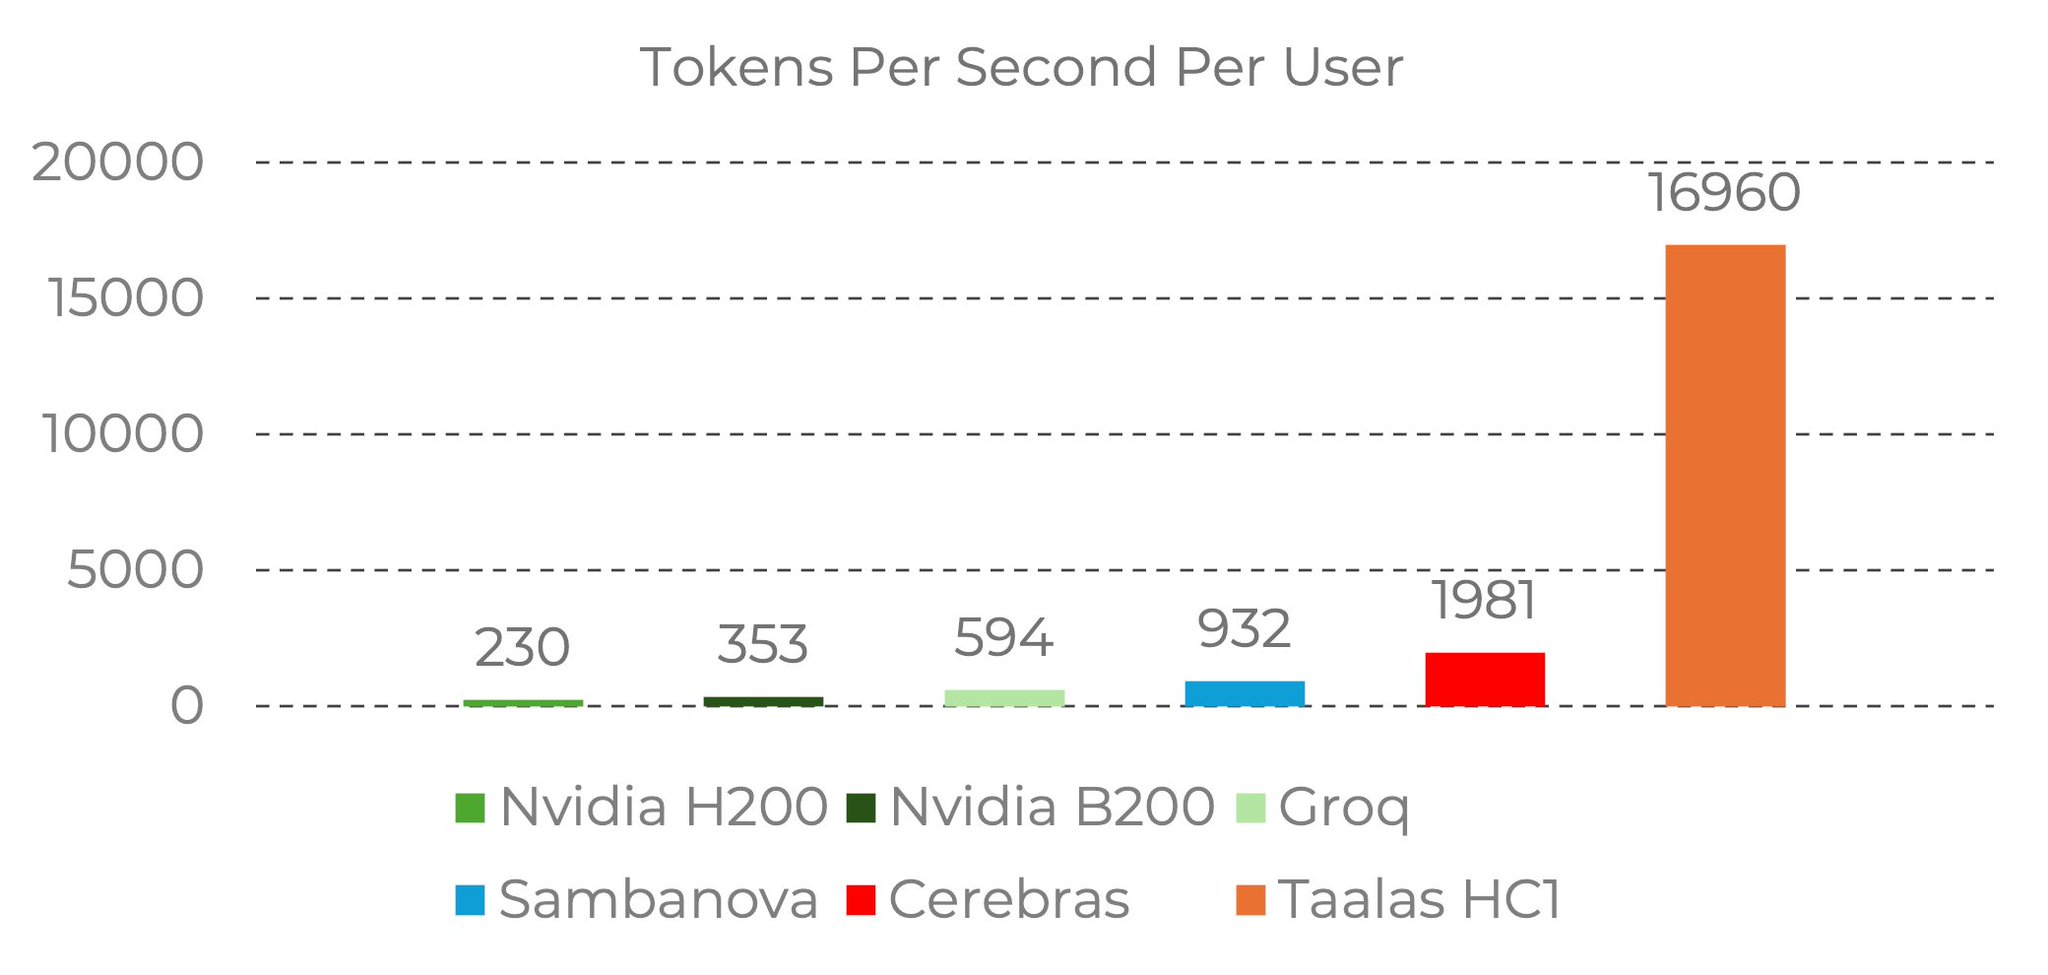
Custom Taalas hardware runs Llama-3.1-8B at 17k tokens per second
By
–
Custom hardware from Taalas runs Llama-3.1-8B, at 17k tokens per second
17k Absolutely insane (For the record Cerebras is crazy good and they're at 2k on the same model)
And latency is very low too! Their chatbot is here: https://
chatjimmy.ai It's genuinely a eerie -
The impact of llama.cpp on LLM proliferation and accessibility
By
–
I'd go to the extent that if it wasn't for @ggerganov and llama.cpp contributors we'd have significantly less proliferation of LLMs in day-to-day! He really kick started a revolution back in 2023
-
Language Models Acquire Reasoning Through Reinforcement Learning Training
By
–
The models will acquire some amount of verbal reasoning just from the language modelling objective. But reinforcement learning training that specifically targets reasoning paths does give you something quite different.
-
Gemini models reasoning behavior and objective function optimization
By
–
This gets tricky and I'll have trouble answering well in non-premium tweets. If you use a Gemini model and turn off the reasoning, it will 'reason' in the output space instead if you let it. What matters is the objective function and the training protocol