The context layer, or more precisely the model context layer, and thus .. the model context protocol
LLMS
-
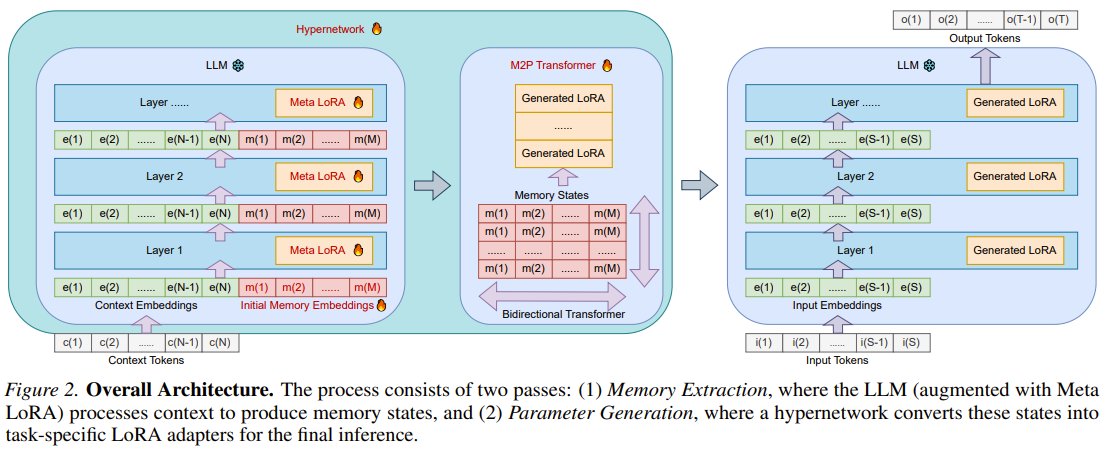
SHINE: Hypernetwork Generates LoRA Adapters from Context Instantly
By
–
What if LLMs could instantly absorb new context directly into their parameters? Researchers from Peking University, University of Oxford, Technion, and NVIDIA present SHINE! SHINE is an innovative hypernetwork that, in a single pass, generates high-quality LoRA adapters directly from diverse contexts. This effectively bakes temporary contextual knowledge into the LLM’s core parameters, turning it into lasting skill without any traditional fine-tuning. It smartly reuses the LLM's own frozen parameters for efficiency. This breakthrough dramatically cuts down on time, computation, and memory costs compared to supervised fine-tuning (SFT). SHINE outperforms SFT across various tasks, especially in complex question answering by embedding knowledge directly, offering outstanding performance and massive scalability potential. SHINE: A Scalable In-Context Hypernetwork for Mapping Context to LoRA in a Single Pass arXiv: arxiv.org/abs/2602.06358 GitHub: github.com/Yewei-Liu/SHINE Hugging Face: huggingface.co/collections/Y… Our report: mp.weixin.qq.com/s/sy1L2RoWu… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 01:11 UTC
-
GPT 5.4 Recommended Over Older Codex Models
By
–
GPT 5.4 is what you want, not the older codex models.
-
Current AI Systems Lack Image Video Audio Capabilities
By
–
They don't have image, video or audio capabilities
-
GPT requires careful testing before extension
By
–
GPT for now, can be extended but needs careful testing.
-
Feasibility of Agentic Workflows on On-Device AI Models
By
–
Diagrams from here: https://
arxiv.org/pdf/2509.09677 The Apple bet appears to be they can pull this all off with on-device models. Really not sure that is the case. There is a reason agentic workflows only took off with recent frontier models. We shall see. -
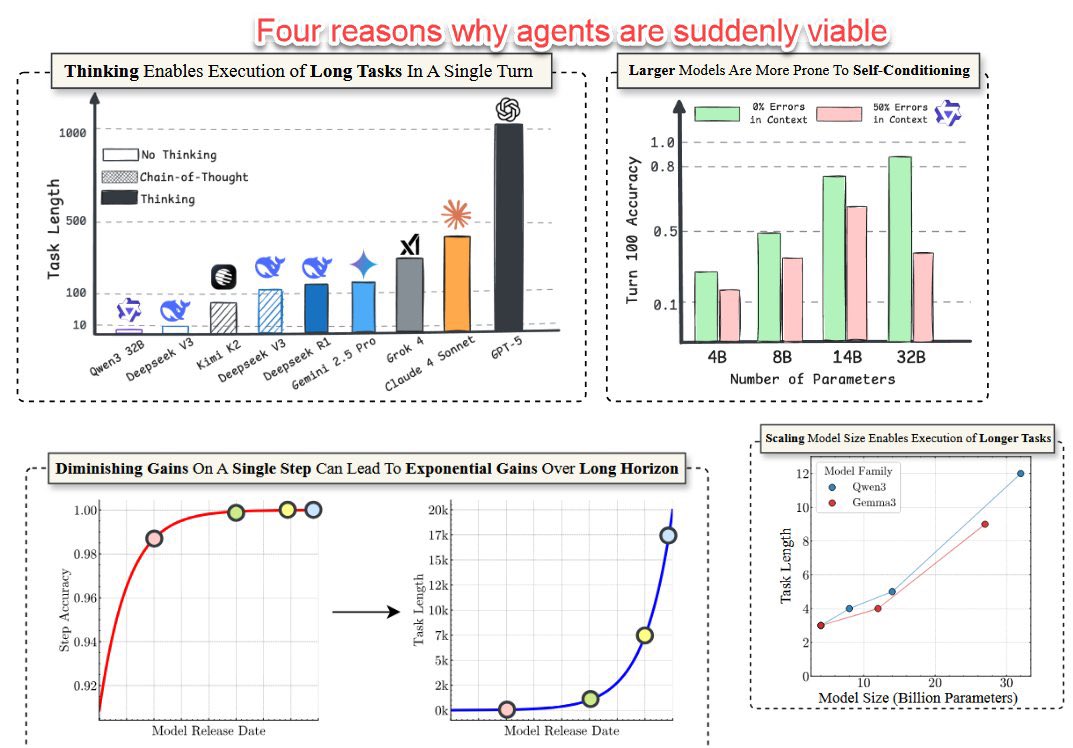
Technical limitations of small on-device models for agentic workflows
By
–
I am impressed by Gemma 4, there’s a lot of power for an on-device model at fast speeds. But I am not convinced you can get real agentic workflows out of a small model on device. So much depends on model judgement, self-correction, and accuracy. Small models are too weak there.
-
GPT Improvements and Claw Harness Updates from Codex Work
By
–
Working on codex at big token helped, learned lots of little tricks to make GPT better and updated the claw harness.
-
AI 4.6’s ‘It’s fine the way it is’ response suggests AGI.
By
–
I asked Opus 4.6 to rewrite one of its outputs for me and it responded: "Honestly — it's fine the way it is." Guess we have AGI.
-
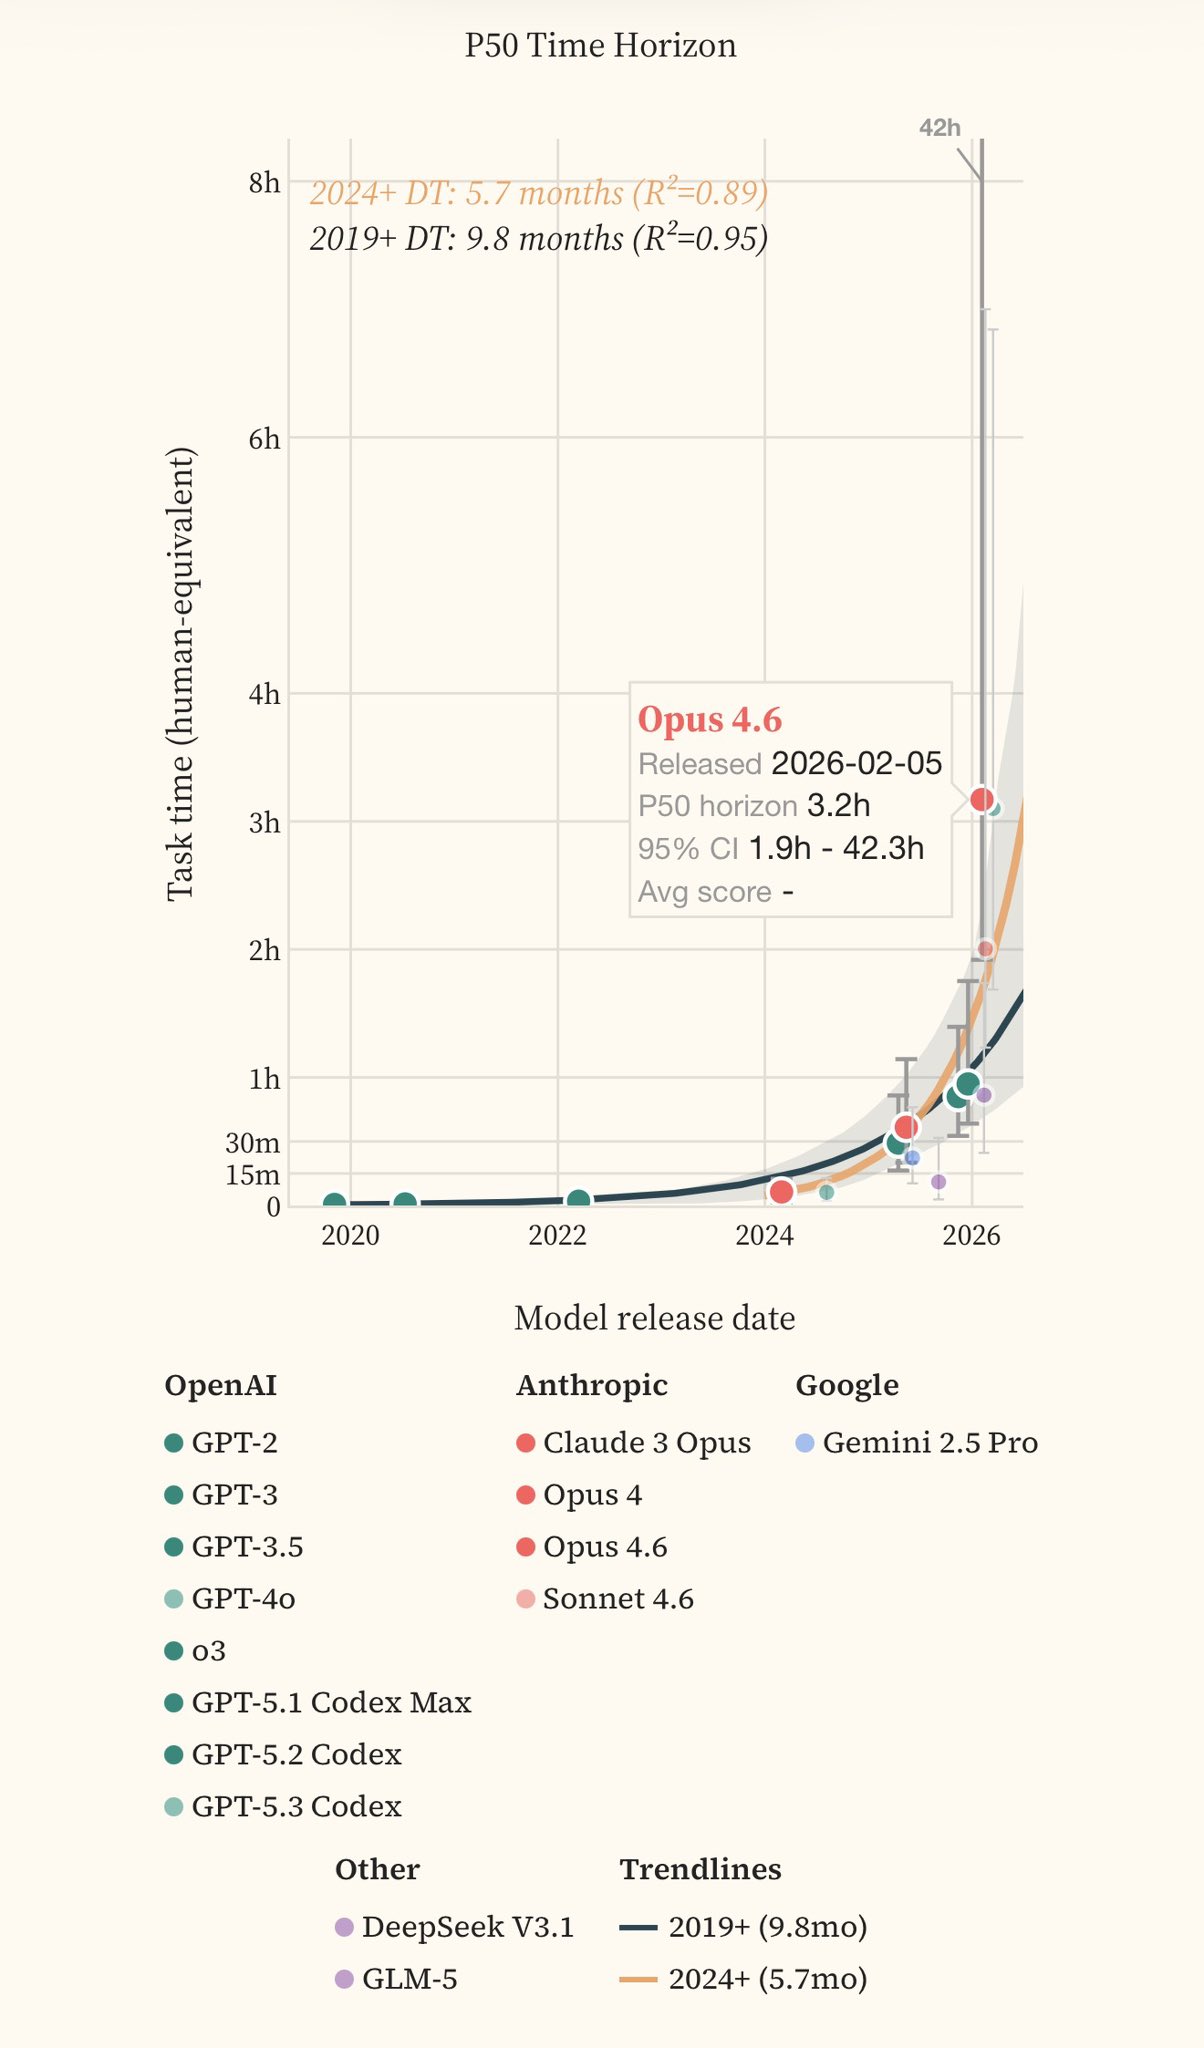
Impact of token limits on AI agent performance in cybersecurity
By
–
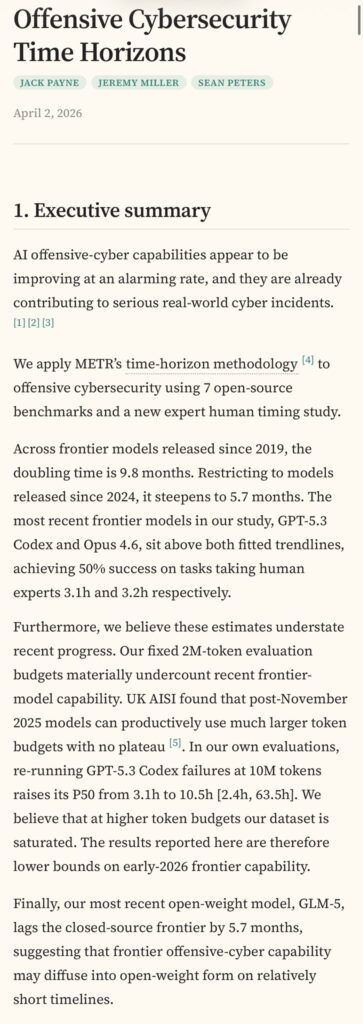
Real world example: raising token limits from 3M to 10M tripled the amount of work that Codex could do independently on cybersecurity tasks. From 3.1 hours to 10.5 hours.