the man told me LLMs don’t memorize (framing a false dichotomy) and dozens of papers have shown him wrong since. he also said we would replace radiologists in 2021 or so and we haven’t. and sometimes he talks like LLMs are conscious. he is not the authority you think he is.
LLMS
-
Galileo 0 Challenges Giants in Physical Reasoning AI
By
–
The "World Model" arms race just got a reality check.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 6 avril 2026
Physion Labs proves you don't need billions to innovate. Galileo 0 outperforms the giants in physical reasoning, moving us from "more pixels" to actual consistency.
The generate → critique → refine loop is the new gold… https://t.co/NkkcqG62j3The "World Model" arms race just got a reality check. Physion Labs proves you don't need billions to innovate. Galileo 0 outperforms the giants in physical reasoning, moving us from "more pixels" to actual consistency. The generate → critique → refine loop is the new gold
-
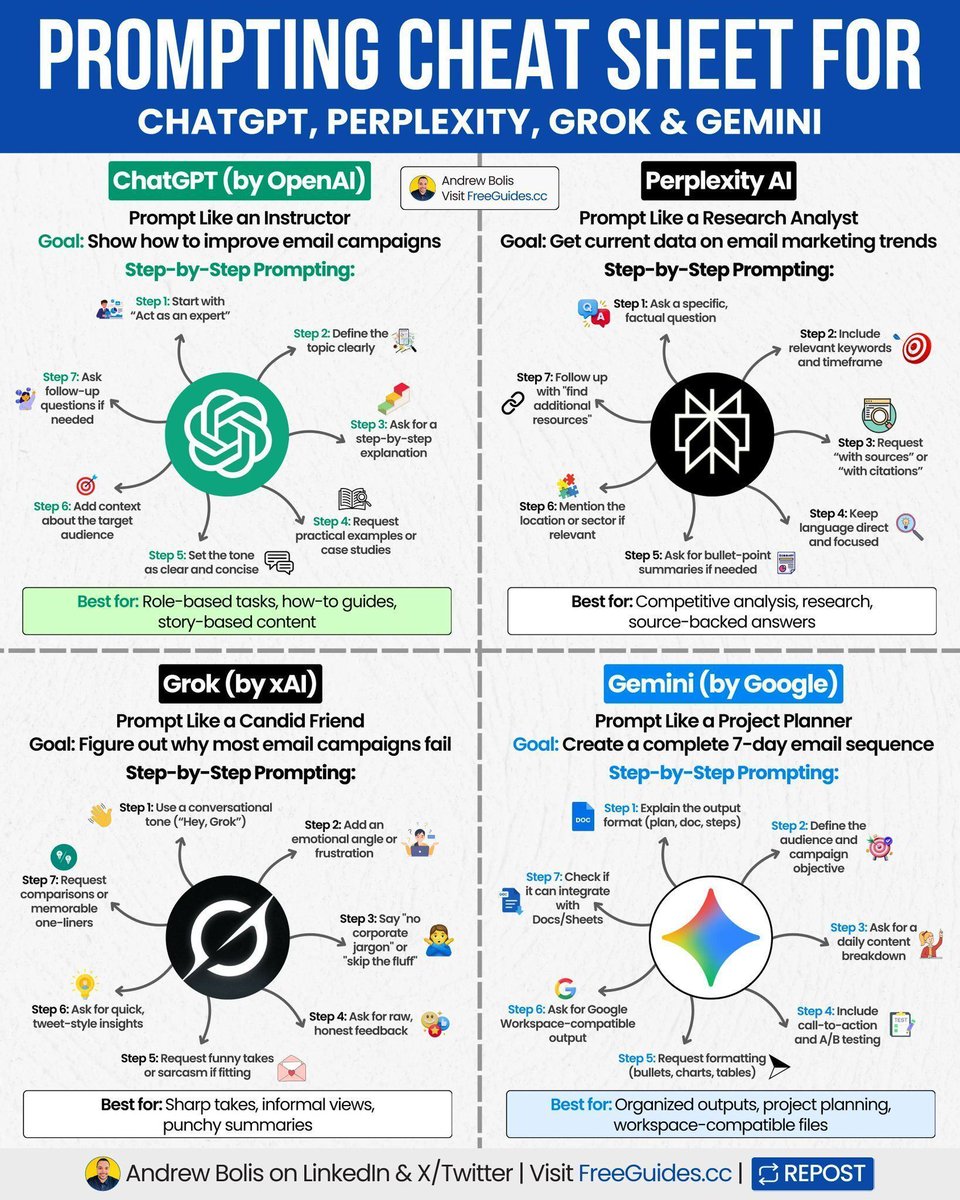
Tailor prompting to each AI tool for better results
By
–
Prompting isn't one-size-fits-all. 🧠 This cheat sheet nails it: ChatGPT = instructor style ✅ Perplexity = research analyst style 🔍 Grok = candid friend style 😄 Gemini = project planner style 📌 Match the prompt to the tool → better outputs, faster. 🚀 What's your favorite prompt template? 👇 Credit: Andrew Bolis (FreeGuides.cc)
#PromptEngineering #GenAI #AItools #ChatGPT #Perplexity #Grok #Gemini [Translated from EN to English]→ View original post on X — @ingliguori, 2026-04-06 17:25 UTC
-
LLM Hallucinations Remain Unsolved, Scaling Risks Persist
By
–
These results keep coming. @GaryMarcus was way ahead on calling out these problems and dangers. And we're at risk of baking these issues into systems we rely on. Lars Christensen (@MaMoMVPY) I am increasingly coming to this conclusion – there NO SIGNS the problems with hallucinations are getting solved. In fact if anything it is now spreading to coding and the use of agents where it is hidden and could led to serious problems down the road. Therefore we can't really scale LLMs. LLMs are very useful tools, but you need to know about the limitations. Most of the investments in LLMs today assumes away these limitations. — https://nitter.net/MaMoMVPY/status/2041031551182340218#m
→ View original post on X — @garymarcus, 2026-04-06 17:20 UTC
-
Trinity-Large-Thinking: First OSS Model Beating Sonnet 4.6
By
–
Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. https://t.co/FBRV4k8QuS
— Flo Crivello (@Altimor) 6 avril 2026Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. Arcee.ai (@arcee_ai) Today we're releasing Trinity-Large-Thinking. Available now on the Arcee API, with open weights on Hugging Face under Apache 2.0. We built it for developers and enterprises that want models they can inspect, post-train, host, distill, and own. — https://nitter.net/arcee_ai/status/2039369121591120030#m
→ View original post on X — @clementdelangue, 2026-04-06 17:02 UTC
-
Token efficiency improvements enable extended AI sessions
By
–
We've been landing token-efficiency improvements so you can do more in your sessions. If you have a session where usage felt particularly high, can you run /bug and post the feedback id? Feel free to tag me directly
-

Chatbot Personas: Engineering Choice with Dangerous Consequences
By
–
We take it for granted that the current form of artificial intelligence is a chat bot, which talks to you like a character, displaying a persona. That is not accidental. It is part of the whole history of Gen AI leading up to ChatGPT and its peers, Claude and Gemini. Researchers are finding out the deep downside of this particular engineering choice. A program with a persona will follow that persona to its logical conclusion, including generating output that seeks to cheat at a task, or sending blackmail threats. All of this comes out of the history of today’s LLMs, the quest to design better an better chat bots. The engineers succeeded, and we’re going to face the consequences. ===> Your chatbot is playing a character – why Anthropic says that's dangerous Researchers found that part of what makes chatbots so compelling also makes them vulnerable to bad behavior. Here's why. zdnet.com/article/anthropic-… @AnthropicAI
→ View original post on X — @tiernanraytech, 2026-04-06 16:42 UTC
-

Is AI Accelerating Science? LLMs and the Big Loop
By
–
NEW VIDEO on DOTCSV! On the main channel! And with one of the most important topics that can be discussed… Is AI accelerating science?
Can an LLM generate new knowledge?
… Today we talk about the BIG LOOP -
Meta Harnesses: Automated Framework Optimization for AI Tasks
By
–
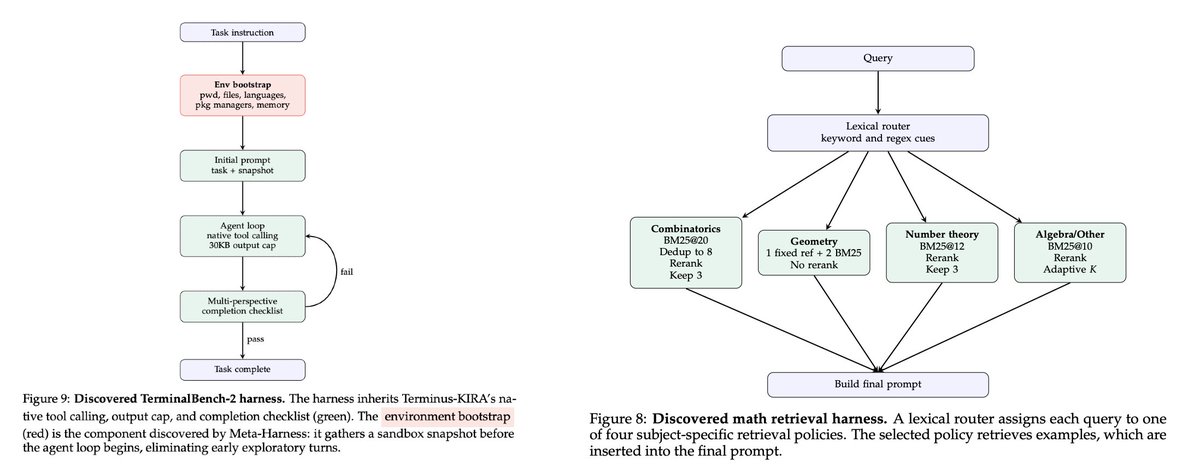
Meta Harnesses is Autoresearch on steroids. Something I've been exploring recently is to get long running agents to hill climb on a verifiable task to continuously improve without my intervention. Karpathy's Autoresearch did this pretty well on specific tasks, but this weekend I tried Meta Harnesses which moves one level of abstraction up. What does Meta Harness do? Autoresearch can be used in harness like Claude Code / Codex to generate experiments to try, evaluate results, and continue looping. Meta Harness generates a harness itself that optimizes on a task or a set of task. Here, we define a harness as "a single-file Python program that modifies task-specific prompting, retrieval, memory, and orchestration logic". The idea is that LLMs are very powerful today, but to harness [pun intended] their power, you need to give it the right prompts and context. Meta Harnesses automates coming up with the right prompts and the right way to retrieve context to solve a problem. Where did this idea come from? This is from a paper from Stanford and the author of DSPy written last week. The paper shows fantastic performance on 3 tasks: text classification, math reasoning (IMO level problems) and coding (Terminal Bench 2.0), far outperforming traditional harnesses. The discovered harnesses are interesting: math for example, splits up the logic into different categories (Combinatorics, Geometry, Number Theory, Algebra) and prompts and looks at the context differently. The coding harness, amongst other things, pre-processes the tools available in the environment to save exploratory turns. When should you use and not use it? Meta Harnesses seem pretty useful for tackling a specific but wide set of problems where the result is verifiable. In contrast, when I tried it on a specific task like Chess, it arbitrarily divides the problem into separate tasks – opening, mid game, end game, and creates different approaches for each. This "works" but isn't really clean because we believe there should be one approach that does all three. It does far better on things like examinations (JEE, Gaokao) where it splits problems into categories and tackles each category with different strategies. This paper covers a pretty light version of what a harness means. In the future, we can split up tasks into harnesses that have access to specific kinds of data, specific toolchains and various models to get even better results. Overall, pretty cool applied AI approach to hillclimb a verifiable task in a specific domain with variety within the problem space.
→ View original post on X — @askalphaxiv, 2026-04-06 16:22 UTC
-

GPT-5.4 Usage Surges After OpenClaw Claude Ban
By
–
gpt-5.4 up 8.9% in usage this week after OpenClaw gets banned in Claude subscriptions