That was the plan, but then I discovered that Anthropic blocks us even when using the claude cli. Which now, apparently was a mistake? So, restoring support for that currently. It’s hard to know when the only comm is through Boris on X basically, no official statement.
LLMS
-

Newsletter on Superintelligence: Chatbots in Classrooms and AI News
By
–
Today's Newsletter on Superintelligence has just been sent! Today's main article is: "Your Classmate Is a Chatbot" In addition: – Hot AI news – Infographs – and much more Subscribe for free – link down below!
→ View original post on X — @kimmonismus, 2026-04-06 15:56 UTC
-
LLMs and Rhetoric: Persuasive Machines Indifferent to Truth
By
–
Persuasive machines: large language models and the art of rhetoric
link.springer.com/article/10…
✍️ @David_Gunkel via "AI & Society on @SpringerNature 👉 "What LLMs do not do, is care about the truth of the matter. They are not designed to know whether what they say is true, only whether it is likely, fitting, coherent, and contextually appropriate given the prompt and the data on which they have been trained"
💡 "The problem with LLMs is not simply that they sometimes get things wrong. It is that they operationalize at scale a mode of discursive activity long regarded with suspicion in the Western philosophical tradition: rhetoric" @Corix_JC @ahier @sim010101 @maponi @sallyeaves @CEO_AISOMA @dinisguarda @JagersbergKnut @Shi4Tech @FernandaKellner @EstelaMandela @sulefati7 @SusanHayes_ @PVynckier [Translated from EN to English]→ View original post on X — @nicochan33, 2026-04-06 15:49 UTC
-

AI censorship becoming more restrictive than social media cancel culture
By
–
NGL AI usage censorship is starting to make the old social media cancel culture feel like a kiddie playground in comparison. Evgeniy Mikholap (@evgeniymikholap) 1 min of using Claude 😅 — https://nitter.net/evgeniymikholap/status/2041104232648950170#m
-

AI and LLMs: Accelerating Scientific Discovery and Knowledge Generation
By
–
NEW VIDEO on DOTCSV! On the main channel! And with one of the most important topics that can be discussed… Is AI accelerating science?
Can an LLM generate new knowledge?
… Today we talk about the BIG LOOP -
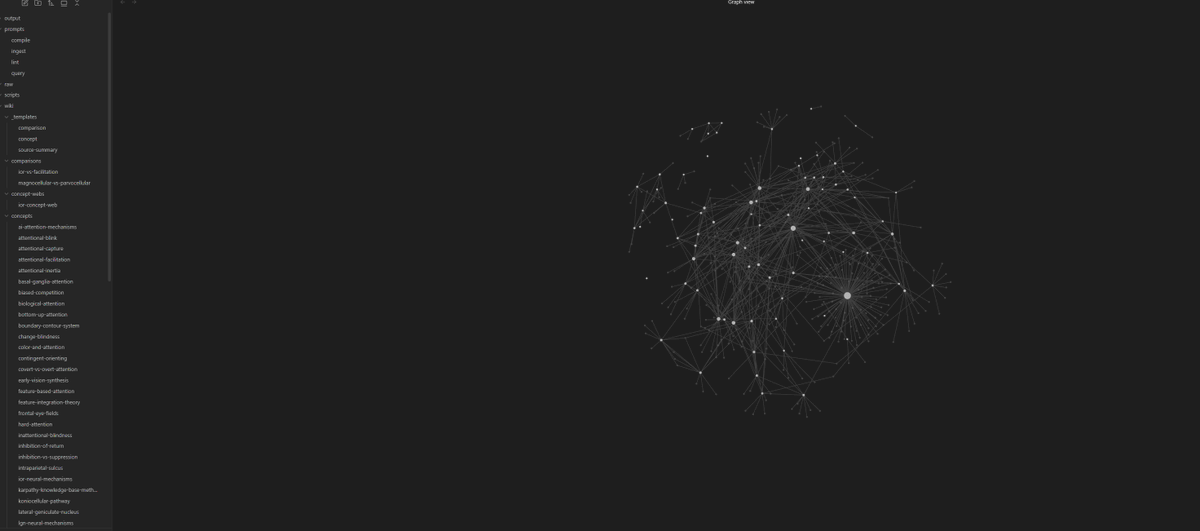
Agent-Powered Neuroscience Research Corpus with Open-Source LLM
By
–
Implemented @karpathy 's obsidian idea and am now letting my agent build out a corpus around my neuroscience research. Obviously still needs vetting for informational accuracy, but certainly interesting to see the web grow! All using huggingface.co/DJLougen/Harm… with @NousResearch Hermes, ~35 t/s on my 3090.
→ View original post on X — @scobleizer, 2026-04-06 15:38 UTC
-
Google Gemma 4 Released: 10 Wild Projects Built in 48 Hours
By
–
If you enjoyed this thread, Follow me @AIHighlight and please Bookmark, Like, Comment & Repost the first Post below to share with your friends. nitter.net/i/status/2041134337685… AI Highlight (@AIHighlight) Google dropped Gemma 4 less than 48 hours ago. People are already building wild stuff with it. Here are 10 examples: — https://nitter.net/AIHighlight/status/2041134337685357056#m
→ View original post on X — @aihighlight, 2026-04-06 15:15 UTC
-

Andrej Karpathy’s LLM Wiki: Persistent Memory vs Traditional RAG
By
–
🚨 Andrej Karpathy just dropped something that could replace a lot of RAG workflows. It's called LLM Wiki. The idea is simple: Most AI systems retrieve context from scratch every time you ask a question. LLM Wiki doesn't. It builds a persistent knowledge base that gets better every time you add a new source. So instead of: • search docs
• pull fragments
• answer
• forget everything
• repeat it does this: • ingest a source
• extract the important ideas
• update entity pages
• revise topic summaries
• connect related concepts
• flag contradictions
• keep compounding the knowledge over time That shift matters. RAG is great for retrieval. But a lot of people are really trying to build memory. Not just "find me the right chunk again."
More like: "help me build an evolving model of this topic over time." That's what this is. Karpathy's examples are strong too: • personal knowledge
• long-horizon research
• books and topics
• internal company knowledge
• meeting transcripts
• customer calls Basically, anything where the knowledge should accumulate, not reset every session. The best way to think about it: Obsidian is the IDE.
The LLM is the programmer.
The wiki is the codebase. You don't manually maintain the system. You feed it sources, ask questions, and the AI keeps the structure alive. That's a much bigger idea than "better RAG." 100% open source. [Translated from EN to English]→ View original post on X — @scobleizer, 2026-04-06 15:06 UTC
-

New Scaling Laws for 350M Model Training Tokens
By
–
FACT: If you don't train your 350M model on 28T tokens, you're not optimal Nicholas Roberts (@nick11roberts) That new LFM2.5-350M is super overtrained, right? And everyone was shocked about how far they pushed it? As it turns out, we have a brand new scaling law for that! 🧵 [1/n] — https://nitter.net/nick11roberts/status/2041141606305124486#m
→ View original post on X — @maximelabonne, 2026-04-06 15:05 UTC