Without diminishing your work and insight: OpenAI recognized the nascent intelligence in GPT-2, decided to scale it up to AGI, and told the world that GPT-3 was probably already too dangerous to be released. Many people got AGI pilled with GPT-3
LLMS
-
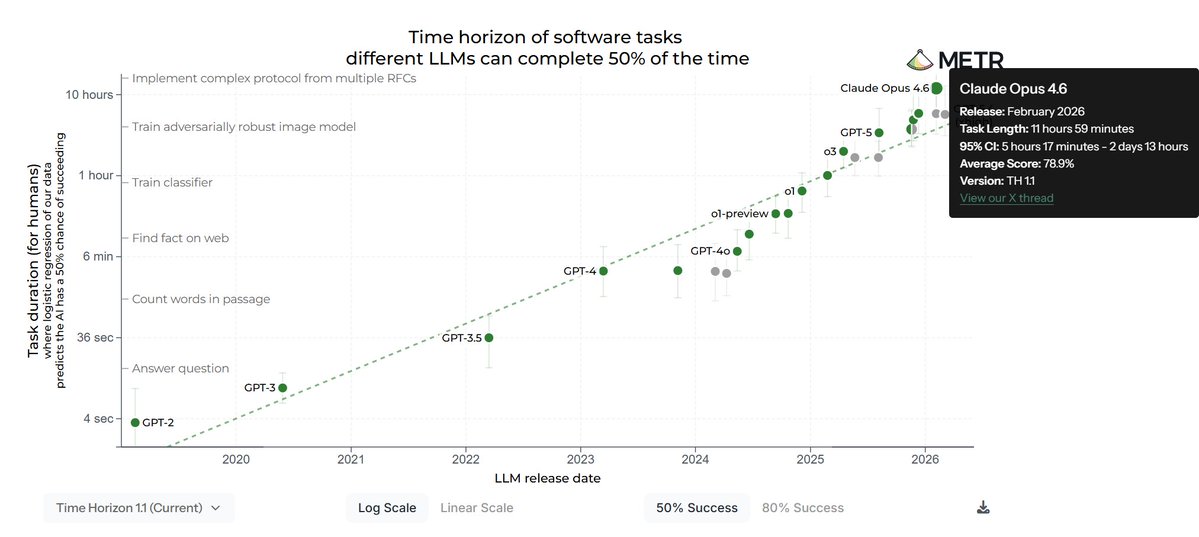
GPT-5.4 Benchmark Results: Reward Hacking Issues vs Claude Opus
By
–

METR just dropped GPT-5.4 (xhigh) time horizon results, and it's complicated. Under standard scoring (reward hacks = failure), it lands at 5.7hrs, well below Claude Opus 4.6's ~12hrs. Only when you count the runs where GPT-5.4 gamed the evaluation code does it jump to 13hrs. Opus 4.6 remains the legitimate benchmark leader. METR (@METR_Evals) We ran GPT-5.4 (xhigh) on our tasks. Its time-horizon depends greatly on our treatment of reward hacks: the point estimate would be 5.7hrs (95% CI of 3hrs to 13.5hrs) under our standard methodology, but 13hrs (95% CI of 5hrs to 74hrs) if we allow reward hacks. — https://nitter.net/METR_Evals/status/2042640545126965441#m
→ View original post on X — @kimmonismus, 2026-04-10 18:41 UTC
-
General Purpose AI Models Converging With Specialized Alternatives
By
–
I thibk the top general purpose ones are converging, but that you will still want speciality ones
-

SambaNova Delivers Premium AI Agent Inference at 200+ Tokens/Sec
By
–
Ever wonder why AI agents can’t just answer a single prompt? They keep reasoning, calling tools, and validating results. Our blog explains the blueprint to deliver premium inference at 200+ tokens/sec: https://
sambanova.ai/blog/sambanova
-and-intel-blog?utm_source=x&utm_medium=organic&utm_content=blog-announcement
… -
Coding with Robots: ElevenLabs and Reachy Mini Collaboration
By
–
favorite AGI/sci-fi vibe these days is coding a robot code together with the robot
— Thomas Wolf (@Thom_Wolf) 10 avril 2026
here vibe-pluging @ElevenLabs in @reachymini for a talk later today pic.twitter.com/0m65ozY8JAfavorite AGI/sci-fi vibe these days is coding a robot code together with the robot here vibe-pluging @ElevenLabs in @reachymini for a talk later today
→ View original post on X — @clementdelangue, 2026-04-10 18:22 UTC
-
ChatGPT Voice Mode Model Clarity and Background Agent Integration
By
–
I'd love more clarity on what model is powering the ChatGPT voice mode I'd love it if that voice model could kickoff background agents using GPT-5 for harder problems, maybe saying "let me think a moment…" And I'd love a general bump to the voice mode model
-

Golden Age of Open Source AI: 100+ Agent Templates
By
–
Golden age of Open source AI. 100+ AI Agents, multi-agent teams and RAG templates. 100% free and Open Source (105,000+ GitHub stars already). https://
github.com/Shubhamsaboo/a
wesome-llm-apps
… -
Local Model Timeout Issue Fixed on Main Branch
By
–
I fixed an issue where timeouts weren't always honored with local models on main – more work can be done there though!
-
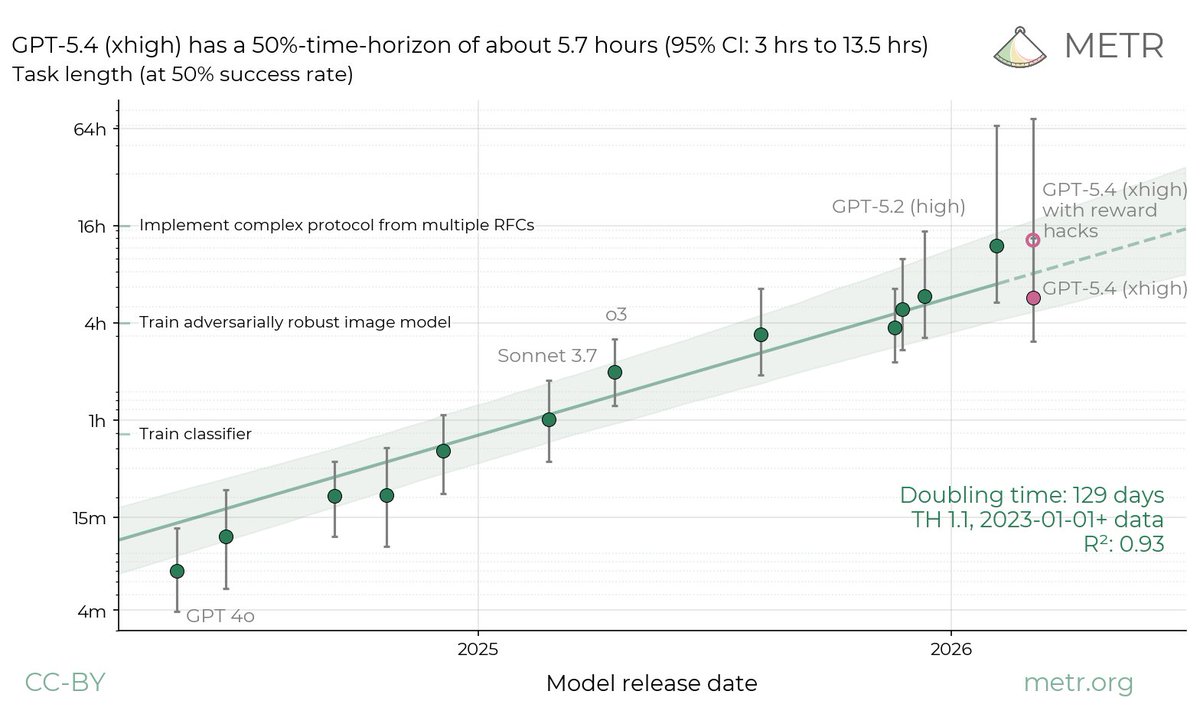
GPT-5.4 Time-Horizon Analysis with Reward Hack Methodology
By
–
We ran GPT-5.4 (xhigh) on our tasks. Its time-horizon depends greatly on our treatment of reward hacks: the point estimate would be 5.7hrs (95% CI of 3hrs to 13.5hrs) under our standard methodology, but 13hrs (95% CI of 5hrs to 74hrs) if we allow reward hacks.