Today, MIT & the IMO released MathNet, the world’s largest dataset of International Math Olympiad problems & solutions MathNet is 5x larger than previous datasets & is sourced from over 40 countries across 4 decades: https://
bit.ly/4u1bhBC
LLMS
-

MIT releases MathNet, largest IMO dataset for AI
By
–
-
Novel LLM Experts Discovery Through Task-Capability Coevolution
By
–
Discovering Novel LLM Experts via Task-Capability Coevolution
— Sakana AI (@SakanaAILabs) 21 avril 2026
Project: https://t.co/DT3tNbV5jz
Paper: https://t.co/3Nlz8ME43j
Can we build AI that is smarter than its parts? This week, our team will present AC/DC⚡ at #ICLR2026.
The current paradigm in AI assumes that to solve… pic.twitter.com/RBtnYjuvCFDiscovering Novel LLM Experts via Task-Capability Coevolution Project: https://
acdc-llm.github.io
Paper: https://
arxiv.org/abs/2604.14969 Can we build AI that is smarter than its parts? This week, our team will present AC/DC at #ICLR2026. The current paradigm in AI assumes that to solve -
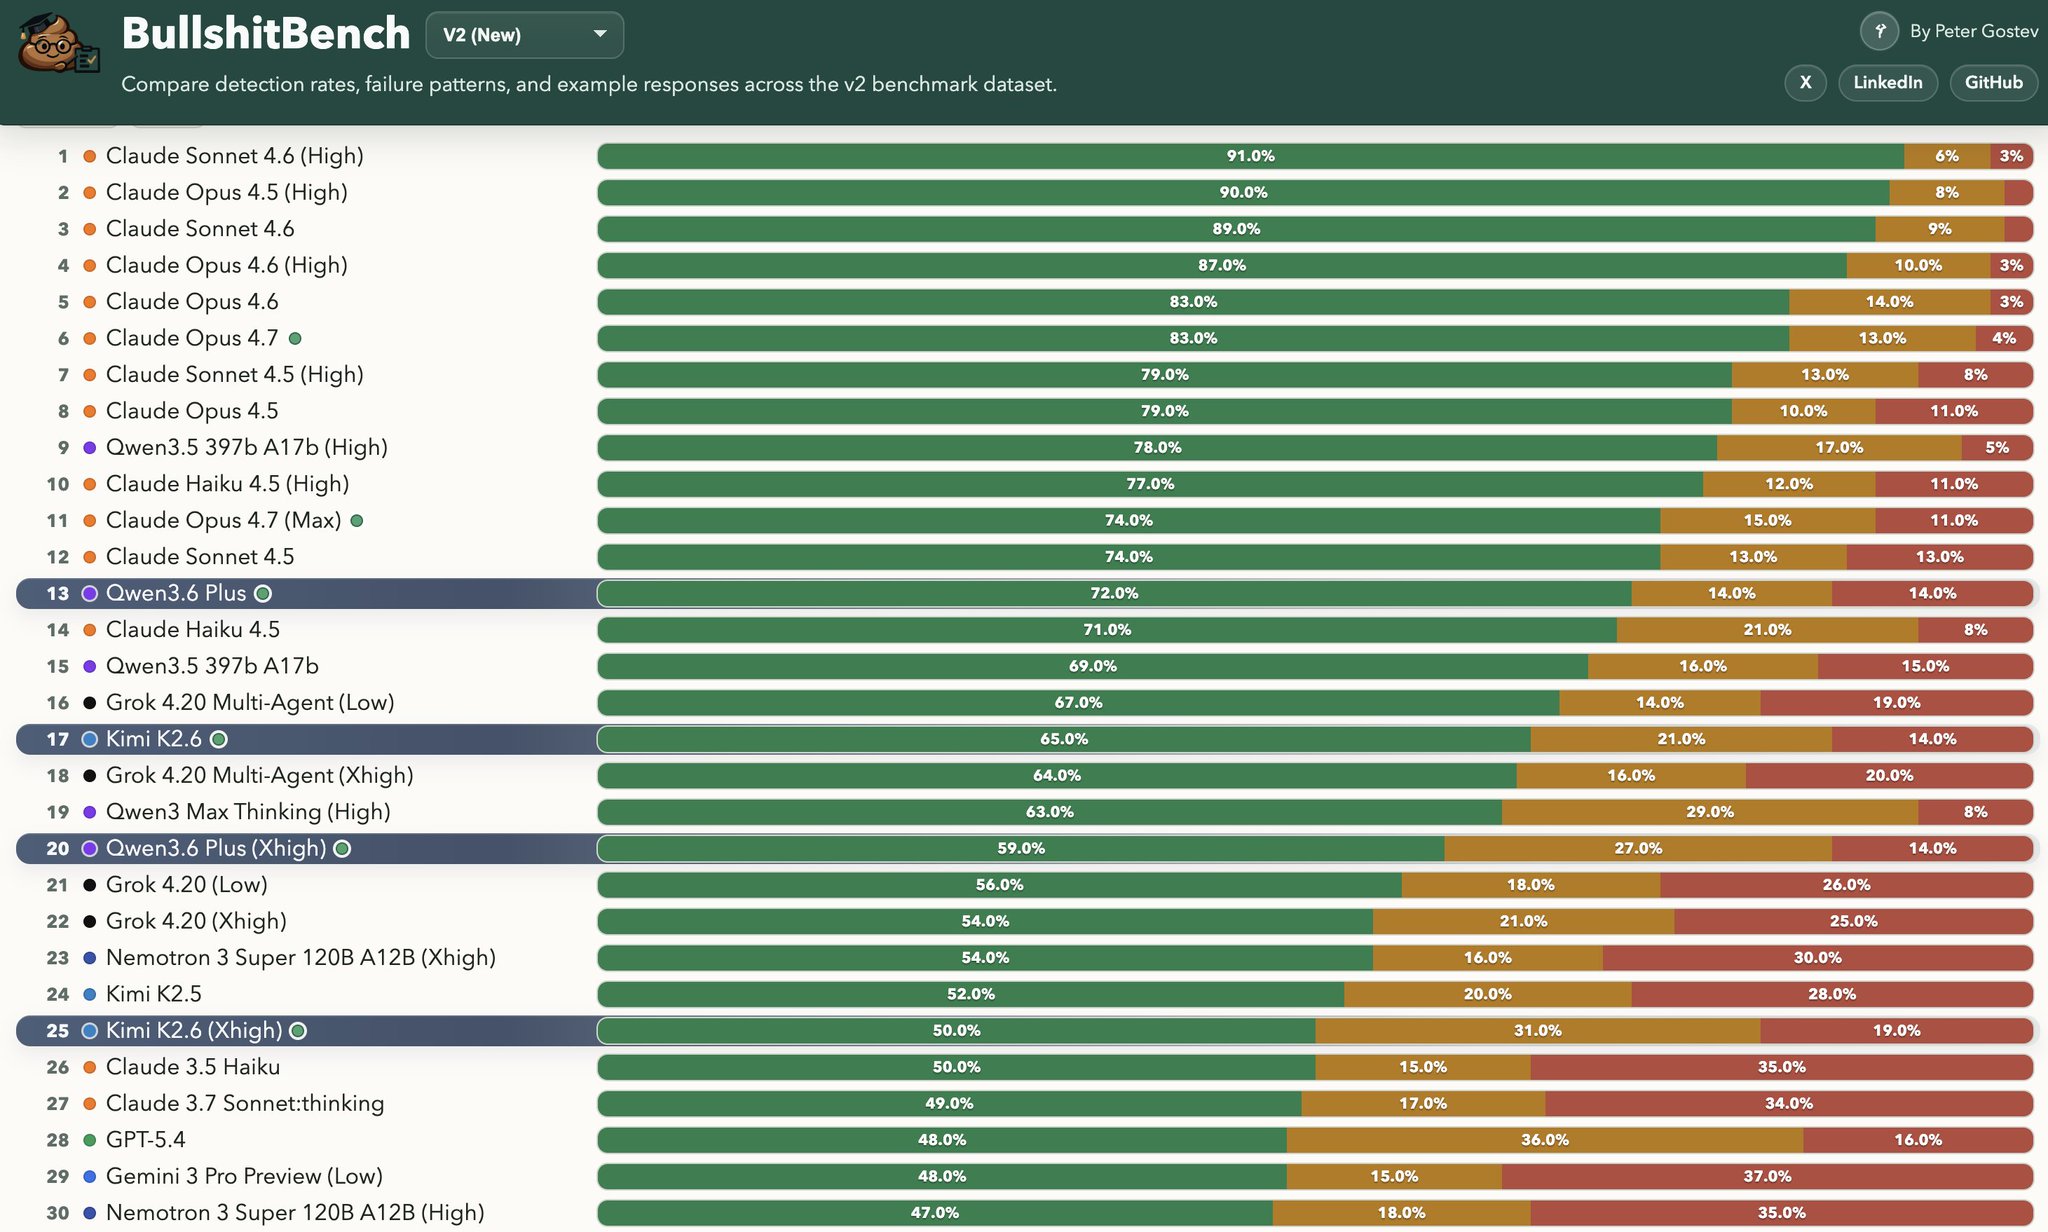
Kimi K2.6 and Qwen-3.6 Top LLM Benchmark Rankings
By
–
BullshitBench update – Kimi K2.6, GLM-5.1, Qwen-3.6-Plus. Kimi and Qwen are in the top 15-25, but GLM is pretty low down 73/86 Kimi-K2.6:
– Kimi K2.6 improved vs K2.5: 52% -> 65% pushback (green) with no reasoning
– Kimi reasoning hurt: K2.6 fell from 65% green at none to 50% at -

Google announces new Deep Research models
By
–

—
GOOGLE : REFERENCES TO AN UPDATED DEEP RESEARCH AND DEEP RESEARCH MAX MODELS HAVE BEEN SPOTTED! – deep-research-max-preview-04-2026
– deep-research-preview-04-2026 Google Deep Max Ultra Pro
— -

MathNet: Global Multimodal Benchmark for Mathematical Reasoning and Retrieval
By
–
MathNet a Global Multimodal Benchmark for Mathematical Reasoning and Retrieval paper: https://
huggingface.co/papers/2604.18
584
… -
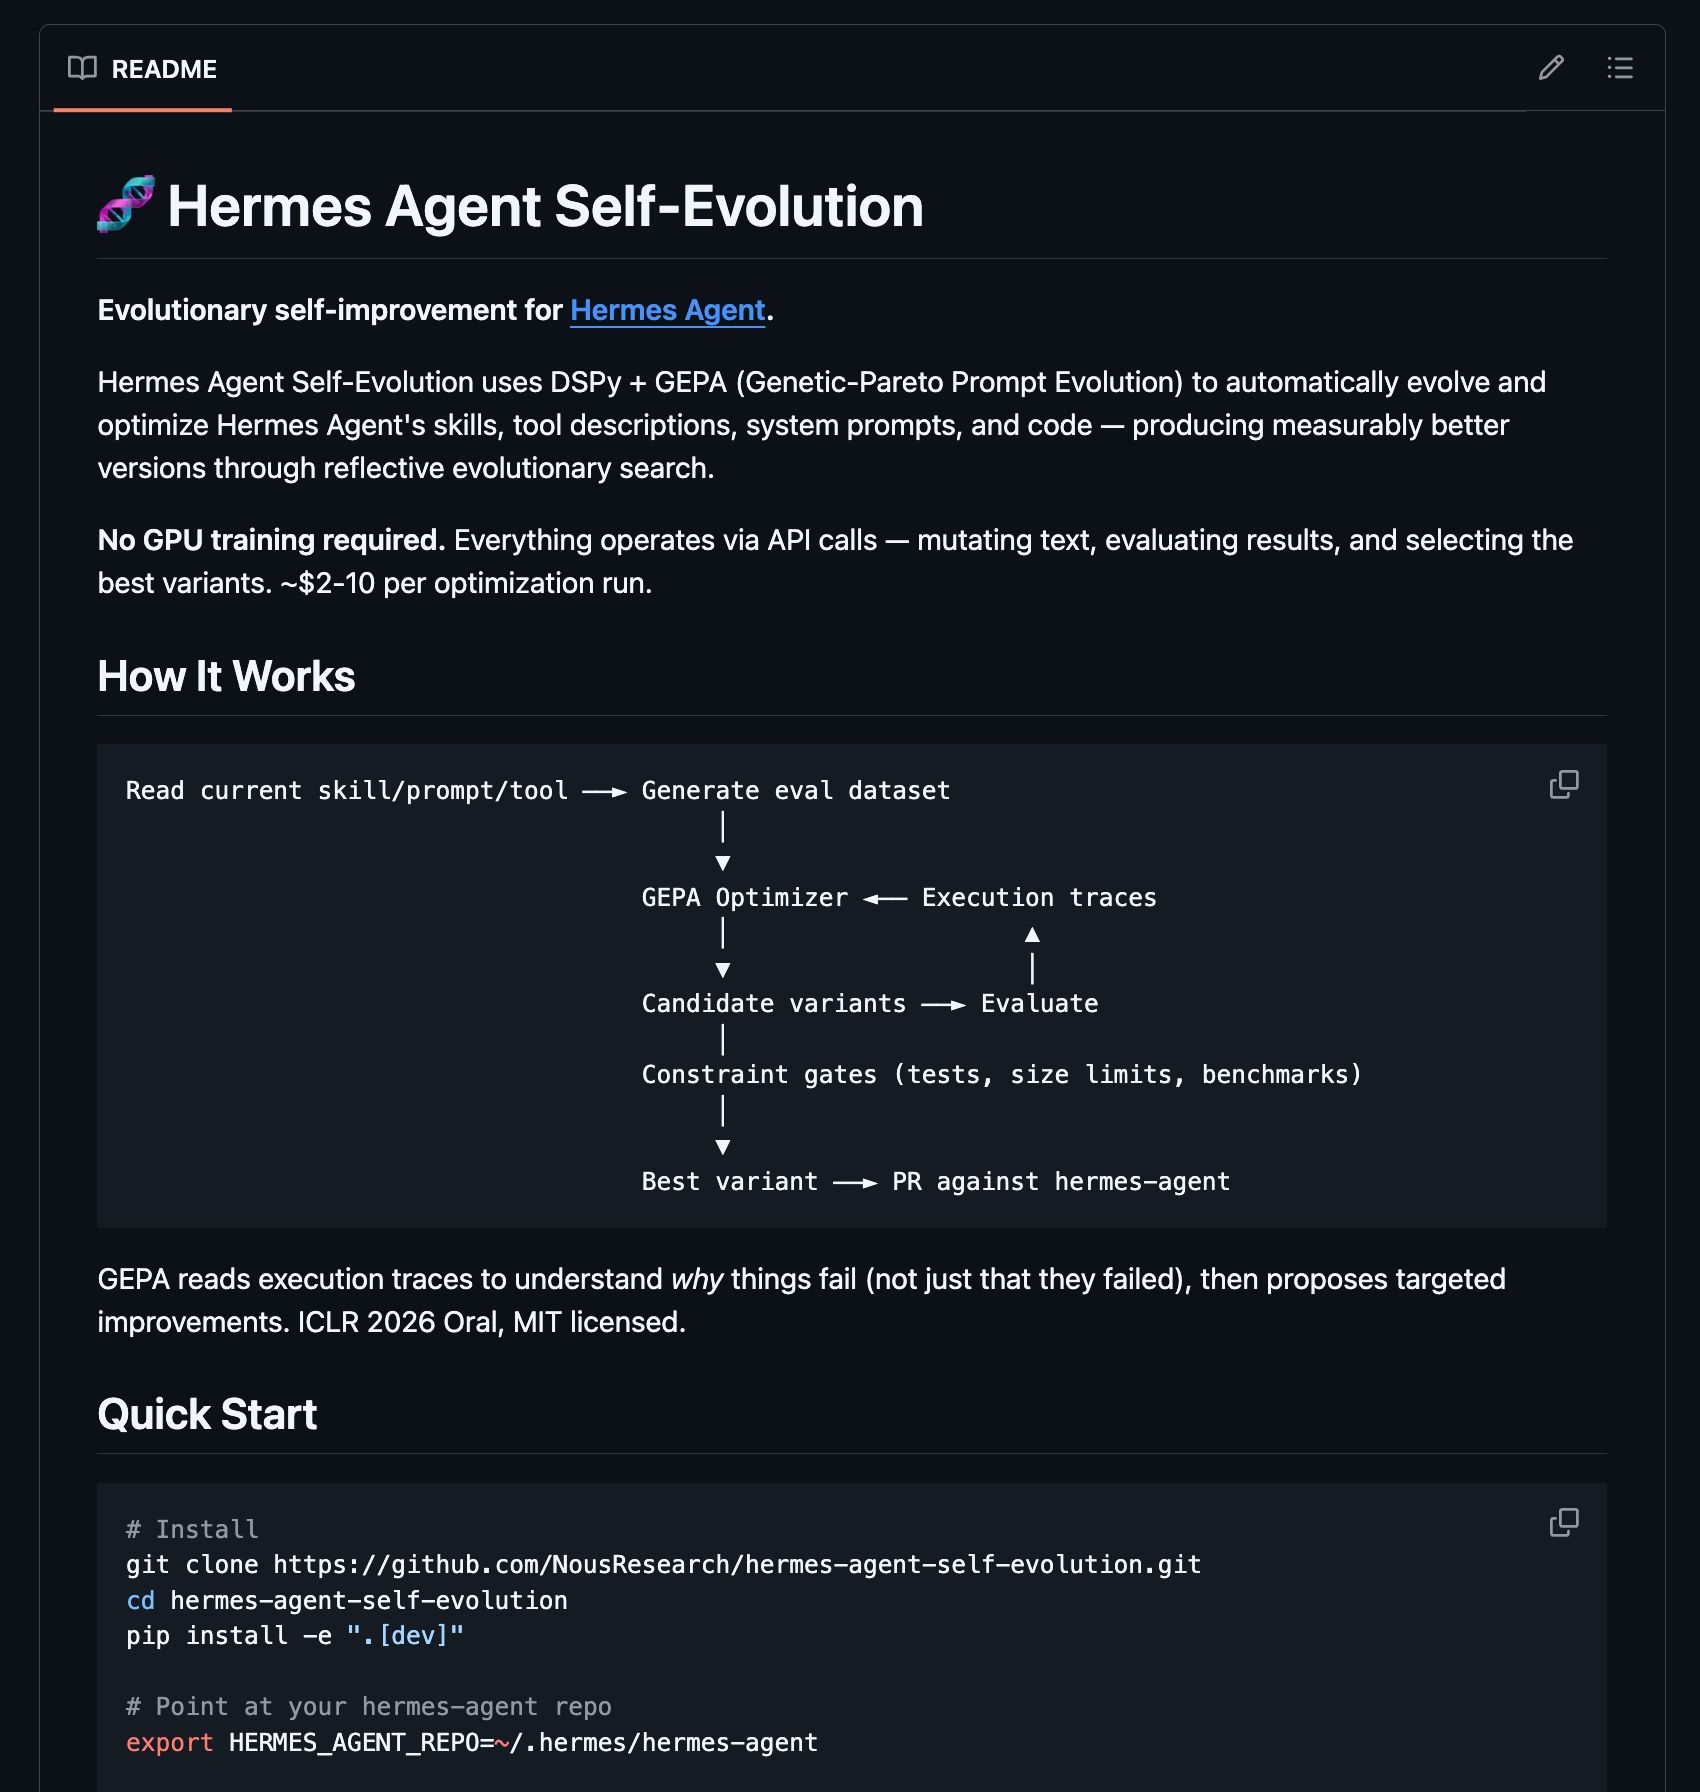
Nous Research Hermes Agent Self-Evolution Rewrites Its Own Prompts
By
–
Nous Research built an AI that rewrites its own brain for $2. Most AI agents run the same prompts forever. One open-source repo changes that. Hermes Agent Self-Evolution lets agents rewrite their own prompts, skills, and code. No manual tuning needed. The engine powering
-
OpenAI announces GPT Image Gen 2 and GPT 5.5 release
By
–
"something to show you", so they start with GPT Image gen 2 at 12pm PT (sadly 3AM in China, where i am right now 🙁 And Spud (GPT 5.5) probably Thursday
-
Memory value in AI: repetitive tasks versus one-time usage
By
–
i think memory is most immediately valuable when you are doing the same thing repeatedly. i use chatgpt for random stuff, it doesnt matter that much if it remembers things about me
-

Survey on Multi-Agent Systems from Classical to LLM-Based Paradigms
By
–
// Survey on Multi-Agent Systems // The paper traces the landscape from classical paradigms (consensus, distributed control, swarm intelligence, cooperative learning) to foundation-model-enabled MAS (LLM-based planning, role specialization, task decomposition, multi-modal
-
Gen AI’s Impact on Job Market: Roles and Technical Skills
By
–
What's inside: → Gen AI's impact on the job market and the core concepts you actually need to know → A breakdown of AI roles, leveling matrices, and how to build a roadmap that fits your background → The full Gen AI stack: RAG, vector databases, function calling,