
How far are we from agents that can self-generate world knowledge? The work proposes an outcome-based reward that measures how much an agent's self-generated world knowledge actually improves its task success rate. The external guidance is then removed at inference. Result: A
LLMS
-
LLMs Enable Parallel Construction in Intelligence and Law Enforcement
By
–
I’ve sometimes heard this referred to as “parallel construction” in an intelligence or law enforcement context. LLMs are presently a parallel construction goldmine. Whether that is for good or for ill, well, one of many things we’ll have to adjust to quickly.
-

NVIDIA NeMo RL Accelerates Agentic Performance with FP8
By
–
Improve agentic performance with accurate RL post-training on low-precision FP8. NVIDIA NeMo RL, an open-source library within NVIDIA NeMo, supports FP8 to speed up RL workloads by 1.48x on Qwen3-8B-Base—enabling faster iterations for agentic tool use and multi-step
-
Using LLMs to Find Public Evidence for Off-Record Journalist Beliefs
By
–
Journalists: if you ever have a thing you understand to be true, but cannot cite it or get it past editors due to commitments made to sources, describe your belief about the world to an LLM and ask the LLM if it can find public evidence which unambiguously confirms the belief.
-
AWQ Quantization Optimization for Agentic AI Workloads
By
–
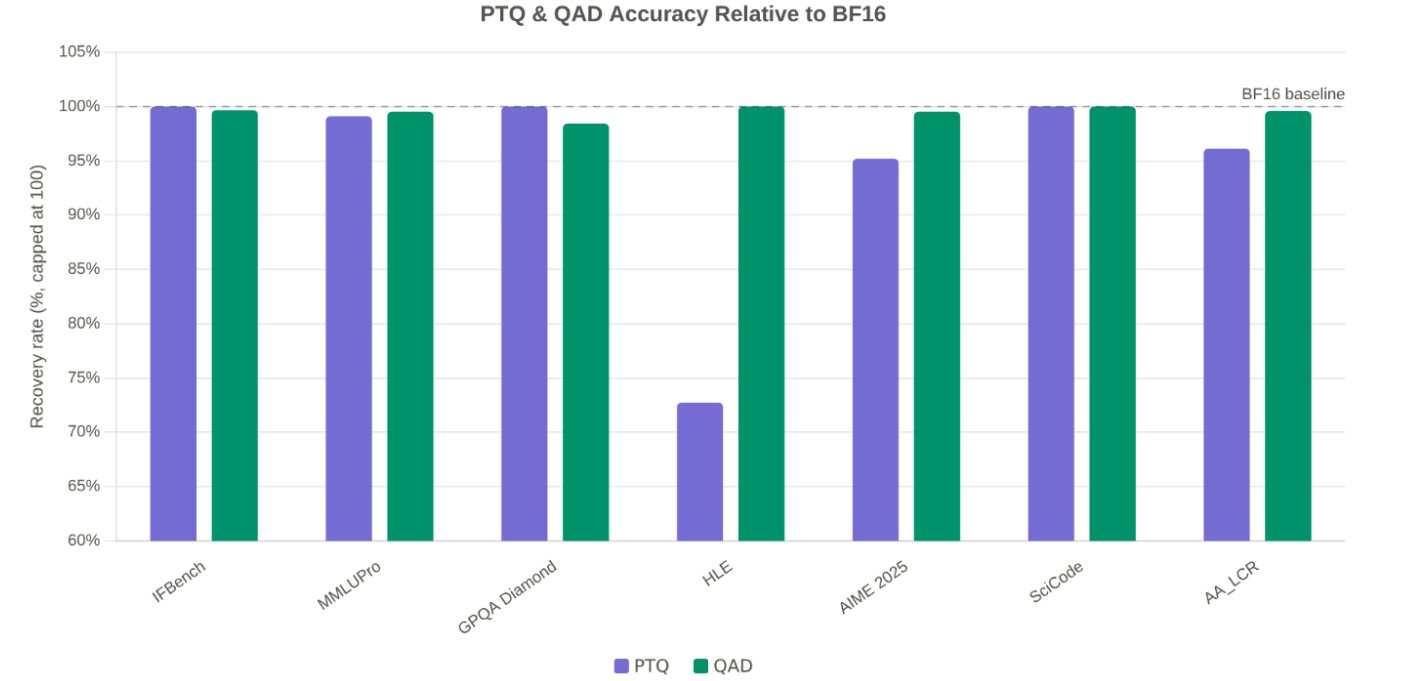
For real agentic workloads (North), short-context calibration wasn't enough. We calibrated AWQ on long internal agentic traces (up to 64k tokens) and added token masking in llm-compressor to exclude repetitive chat templates/tool descriptions from calibration stats. Plus QAD
-

BF16 to FP8 Quantization: Per-Channel Scaling for LLM Accuracy
By
–
The tricky part: naïvely casting BF16 group scales to FP8 dropped the quality. Our fix: quantize scales per-channel (outer vector scaling) + rescale by 1/8 to avoid FP8 clipping. Result: >99.5% of W4A16 accuracy recovered on Command A & Cohere MoE. Paired with a CUTLASS
-

W4A8 Inference Production-Ready Integration in vLLM
By
–
Excited to share our work on production-ready W4A8 inference, now integrated in vLLM! By combining 4-bit weights (low memory) with 8-bit activations (high compute), we hit the sweet spot for both decoding and prefill — up to 58% faster TTFT and 45% faster TPOT vs W4A16 on Hopper.
-
Plugin Architecture for Multiple AI Providers Integration
By
–
It’s all plugins – just like we have plugins for alibaba, tencent, kimi, minimax, anthropic and many others.
-
Oracle AI agent lets Gemini users query enterprise data in natural language
By
–
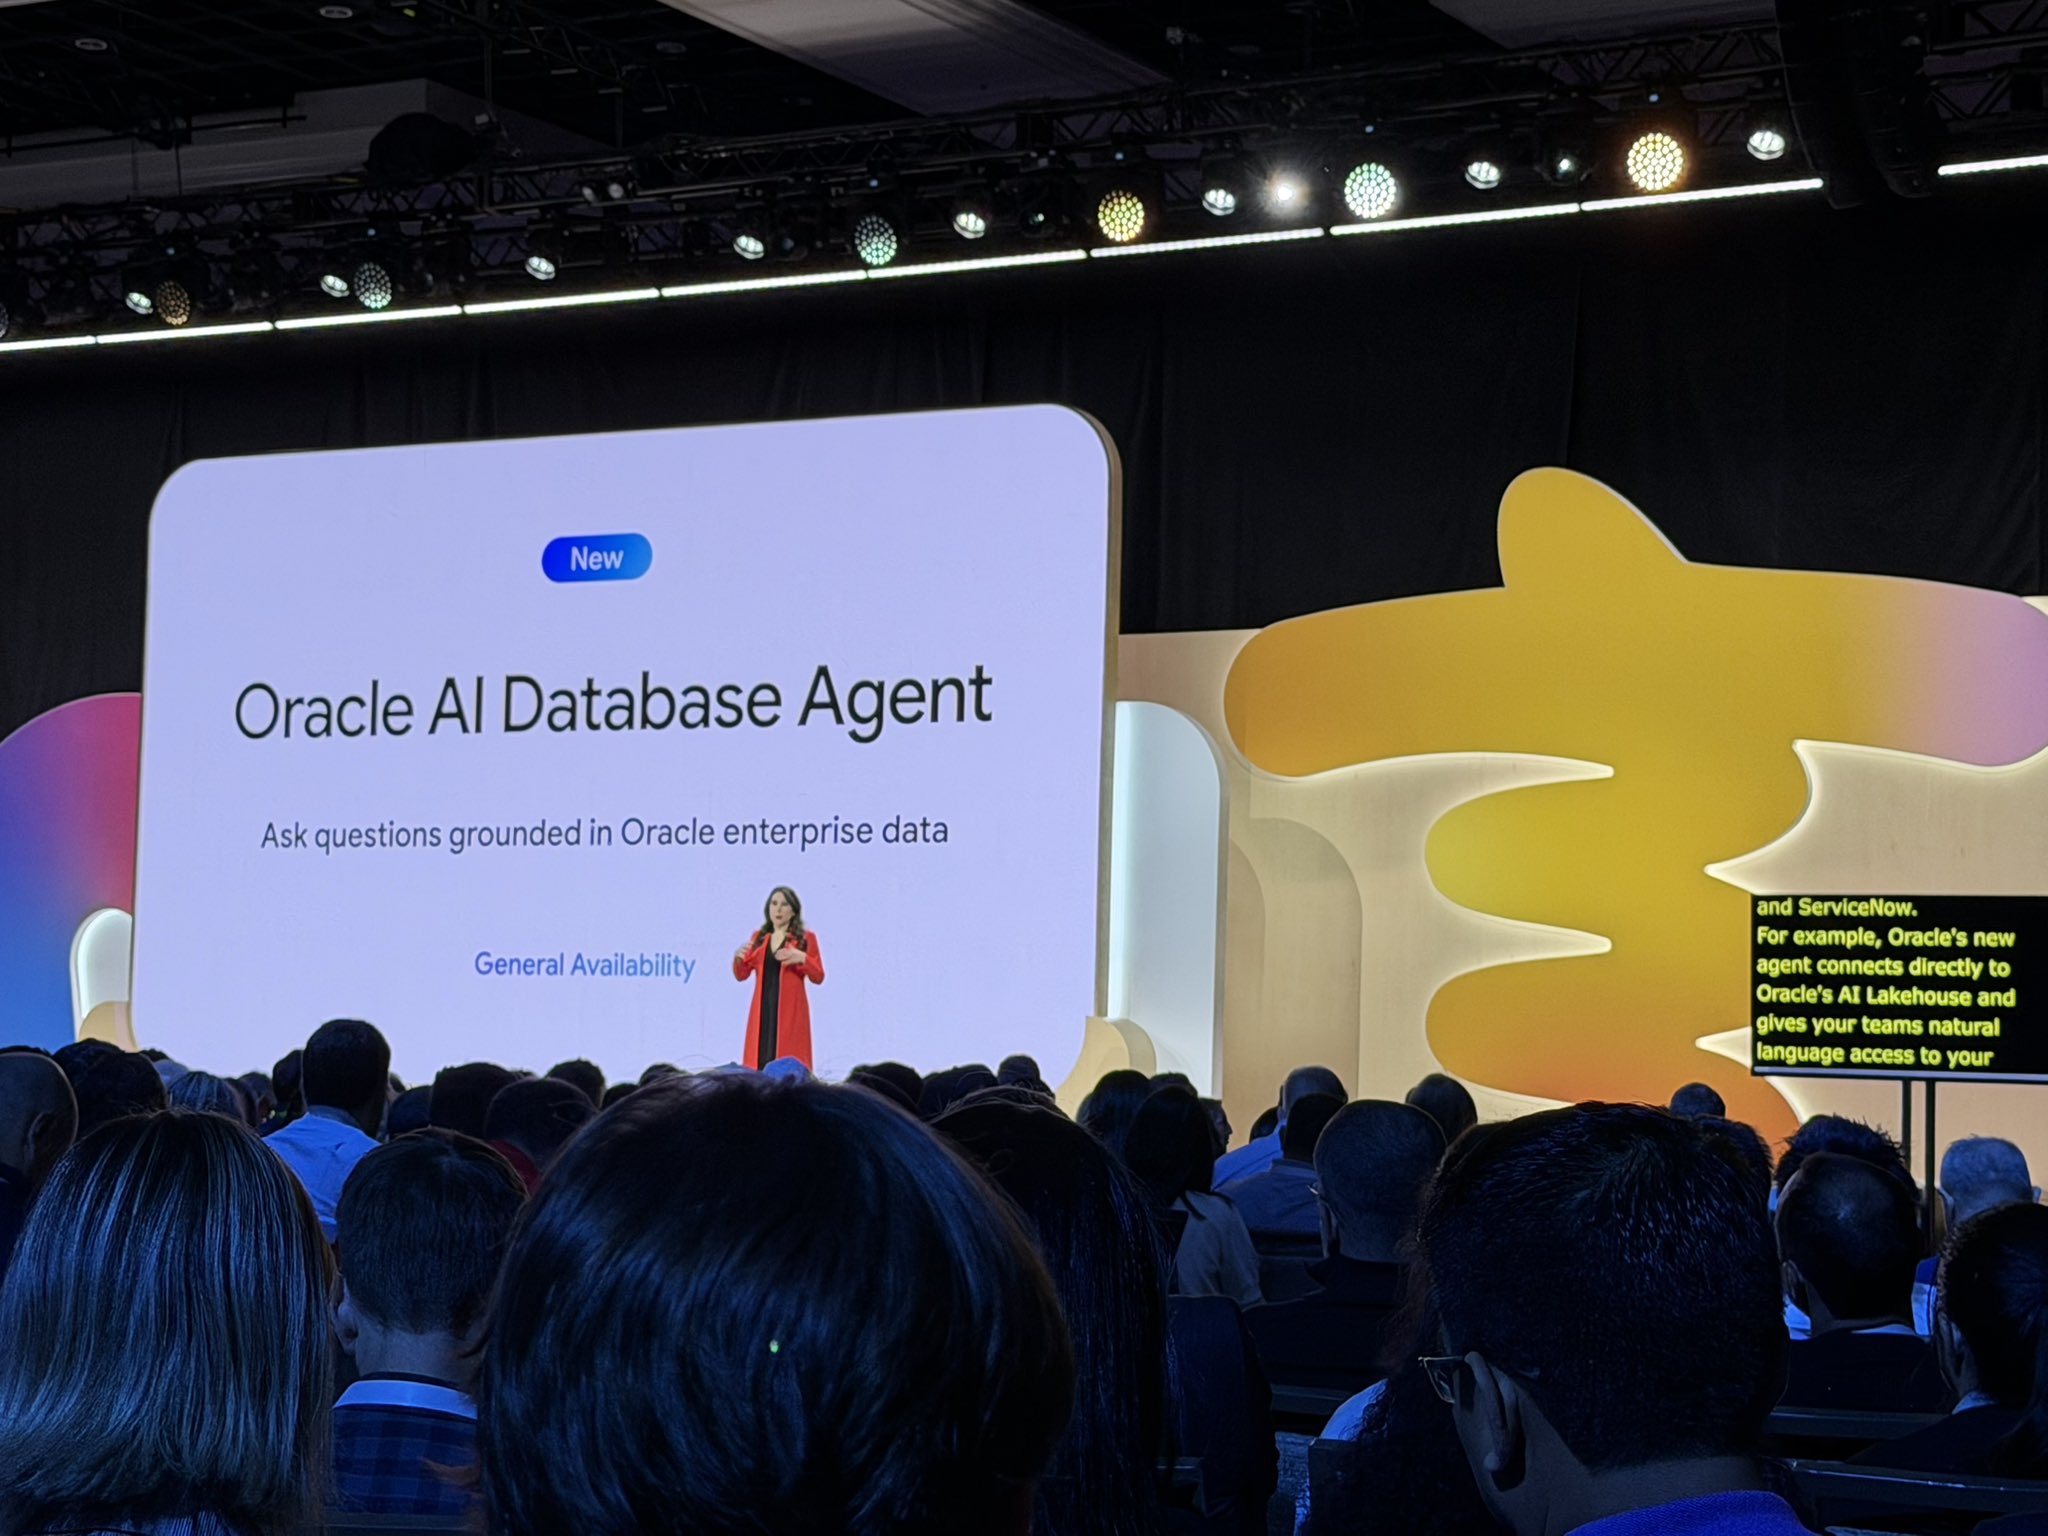
ICYMI: @Oracle
's new AI agent enables Google Gemini users to query their most important enterprise data in natural language, without moving or copying data. Seamless, secure, and awesome.