self-driving sushipic.twitter.com/v53GyS6MyB
— hardmaru (@hardmaru) 3 avril 2026
self-driving sushi
By
–
self-driving sushipic.twitter.com/v53GyS6MyB
— hardmaru (@hardmaru) 3 avril 2026
self-driving sushi
By
–
MultiGen
— AK (@_akhaliq) 3 avril 2026
Level-Design for Editable Multiplayer Worlds in Diffusion Game Engines
paper: https://t.co/UT01uUYBxj pic.twitter.com/AMY0bDusAj
MultiGen Level-Design for Editable Multiplayer Worlds in Diffusion Game Engines paper: huggingface.co/papers/2603.0…
By
–
Zipline Unveils #Autonomous Charging Stations for Its #Drone Delivery Fleet
— Ronald van Loon (@Ronald_vanLoon) 3 avril 2026
by @tweetciiiim
#EmergingTech #Technology #Innovation pic.twitter.com/qGhjC53ysu
Zipline Unveils #Autonomous Charging Stations for Its #Drone Delivery Fleet
by @tweetciiiim #EmergingTech #Technology #Innovation
By
–
A better algo than the algo for watching AI news here on X: https://
alignednews.com/ai Happy Friday!
By
–
Really digging this Seedance integration. … and good to see you back on X, folks! 🙂

By
–
How can enterprises accelerate decision-making and improve efficiency? We're joining @Microsoft's Model Mondays on April 6th to discuss how AI can help you: 🌎 Drive real-world enterprise value 💡 Surface precise, verifiable insights 📌 Use Microsoft Azure and Cohere enterprise models to accelerate your AI journey
By
–
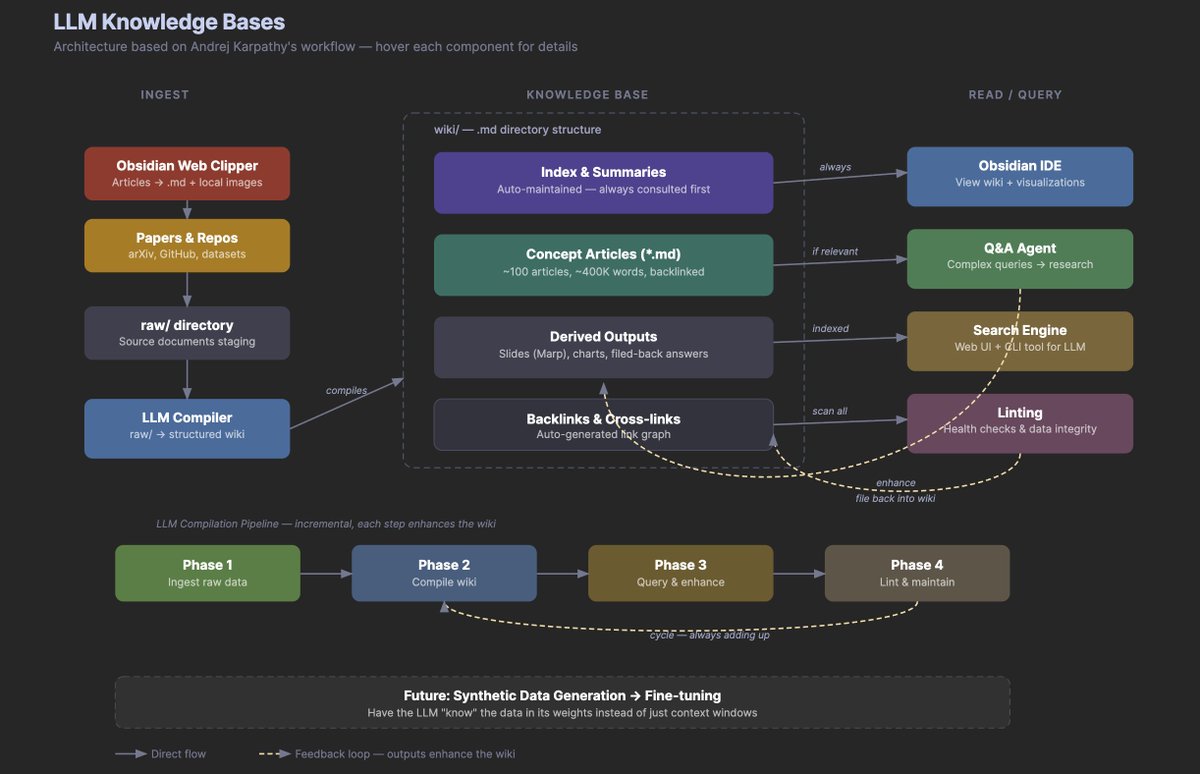
Diagram of the LLM Knowledge Base system. Feed this to your favorite agent and get your own LLM knowledge base going. Andrej Karpathy (@karpathy) LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts. — https://nitter.net/karpathy/status/2039805659525644595#m

By
–

Matthew Gallagher built MEDVi into a $1.8B company generating more than $400M in revenue with just two employees. It is one of the clearest examples yet of how AI can dramatically compress the headcount needed to build at scale. [Translated from EN to English]
→ View original post on X — @taryl_ogle, 2026-04-03 16:09 UTC

By
–
On May 5, join @StanfordHAI and Stanford Data Science as we explore AI's role in science: What are the real breakthroughs, limits, and risks? How do we leverage AI while keeping scientific discovery fundamentally human? Register now to secure your spot: hai.stanford.edu/events/ai-s… [Translated from EN to English]
→ View original post on X — @stanfordhai, 2026-04-03 16:05 UTC
By
–
Try Lyria 3:
replicate.com/google/lyria-3 [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 15:59 UTC