“support” just means “doesnt error”…
INNOVATION
-
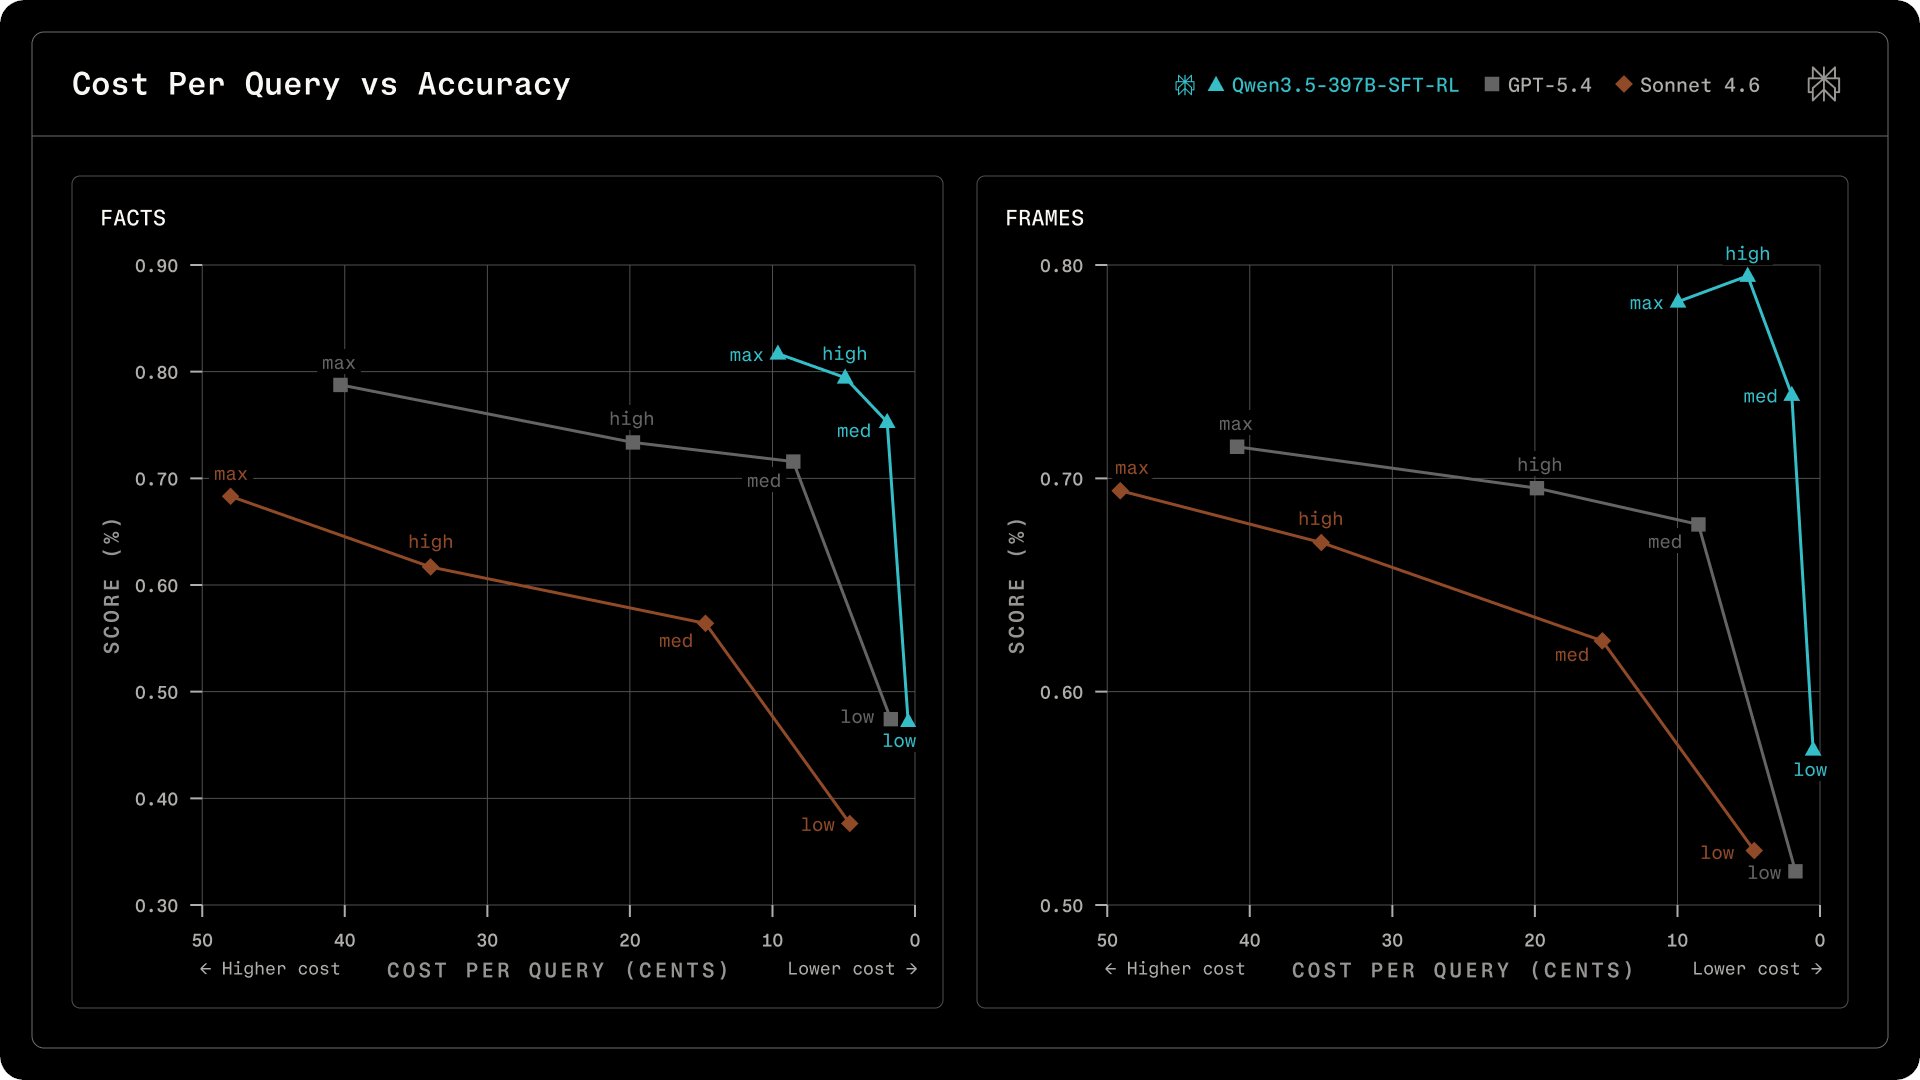
Qwen-based Model Achieves Pareto Optimality in Accuracy-Cost
By
–
We’ve post trained a model on top of Qwen that achieves Pareto optimality on accuracy-cost curves. Unlike our previous post trained models, this model has been trained to be good at search and tool calls simultaneously, allowing us to unify the tool call router and
-
Unitree Robotics: China Supply Chain Mastery Threatens US Competition
By
–
Sam is right about the importance of robotics for the US but Unitree offers a real lesson to US companies hoping to compete at the bleeding edge. It has risen thanks to a true mastery of China’s supply chain.
-

Challenges in Manufacturing World-Class Affordable Robot Actuators
By
–
If only it were that easy to make world-class cheap robot actuators… https://t.co/0iO1tfZ8vf
— Will Knight (@willknight) 22 avril 2026If only it were that easy to make world-class cheap robot actuators…
-
Perplexity’s Pipeline Improves Base Model Accuracy and Efficiency
By
–
This pipeline is why the same base model produces more accurate, better-cited, and more efficient answers inside Perplexity than out of the box. Read our research:
-
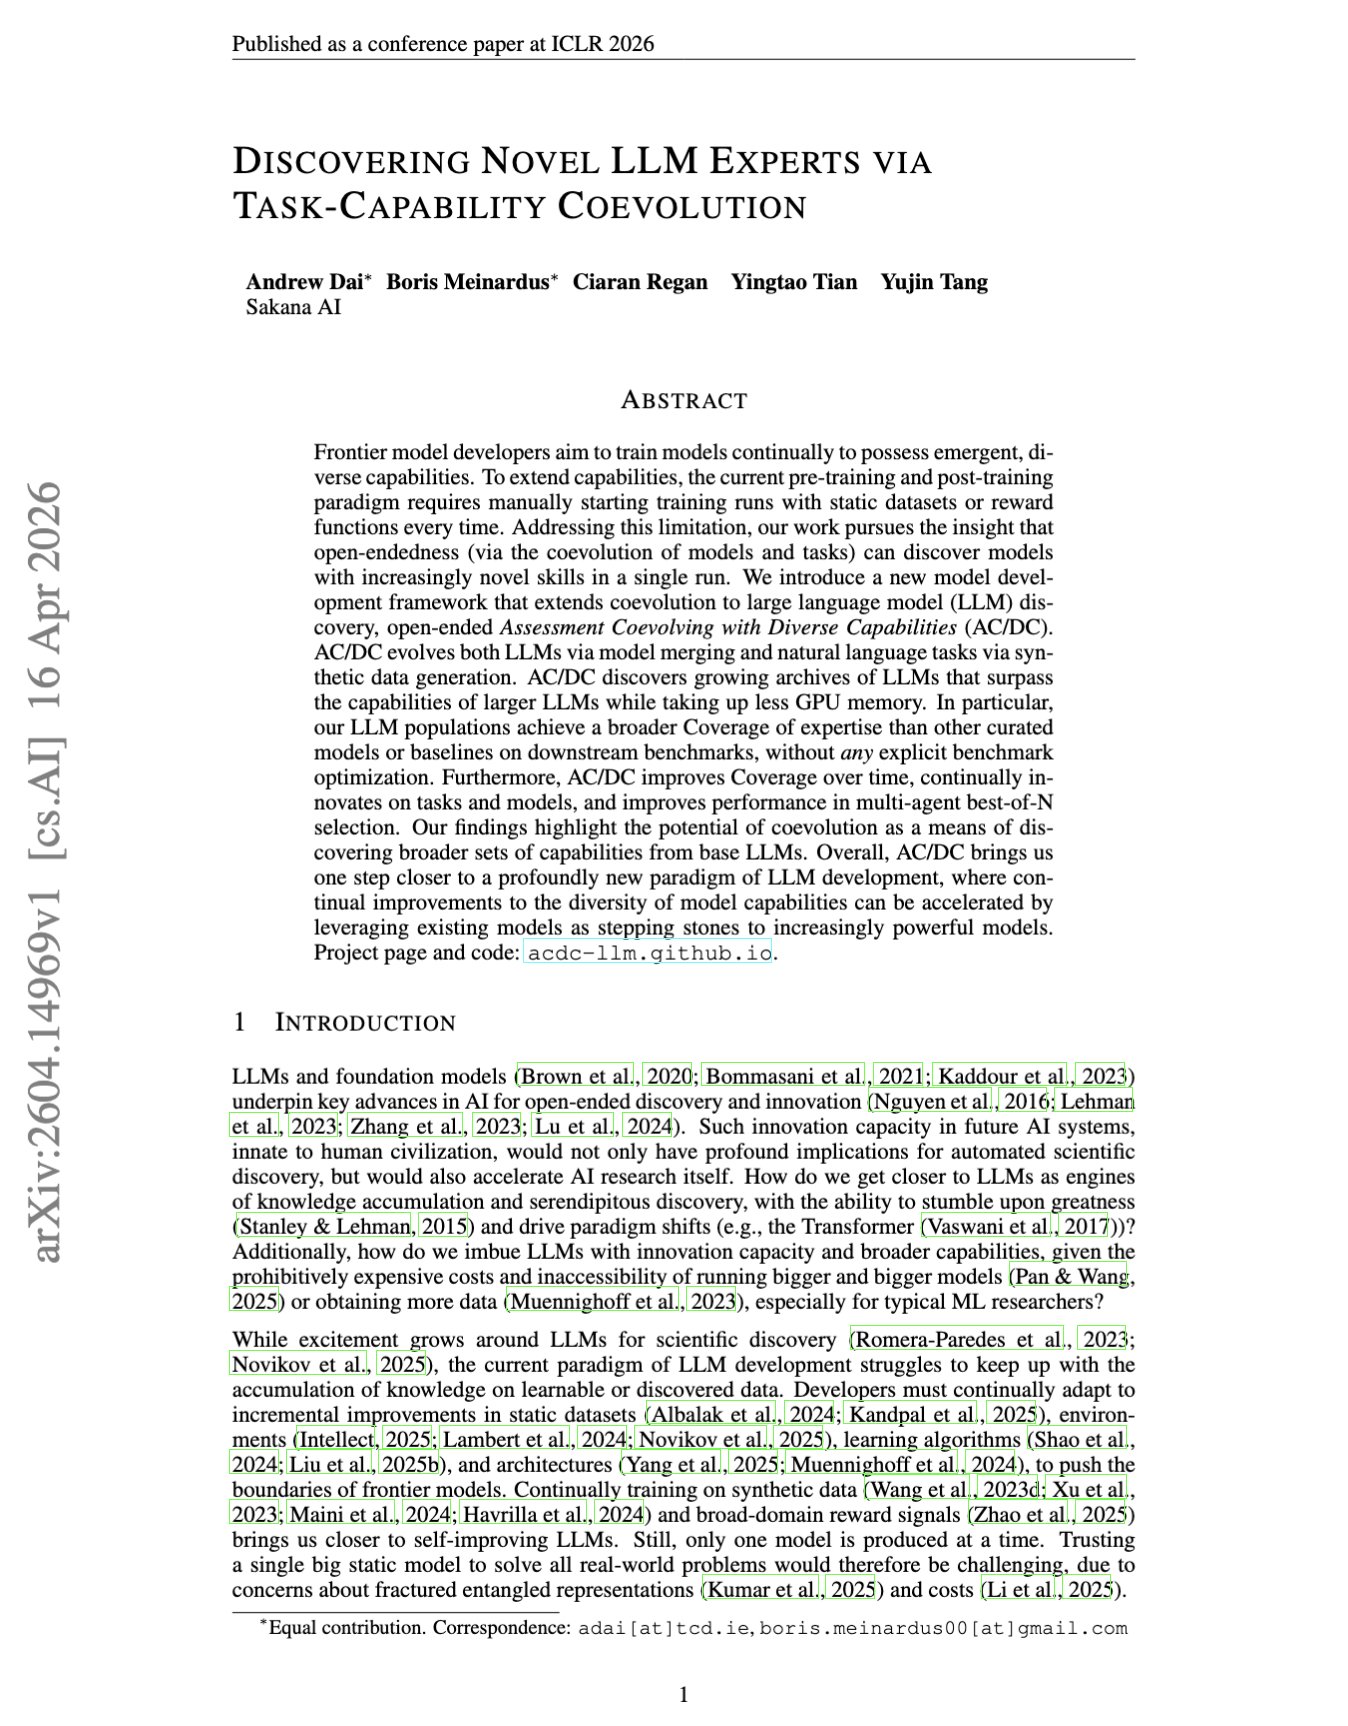
Discovering Novel LLM Experts via Task-Capability Coevolution
By
–
Most LLM development still optimizes one model at a time. So this paper from Sakana AI proposes AC/DC (Assessment Coevolving with Diverse Capabilities), where models and tasks evolve together. The main idea is
-
Apple GPU Strategy: Potentially Prescient Decision for AI Hardware
By
–
Maybe. IMHO it is still too early for the final verdict. If Apple GPUs end up going far, then it could potentially be one of the most prescient decisions in company’s history.
-

Account tier access expansion for business and education users
By
–
For now, they only reach Business, Enterprise, Edu, and Teacher accounts.
-

SF Meetup: Building Better AI Agents with Improvement Loops
By
–
Join us in SF for a meetup on building better agents with the agent and code improvement loops. You'll hear talks by @samecrowder
, Head of Product at @LangChain
, and @nnennahacks
, AI Developer Relations Lead at @QodoAI
. Sam will walk through the agent improvement loop and how -
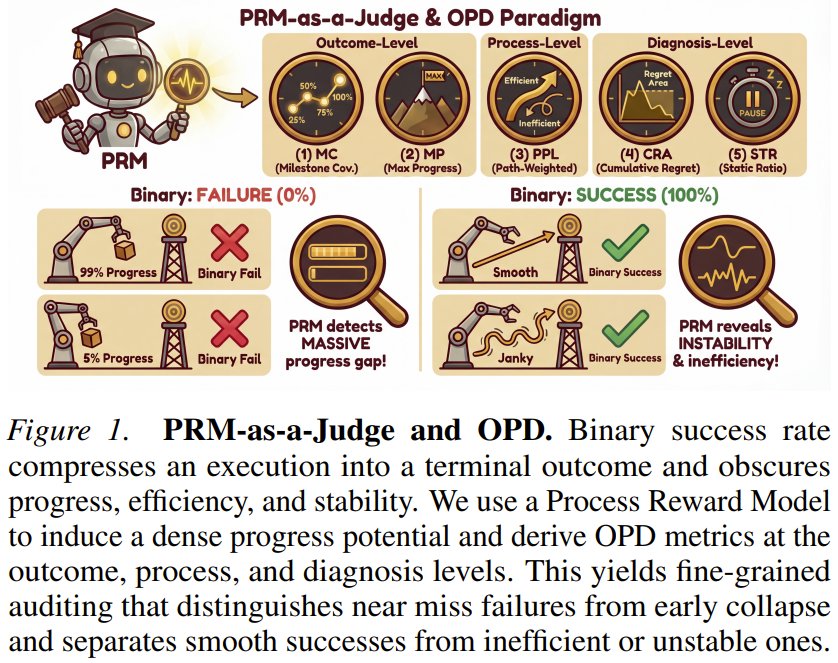
Process Reward Models Grade Robot Performance Like Sports Replay
By
–
What if we could audit a robot's performance like a sports replay, grading every move, not just the final score? Researchers from Peking University, Chinese Academy of Sciences, and the Beijing Academy of AI present PRM-as-a-Judge. They use a "Process Reward Model" to watch a