Jamba’s speed also shows in OTPS, as seen in @ArtificialAnlys
. Jamba 1.5 Mini ranks the fastest @ 10K contexts [4/6]
GENERATIVE AI
-
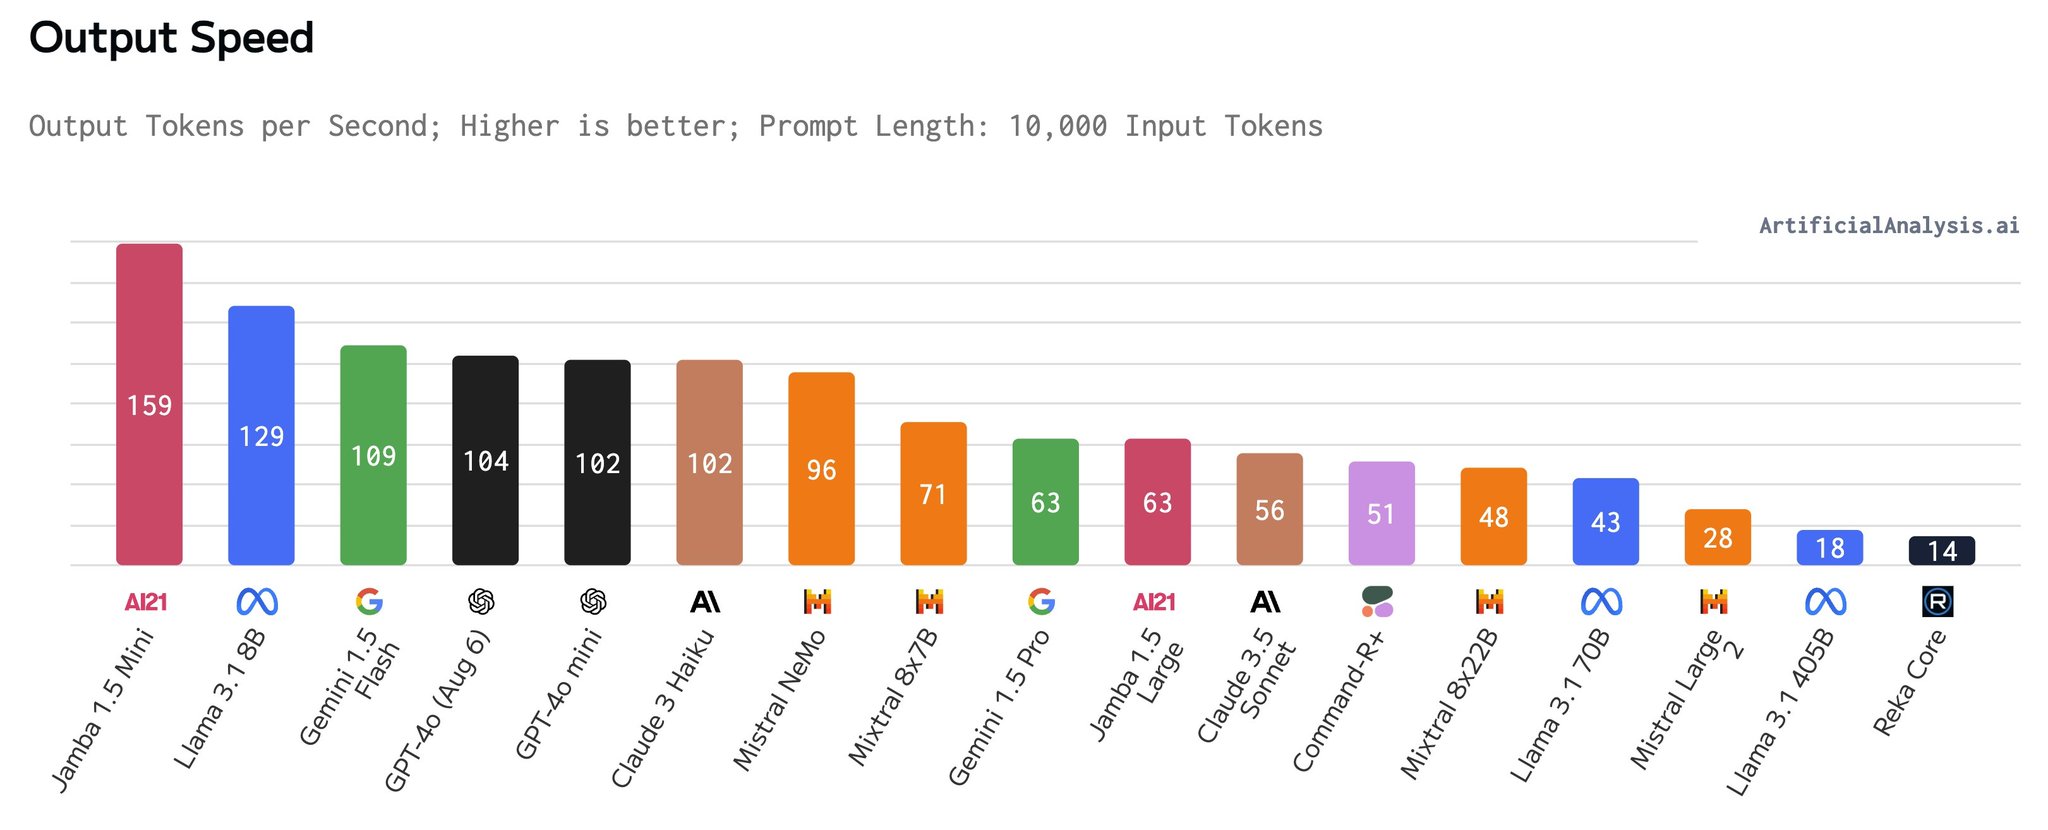
Jamba 1.5 Mini Achieves Fastest Speed at 10K Contexts
By
–
-

Jamba 1.5 Models Deliver 2.5X Faster Inference Performance
By
–
Both Jamba 1.5 models are faster than competitors of a similar size, with up to 2.5X faster inference on long contexts. [3/6]
-
Jamba 1.5 Models: Hybrid SSM-Transformer Architecture Innovation
By
–
The Jamba 1.5 models are based on our novel hybrid SSM-Transformer architecture, which combines the quality, speed and efficiency of both. Jamba 1.5 Mini has 12B active/52B total parameters, while Large is 94B active/398B total – the largest Mamba model ever made. [2/6]
-
Jamba 1.5 Model Family: Detailed Benchmarks and Performance Metrics
By
–
We wanted to share some more granular details about the Jamba 1.5 model family – and specific benchmarks on latency, context window, and quality. [1/6]
-

LoRA: Breakthrough in Efficient LLM Fine-tuning
By
–
Thrilled to feature LoRA this week! Published in 2021, LoRA offered a breakthrough in the ability to train and fine-tune LLMs efficiently. Author @edwardjhu will be responding to your questions and comments!
-
Jabberwacky Dialogs Appeared in LLaMA Training Data
By
–
jabberwacky is a pre-LLM chatbot and dialog examples from it appear in llama’s training data so it often appears to assume that context (for the particular chat syntax openrouter adds)
-

Generative AI Adoption: From Journey Start to Business Impact
By
–
90% of organizations have started their generative AI journey, but only 13% are seeing a business impact. We're partnering with Google Cloud to help companies overcome generative AI challenges. Our combined solution simplifies the AI lifecycle—building, operating, and governing
-
Learning AI Basics Before Advanced Implementation
By
–
I’ll go raw to start, wanna learn the basics before I jump on that train.
-

Claude Adds LaTeX Rendering Support for Mathematical Equations
By
–
We've added support for LaTeX rendering as a feature preview. Claude can now display mathematical equations and expressions in a consistent format.
-
Head-to-Head Latency Test Results Comparison
By
–
We ran a head-to-head #latency test, with the same hardware and same prompts.
— AI21 Labs (@AI21Labs) 22 août 2024
Want to guess who won? 🤔 pic.twitter.com/SJGTKk7SCLWe ran a head-to-head #latency test, with the same hardware and same prompts. Want to guess who won?