ICYMI: ChatGPT has loads of style presets for its DALL-E GPT. The amount of presets has increased recently. However, it takes ages to scroll through and what it does is only add a keyword to the chat Now even Cyberpunk style is there too
GENERATIVE AI
-

ChatGPT-4o Custom GPTs to Earn $10,000 per Job
By
–
ChatGPT-4o can help you make $10,000, If you have good GPTs. But most people don't know the best GPTs. That's why I made "100+ custom GPTs" for each job. Like + comment "AI" and I'll DM you the file. (Must be following me)
-

Real-Time Video Generation with Pyramid Attention Broadcast
By
–
Real-Time Generation with Pyramid Attention Broadcast discuss: https://
huggingface.co/papers/2408.12
588
… We present Pyramid Attention Broadcast (PAB), a real-time, high quality and training-free approach for DiT-based video generation. Our method is founded on the observation that -
Show-o: Unified Transformer for Multimodal Understanding and Generation
By
–
Show-o
— AK (@_akhaliq) 23 août 2024
One Single Transformer to Unify Multimodal Understanding and Generation
discuss: https://t.co/haGX7CKOYp
We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies… pic.twitter.com/UosIpqiuYHShow-o One Single Transformer to Unify Multimodal Understanding and Generation discuss: https://
huggingface.co/papers/2408.12
528
… We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies -

Scalable Autoregressive Image Generation with Mamba Architecture
By
–
Scalable Autoregressive Image Generation with Mamba discuss: https://
huggingface.co/papers/2408.12
245
… model: https://
huggingface.co/hp-l33/aim We introduce AiM, an autoregressive (AR) image generative model based on Mamba architecture. AiM employs Mamba, a novel state-space model characterized by its -
Meta Introduces Sapiens: Foundation Models for Human Vision Tasks
By
–
Meta presents Sapiens
— AK (@_akhaliq) 23 août 2024
Foundation for Human Vision Models
discuss: https://t.co/0hDjPL6p4T
We present Sapiens, a family of models for four fundamental human-centric vision tasks – 2D pose estimation, body-part segmentation, depth estimation, and surface normal prediction. Our… pic.twitter.com/gghxSKylcPMeta presents Sapiens Foundation for Human Vision Models discuss: https://
huggingface.co/papers/2408.12
569
… We present Sapiens, a family of models for four fundamental human-centric vision tasks – 2D pose estimation, body-part segmentation, depth estimation, and surface normal prediction. Our -

Video-Foley: Two-Stage Video-To-Sound Generation for Temporal Events
By
–
-Foley Two-Stage Video-To-Sound Generation via Temporal Event Condition For Foley Sound discuss: https://
huggingface.co/papers/2408.11
915
… Foley sound synthesis is crucial for multimedia production, enhancing user experience by synchronizing audio and video both temporally and -

Building Agentic Workflows with Multiple Function Support
By
–
Here’s what is supported! Imagine being able to quickly build agentic workflows that leverage any of these functions!
-
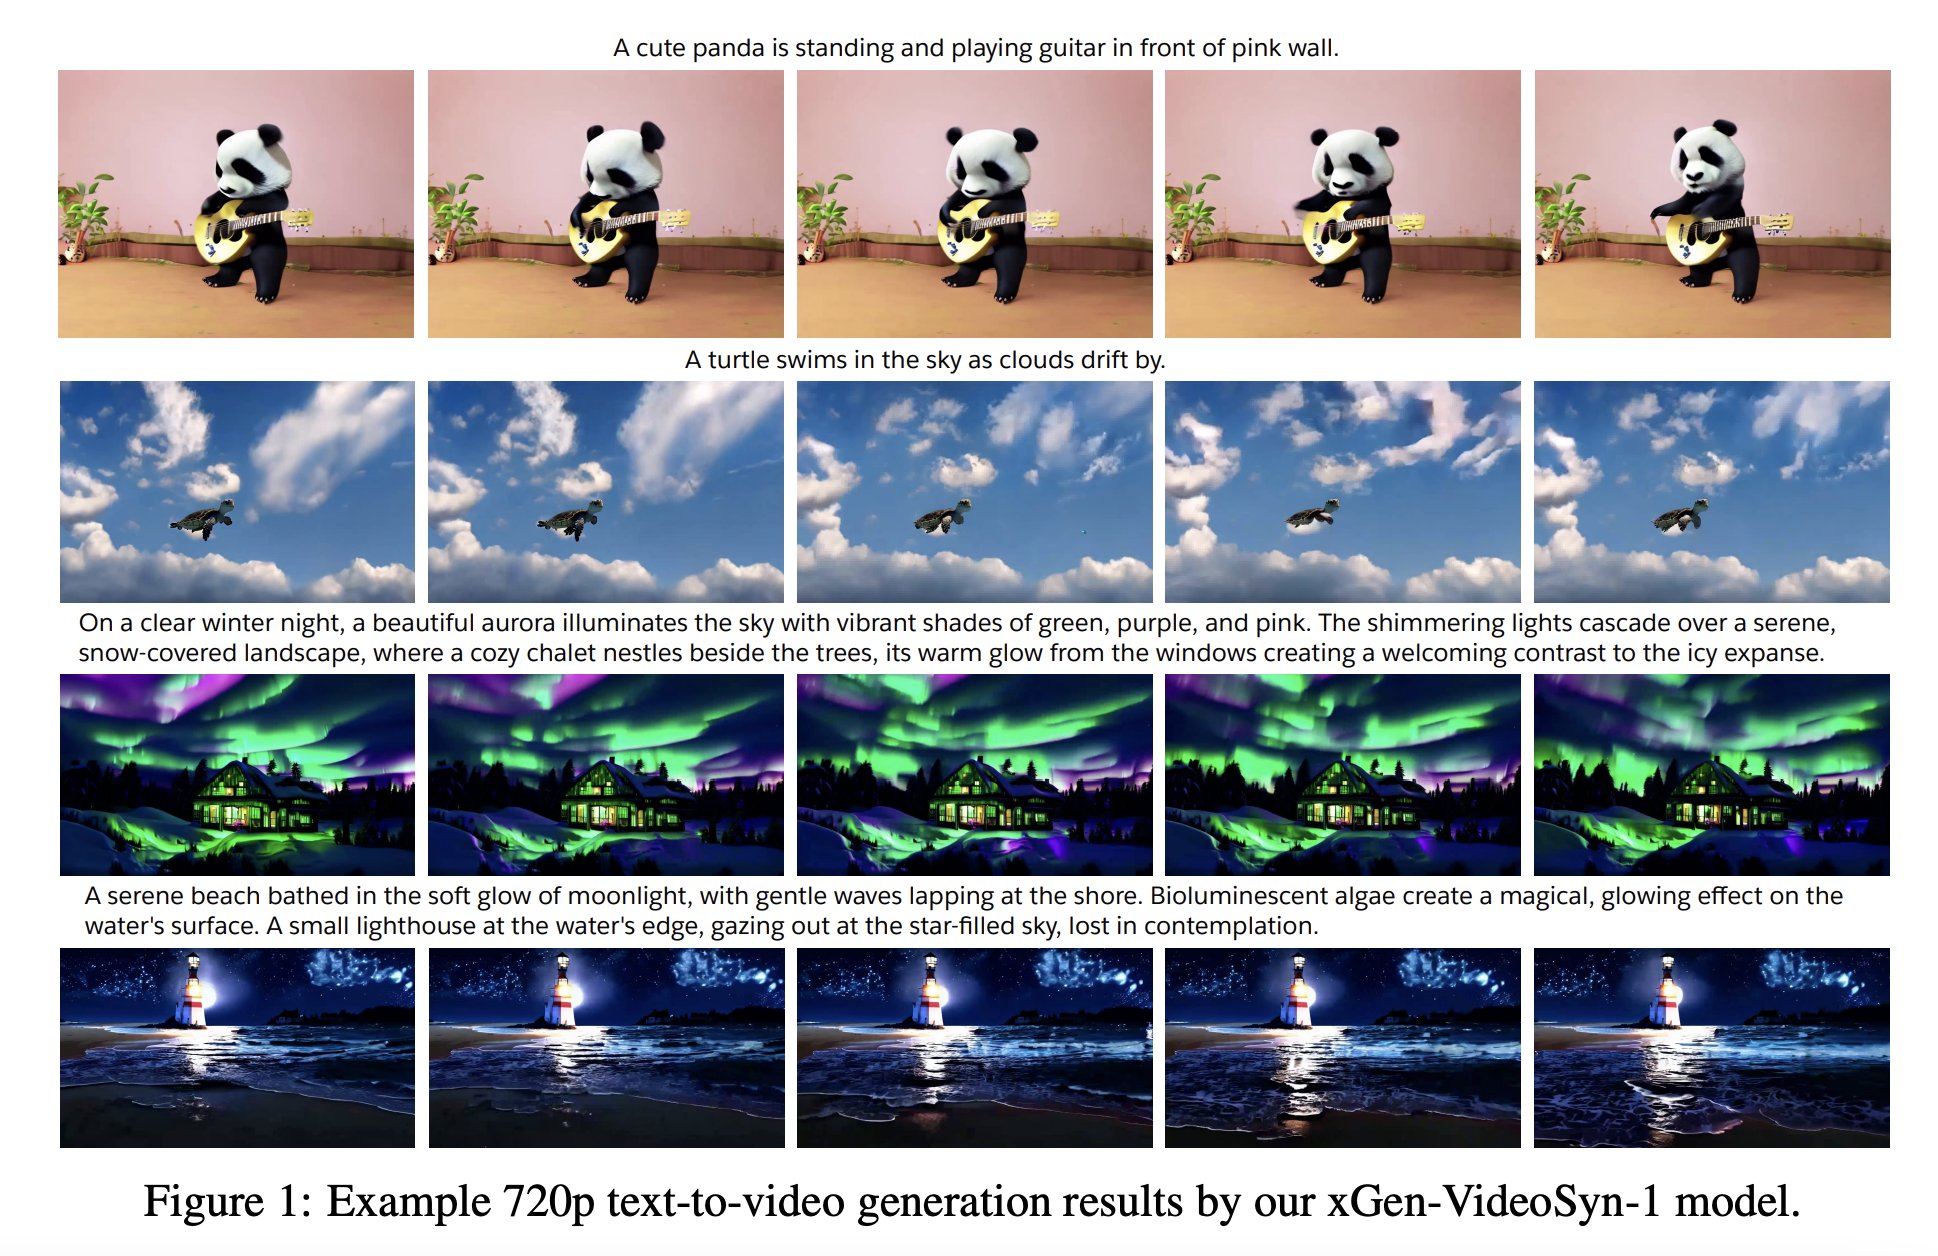
Salesforce xGen-VideoSyn-1: Advanced Text-to-Video Synthesis Model
By
–
Salesforce presents xGen-VideoSyn-1 High-fidelity Text-to-Video Synthesis with Compressed Representations discuss: https://
huggingface.co/papers/2408.12
590
… We present xGen-VideoSyn-1, a text-to-video (T2V) generation model capable of producing realistic scenes from textual descriptions. -
Criminalizing AI-Generated Harm Through Stronger Regulation
By
–
Even if AI generation leads to harm, let us criminalize the harm – it is immaterial that it was AI-generated. Deep fakes, dangerous chemicals, etc, are harmful no matter how they are generated. @FTC has taken a wise stance on this. Why not strengthen our existing laws to prevent