
Ooo looks like I’ve used 19/50 of the top generative AI consumer web products. (Thought it would be higher, honestly—maybe it’s more Gen Z-heavy and less enterprise-focused?) How many are you at? Drop your score below. Highest gets a Crumbl cookie cc: @a16z
GENERATIVE AI
-

LLMs Eliminate Need for Traditional Coding System Standardization
By
–
In the era of large language models: "The extensive efforts previously required to standardize and make coding systems and ontologies interoperable for traditional computing are no longer necessary." https://
nature.com/articles/s4159
1-024-03199-w
…
by @jnkath @DanielTruhn @Dykex6 @IsabellaWies -
Non-engineer discovers Cursor AI coding tool revolutionary impact
By
–
I’m a non-engineer and started building in Cursor recently. The only reaction I had for the first 30 minutes was “holy hell”. Felt like trying ChatGPT for the first time.
-

Mistral AI Developing Web Search Functionality
By
–
BREAKING: Mistral AI is working on web search functionality. The toggle will appear under "Options" when available. Currently visible in UI but not supported by the model itself yet. It seems to be a common toggle for all models.
-

VCs Recognize Blockchain Opportunity for Creator Rights Protection
By
–
They said investors didn't believe in Copyright. They said investors didn't care about creative people. Blockchain fixes that! (Jokes aside it's a good sign; it shows top VCs see the business opportunity in the changing meta, and believe there's a strong demand for solutions.)
-
Jamba Architecture Advantages in Long Context Fine-Tuning Efficiency
By
–
We found our efficient Jamba architecture to be advantageous in long context fine-tuning, as it allows for greater speed and lower cost. Therefore, we could experiment with multiple different training recipes during the fine-tuning phase. This is especially interesting for all
-
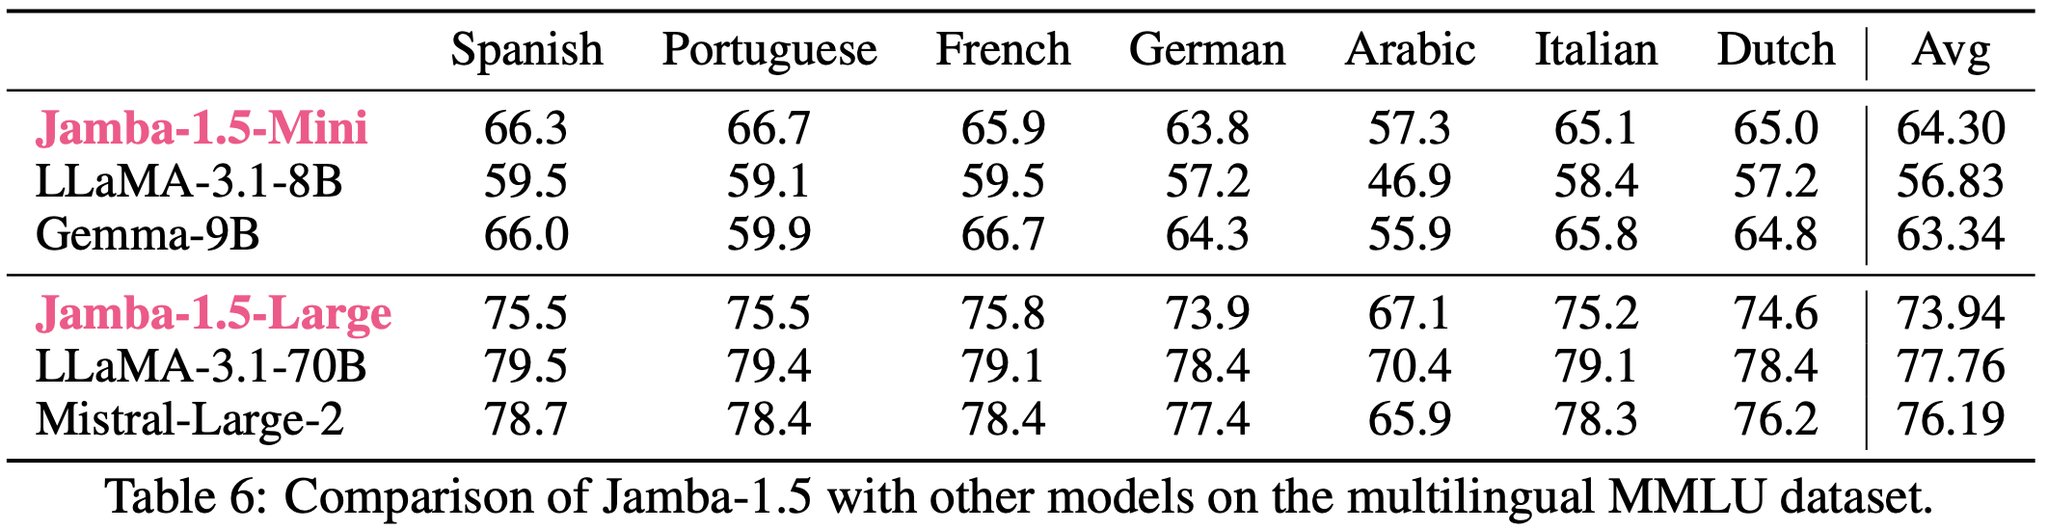
Jamba-1.5 Models Demonstrate Strong Multilingual Performance Despite Limited Post-Training Data
By
–
Jamba-1.5 models perform well in multiple languages, even though we include only a very small fraction of non-english data in the post-training phase. Therefore, we speculate the models are able to use the learned multilingual capabilities from the pre-training phase. 6/7
-
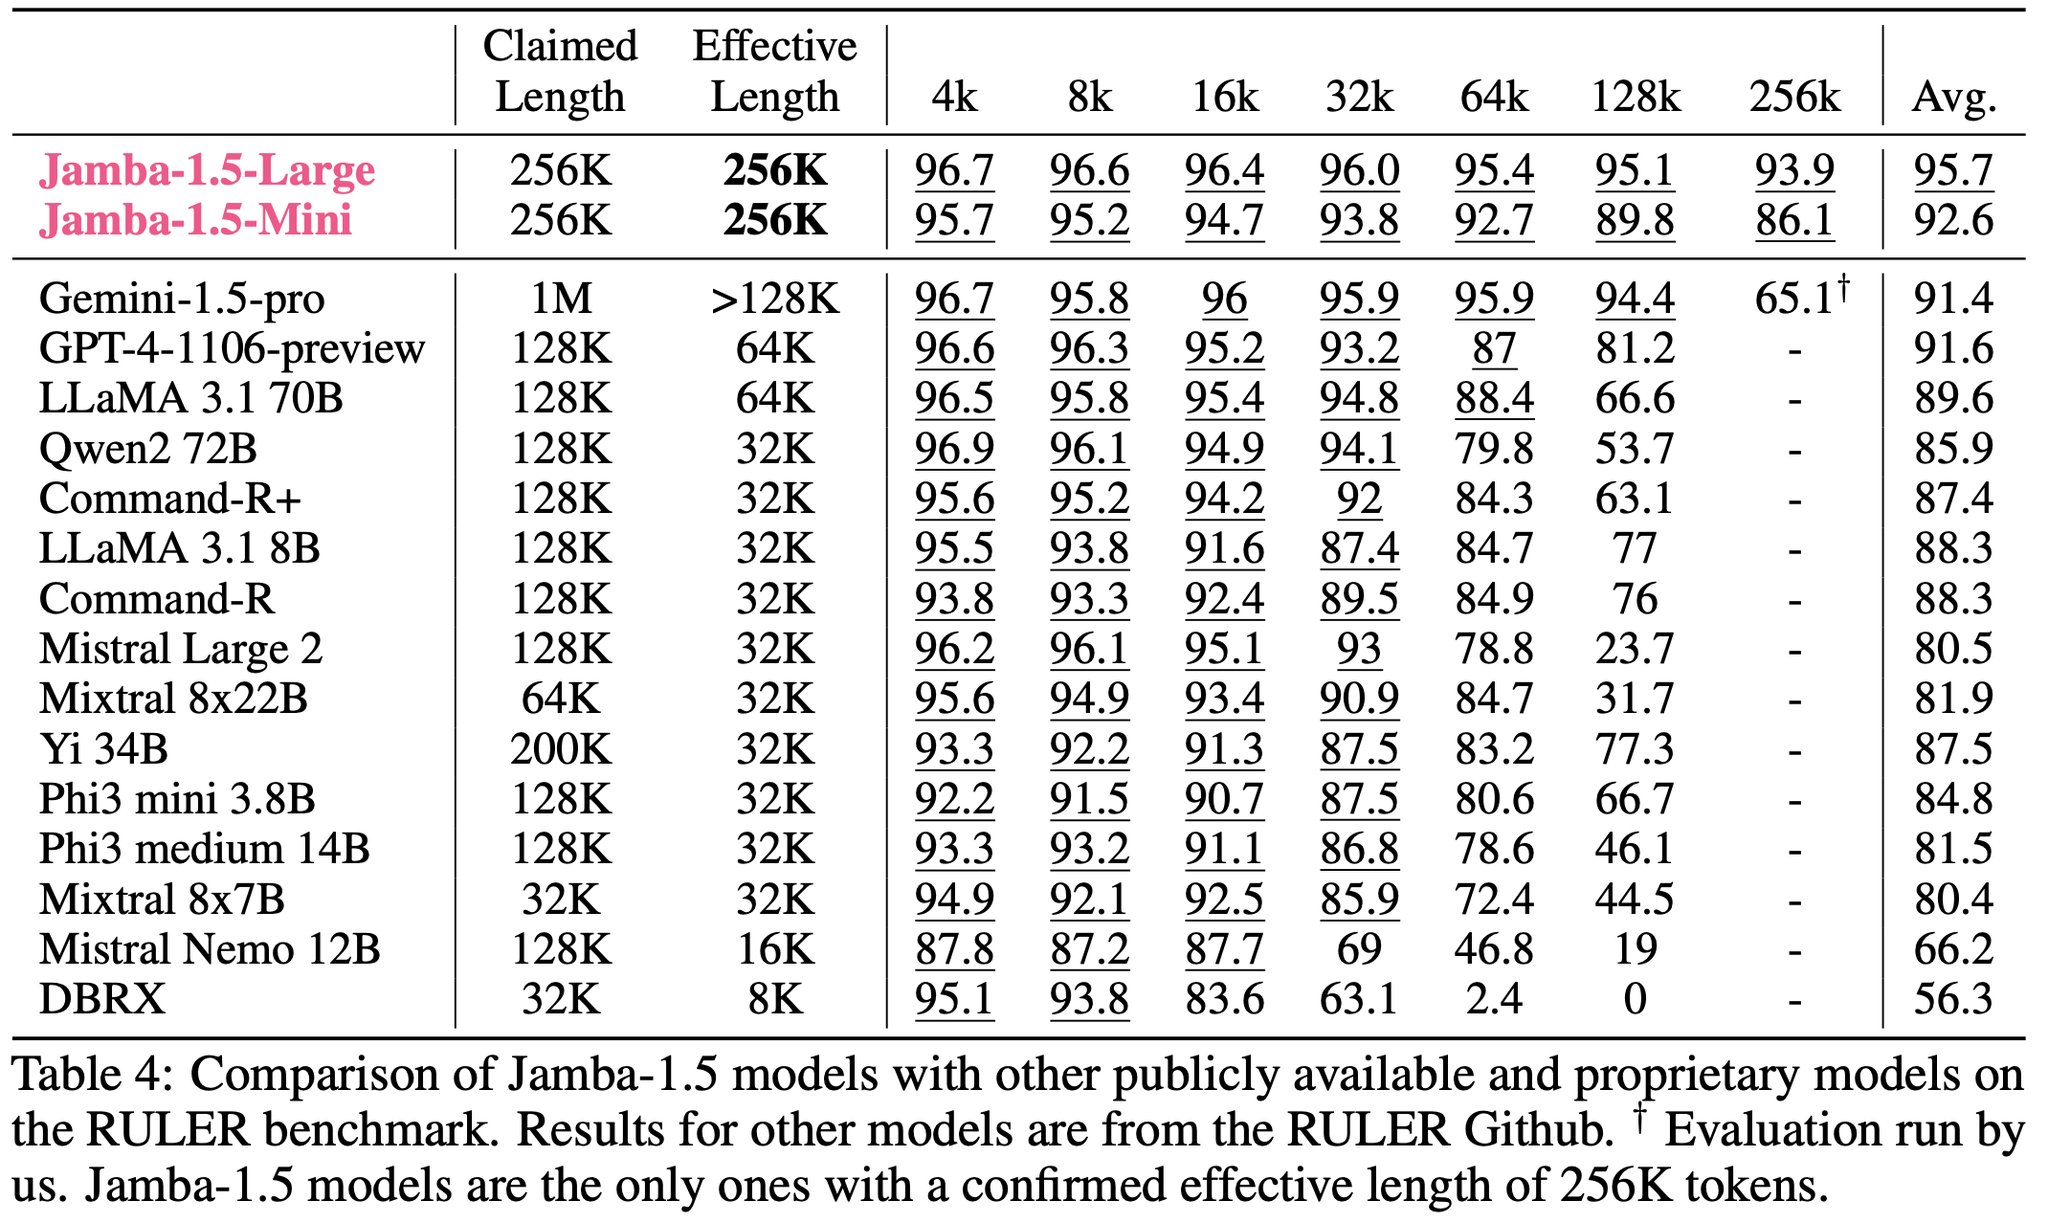
Jamba-1.5 Models Achieve 256K Token Effective Length
By
–
Among all publicly available and proprietary models, Jamba-1.5 models are the only ones with an effective length of 256K tokens, as evaluated by the RULER benchmark. 5/7
-
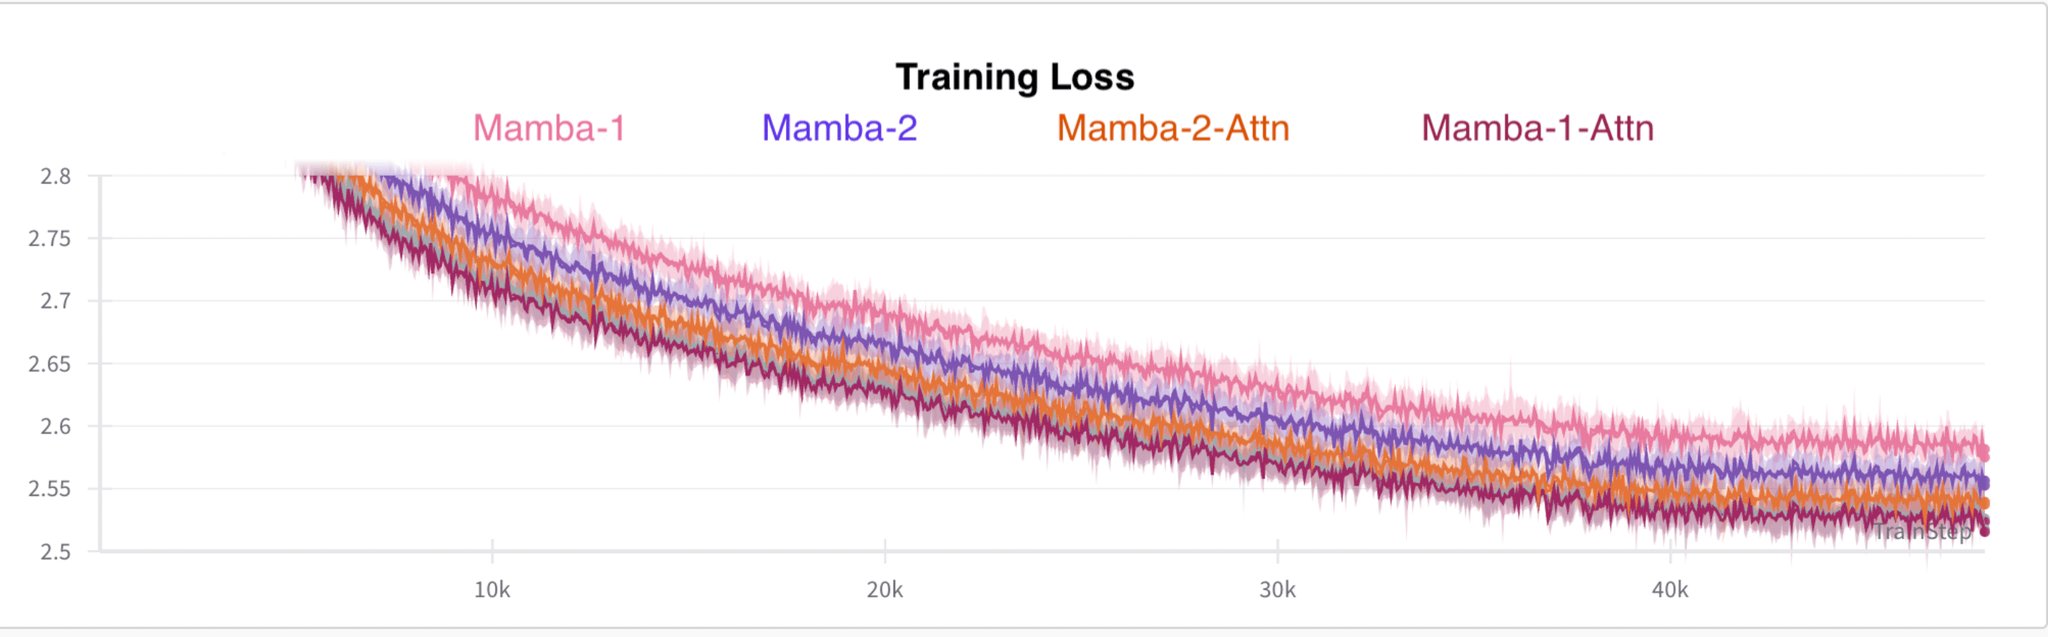
Jamba Architecture: Mamba-1-Attention Hybrid Outperforms Mamba-2
By
–
We experimented with alternatives to our final Jamba architecture, including Mamba-2 (which was released a few months after the original Jamba). However, we found that in a hybrid architecture, the Mamba-1-Attention combination outperforms both Mamba-2-Attention and pure Mamba-2.
-
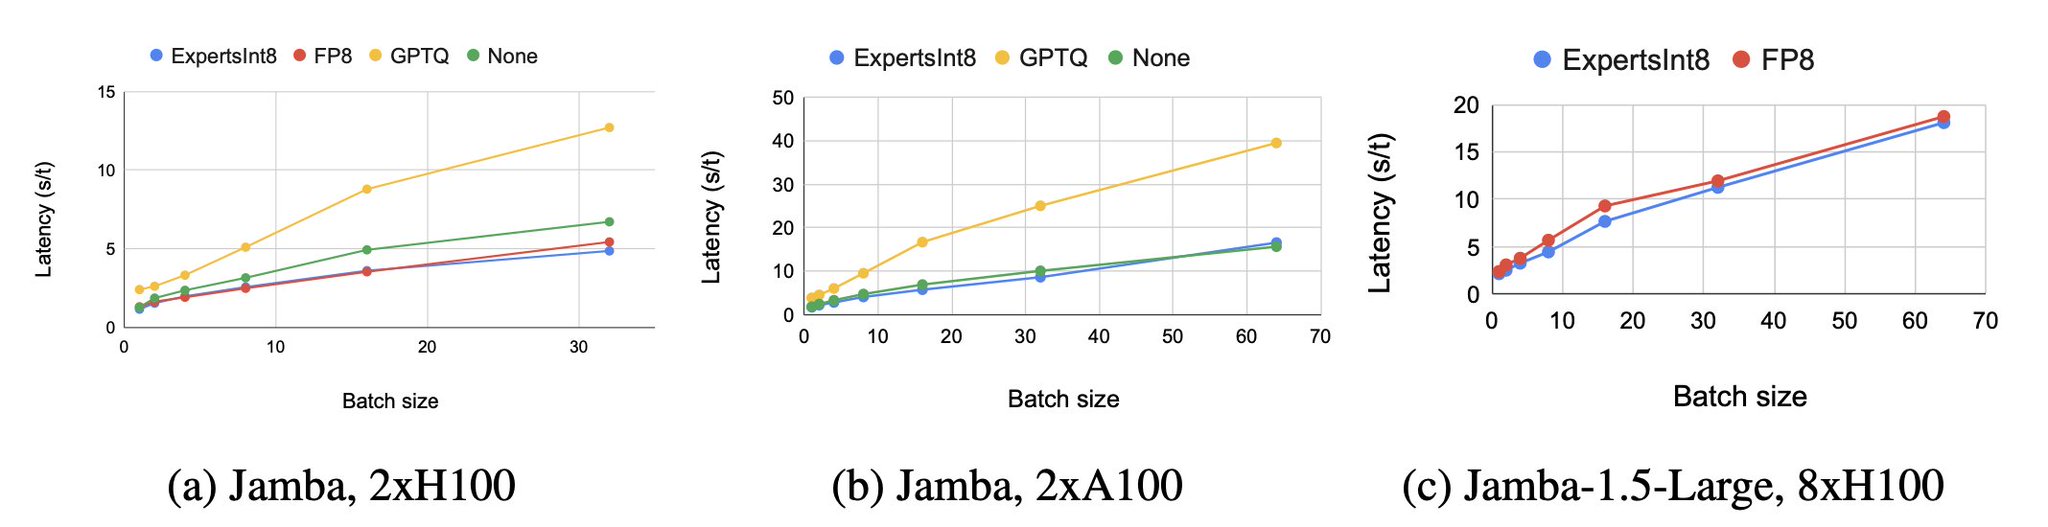
ExpertsInt8: Novel Quantization Technique for Jamba-1.5-Large Efficient Serving
By
–
To support efficient serving of Jamba-1.5-Large, we developed a novel quantization technique – ExpertsInt8. We quantize the MoE and MLP weights to INT8 in order to store them, and dequantize them back to BF16 before the actual computation. This technique is both very fast and