New CodeLLM Release – Upload images in Agents and generate code
– Grok 3 and Grok-3 mini in CodeLLM agents
– One more step change in Autocomplete Coming soon – Rich prompting
– Large code bases
– Better human-in-the-loop management
GENERATIVE AI
-
CodeLLM Advances: Image Upload, Grok 3 Integration, Autocomplete Improvements
By
–
-
Google’s Marketing Weakness Versus Strong Technology Leadership
By
–
Google has never been good at marketing its products, but boy is it good at technology. Very bullish on Gemini, the Gemma line of open models, and the JAX/Keras/TPU stack
-
Gemini 2.5 Pro Reception Exceeds Expectations Across Benchmarks
By
–
We are blown away by the reception of Gemini 2.5 Pro, and the many positive surprises from benchmarks and community evaluations. That is the ultimate leaderboard!
-

VideoChat-R1: Spatio-Temporal Perception via Reinforcement Fine-Tuning
By
–
Chat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning This paper explores the use of Reinforcement Fine-Tuning (RFT) with Group Relative Policy Optimization (GRPO) to enhance spatio-temporal perception in video multimodal large language models (MLLMs),
-

SmolVLM: Efficient Vision-Language Models for Edge Devices
By
–
SmolVLM: Redefining small and efficient multimodal models SmolVLM is a family of highly efficient, small-scale vision-language models (VLMs) engineered for low-memory, real-time multimodal inference on mobile and edge devices. These models achieve competitive or even superior
-
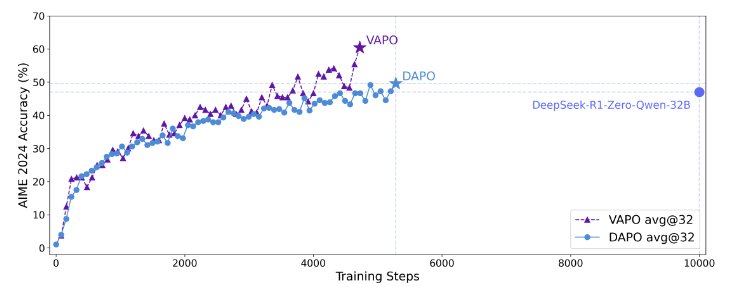
VAPO: Value-Based RL Framework for Advanced LLM Reasoning
By
–
VAPO: Efficient and Reliable Reinforcement Learning for Advanced Reasoning Tasks VAPO is a new value-based reinforcement learning framework designed to enhance long chain-of-thought reasoning in large language models. Built upon Qwen2.5-32B, it outperforms existing methods in
-

Test-Time Training Enables One-Minute Video Generation
By
–
One-Minute Generation with Test-Time Training This paper augments Transformers with Test-Time Training (TTT) layers—neural networks used as hidden states—to generate coherent one-minute videos from text storyboards. Problem: Long video generation is bottlenecked by
-

Hogwild! Inference: Parallel LLM Generation via Concurrent Attention
By
–
Hogwild! Inference: Parallel LLM Generation via Concurrent Attention This paper introduces Hogwild! Inference, a parallel LLM inference framework where multiple model instances collaborate by sharing a synchronized attention cache and dynamically adapting their strategies in
-

Top 10 Papers: Video Generation and Multimodal AI Models
By
–
Huge week for video generation and multimodal models, with detailed one-minute video generation and more efficient approaches to multimodality Check out the top 10 papers for the week – Hogwild! Inference: Parallel LLM Generation via Concurrent Attention
– One-Minute -
Gemini 2.0 Flash Enables Native Image Generation on Poe
By
–
Native image generation is available in Gemini 2.0 Flash Experimental at https://
poe.com/Gemini-2.0-Fla
sh-Exp
… and on all platforms where Poe is available. (3/3)