AI-assisted programming was happening, but the models weren't yet strong enough to support true don't-even-look-at-the-code vibe coding
GENERATIVE AI
-

Using Perplexity Comet as an AI Tutor for YouTube Videos
By
–
Chatting with YouTube videos is a Perplexity Comet use case I've been spamming It's an AI tutor for every educational video Whenever I don't fully understand something, I pause the video and do a mini rabbit hole session I've been doing this while reading with ChatGPT Voice
-
Apple Launches Multilingual Foundation Models for On-Device AI
By
–
10. Apple Intelligence Foundation Language Models Apple introduces two multilingual, multimodal foundation models: a 3B-parameter on-device model optimized for Apple silicon and a scalable server model using a novel PT-MoE transformer architecture.
-
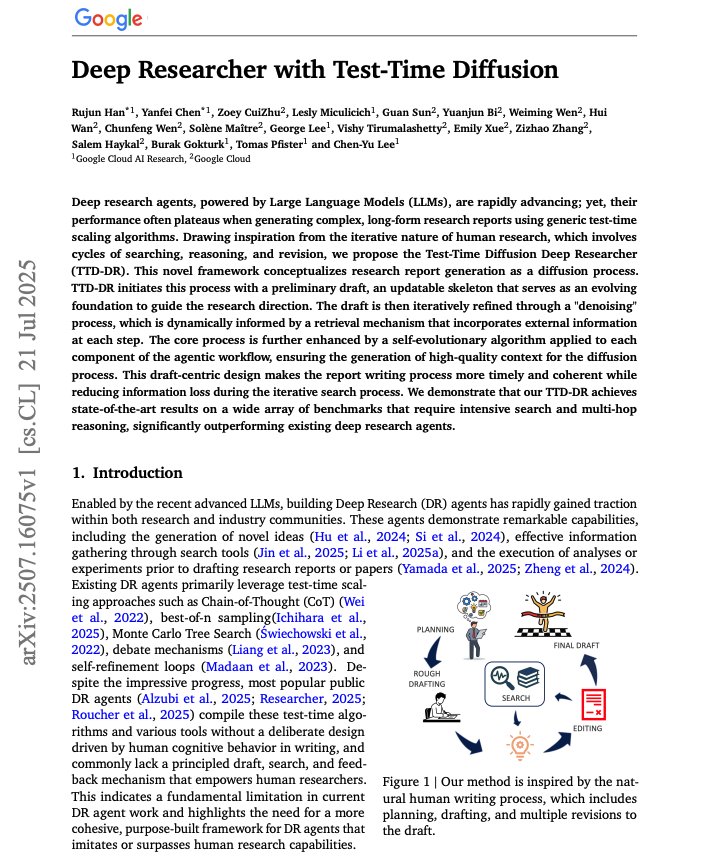
Deep Researcher: Test-Time Diffusion for Report Generation
By
–
8. Deep Researcher with Test-Time Diffusion Rather than relying on static inference strategies like CoT or best-of-n sampling, this work frames the report generation process as a diffusion process.
-
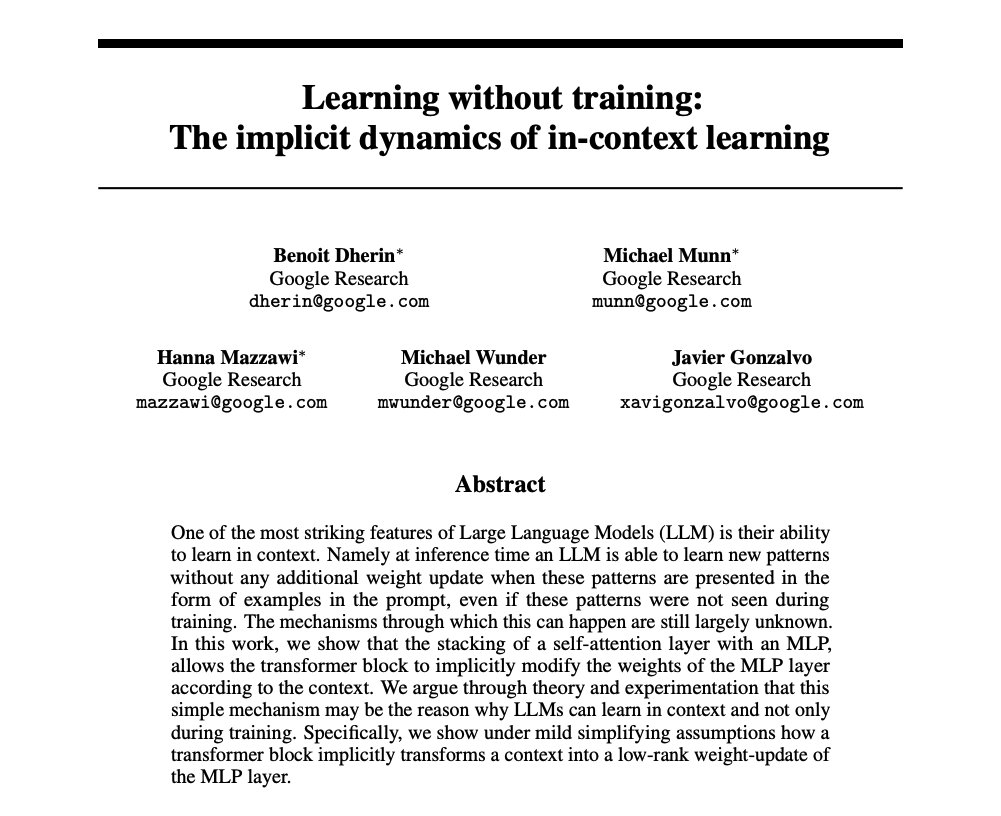
In-Context Learning Without Weight Updates in LLMs
By
–
5. Learning without Training This paper provides a theoretical and empirical explanation for how LLMs exhibit in-context learning, the ability to learn from examples in a prompt without weight updates.
-
Model Convergence Through Distillation and Subliminal Learning Transfer
By
–
This model convergence is quite perplexing. Possibly related to recent results on subliminal learning? Basically deeper knowledge correlations transfer when training via distillation. As the amount of data online from LLMs increases, it’s possible this makes them converge to some
-
Best AI Models Capabilities Six Months Ago
By
–
The best models could do 6 months ago. pic.twitter.com/Kg5iAczkaS
— Ethan Mollick (@emollick) 27 juillet 2025The best models could do 6 months ago.
-
Generative AI’s Unprecedented Adoption Cycle
By
–
Generative AI’s Unprecedented Adoption Cycle
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @lexfridman @sama @kaifulee @ID_AA_Carmack @karpathy @2morrowknight @ylecun -

5 Popular LLM Fine-Tuning Methods Visual Guide
By
–
And those were the 5 popular LLM fine-tuning. Here's the visual again for your reference
-

LoRA: Efficient Fine-tuning with Low-Rank Matrices
By
–
1) LoRA – Add two low-rank trainable matrices, A and B, alongside weight matrices.
– Instead of fine-tuning W, adjust the updates in these low-rank matrices. Even for the largest of LLMs, LoRA matrices take up a few MBs of memory. Check this