AI Dynamics

Global AI News Aggregator

About

DATA

  • Cosine Similarity: Elegant Geometric Approach to Document Comparison

    “Cosine Similarity” is everywhere in machine learning, but it’s often treated as a black box. At its core, it’s just a normalized measure in a vector space, comparing two document representations. It doesn’t really understand meaning, it’s a purely geometric view based on the angle between vectors, yet it works surprisingly well at capturing how similar two documents are, almost as if it understood their content. Simple idea, but the intuition behind it is genuinely elegant. This is one of the most read pages on Algebrica. algebrica.org/cosine-similar…

    → View original post on X — @deeplearn007, 2026-04-05 13:22 UTC

  • BM25: The Powerful 30-Year-Old Search Algorithm Still Beating Vectors
    BM25: The Powerful 30-Year-Old Search Algorithm Still Beating Vectors

    Stop using vector search everywhere! A 30-year-old algorithm with zero training, zero embeddings, and zero fine-tuning still powers Elasticsearch, OpenSearch, and most production search systems today. It's called BM25. Let me explain what makes it so powerful: Imagine you're searching for "transformer attention mechanism" in a library of ML papers. BM25 asks three simple questions: "How rare is this word?" Every paper contains "the" and "is", which makes it useless. But "transformer" is specific and informative. BM25 boosts rare words and ignores the noise. → This is IDF(qᵢ) in the formula "How many times does it appear?" If "attention" appears 10 times in a paper, that's a good sign. But 10 vs 100 occurrences won't make much difference. BM25 applies diminishing returns. → This is f(qᵢ, D) combined with k₁ that controls saturation "Is this document unusually long?" A 50-page paper will naturally contain more keywords than a 5-page paper. BM25 levels the playing field so longer documents don't cheat their way to the top. → This is |D|/avgdl controlled by parameter b Three questions. No neural networks. No training data. Just elegant math (refer to the image below) The best part: BM25 excels at exact keyword matching – something embeddings often struggle with. If your user searches for "error code 5012," embeddings might return semantically similar results. BM25 will find the exact match. This is why hybrid search exists. Top RAG systems today combine BM25 with vector search. You get the best of both worlds: semantic understanding AND precise keyword matching. So before you throw GPUs at every search problem, consider BM25. It might already solve your problem, or make your semantic search even better when combined.

    → View original post on X — @akshay_pachaar, 2026-04-05 13:02 UTC

  • LLMs democratizing government transparency through data processing

    Government transparency limited by people's ability to process raw data is such an underrated problem. LLMs processing spending bills, lobbying disclosures, zoning decisions… this could genuinely change how democracy works at the local level. Super exciting.

    → View original post on X — @whats_ai

  • File-Based Data Management for Long-Term Memory Systems

    Everything managed in files is the way to go, just hard to manage long-standing memory still. Even with such a wikipedia version, but at least better to have more and well organized data vs. none!

    → View original post on X — @whats_ai

  • Industrial IoT Maturity Acceleration: Industry Perspectives Sought

    Industrial IoT maturity is accelerating fast. Curious about your take on this. @IIoT_World @CRudinschi @agentic_factory @shyamvaran @MasterofIoT @survivingwithan

    → View original post on X — @fogoros, 2026-04-05 12:37 UTC

  • Better Algorithm for Tracking AI World on X

    I built a better algorithm for watching the AI world here on X:

    → View original post on X — @scobleizer

  • China Builds Massive Robot Training Data Factories at Scale

    Those who work in manual trades still say they will never be replaced… take a look at what follows. China is building data factories for robots. On a scale that no one had anticipated. What you see in this video: rows of human operators equipped with VR headsets and

    → View original post on X — @vision_ia

  • Context Layer: The Core of Enterprise AI Stack Architecture

    One of the core things we’re going to have to contend with in AI is that even the most advanced models in the word can’t have all the relevant knowledge needed to be useful, because everyone has different use-cases and ways they’ve designed their workflows. Perhaps most importantly, as you get into the enterprise, everyone has entirely different access levels to corporate knowledge and information. Continual learning at the model layer, even at a single enterprise level, is near impossible because every user knows and has access to something different than another user. This isn’t like coding where by and large most developers can access all the relevant stuff to their job. On a single banking team, bankers have entirely different sets of documents they’re ever allowed to see. Sanitizing this is hard and having the model keep secrets is impossible. This is why the context layer is going to always be the core part of the AI stack for applied use cases to turn general models turn into useful agents. Can’t fight the physics on this one. Harrison Chase (@hwchase17) x.com/i/article/204046441296… — https://nitter.net/hwchase17/status/2040467997022884194#m

    → View original post on X — @langchain, 2026-04-05 04:40 UTC

  • Karpathy’s LLM Knowledge Base System and the Future of Memory Infrastructure

    Karpathy posted a long thread about his most frequent use cases with LLMs recently. Not writing code, but building knowledge bases. The approach is quite hardcore: he dumps papers, articles, code repositories and other materials into a folder, then lets an LLM "compile" them into a Markdown wiki. The wiki includes summaries, backlinks, concept categorization, and articles linked to each other. The frontend uses Obsidian for viewing, and Q&A also has the LLM retrieve against the wiki. In his own words, most token consumption now isn't in manipulating code, but in manipulating knowledge. This shift is quite interesting. The entire system can also maintain itself. He wrote some LLM "health check" scripts that periodically scan the wiki for contradictory data, missing information, and potential connections, letting the LLM patch itself. The results from each Q&A can also be archived back into the wiki, making it thicker with each use. Actually, Karpathy clarified something that's happening right now: the greatest value of LLMs might not be helping you generate content, but helping you manage knowledge. But the last sentence of his post is the most worth pondering: "I think there is room here for an incredible new product instead of a hacky collection of scripts." He himself knows this system is hacked together from scripts. Obsidian + command line + manual processes—it works, but it's just a demo. And there are several problems he probably felt:
    The wiki is local Markdown files, tied to the computer—it breaks when you switch machines. Retrieval relies on the LLM's own maintained indexes and summaries; he said around 400K words it still holds up, but beyond that? He even said "I thought I had to reach for fancy RAG," just that the scale hasn't reached that point yet. A more fundamental problem is that the wiki stores knowledge, but not memory. What does that mean? Knowledge is "domain X has these concepts, and their relationships are like this." Memory is "I just read a paper last week that refutes this viewpoint, and my judgment on this direction changed." One is static, one walks with you. Karpathy's system can help you store things and search things, but it doesn't know you've changed.
    This is actually the difference between a knowledge base and a memory system. The gap isn't a better script—it's an entire architecture. The model can't just "store" and "search"; it needs to sense which information is relevant to who you are now, needs to evolve itself as you use it, needs to maintain coherence across projects and timelines. Karpathy proved with a hand-rolled solution that this direction is right. But he also proved firsthand that you can't go far with just file systems and prompts. Memory needs to be infrastructure, not a collection of scripts. [Translated from EN to English]

    → View original post on X — @elliotchen100, 2026-04-05 04:31 UTC

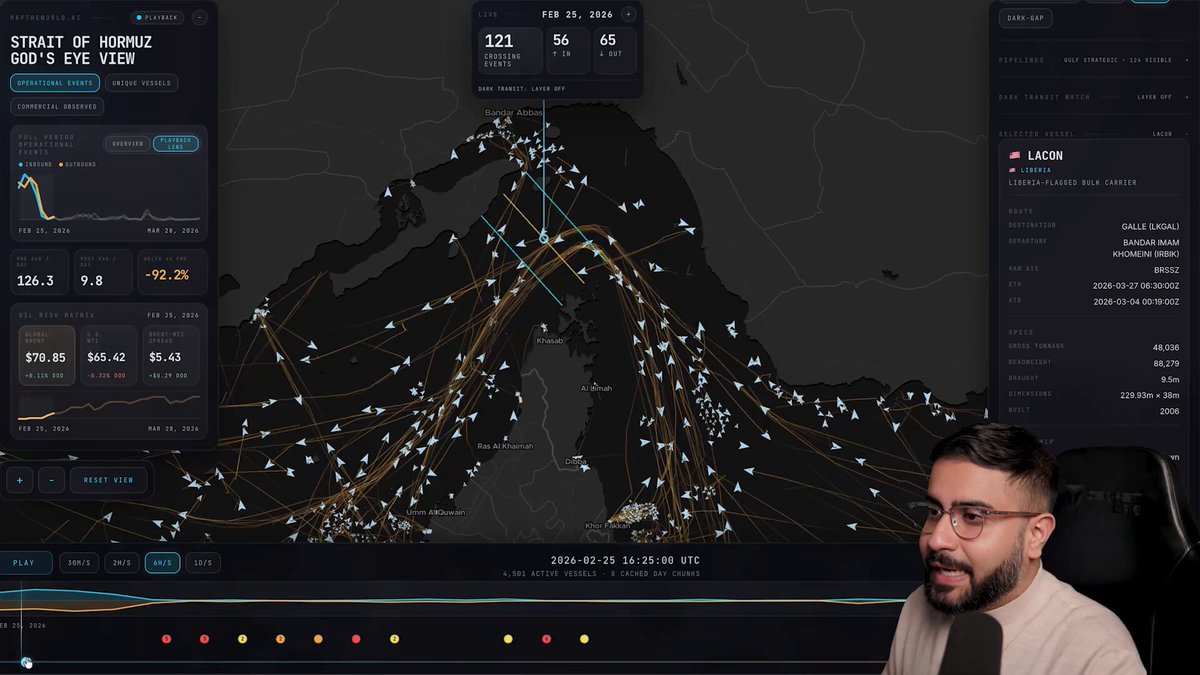
  • 4D Reconstruction of Iran’s Strait of Hormuz Oil Blockade
    4D Reconstruction of Iran’s Strait of Hormuz Oil Blockade

    i built this 4d reconstruction of iran's chokehold on the world's oil. almost nothing is getting through the strait of hormuz. you can clearly see the path ships took before/after the blockade, and can even detect & track "dark vessels" getting through. 0:00 – clearly see the before/after route change 0:26 – tracking iran's new tollbooth 1:31 – dark vessel detection 2:17 – tracking ships going dark mid-transit

    → View original post on X — @bilawalsidhu, 2026-04-05 03:06 UTC