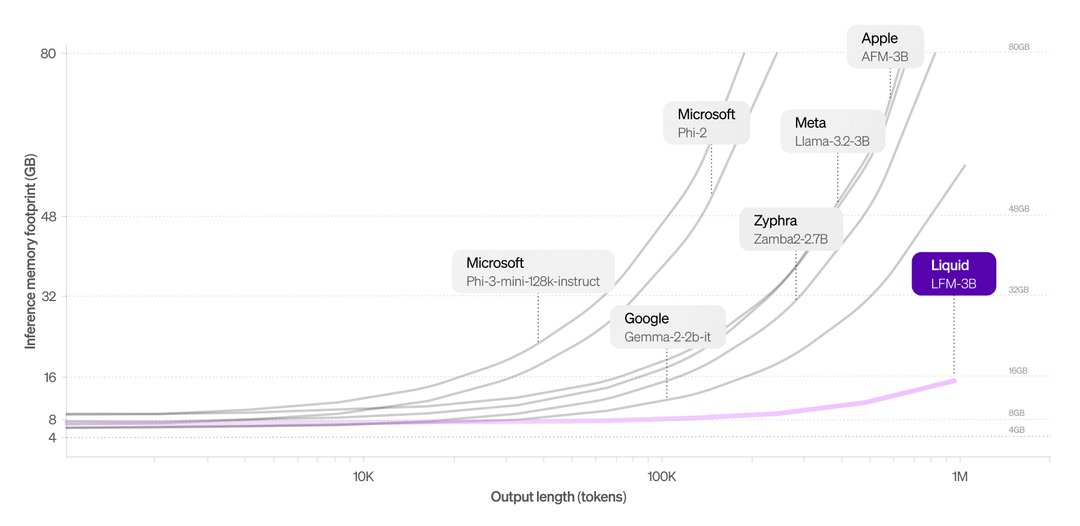
The LFM architecture is also super memory efficient. While the KV cache in transformer-based LLMs explodes with long contexts, we keep it minimal, even with 1M tokens. This unlocks new applications, like document and book analysis, directly in your browser or on your phone.
COMPUTING
-

Liquid AI Launches Three LLMs with SOTA Performance and Edge Optimization
By
–
This is the proudest release of my career 🙂 At @liquidai
, we're launching three LLMs (1B, 3B, 40B MoE) with SOTA performance, based on a custom architecture. Minimal memory footprint & efficient inference bring long context tasks to edge devices for the first time! -
Scaling compute requirements for AI usage demand
By
–
They will also need much more compute power to fulfill usage demand in case it pops up
-
SambaNova Cloud: Fastest API for Developers Unveiled
By
–
In case you missed it: @Tobias_Writes of @TheRegister shared a deep dive into the fastest #API for developers — SambaNova Cloud. Make sure to check out his article https://
theregister.com/2024/09/10/sam
banovas_inference_cloud/
… Start developing http://
cloud.sambanova.ai -
AlphaChip: Reinforcement Learning Designs Google TPU Physical Layout
By
–
3). AlphaChip – a reinforcement learning-based method trained to design the physical layout of chips; AlphaChip is reportedly used in three additional generations of Google’s TPU…https://t.co/kM6HcgSTj4
— DAIR.AI (@dair_ai) 29 septembre 20243). AlphaChip – a reinforcement learning-based method trained to design the physical layout of chips; AlphaChip is reportedly used in three additional generations of Google’s TPU…
-

ECCV 2024 Event: AI Agents Workshop Suite 9 at 2pm
By
–
It will happen soon, at 2pm, suite 9! I will be there with co-organizers @Alvaro_kai93 @vtaohu #ECCV2024 Webpage: https://
sites.google.com/view/avgenl -

Python-Speed AI Model Performance in Google Colab
By
–
It is very close to Python's print word per second" in Google Colab. Amazing!!
-
Distributed Neural Network Training: From 1990 to Large Scale
By
–
I did an undergrad thesis on parallel training of neural networks in 1990, then detoured through HIV/AIDS forecasting, compiler optimizations, information retrieval, distributed computation and storage systems before returning to large scale distributed training of neural
-

7 Free Cloud IDEs for Data Science Development
By
–
7 Free Cloud IDE for Data Science That You Are Missing Out: Access a pre-built Python environment with free GPUs, persistent storage, and large RAM. These Cloud IDEs include AI code assistants and numerous plugins for a fast and efficient development… https://
kdnuggets.com/7-free-cloud-i
de-for-data-science-that-you-are-missing-out?utm_source=dlvr.it&utm_medium=twitter&utm_campaign=7-free-cloud-ide-for-data-science-that-you-are-missing-out
… -
Spanish surgeon performs remote surgery on patient 8000 kilometers away
By
–
Une prouesse qui en dit long sur le monde dans lequel nous entrons : un chirurgien espagnol opère depuis Bordeaux un patient situé à Pékin pour lui retirer une tumeur. Fascinant. https://
ouest-france.fr/sante/un-chiru
rgien-retire-la-tumeur-dun-patient-qui-se-trouve-a-8-000-km-de-lui-grace-a-la-telechirurgie-1555ea82-7b48-11ef-977d-be93a24a1048
…