shipping a few new tools for developers today! from last devday to this one: *98% decrease in cost per token from GPT-4 to 4o mini
*50x increase in token volume across our systems
*excellent model intelligence progress
*(and a little bit of drama along the way)
COMPUTING
-
OpenAI Releases Developer Tools with 98% Cost Reduction
By
–
-

Supercloud: Seamless Multi-Cloud Migration Without Traditional Limitations
By
–
Supercloud is an evolution in cloud computing where boundaries between providers become less relevant, allowing for seamless migration and offering businesses cost-effective, scalable solutions without the traditional limitations of multi-cloud. Microblog @antgrasso #Supercloud
-
Broadcom’s Software-Defined Edge Lifecycle Management Solutions
By
–
Broadcom's enhanced Software-Defined Edge includes lifecycle management features that streamline application updates, improve scalability, and ensure businesses can efficiently manage diverse environments.
-
LLama 3.2 1GB 2GB Versions Enable Ubiquitous Deployment
By
–
in case you missed it: LLama 3.2 in 1GB and 2GB sized version run it everywhere…
-
AWS Community Day Saudi Arabia 2024: Innovation and Cloud Collaboration
By
–
AWS Community Day Saudi Arabia 2024: A Journey of Innovation, AI, and Collaboration At @PSU_RUH
, an exciting energy filled the air during the @awscloud Community Day Saudi Arabia 2024—a community-driven event that brought together developers, cloud enthusiasts, and tech -

SambaNova Cloud Delivers Fastest Llama 3.1 Inference
By
–
We've spoken with the devs and they've told us what they need: fast inference. ⚡️
— SambaNova (@SambaNovaAI) 30 septembre 2024
SambaNova Cloud delivers the fastest inference on @AIatMeta's Llama 3.1 405B, 70B and 8B — all running at full precision.
Start developing 👉 https://t.co/zm6RCXY00n#API #AI @aton2006 pic.twitter.com/ORu1lalYAhWe've spoken with the devs and they've told us what they need: fast inference. SambaNova Cloud delivers the fastest inference on @AIatMeta
's Llama 3.1 405B, 70B and 8B — all running at full precision. Start developing http://
cloud.sambanova.ai #API #AI @aton2006 -
Apple Silicon: Why Your Employer Should Invest Now
By
–
There are so many good reasons to get apple silicon. I'm sure your lovely employer would be happy to shell out 🙂
-
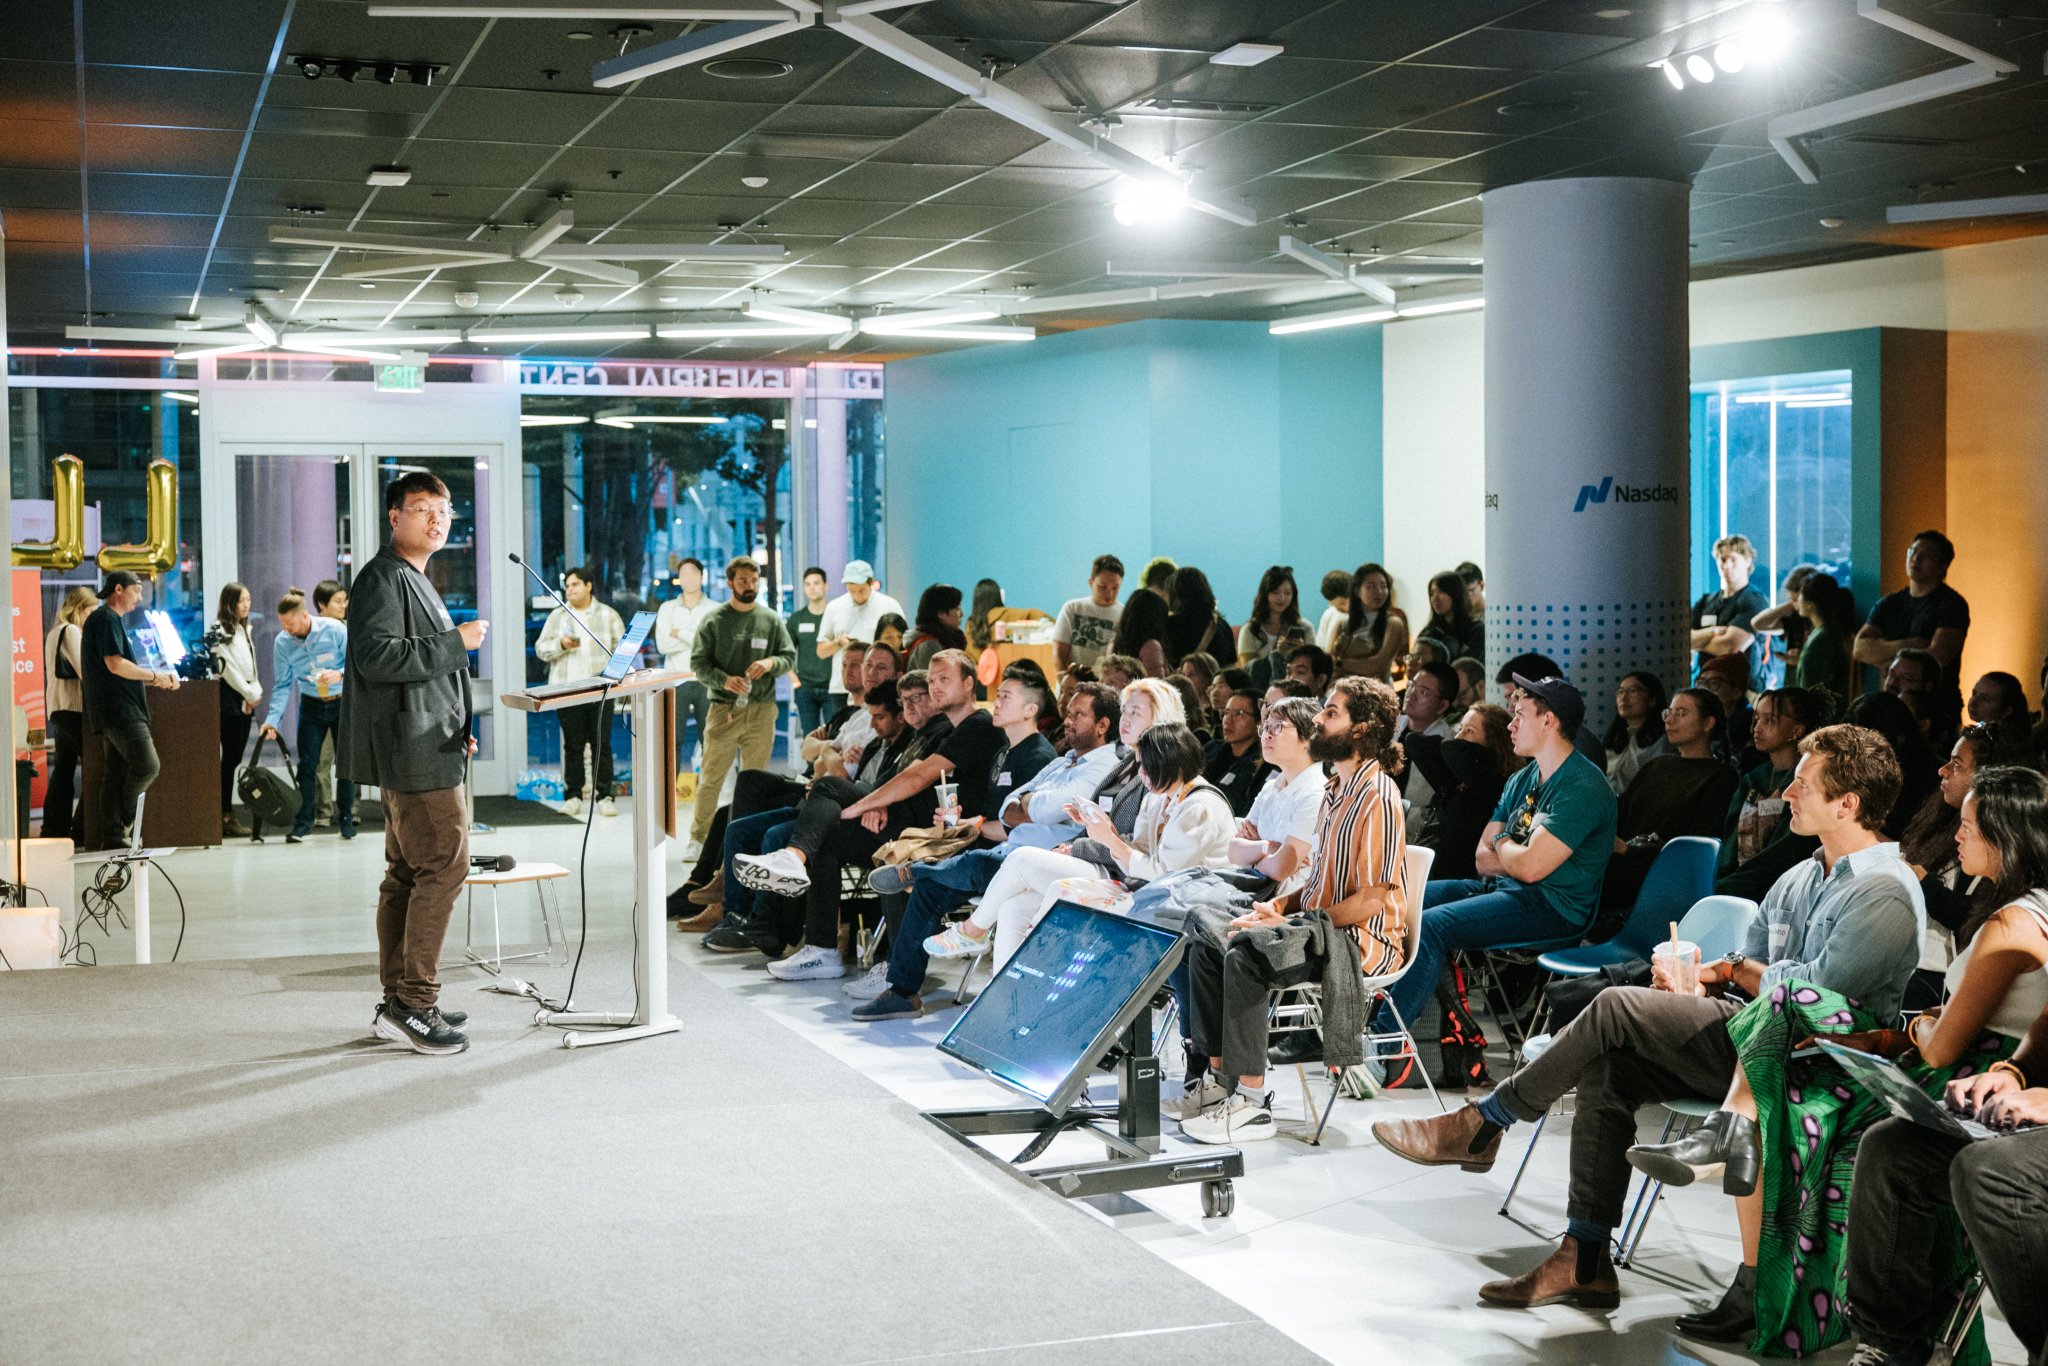
Cerebras Achieves 2000 Tokens Per Second Llama Inference
By
–
4/6 Daniel Kim, Head of DevRel at Cerebras, gave a behind the scenes talk on how to support over 2000 tok/s inference with llama models.
-
SambaNova DataScale: Fastest AI Hardware Platform for Training and Inference
By
–
Meet SambaNova DataScale, the fastest #AI hardware platform for model training, fine-tuning, & #inference! 🚀
— SambaNova (@SambaNovaAI) 30 septembre 2024
🎯 Deliver world-record performance & accuracy
🏎️ Run & switch between models quickly
🔒 Securely fine tune models
Learn more ⤵️https://t.co/LIKsyCMJTO pic.twitter.com/EWtZH6lPbXMeet SambaNova DataScale, the fastest #AI hardware platform for model training, fine-tuning, & #inference! Deliver world-record performance & accuracy Run & switch between models quickly Securely fine tune models Learn more https://
sambanova.ai/products/datas
cale
… -
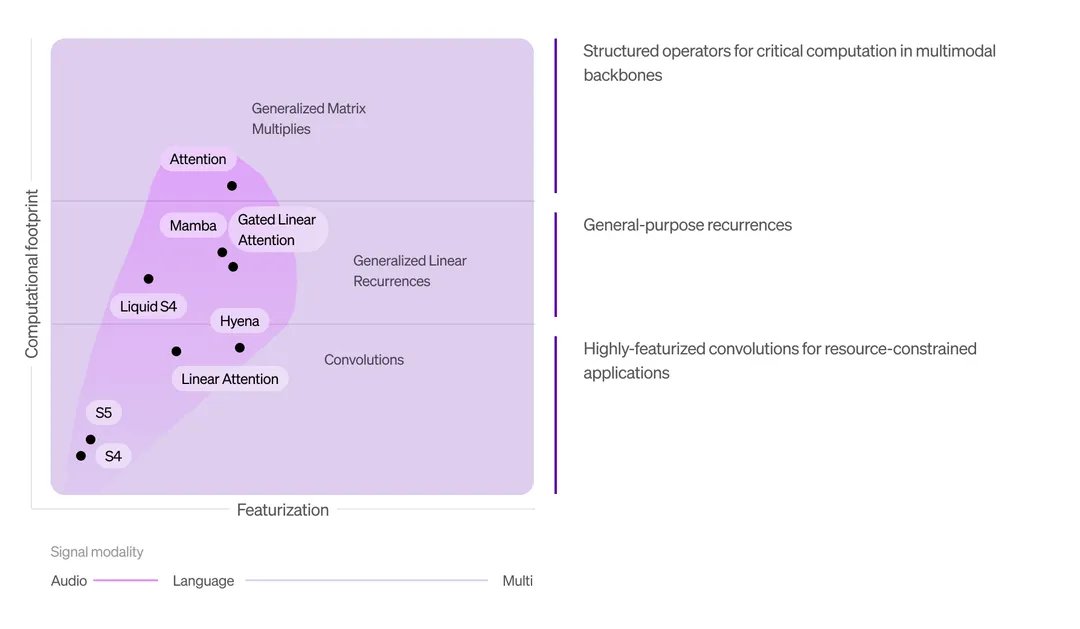
LFM Architecture Enables New Foundation Model Design Space
By
–
The LFM architecture opens a new design space for foundation models. This is not restricted to language, but can be applied to other modalities: audio, time series, images, etc. It can also be optimized for specific platforms, like @Apple
, @AMD
, @Qualcomm
, and @cerebras