Ten Years of Digital Progress: Building an Inclusive and Future-Ready India Read More: https://
pib.gov.in/PressNoteDetai
ls.aspx?NoteId=154788&ModuleId=3
…
COMPUTING
-
India’s Digital Progress: Ten Years of AI and Technology
By
–
-
Scaling LLM Inference Compute: Adaptive Branching Tree Search
By
–
Our paper: “Wider or Deeper? Scaling LLM Inference-Time Compute with Adaptive Branching Tree Search”
-
Engineering work underway to boost AI performance
By
–
Lots of background engineering work going on to improve performance !
-
T-Mobile 5G Infrastructure Enables Robotics and Immersive Media
By
–
It is great to see how @TMobileBusiness is turning 5G from buzzword to real-time infrastructure. When networks become enablers of immersive media, robotics, and continuity at scale, we’re watching the future in action.
-
Google Drive as a Universal RAG Sharing Tool
By
–
Google Drive is slowly becoming a universal RAG sharing tool, as you can connect it to almost any LLM now. This will also be huge for Workspace accounts.
-
NVIDIA Edge AI Solution Drives Innovation Forward
By
–
Congratulations! Proud to see our NVIDIA Edge AI solution driving innovation at the edge
-
Draft Model Pruning Achieves 43% Fewer MACs with Strong Performance
By
–
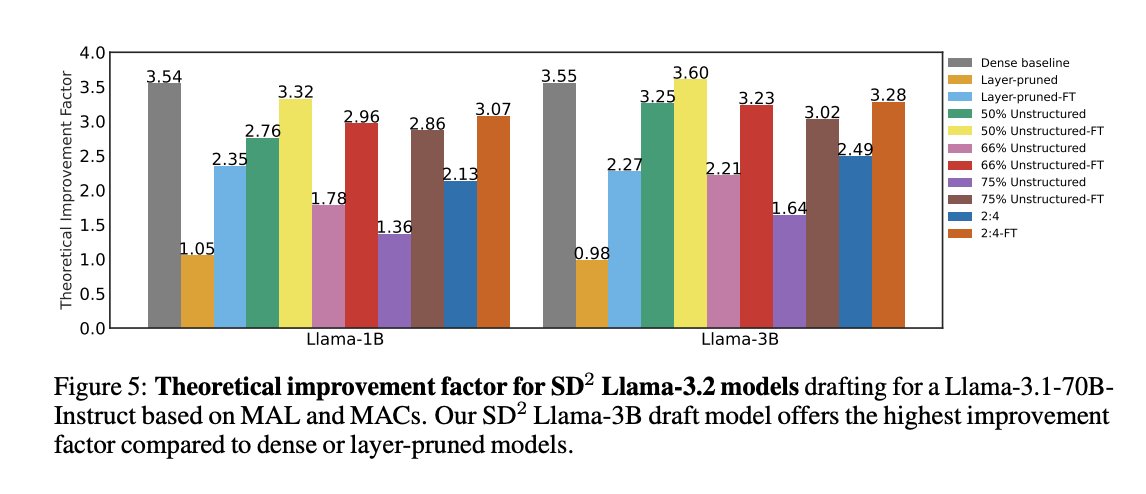
The results: – 1.59× higher Mean Accepted Length (MAL) than layer-pruned draft models
– 43.87% fewer MACs (Multiply-Accumulate operations) than dense draft models
– Only 8.36% reduction in MAL vs. dense models — a strong tradeoff for efficiency -
SD² Enhances Draft Token Acceptance Reducing MACs
By
–
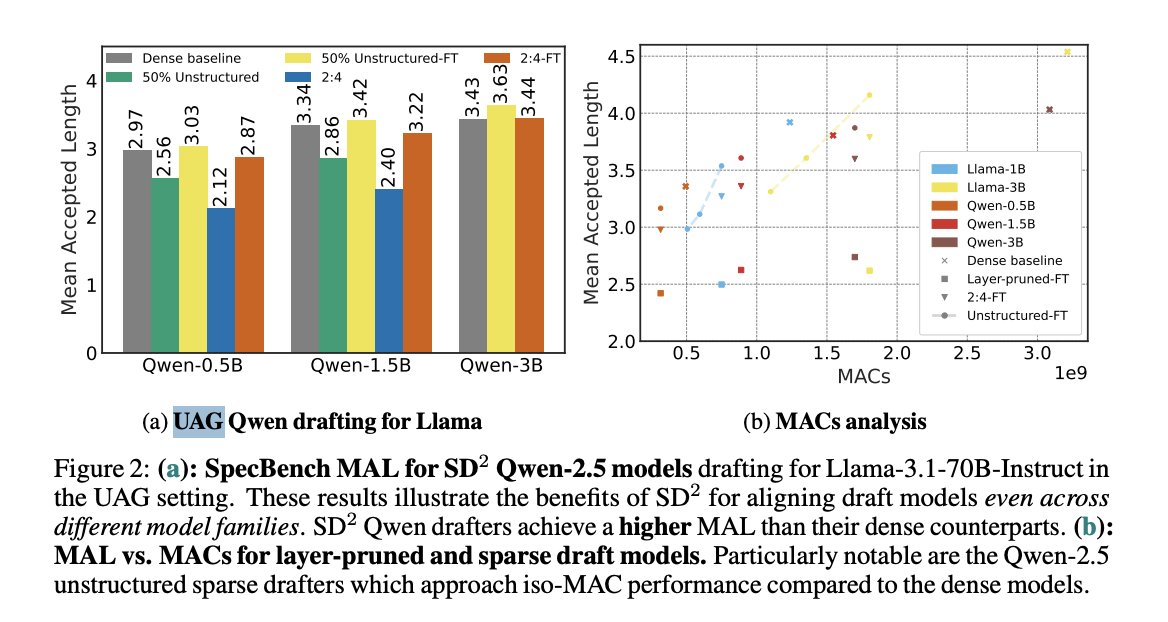
SD² systematically enhances draft token acceptance rates while significantly reducing Multiply-Accumulate operations (MACs), even in the Universal Assisted Generation (UAG) setting, where draft and target models originate from different model families.
-
SD² Self-Distilled Sparse Drafters Speeds Up LLM Inference
By
–
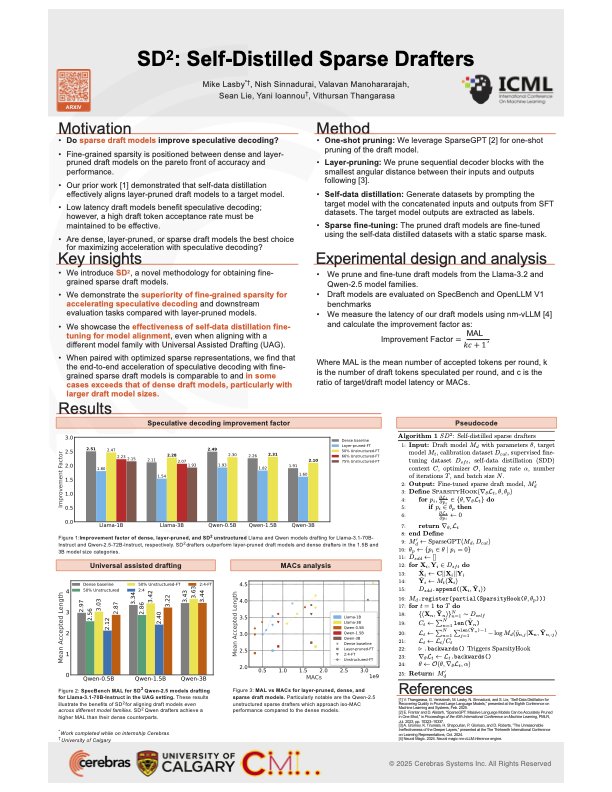
Featured Paper at @icmlconf – The Internationall Conference on Machine Learning: SD² – Self-Distilled Sparse Drafters Speculative decoding is a powerful technique for reducing the latency of Large Language Models (LLMs), offering a fault-tolerant framework that enables the
-
Energy sources crucial for AI competitiveness against China
By
–
We need all power sources, as much as possible, if we want to stand any chance of competing with China in AI. Why does being pro-coal mean you have to be anti-solar?