The three.js visualization parses the output of llama-cpp's ggml debug output (of unsloth llama 3.1) to directly obtain all the tensor calculations happening under the hood. Operations (MUL_MAT, ROPE, RESHAPE, ADD) are grouped into query, key, value, MLP, and residual stream
CODE
-
LlaMA Tensor Trace Tool for Model Analysis
By
–
Fly through LlaMA here! https://
alphaxiv.org/labs/tensor-tr
ace
… -
3D Illustrated Transformer: Interactive LLaMA Learning Tool
By
–
Introducing the Illustrated Transformer in 3D 🚀
— alphaXiv (@askalphaxiv) 29 octobre 2025
Fly through LLaMA like never before. See every tensor and operation in motion.
Click any component to reveal the exact lines of code that run it.
A new way to learn and teach LLMs. Try it out in the link below 👇 pic.twitter.com/pBpEZyse2vIntroducing the Illustrated Transformer in 3D Fly through LLaMA like never before. See every tensor and operation in motion. Click any component to reveal the exact lines of code that run it. A new way to learn and teach LLMs. Try it out in the link below
-
DeepSeek-OCR OmniDocBench: Document Recognition Benchmark
By
–
Detailed report + code: https://
github.com/alphaXiv/DeepS
eek-OCR-OmniDocBench/blob/main/REPORT.md
… Datasets page: http://
alphaxiv.org/datasets/shang
hai-ai-laboratory/omnidocbench
… -

GitHub announces Agent HQ with coding agents
By
–

GitHub announced Agent HQ. "Over the coming months, coding agents from Anthropic, OpenAI, Google, Cognition, xAI, and more will become available directly within GitHub." GitHub Copilot Pro+ users can access Codex in VS Code Insiders with their current subscription.
-

LFM2-ColBERT-350M Achieves Competitive Inference Speed
By
–
LFM2-ColBERT-350M is also very fast! Its inference speed is on par with GTE-ModernColBERT-v1 (only 150M parameters) for query and document encoding across various batch sizes.
-
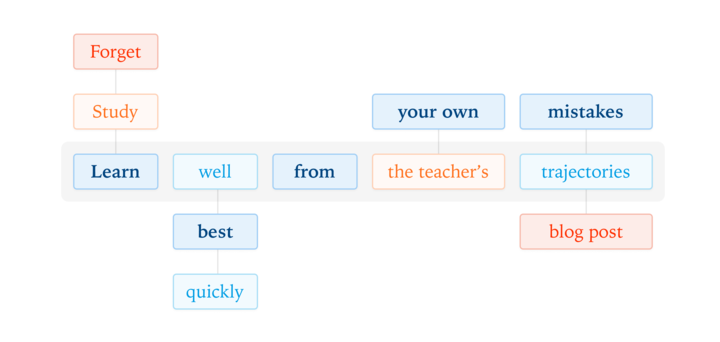
On-Policy Distillation: Combining RL Error Correction with SFT Reward Density
By
–
On-policy distillation provides an elegant way to use the teacher model as a process reward model to provide dense reward while preventing SFT style "OOD shock" during rollout. Thinking Machines (@thinkymachines) Our latest post explores on-policy distillation, a training approach that unites the error-correcting relevance of RL with the reward density of SFT. When training it for math reasoning and as an internal chat assistant, we find that on-policy distillation can outperform other approaches for a fraction of the cost. thinkingmachines.ai/blog/on-… — https://nitter.net/thinkymachines/status/1982856272023302322#m
→ View original post on X — @lilianweng, 2025-10-27 17:31 UTC
-

PyTorch MPS Backend Bug: Silent Tensor Contiguity Failures
By
–
Beautiful technical debugging detective longread that starts with a suspicious loss curve and ends all the way in the Objective-C++ depths of PyTorch MPS backend of addcmul_ that silently fails on non-contiguous output tensors. I wonder how long before an LLM can do all of this.
-
Concise MLOps Guide and Complete Machine Learning Package
By
–
I wrote a concise guide to MLOps sometime back(a supplement to complete machine learning package). MLOps: https://
github.com/Nyandwi/machin
e_learning_complete/blob/main/010_mlops/1_mlops_guide.md
…
ML Complete Package: https://
nyandwi.com/machine_learni
ng_complete/
… -
Deep Generative Models: Complete Lecture Resources and Materials
By
–
Deep Generative Models Lectures: videos, slides, notes, papers