Congrats, and great news regarding the continued support of open source 🙂
CODE
-

Claude Code Bash Alias for Fast VPS Coding Workflow
By
–

Update on my Claude Code alias I put in ~/.bashrc to code fast on VPS: c() { IS_SANDBOX=1 claude –continue –dangerously-skip-permissions "$@"; –continue makes it continue the last session in case it logs out To add it: echo 'c() { IS_SANDBOX=1 claude –continue
-
Learning New Programming Languages Zero-Shot: Achievable Challenge
By
–
You won't convince me that approaching a new programming language and working with it zero-shot is insurmountable. At my first job I had to work with a stack I had zero experience in (aside from Python) and I was shipping PRs in my first week. I had <1000 hours of programming
-
Software Engineers Should Learn New Programming Languages
By
–
For those saying "I couldn't do it either!" — I *do* think that a software engineer should be able to look at a new programming language and start solving familiar problems in the language while consulting the docs. Even if it takes more effort and more iterations. You shouldn't
-
Language Models Struggle with Esoteric Programming Languages
By
–
All models struggle in this benchmark because languages are: Brainfuck, Whitespace, Unlambda, Shakespeare. 😅
— Alex J. Champandard 🌱 (@alexjc) 19 mars 2026
If you actually pick a useful but still esoteric language like Joy, the frontier models do great (they *can* reason), but the open source ones struggle (they memorize). https://t.co/E5Mozy0yEBAll models struggle in this benchmark because languages are: Brainfuck, Whitespace, Unlambda, Shakespeare. If you actually pick a useful but still esoteric language like Joy, the frontier models do great (they *can* reason), but the open source ones struggle (they memorize).
-
4-bit Quantization Fixes Tool Calling Performance Issues
By
–
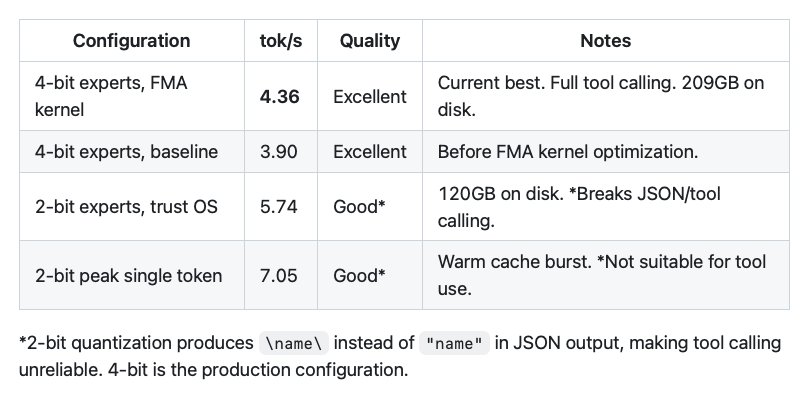
Dan found that the 2-bit quantization broke tool calling but upgrading to 4-bit (at 4.36 tokens/second) got that working
-
LLM Coding Benchmarks Questioned Real World Performance
By
–
These kind of claims never pass the sniff test. Benchmarks can be cheated, but if it worked 0-11% of the time on real tasks (which are not part of benchmarks) nobody would ever use LLMs for coding. https://t.co/zp1qpQjf3P
— Peter Gostev (@petergostev) 19 mars 2026These kind of claims never pass the sniff test. Benchmarks can be cheated, but if it worked 0-11% of the time on real tasks (which are not part of benchmarks) nobody would ever use LLMs for coding.
-
AI Agent Iteratively Building and Editing Complex Workflows
By
–
good thing is that it can also edit an already-existing workflow, so if the workflow becomes too complex you can also have the agent building it chunk by chunk
-

Real AI Agent Impact Examples That Will Amaze You
By
–
I have a very long list of real AI agent impact that I've been collecting. Here are some that will make your jaw drop. – Fixed a production bug from a tweet screenshot while the dev was on vacation in Morocco. He didn’t have a laptop. Just a phone notification and an agent that handled it – Negotiated a car purchase. An AI agent went back and forth with the dealership. Saved the human $4,200 on a Hyundai Palisade. The car dealer did not know they were negotiating with AI – Generated 1,000 hyper-targeted sales leads for $6 – Built a full YouTube analytics dashboard overnight. Owner woke up, opened their browser, and it was ready As creator of OpenClaw @steipete put it: 'It is just like having a new weird friend that is also really smart and resourceful that lives on your computer.' If you wanna learn more about AI agents, join my free workshop on March 25 at 12pm ET: events.alliekmiller.com/
→ View original post on X — @alliekmiller, 2026-03-19 17:28 UTC