
Cursor's new in-house model now competes with GPT-5.4 and Opus 4.6 on coding. The difference: it's 10-20x cheaper to run. Composer 2 Fast output tokens: $7.50 / million. GPT-5.4 Fast: $75. Opus 4.6 Fast: $150. Terminal-Bench 2.0 scores: Composer 2 at 61.7, Opus 4.6 at 58.0,
CODE
-
Vibe Coding vs. Traditional Coding: A Skill Comparison
By
–
Don’t use a calculator until you can do the math on your own. Don’t vibe code until you can code – and debug and maintain code – on your own. It’s that simple.
-

OpenAI Monitors 99.9% of Internal Traffic to Detect Anomalies
By
–
Sharing some of the work I've been doing at OpenAI: we now monitor 99.9% of internal coding traffic for misalignment using our most powerful models, reviewing full trajectories to catch suspicious behavior, escalate serious cases quickly, and strengthen our safeguards over time. [Translated from EN to English]
-

Cyberpunk robot prompt as a potential Copilot feature
By
–
"cyberpunk hacker robot working in front of many monitors" test. Would be a nice upgrade for Copilot!
-
OpenAI acquires Astral: uv, ruff, and Typer tools
By
–
Thoughts on OpenAI acquiring Astral and uv/ruff/ty
-
Open Source AI Inference: Competition and Community Contribution
By
–
as babyagi turns 3 yrs old, i finally sat down to compare the 9 iterations i did over the years…
— Yohei (@yoheinakajima) 19 mars 2026
this turned into https://t.co/x2evpDgcIM
a technical history of a personal project (which kind of captures the progress of the agent space overall) pic.twitter.com/L8fTiEAcM8as babyagi turns 3 yrs old, i finally sat down to compare the 9 iterations i did over the years… this turned into http://
babyagi.wiki a technical history of a personal project (which kind of captures the progress of the agent space overall) -

Frontier-Level Coding Model Pricing Tiers Revealed
By
–
It's frontier-level at coding, priced at: – Standard: $0.50/M input and $2.50/M output
– Fast: $1.50/M input and $7.50/M output -
LLM Performance Falls Apart on Unmemorizable Coding Benchmarks Due to Distribution Shift
By
–
Pretty shocking result (that once again confirms what I wrote about the perils of distribution shift, 25 years ago):
— Gary Marcus (@GaryMarcus) 19 mars 2026
Translate coding benchmarks into languages LLMs can’t memorize and performance utterly falls apart. https://t.co/wu5fh57nLZPretty shocking result (that once again confirms what I wrote about the perils of distribution shift, 25 years ago): Translate coding benchmarks into languages LLMs can’t memorize and performance utterly falls apart.
-
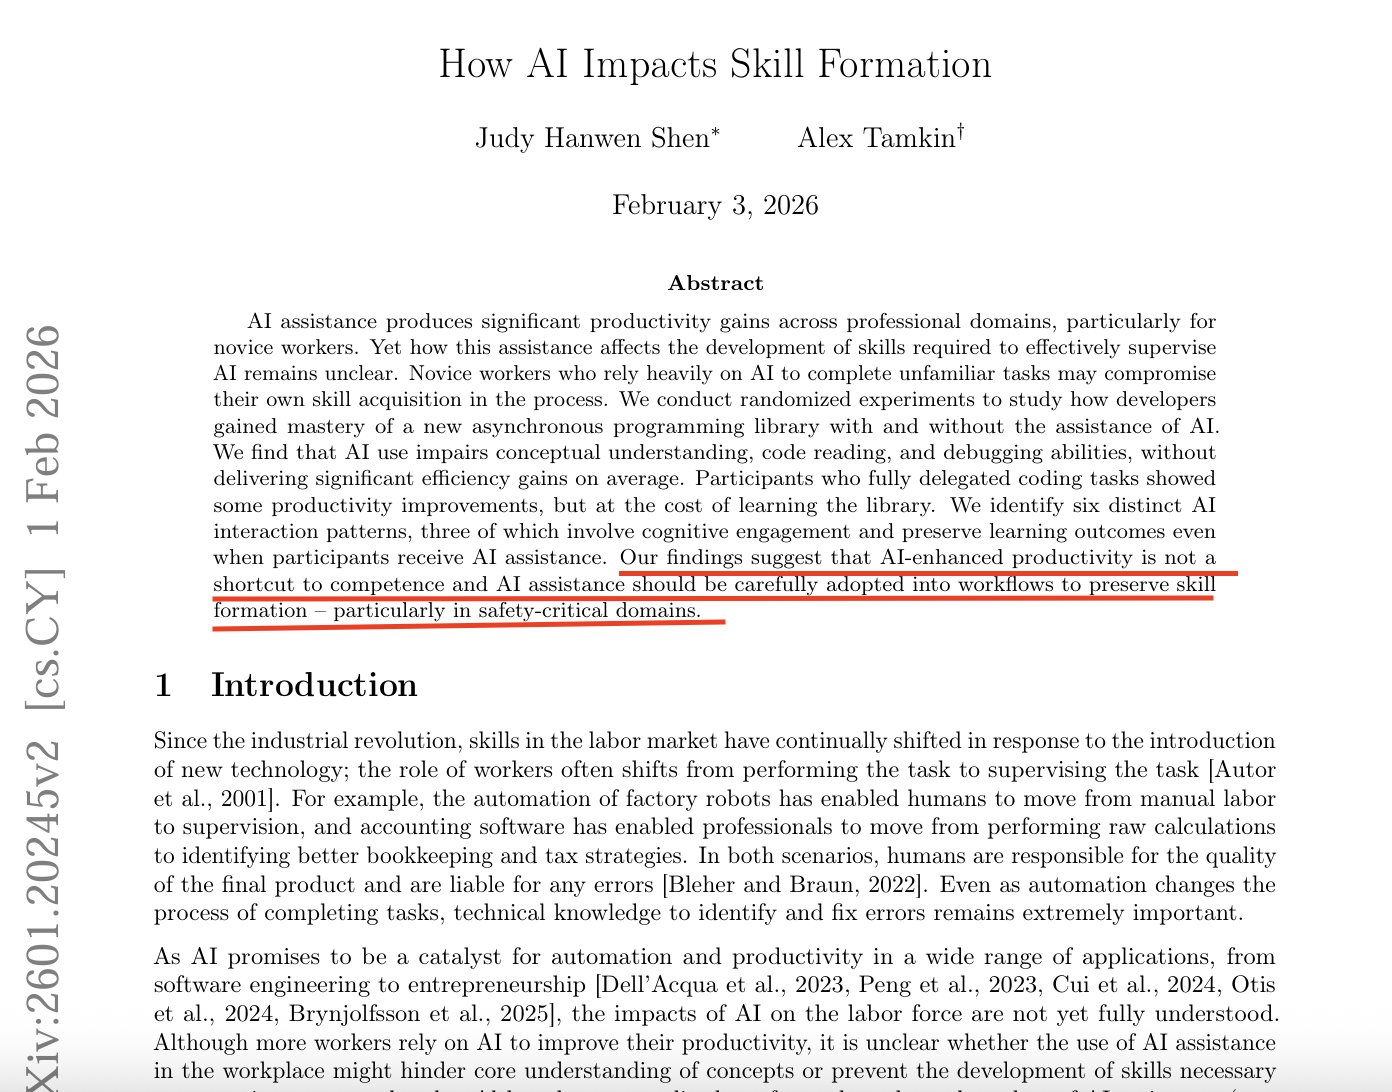
Anthropic Research: AI Use Impairs Conceptual Understanding, Code Reading, and Debugging
By
–
“AI use impairs conceptual understanding, code reading, and debugging without delivering significant efficiency gains” — and that’s a quote from Anthropic’s own research!
