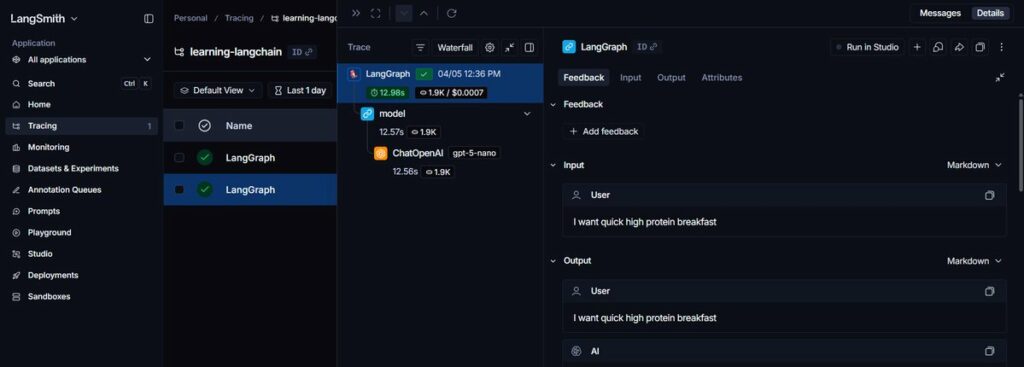
Day 3 of becoming 100xdevs: – make a travel agent with mcp – learn about the state – learn about runtime context – making multiagents – tracking sub-agents from Langsmith Akash (@akashcorex) Day 2 of becoming 100xdevs: – LangSmith tracking of each agent – how to create MCP – run MCP locally and use it – create a travel agent with mcp + ai — https://nitter.net/akashcorex/status/2040872532816154958#m
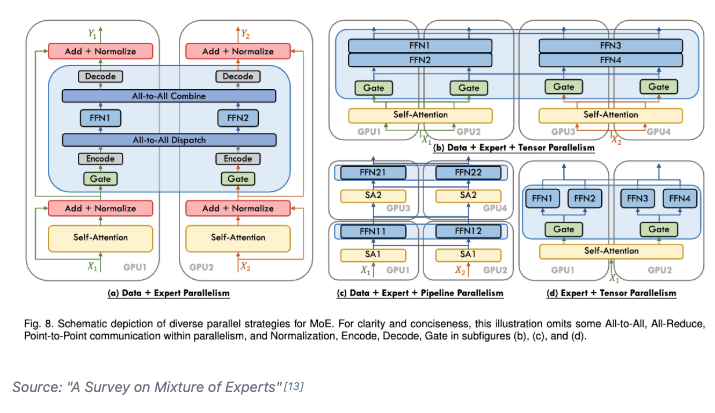
Day 93/365 of GPU Programming Studying parallelism today and stumbled upon this incredible blog post/book The Ultra-Scale Playbook: Training LLMs on GPU Clusters by Hugging Face that dives deep into data parallelism, expert parallelism, tensor parallelism, pipeline parallelism and context parallelism. I've read a bit about each of these methodologies before but this is the best resource I've found that really pieces them all together into a unified coherent picture. Kinda like its name implies, the team goes into actual empirical examples based on the 4000 scaling experiments (across up to 512 GPUs!) they conducted. E.g. how does tensor parallelism reduce activation memory for matmuls but still require gathering full activations for LayerNorm? When does pipeline parallelism's bubble overhead outweigh its memory savings? When and why would you combine TP/PP/DP on a specific cluster topology? What's the real memory breakdown between params, gradients, optimizer states and activations and which parallelism strategy targets which? et cetera Also loved all the beautiful and sometimes interactive diagrams that reminded me of distill.pub (which makes sense given they used distill's template to create the post). I wish more blog posts in ML would use a similar approach to help visual learners understand the content at an intuitive level. Especially now that rich visualizations/animations are so easy to spin up with LLMs. Really wonderful work by @Nouamanetazi @FerdinandMom @xariusrke @mekkcyber @lvwerra @Thom_Wolf. In times when things are going more and more closed source in, this is such a good example of what great open source AI education and research can look like. levi (@levidiamode) Day 92/365 of GPU Programming Taking a closer look at disaggregated LLM inference today, which I've been wanting to survey more after listening to the Dean <> Daly discussion at GTC. The best resource I found on the topic was this great talk by @Junda_Chen_ on the past, present and future of prefill decode disaggregation. In the lecture, Junda goes through Nvidia's dynamo, the intrinsic tradeoff spectrum between throughput & latency, TTFT, TPOT, the "goodput" metric, distinct characteristics between prefill vs decode, chunking P&D, the problem of interference, pipeline parallelism, resource & parallelism coupling, disaggregation and DistServe. — https://nitter.net/levidiamode/status/2040938107604742640#m
We partnered with @askalphaxiv on a competition. Pick a paper, build a marimo notebook that brings the core idea to life, and become one of the few experts on your research topic. Oh, and did we mention you can win a Mac Mini + $1K in prizes? 👀 Full details found here: marimo.io/pages/events/noteb…
These results keep coming. @GaryMarcus was way ahead on calling out these problems and dangers. And we're at risk of baking these issues into systems we rely on. Lars Christensen (@MaMoMVPY) I am increasingly coming to this conclusion – there NO SIGNS the problems with hallucinations are getting solved. In fact if anything it is now spreading to coding and the use of agents where it is hidden and could led to serious problems down the road. Therefore we can't really scale LLMs. LLMs are very useful tools, but you need to know about the limitations. Most of the investments in LLMs today assumes away these limitations. — https://nitter.net/MaMoMVPY/status/2041031551182340218#m
we're building out a community middleware page for @LangChain, and we need your help growing it. agent middleware is one of the most powerful building blocks we've shipped. what are you building with it? docs.langchain.com/oss/pytho…
Want to impress employers? • Earn a SAS certification
• Build real, job-ready skills
• Add a recognized credential to your résumé Skill Builder for Students has everything you need to get certified—free digital learning, practice exams + prep materials to help you at your
We've been landing token-efficiency improvements so you can do more in your sessions. If you have a session where usage felt particularly high, can you run /bug and post the feedback id? Feel free to tag me directly
What if you could build a full Vision AI pipeline… just by describing it? In our upcoming livestream, we’re showing how NVIDIA DeepStream is transforming how developers build and deploy vision AI with coding agents like Claude Code or Cursor —cutting development cycles from weeks to hours. 🗓️ April 16, 9am PT Register 👉 nvda.ws/48psM63