Agentic AI needs CPUs, GPUs, and AI accelerators working together. @TheRegister highlights @intel
's new rack-scale agentic AI designs and the first customer deployment of the Intel + SambaNova disaggregated inference blueprint through VC2. The result: GPUs handle prefill,
AI HARDWARE
-
SambaNova post about Intel’s rack-scale agentic AI design
By
–
-

Develop Physical AI Reasoning, World, and Action Models with NVIDIA
By
–

Develop Physical AI Reasoning, World, and Action Models with NVIDIA! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux
-

Splash Music Generates Music with AWS Trainium & SageMaker HyperPod
By
–

Splash Music Transforms Music Generation using AWS Trainium and Amazon SageMaker HyperPod! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless
-
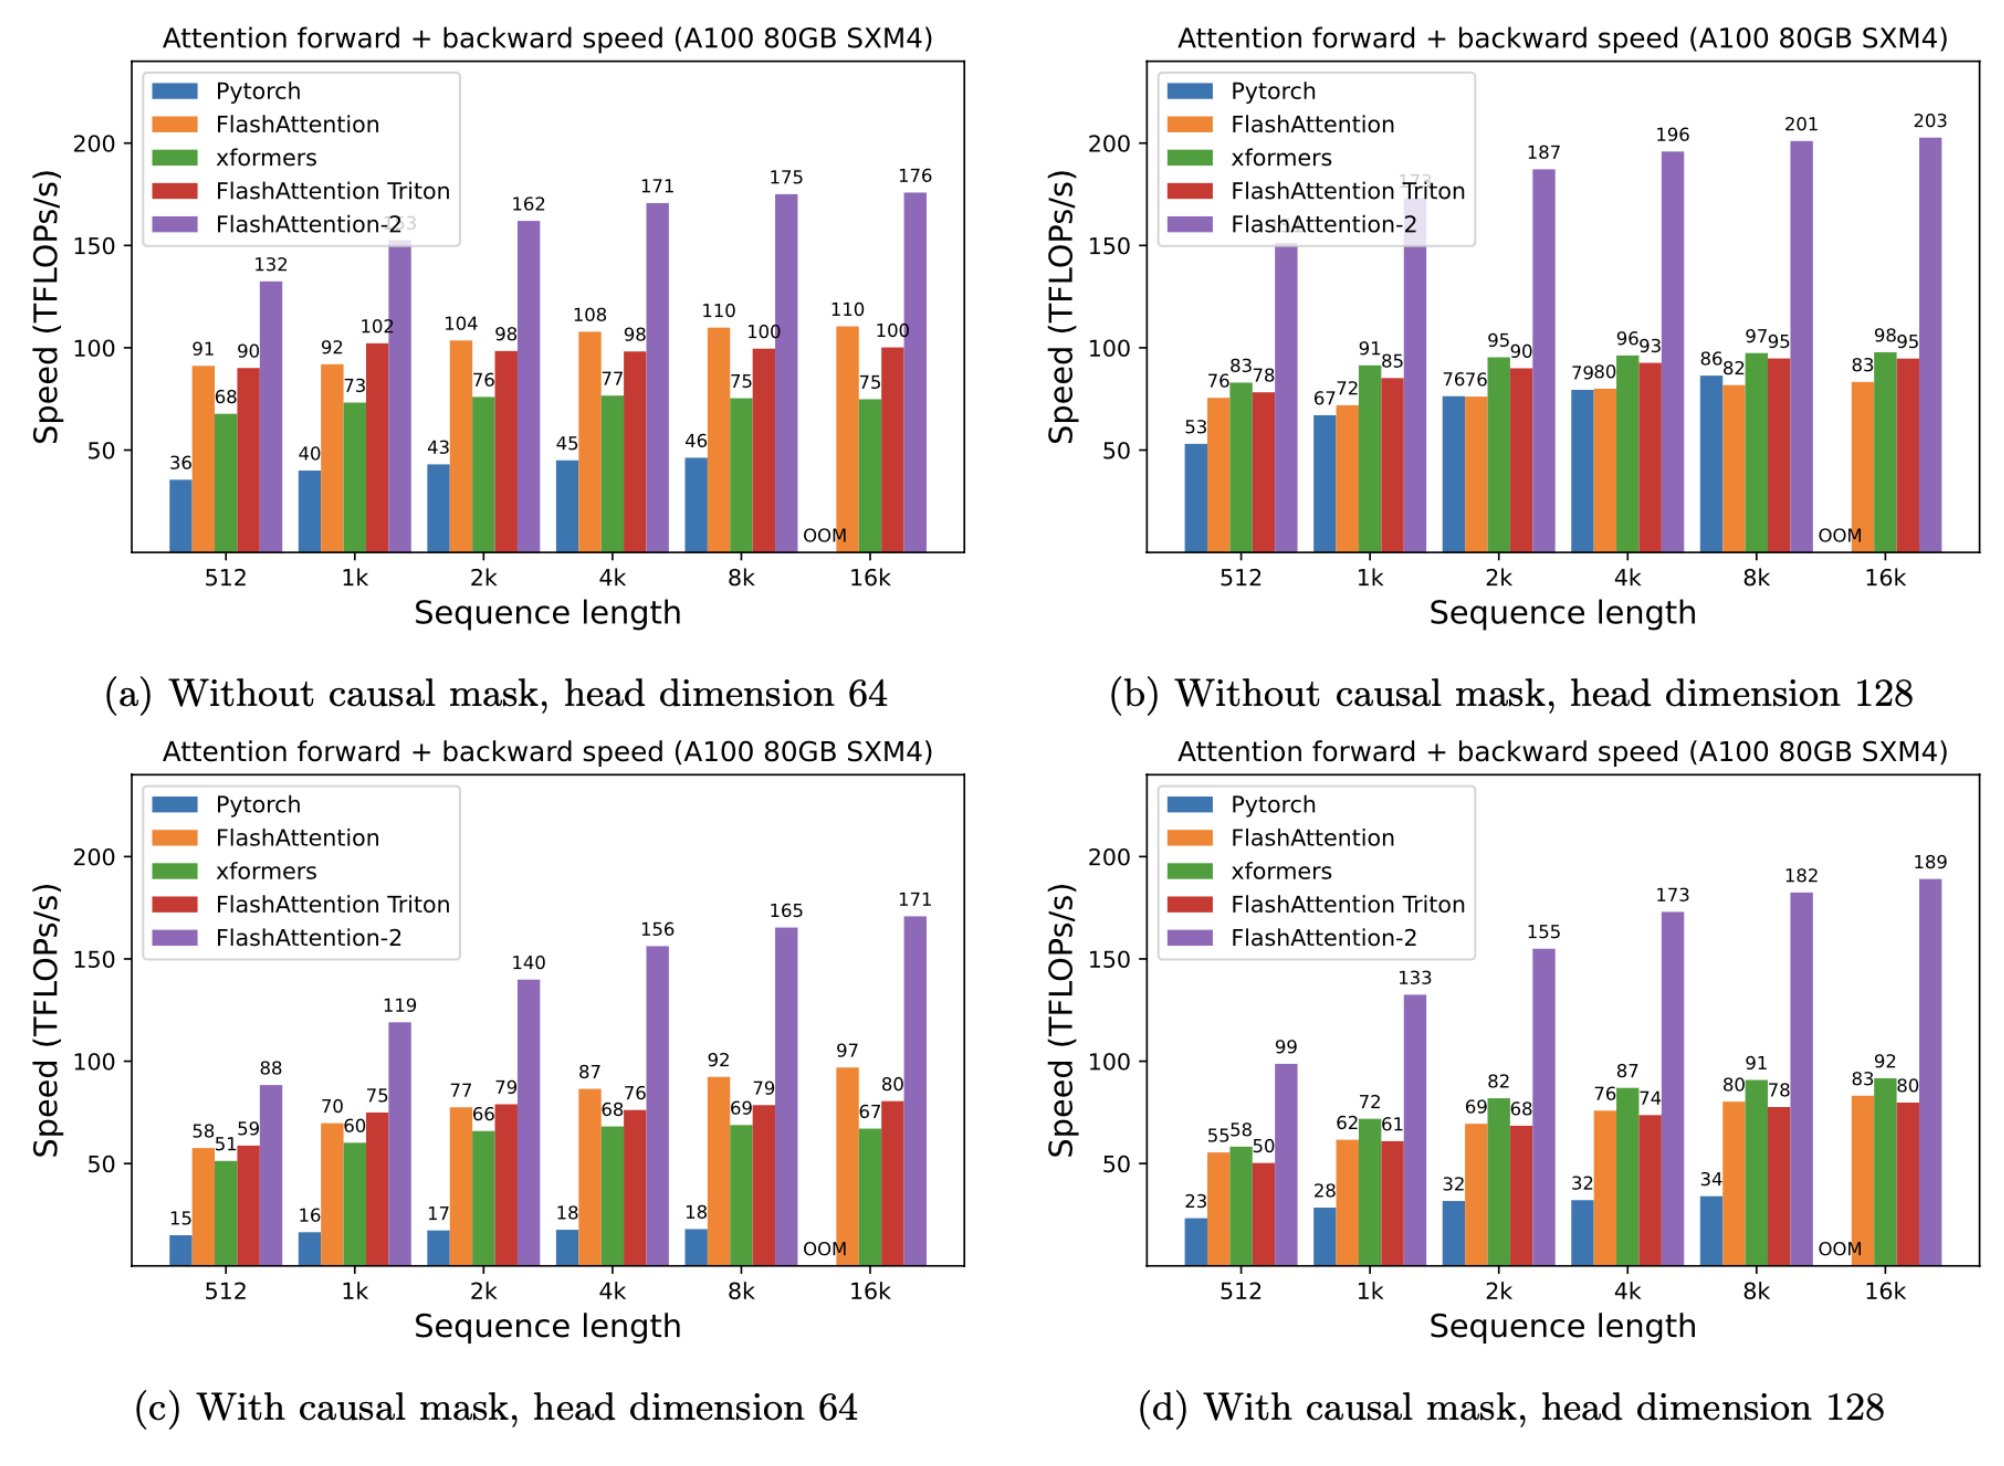
Flash Attention: Hardware-Level SRAM Caching Achieves 7.6x Speedup
By
–
Flash attention involves hardware-level optimizations wherein it utilizes SRAM to cache the intermediate results. This way, it reduces redundant movements, offering a speed up of up to 7.6x over standard attention methods. Check this
-
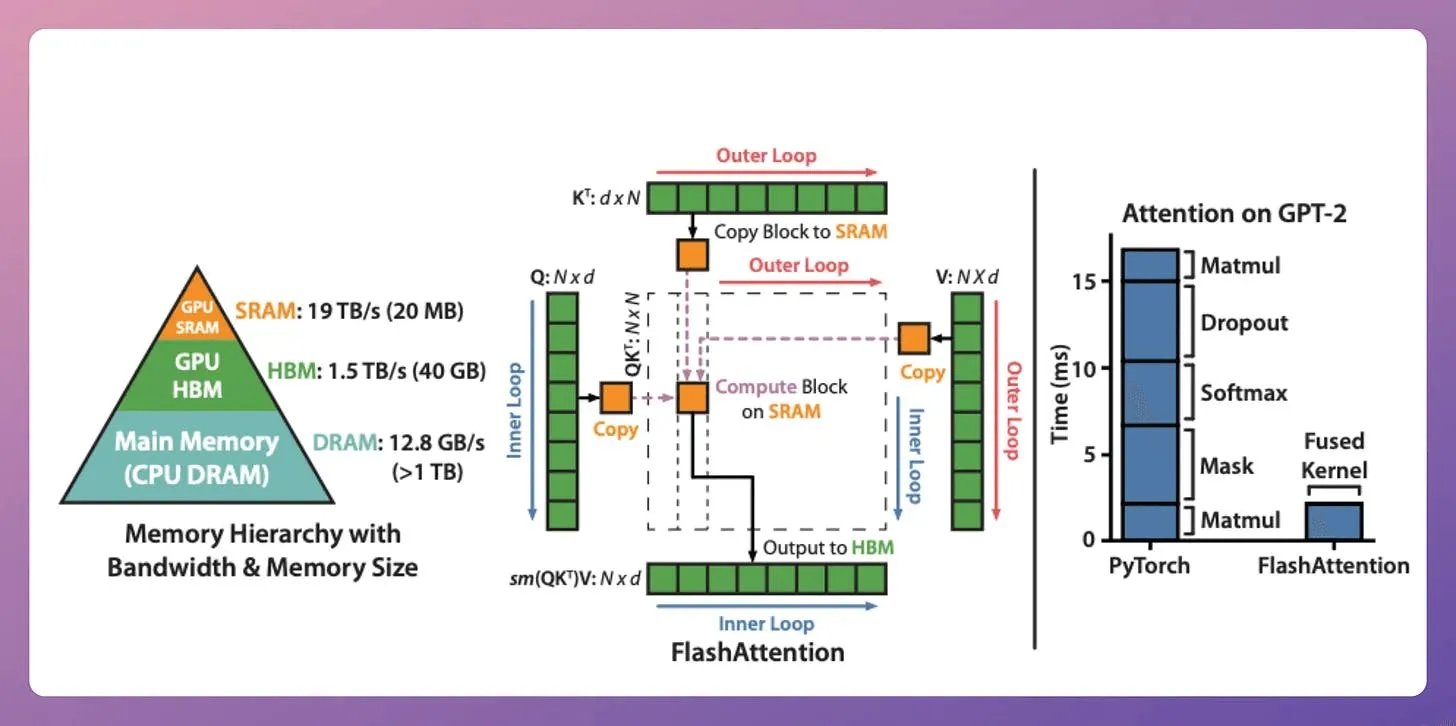
Flash Attention: Efficient Global Attention via GPU Memory Optimization
By
–
2) Flash Attention This is a fast and memory-efficient method that retains the exactness of traditional attention mechanisms, i.e., it uses global attention but efficiently. The whole idea revolves around optimizing the data movement within GPU memory. Let's understand!
-

SambaNova unveils disaggregated inference demo with 2x speedup
By
–
The first disaggregated inference demo for AI agents is now live. At #COMPUTEX2026, SambaNova demonstrated premium inference running in production at VC2 — using NVIDIA B200 GPUs for prefill and SambaNova RDUs for decode. The result: 2x faster inference than B200-only
-

Google’s Eloquent: Bringing AI to Edge Devices with Open Source
By
–
get it here → https://
ai.google.dev/edge/eloquent -

Full-load GPU limited to 220W with DFlash, DDTree optimizations
By
–
Looks like this under full-load btw Lots of juice to squeeze yet with DFlash / DDTree / Spec. Decoding / etc Also, power limiting the GPUs to 220w down from 440w as well (okay w/ leaving the perf. loss on the table given the heat / energy savings from that)
-

14 RTX 3090s running 42 parallel agents at full 256k context
By
–
14x RTX 3090s + Qwen 3.6 27B Running 42 agents IN PARALLEL at full 256k context – exl3 6bpw
– fp8 KV Cache
– Aphrodite Inference Engine w/ tp=2, pp=7 The world of agents will run locally btw -
Mustafa Suleyman predicts three OOM jumps in training compute by 2029
By
–
https://t.co/LizAzIh7dN pic.twitter.com/VVreg7R7OW
— Bojan Tunguz (@tunguz) 2 juin 2026At Microsoft Build today, Mustafa Suleyman predicted three more OOM jumps in the amount of training compute between now and summer 2029.