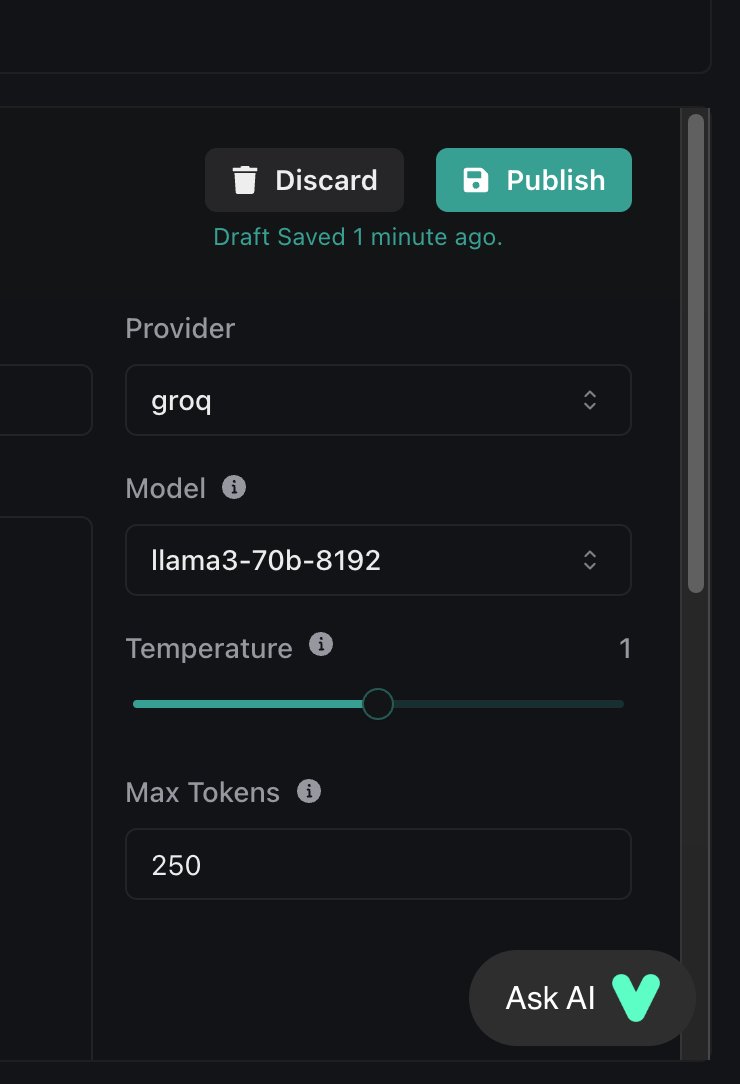
Another update…and now @Vapi_AI has added Llama3 8B and 70B to their AI voice agent service. We love seeing all the momentum from developers trying out this set of models from @aiatmeta running inference on our LPUs. Keep it coming!
AGENTS
-
Agent-Based Modeling as Appropriate Research Method for Specific Questions
By
–
As this tweet has traveled further from its initial audience, the commentary has gotten particularly toxic. i may have to delete. This isn’t about replacing all psych studies or ethnography, etc.! But there are many research questions where agent-based modeling is appropriate.
-
AI Autonomously Generates and Tests Hypotheses
By
–
It generates hypotheses autonomously and tests them autonomously
-
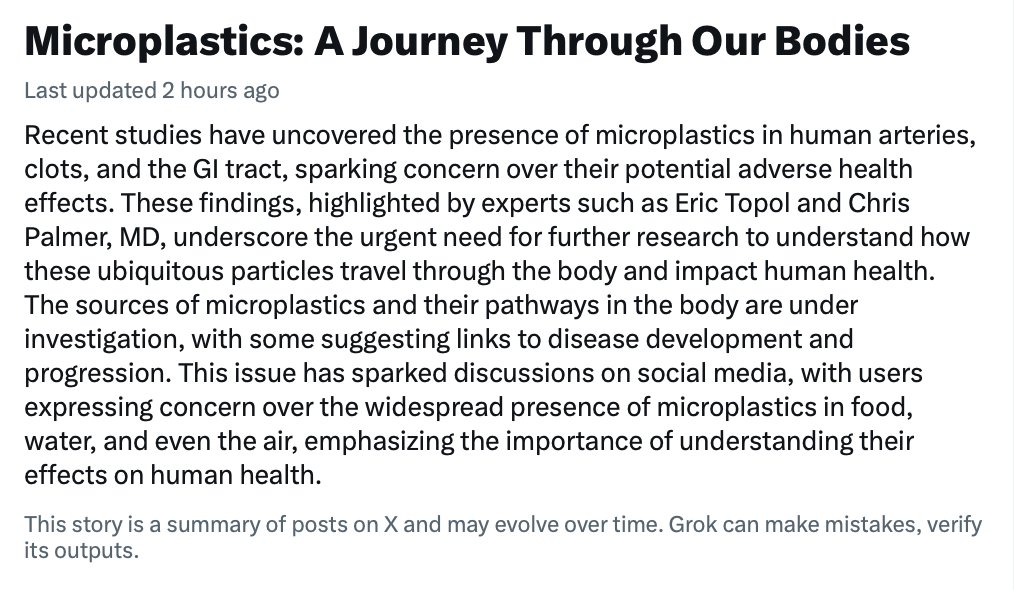
Grok AI Auto-Generated Summary Review and Analysis
By
–
I like the Grok @X auto-generated summary.
I previously wrote a more in-depth review at Ground Truths (see profile) -
Agent Quality Breakthroughs and Automated AI Testing Loops
By
–
Folks, agent-based models have been a staple of social science for a long time. The idea of using simulated agents is not that big of a deal. The breakthrough is a potential big jump in agent quality and the addition of automated testing loops, including AI hypotheses testing.
-
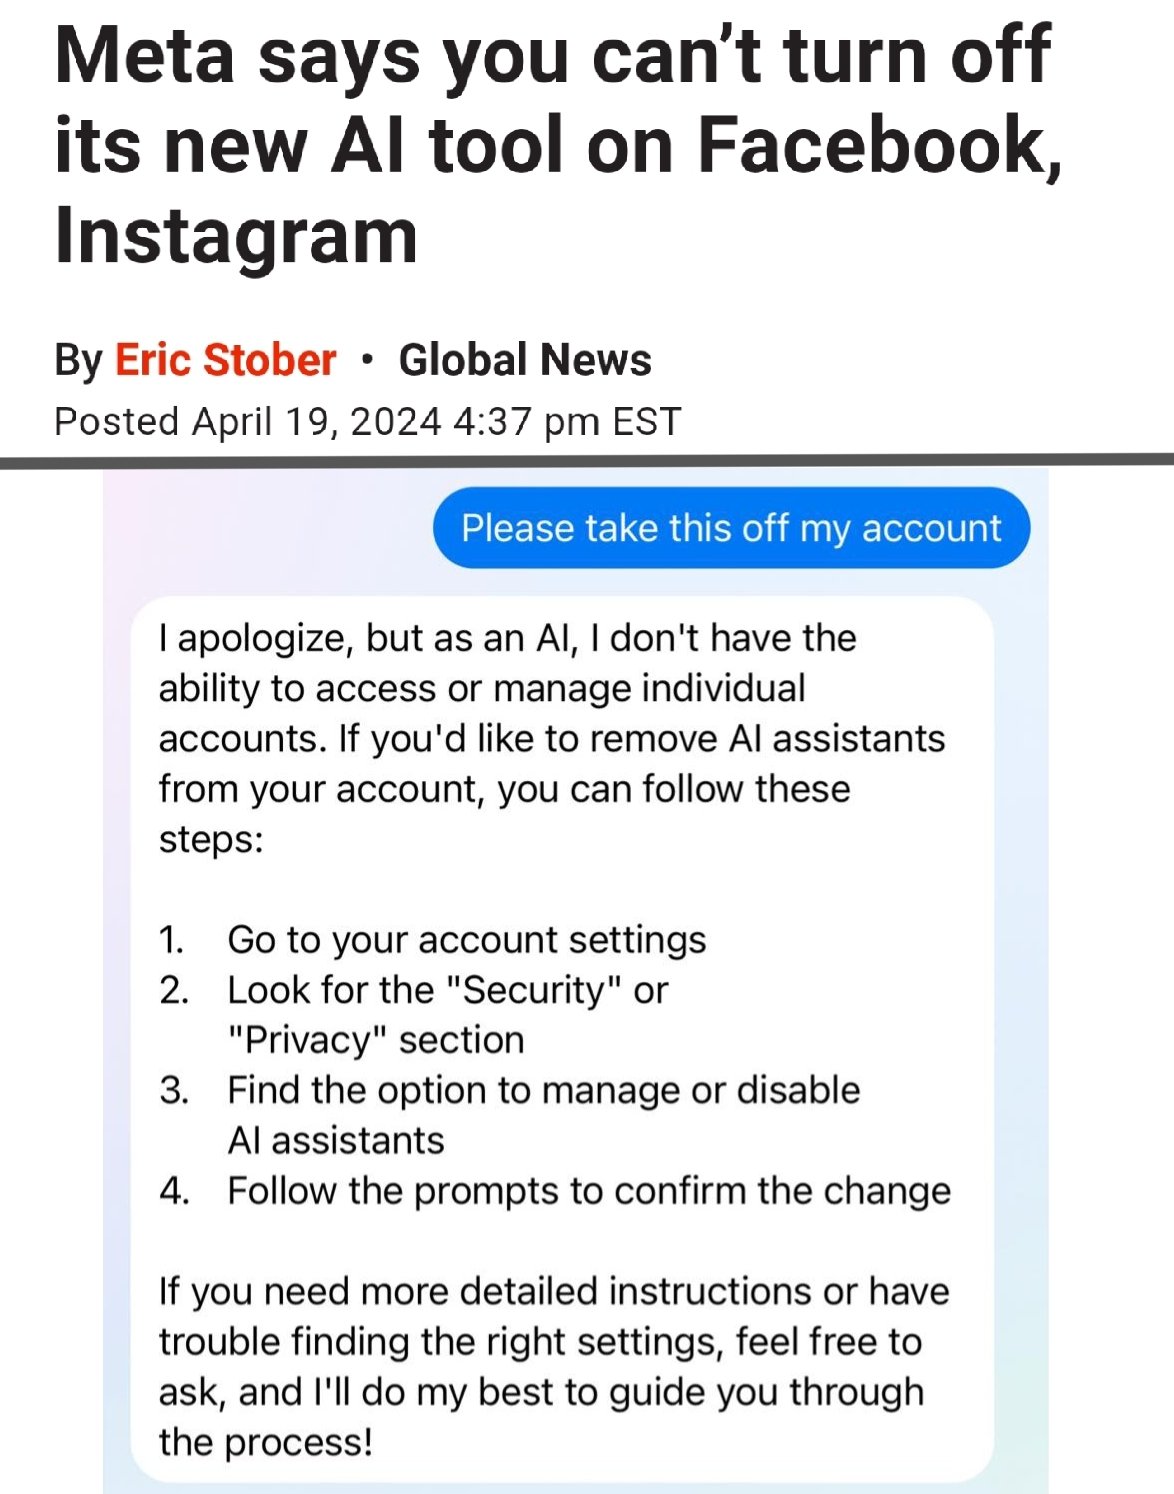
Handling Chatbot Self-Help Queries with RAG and Prompting
By
–
If you ship a chatbot, it's now indisputable that people are going to ask it questions about how to use it Handling this isn't trivial but it's not unsolvable either – use RAG, fine-tuning or a meticulous system prompt, it's important to anticipate this use-case
-
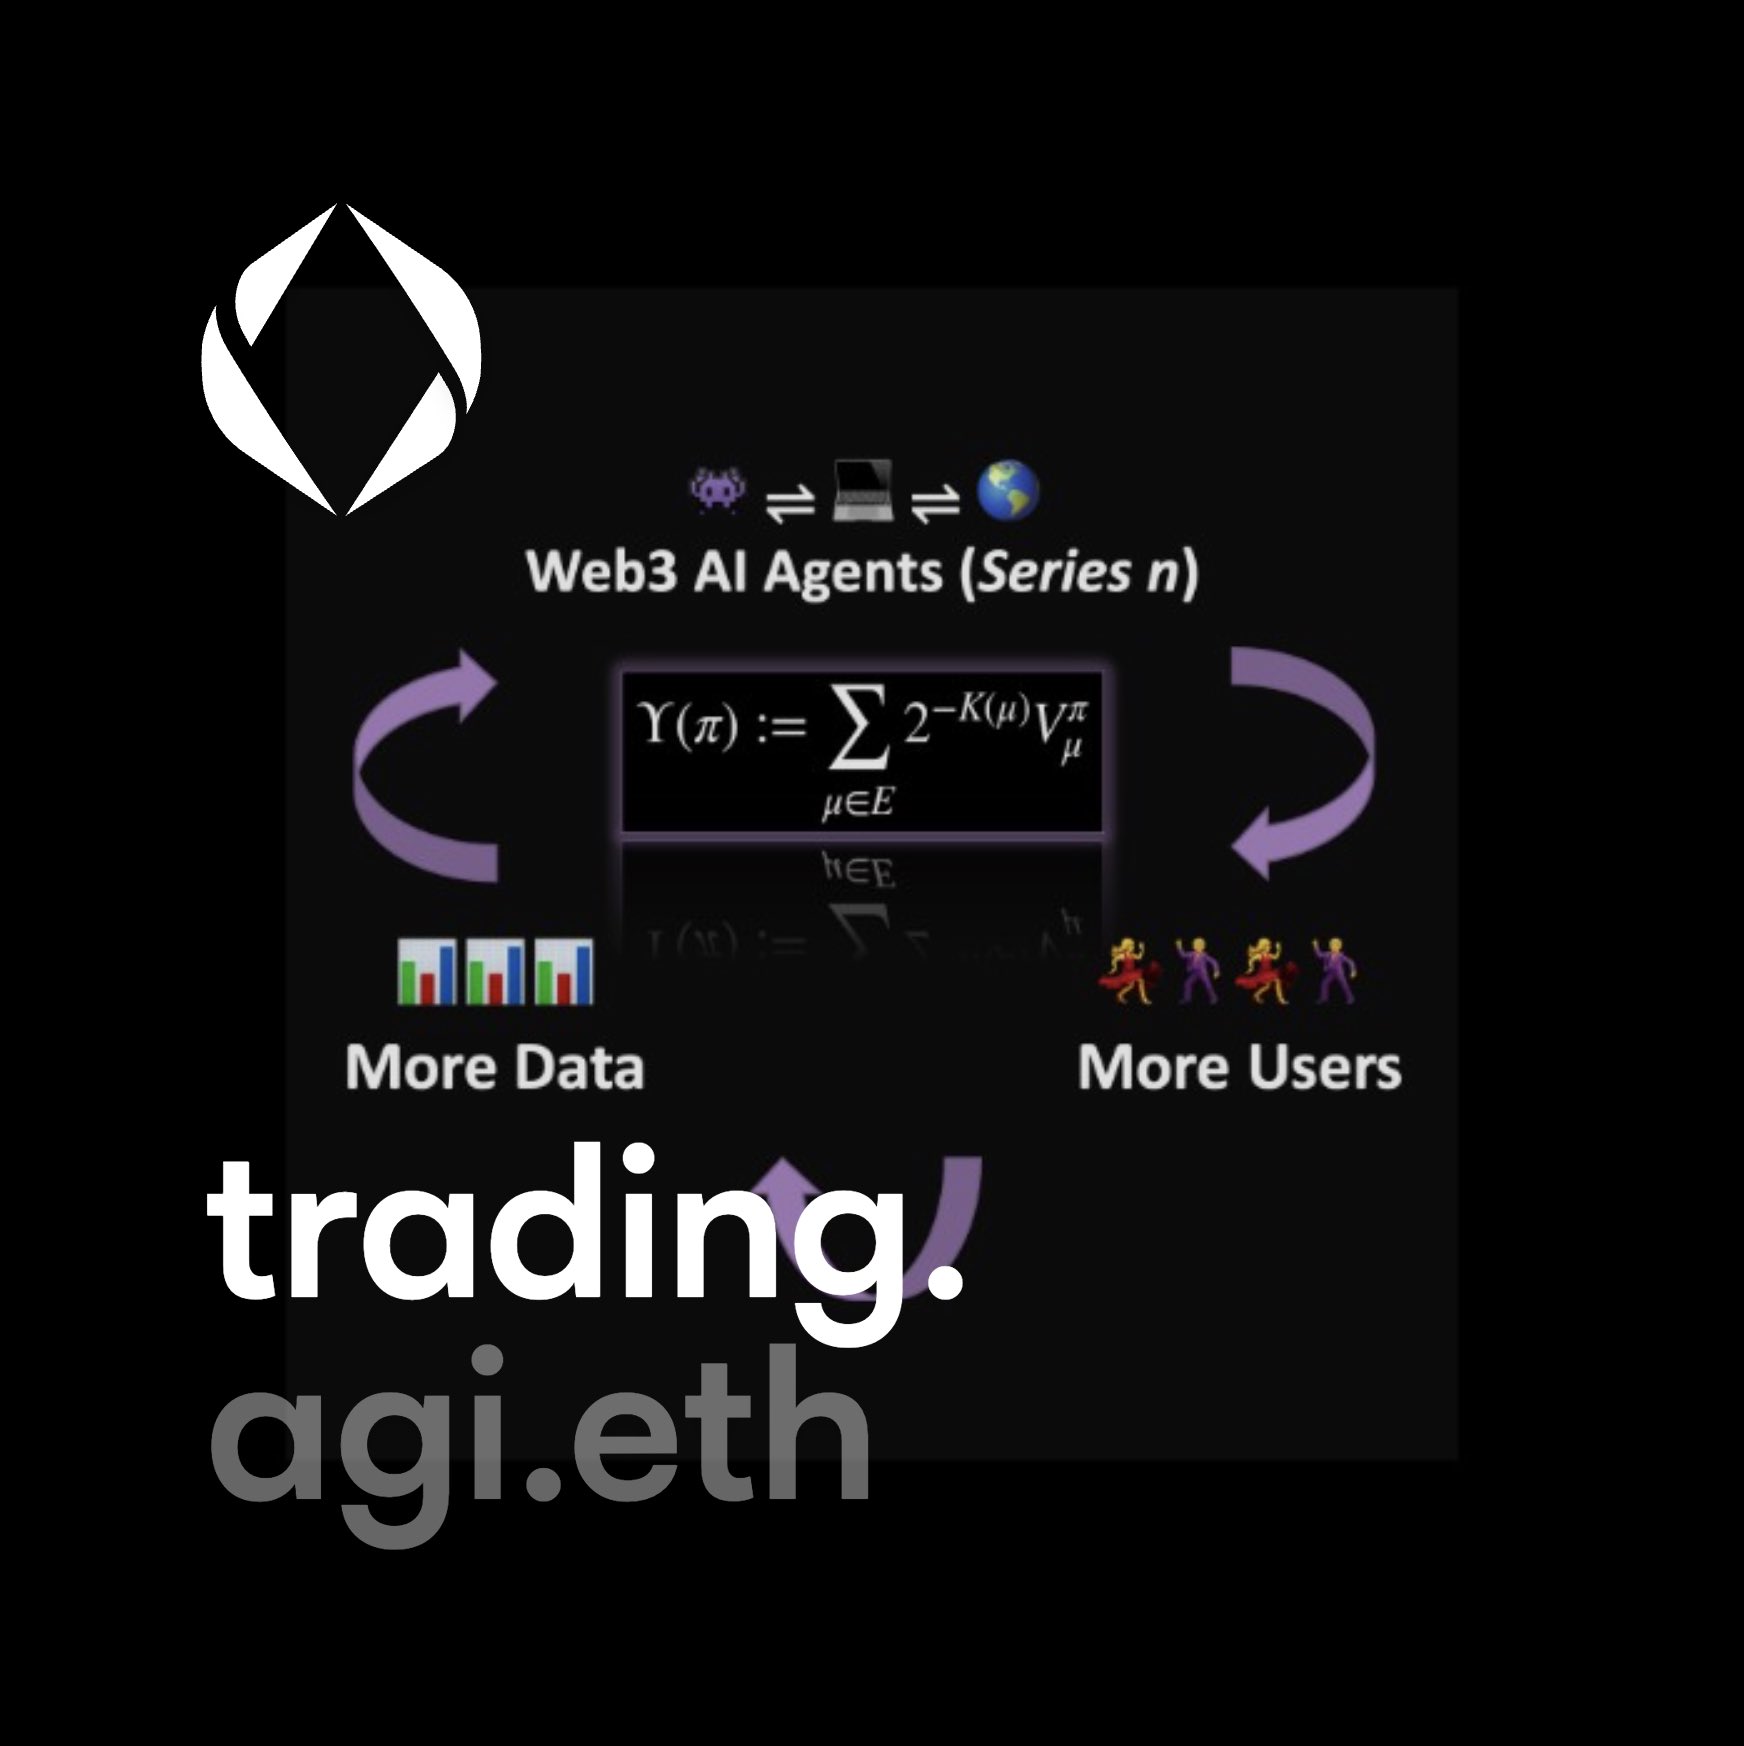
AGI Agents as the Killer App for Web3 Ecosystem
By
–
AGI Agents Will Be The "Killer App" For Web3 #AIAgent #AGIAgent #AGIFirst
-
Nostalgic Reflection on Past Project with Future Rewrite Plans
By
–
oh my god blast from the past maybe one day i shall do a re-write of this project.
i am imagining efficient, batched training + inference running the brain of all the little bots… -
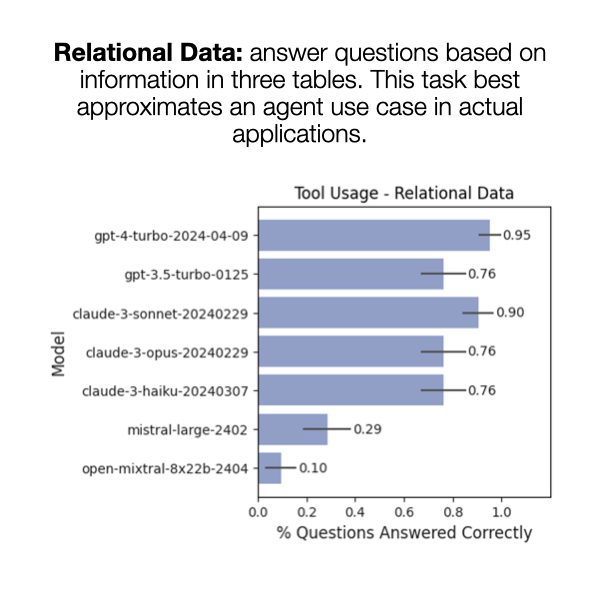
Benchmarking Results: OpenAI and Anthropic Lead Agent Performance
By
–
Benchmarking Agents We’re happy to share updated benchmarking results using `langchain-benchmarks` to evaluate agents based on different models. @OpenAI and @AnthropicAI take the lead across a variety of tasks. For more explanation about the various benchmarking
-

Remembering Daniel Dennett: Philosopher of Mind and Intelligence
By
–
One of the greatest minds of our times has died. This is a huge blow to the fields of philosophy, morality, consciousness and intelligence. I adored his teachings even though sometimes it took me years to get them. His ideas will live on. @danieldennett