
9/ How Code Empowers LLMs – an overview of the benefits of training LLMs with code-specific data. Some capabilities include enhanced code generation, enabling reasoning, function calling, automated self-improvements, and serving intelligent agents.
@dair_ai
-
Instruct-Imagen: Multimodal Context Grounding for Heterogeneous Image Generation
By
–
10/ Instruct-Imagen – tackles heterogeneous image generation by first enhancing the model’s ability to ground its generation on an external multimodal context and fine-tunes on image generation tasks with multimodal instructions.https://t.co/3jQa0piXlG
— DAIR.AI (@dair_ai) 7 janvier 202410/ Instruct-Imagen – tackles heterogeneous image generation by first enhancing the model’s ability to ground its generation on an external multimodal context and fine-tunes on image generation tasks with multimodal instructions.
-
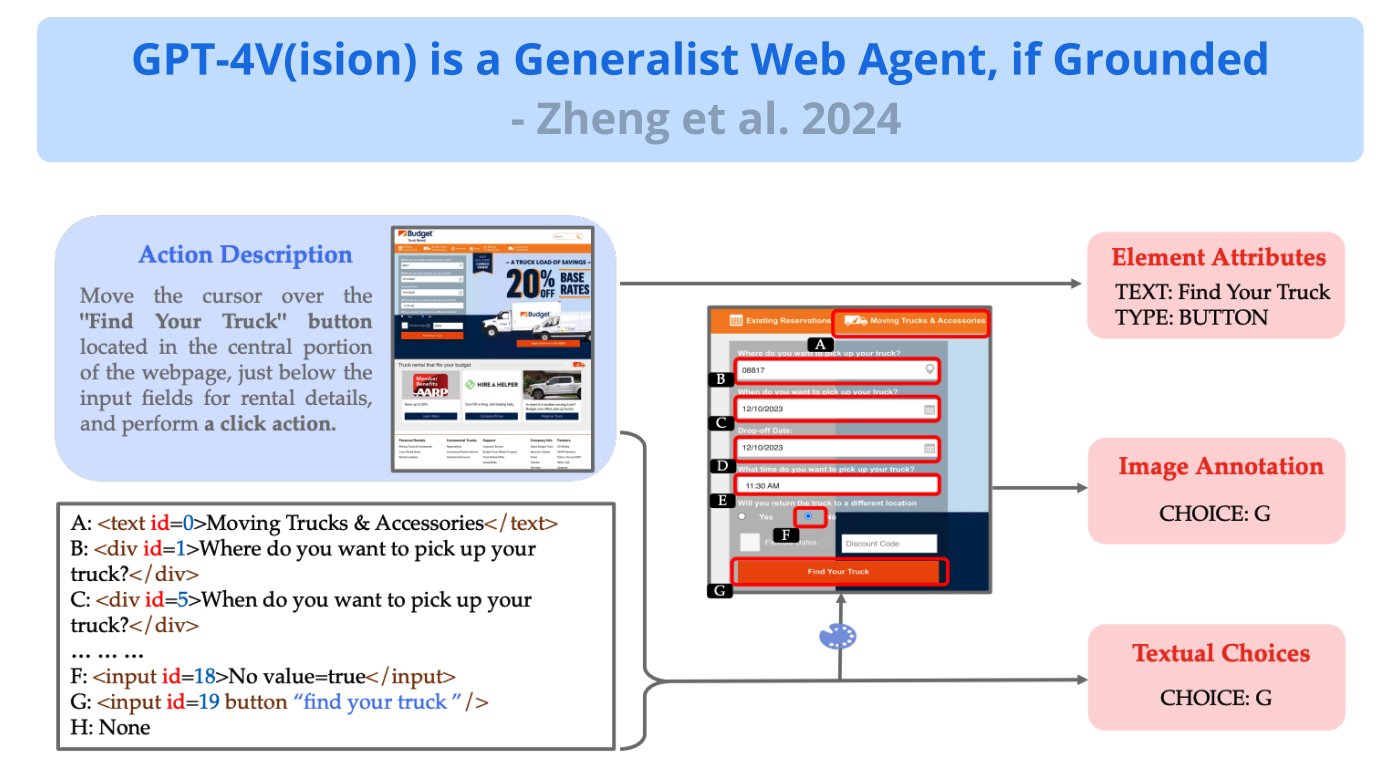
GPT-4V as Generalist Web Agent: 50% Task Completion
By
–
7/ GPT-4V is a Generalist Web Agent – explores the potential of GPT-4V as a generalist web agent; findings suggest that GPT-4V can complete 50% of tasks on live websites – possible through manual grounding of its textual plans into actions.
-
DocLLM: Visual Document Reasoning with Bounding Box Spatial Layout
By
–
8/ DocLLM – an extension to traditional LLMs for reasoning over visual documents; focuses on using bounding box information to incorporate spatial layout structure; demonstrates SoTA on 14 of 16 datasets across several document intelligence tasks.
-
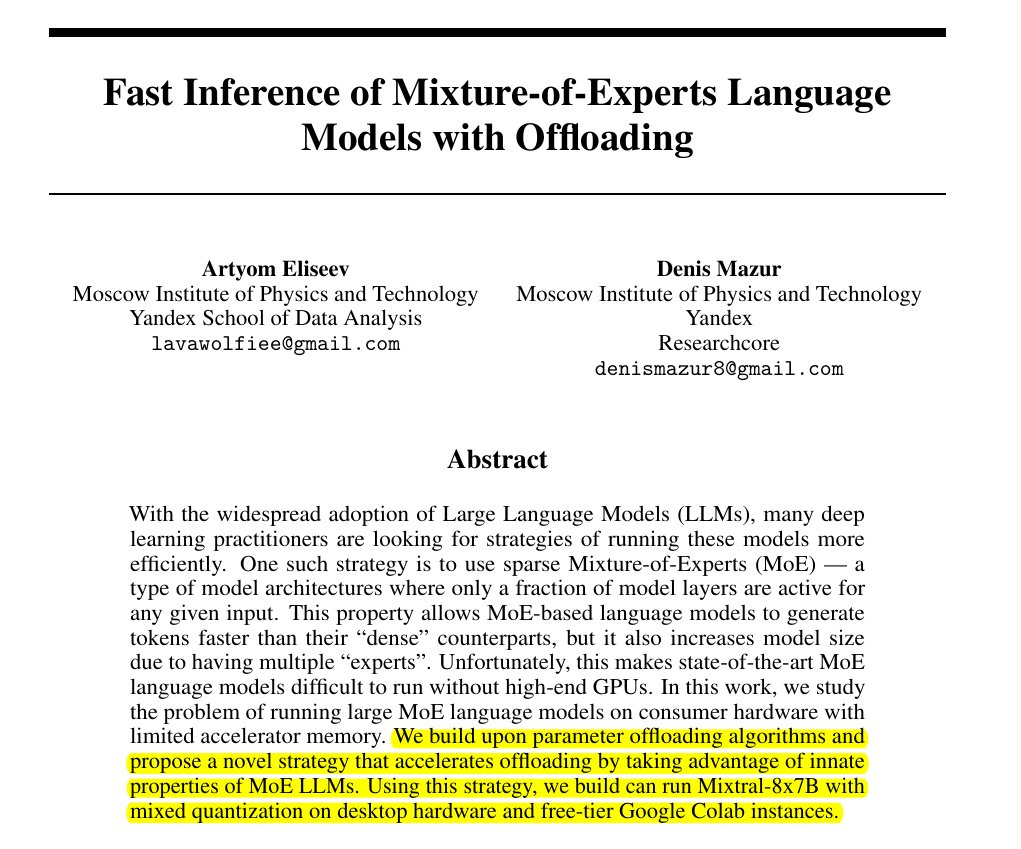
Fast Inference of Mixture-of-Experts Models via Offloading
By
–
6/ Fast Inference of Mixture-of-Experts – achieves efficient inference of Mixtral-8x7B models through offloading; designs a MoE-specific offloading strategy that enables running Mixtral-8x7B on desktop hardware and free-tier Google Colab instances.
-

LLM Augmented LLMs: Composing Models for Expanded Capabilities
By
–
5/ LLM Augmented LLMs – explore composing existing foundation models with specific models to expand capabilities; introduce cross-attention between models to compose representations that enable new capabilities.
-

LLaMA Pro: Post-Pretraining Method Without Catastrophic Forgetting
By
–
4/ LLaMA Pro – proposes a post-pretraining method to improve an LLM’s knowledge without catastrophic forgetting; it achieves this by tuning expanded identity blocks using only new corpus while freezing the inherited blocks.
-

32 Techniques to Mitigate Hallucination in Large Language Models
By
–
2/ Mitigating Hallucination in LLMs – summarizes 32 techniques to mitigate hallucination in LLMs; introduces a taxonomy categorizing methods like RAG, Knowledge Retrieval, CoVe, and more.
-
Mobile ALOHA: Bimanual Mobile Manipulation via Low-Cost Teleoperation
By
–
1/ Mobile ALOHA – proposes a system that learns bimanual mobile manipulation with low-cost whole-body teleoperation; it first collects high-quality demonstrations and then performs supervised behavior cloning.https://t.co/Vf4REkMBuW
— DAIR.AI (@dair_ai) 7 janvier 20241/ Mobile ALOHA – proposes a system that learns bimanual mobile manipulation with low-cost whole-body teleoperation; it first collects high-quality demonstrations and then performs supervised behavior cloning.
-
Top ML Papers of the Week: DocLLM, ALOHA, Fine-tuning
By
–
The Top ML Papers of the Week (Jan 1 – Jan 7): – DocLLM
– Mobile ALOHA
– Self-Play Fine-tuning
– Fast Inference of MoE
– LLM Augmented LLMs
– Mitigating Hallucination in LLMs
…