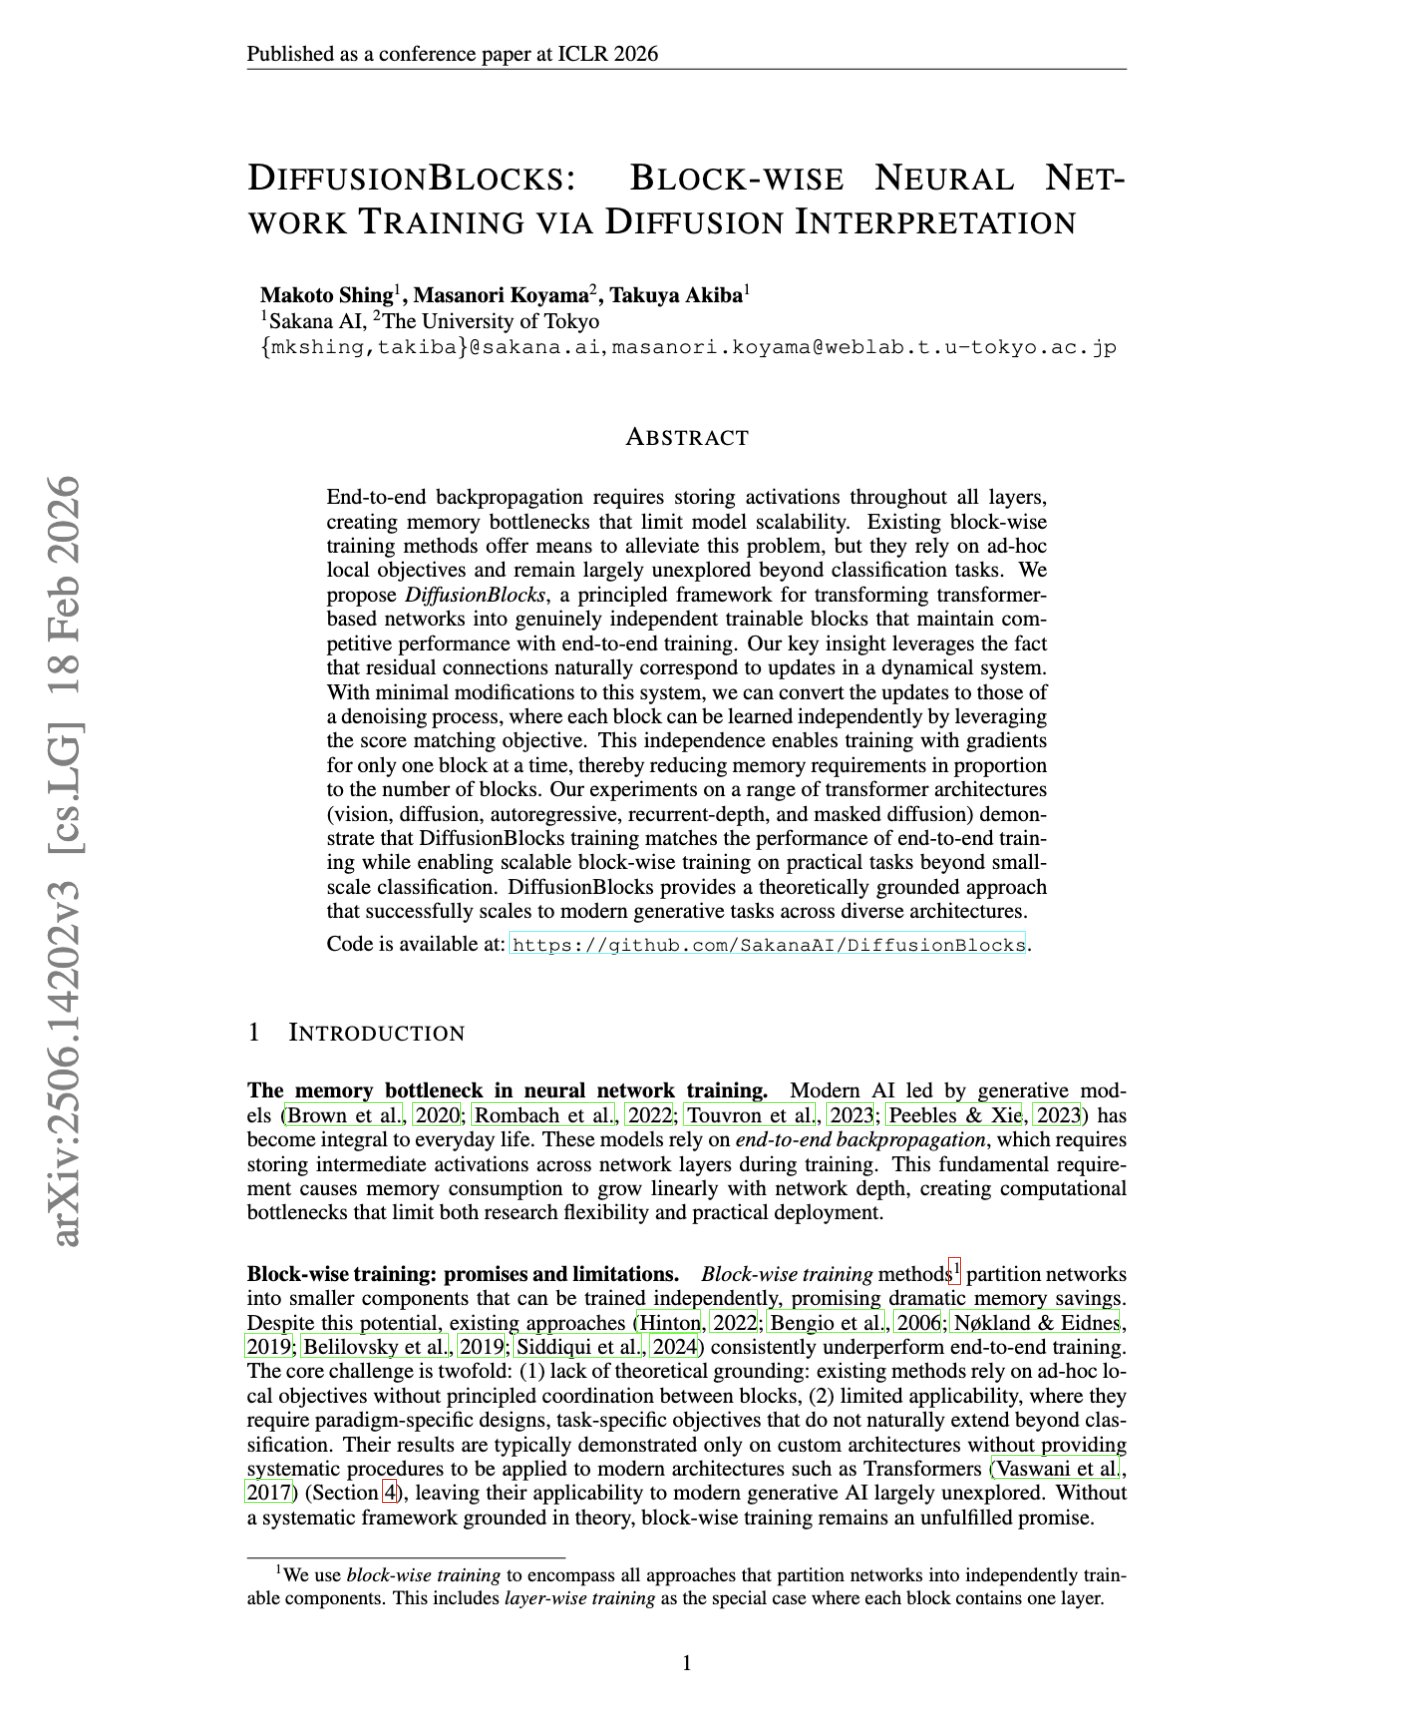
"DiffusionBlocks: Block-wise Neural Network Training via Diffusion Interpretation" End to end backprop stores activations through every layer, which is why deep Transformers is expensive to train. This paper reinterprets residual blocks as diffusion denoising steps, so each
@askalphaxiv
-
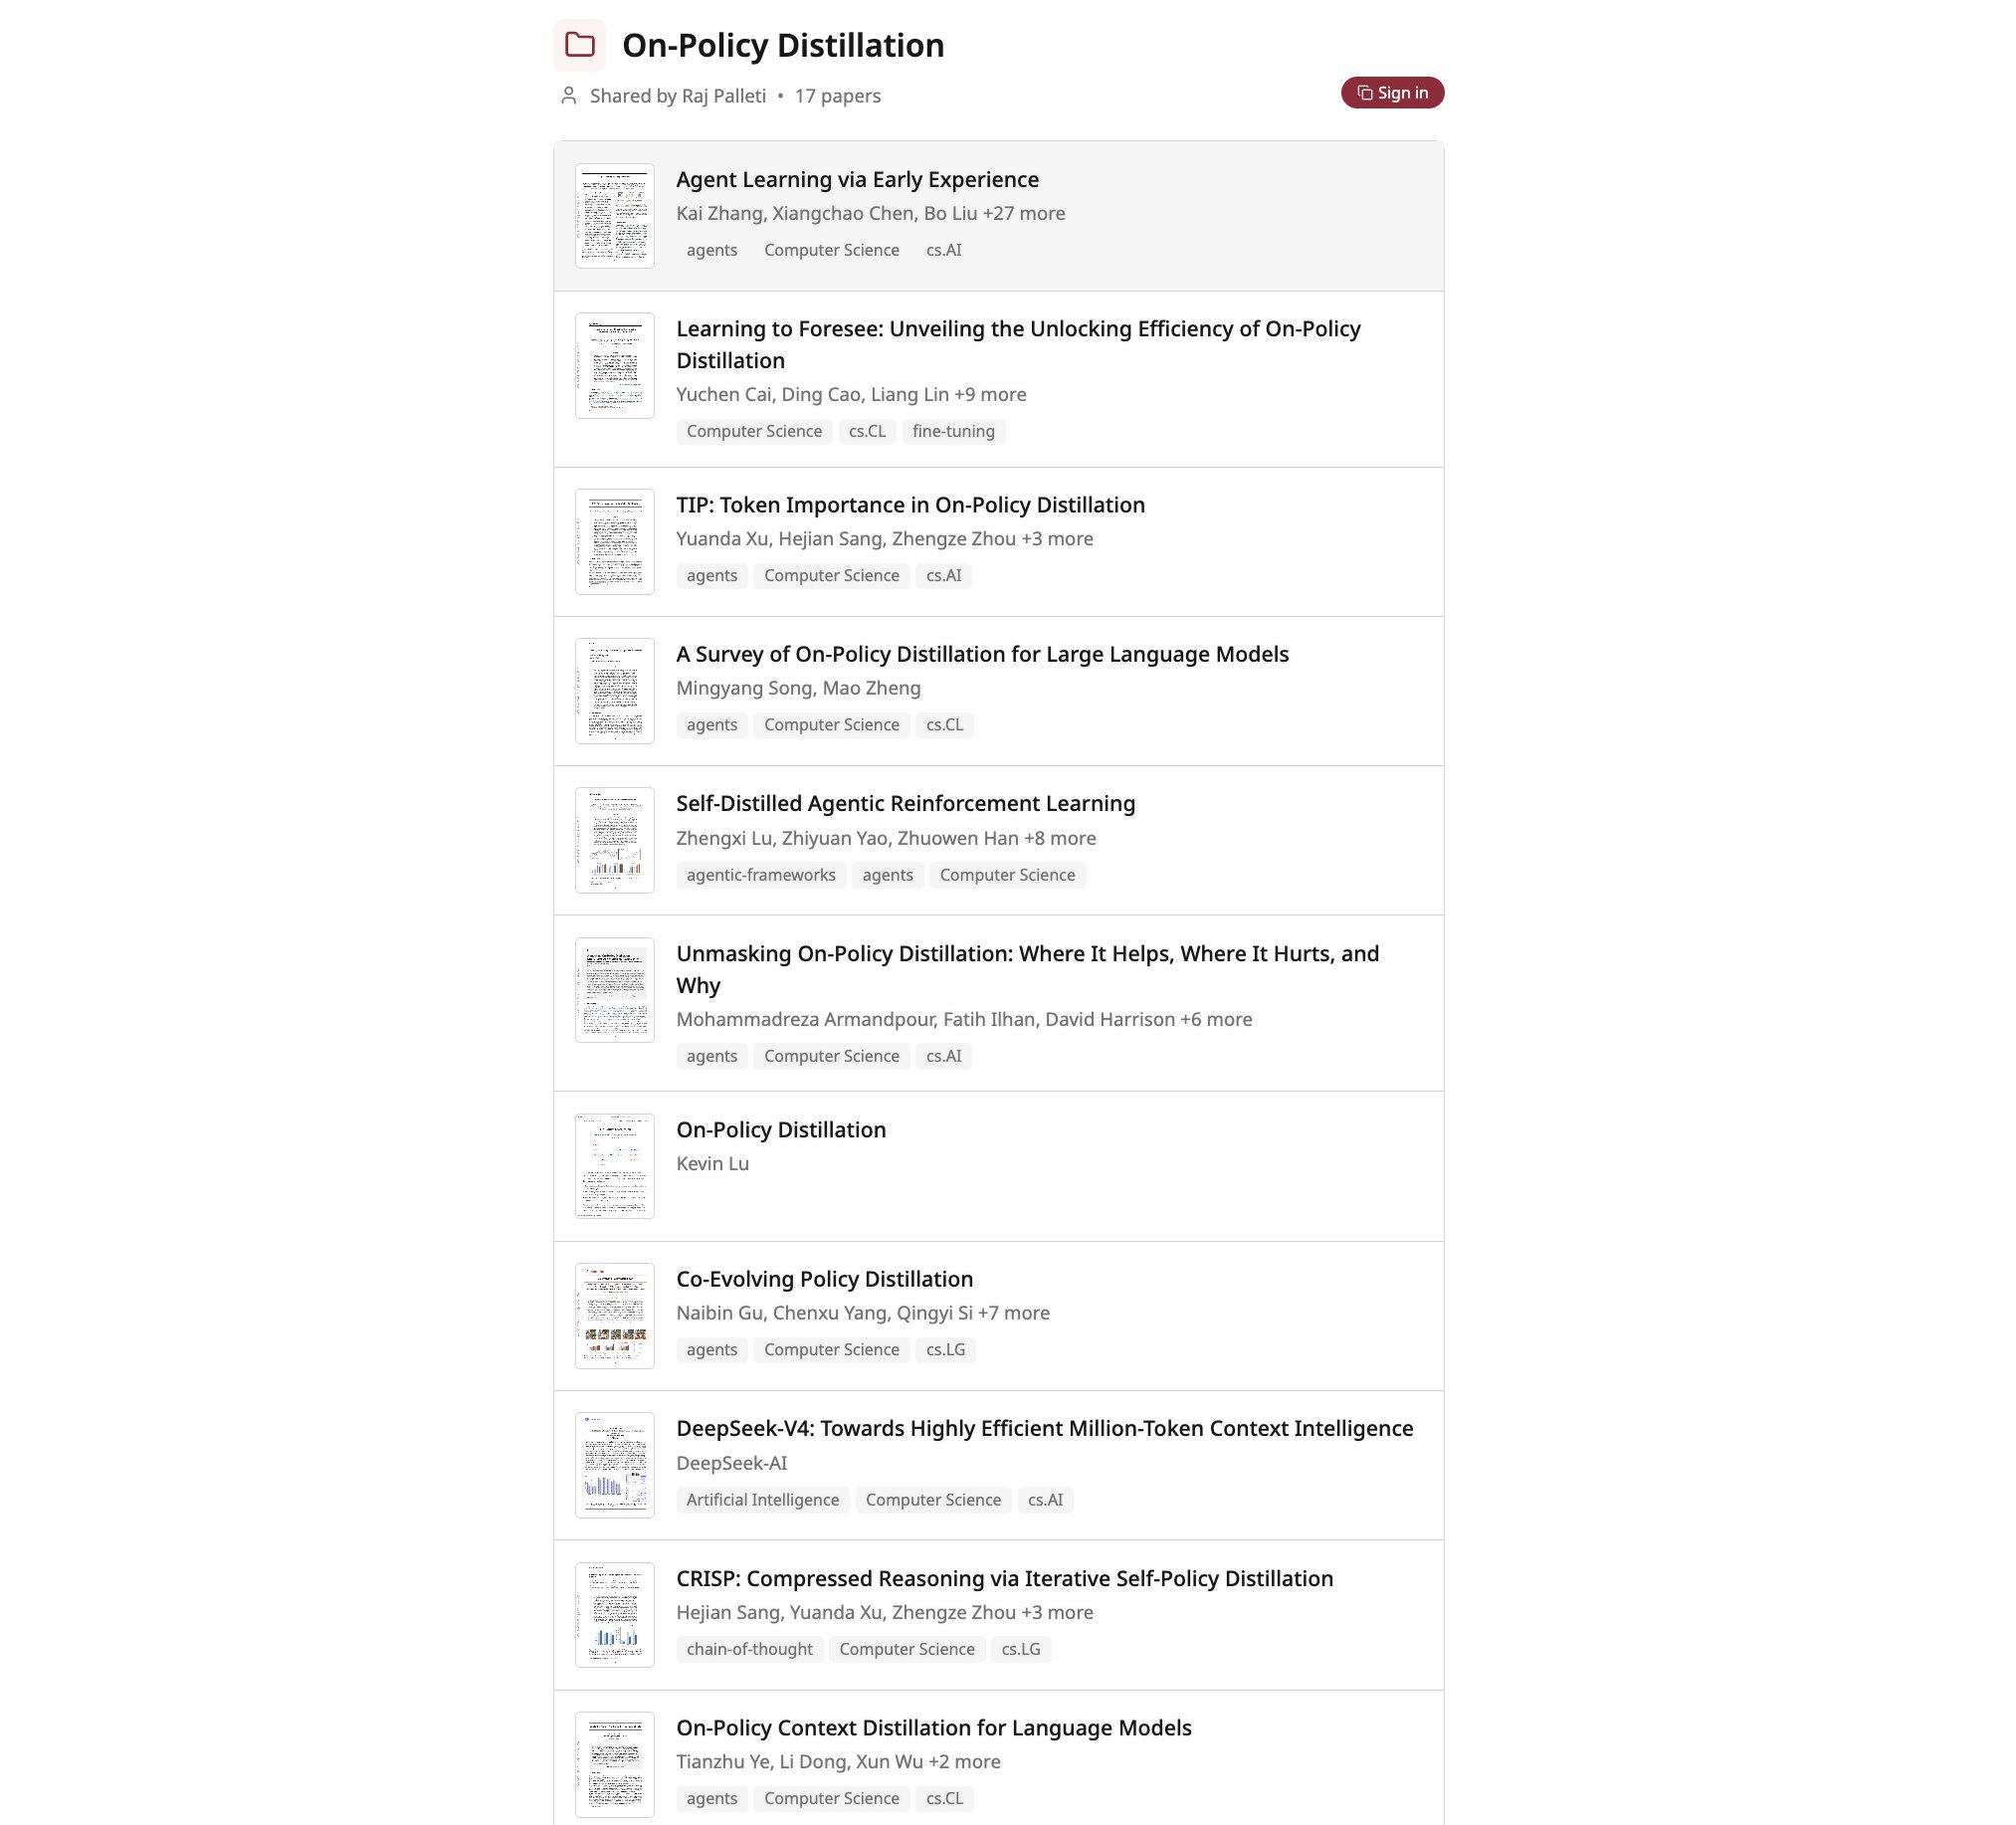
On-Policy Distillation: Emerging AI Post-Training Method
By
–
A new class of post-training method is emerging in 2026: On-Policy Distillation (OPD). It’s already showing up across frontier open-weight model releases, and it’s quickly becoming a technique worth understanding. To help you get up to speed, we’ve compiled a list of the most
-
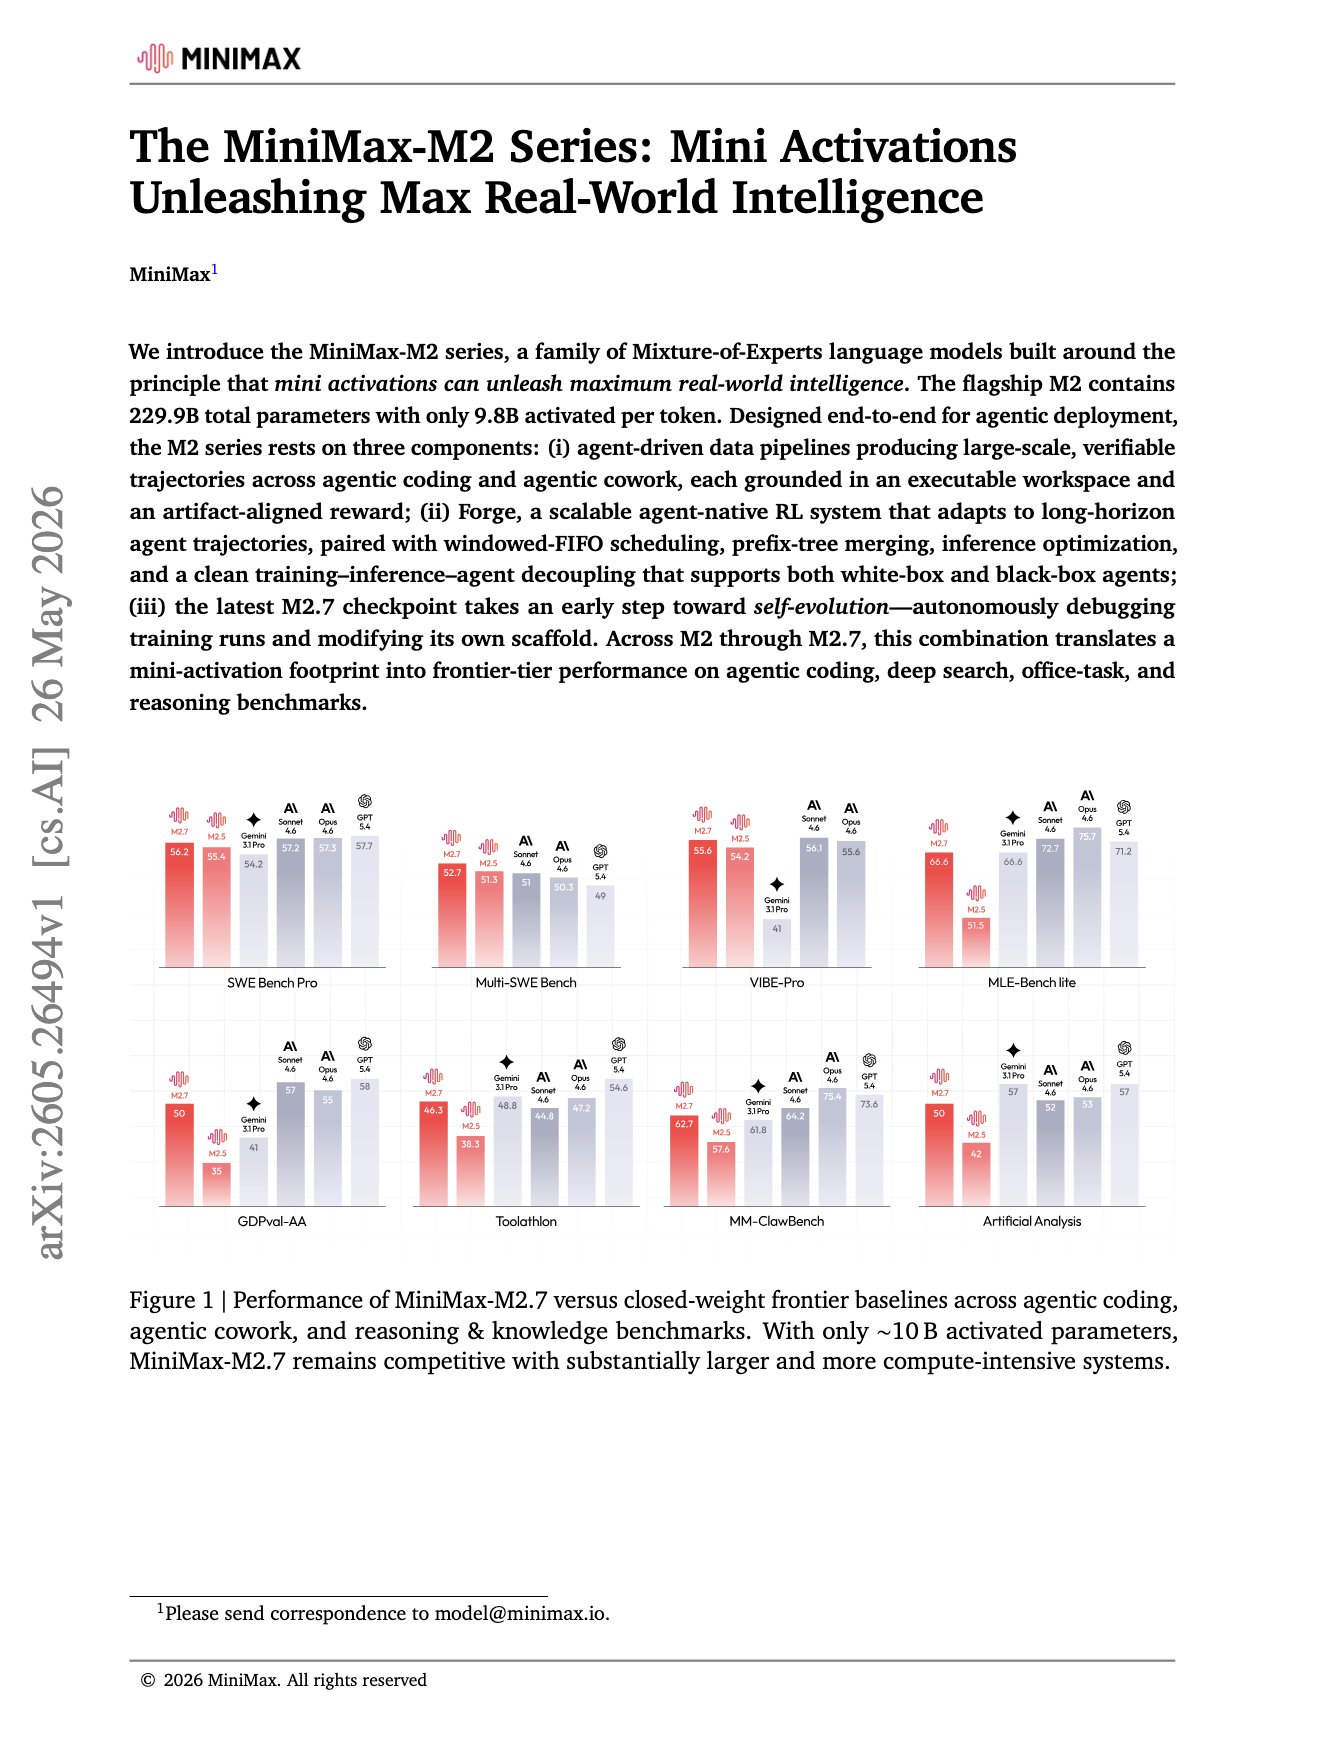
MiniMax-M2 Agent-Native RL Training Paper Released
By
–
MiniMax-M2 paper just dropped The key focus of M2 is on something more agent-native. It trains on runnable workspaces and artifact-grounded rewards, then uses Forge to scale RL over long coding, app, search, and office-task trajectories. What's interesting is that M2.7
-
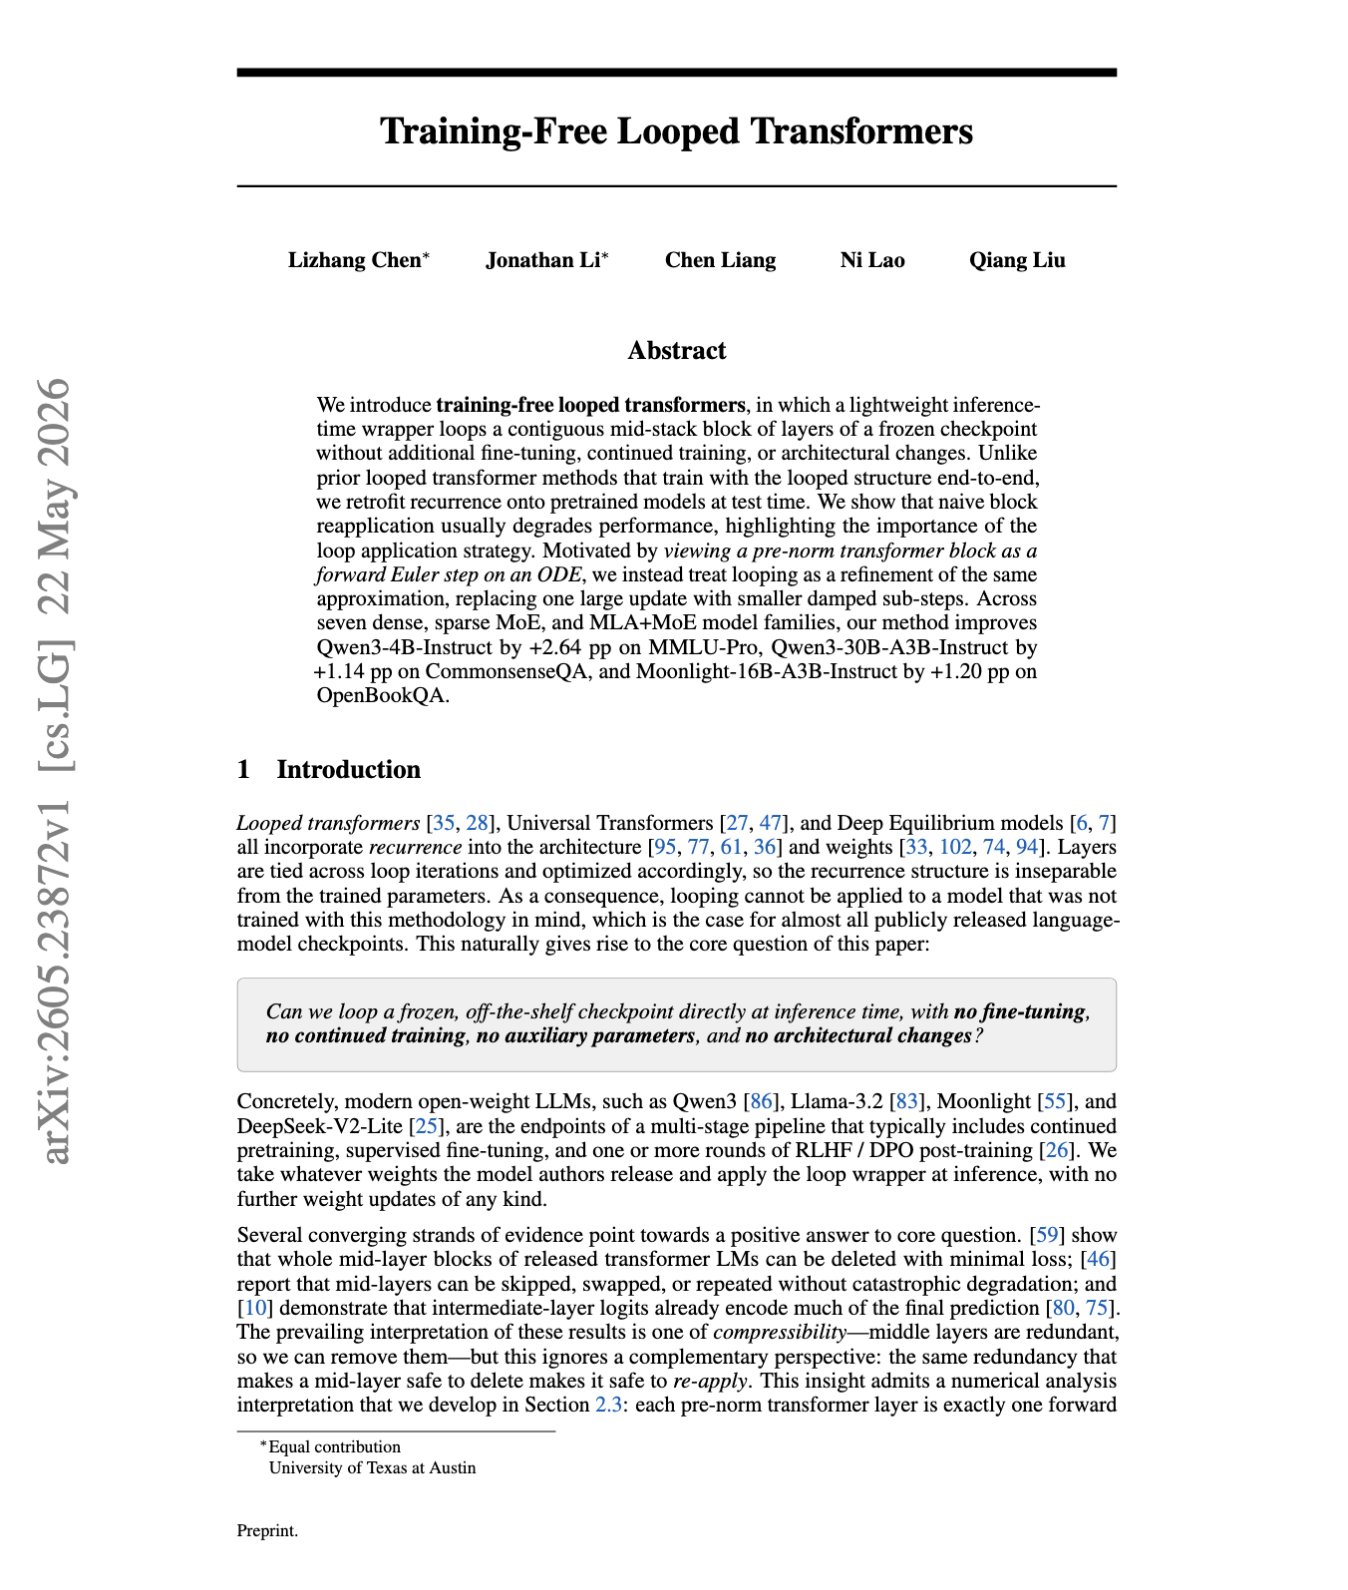
Looped Transformers: Frozen Checkpoint Inference Optimization
By
–
Another cool research on Looped Transformers They ask the question: "Can we loop a frozen, off-the-shelf checkpoint directly at inference time without any modifications?" So naive repetition pushes hidden states outside the distribution later layers expect, so performance
-
Language Models Sleep: Context Replay for Deep Reasoning
By
–
"Language Models Need Sleep" Instead of thinking longer at answer time, this paper makes LLMs sleep before forgetting. They replay old context, write it into fast weights, clear the KV cache, and answer later at normal speed. More sleep improves deep reasoning over long and
-
One-click VPO template for Qwen from openresearch.sh
By
–
Check out the one-click template of VPO here! https://
openresearch.sh/templates/qwen
-vpo
… -
OpenResearch sneak peek: train VPO on ToolRL in one click
By
–
Here’s an early sneak peak of OpenResearch, our brand new feature for reproducing and experimenting on top of papers
— alphaXiv (@askalphaxiv) 26 mai 2026
We put together a template so you can train VPO on ToolRL in one click on a single gpu
Vector Policy Optimization trains models to generate diverse answer sets… pic.twitter.com/MEaGQ1HIYMHere’s an early sneak peak of OpenResearch, our brand new feature for reproducing and experimenting on top of papers We put together a template so you can train VPO on ToolRL in one click on a single gpu Vector Policy Optimization trains models to generate diverse answer sets
-
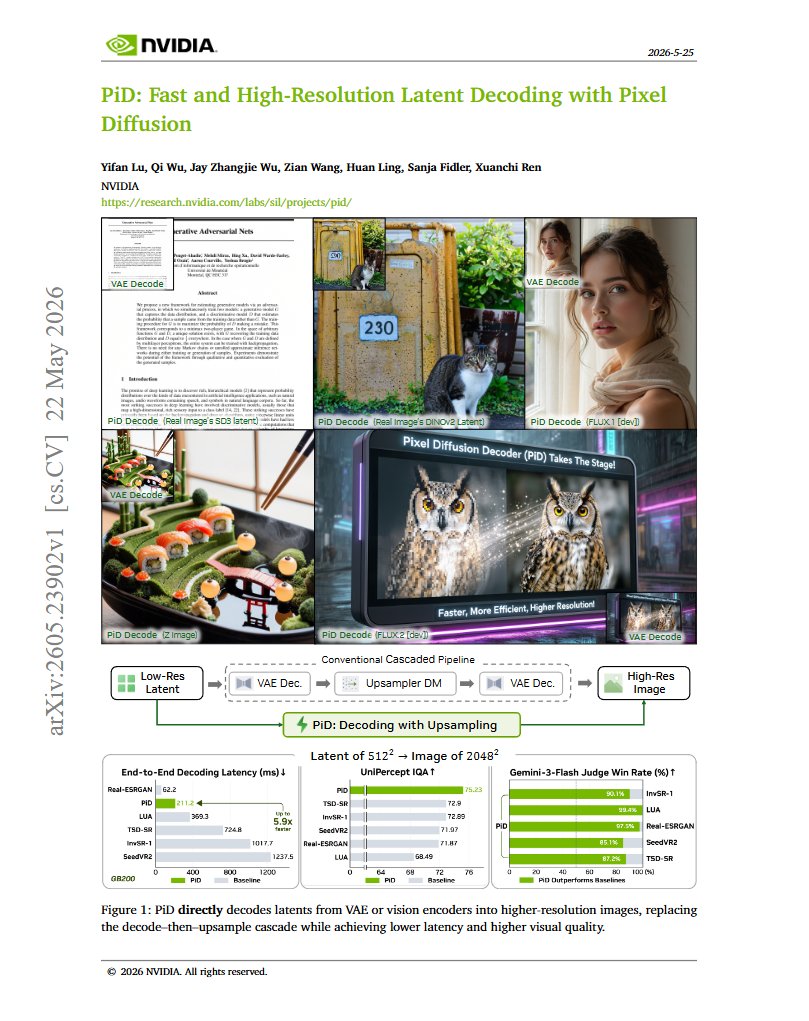
Fast and High-Resolution Latent Decoding with Pixel Diffusion
By
–
Image models usually VAE decode first, then super-res later, which is slow and mostly reconstructs rather than creates detail. This NVIDIA research makes the decoder itself a pixel diffusion model, so a 512^2
-
DeepMind LLMs Lean Proof-Search Agents Solve Open Problems
By
–
This new DeepMind research turns LLMs into Lean proof-search agents, so every step must compile and the final proof is mechanically verified. Under this setup, they solved 9 open Erdős problems, proved 44 OEIS conjectures, and helped advance actual research in optimization,
-
ConvexTok: Linear Programming for Optimal LLM Tokenization
By
–
"Tokenisation via Convex Relaxations" Most LLM tokenizers still use BPE, a greedy merge algorithm that can waste vocab slots on locally good but globally suboptimal tokens. This paper turns tokenizer training into a linear program, then rounds the solution into ConvexTok. This