"VLM^3: VLMs Are Native 3D Learners" This paper shows that VLMs can learn 3D natively. Most 3D vision systems rely on expert architectures, regression heads, heavy augmentations, and task-specific losses. But they show that you can skip the majority of these designs. All they
@askalphaxiv
-
AlphaXiv.org now offers GPT 5.5 and Claude models
By
–
Now available in addition to GPT 5.5 and Claude. Check out http://
alphaXiv.org! -
Gemini 3.5 Flash: Understand Research Papers Faster with Highlighted Q&A and Cross-Paper Context
By
–
Introducing Gemini 3.5 Flash for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 2 juin 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/6bmBR63SegIntroducing Gemini 3.5 Flash for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-
Representation Forcing for Bottleneck-Free Unified Multimodal Models
By
–
Most Unified Multimodal Models still generate images through a frozen VAE, which means perception and generation are not fully learned in one model. This paper fixes this by making the decoder first predict
-
Self-Improving Language Models with Bidirectional Evolutionary Search
By
–
Most LLM search still works by sampling more rollouts or extending one path at a time. This paper's bidirectional evolutionary search does it in a smarter way. It breaks the task backward into smaller
-
Latent prediction reduces sample complexity in hierarchical data learning
By
–
"Learn from your own latents, not tokens: A Sample Complexity Theory" This paper explains why data2vec and JEPA can learn with much less data. They showed that when data has hidden hierarchy, token prediction becomes harder as the hierarchy gets deeper. But latent prediction
-
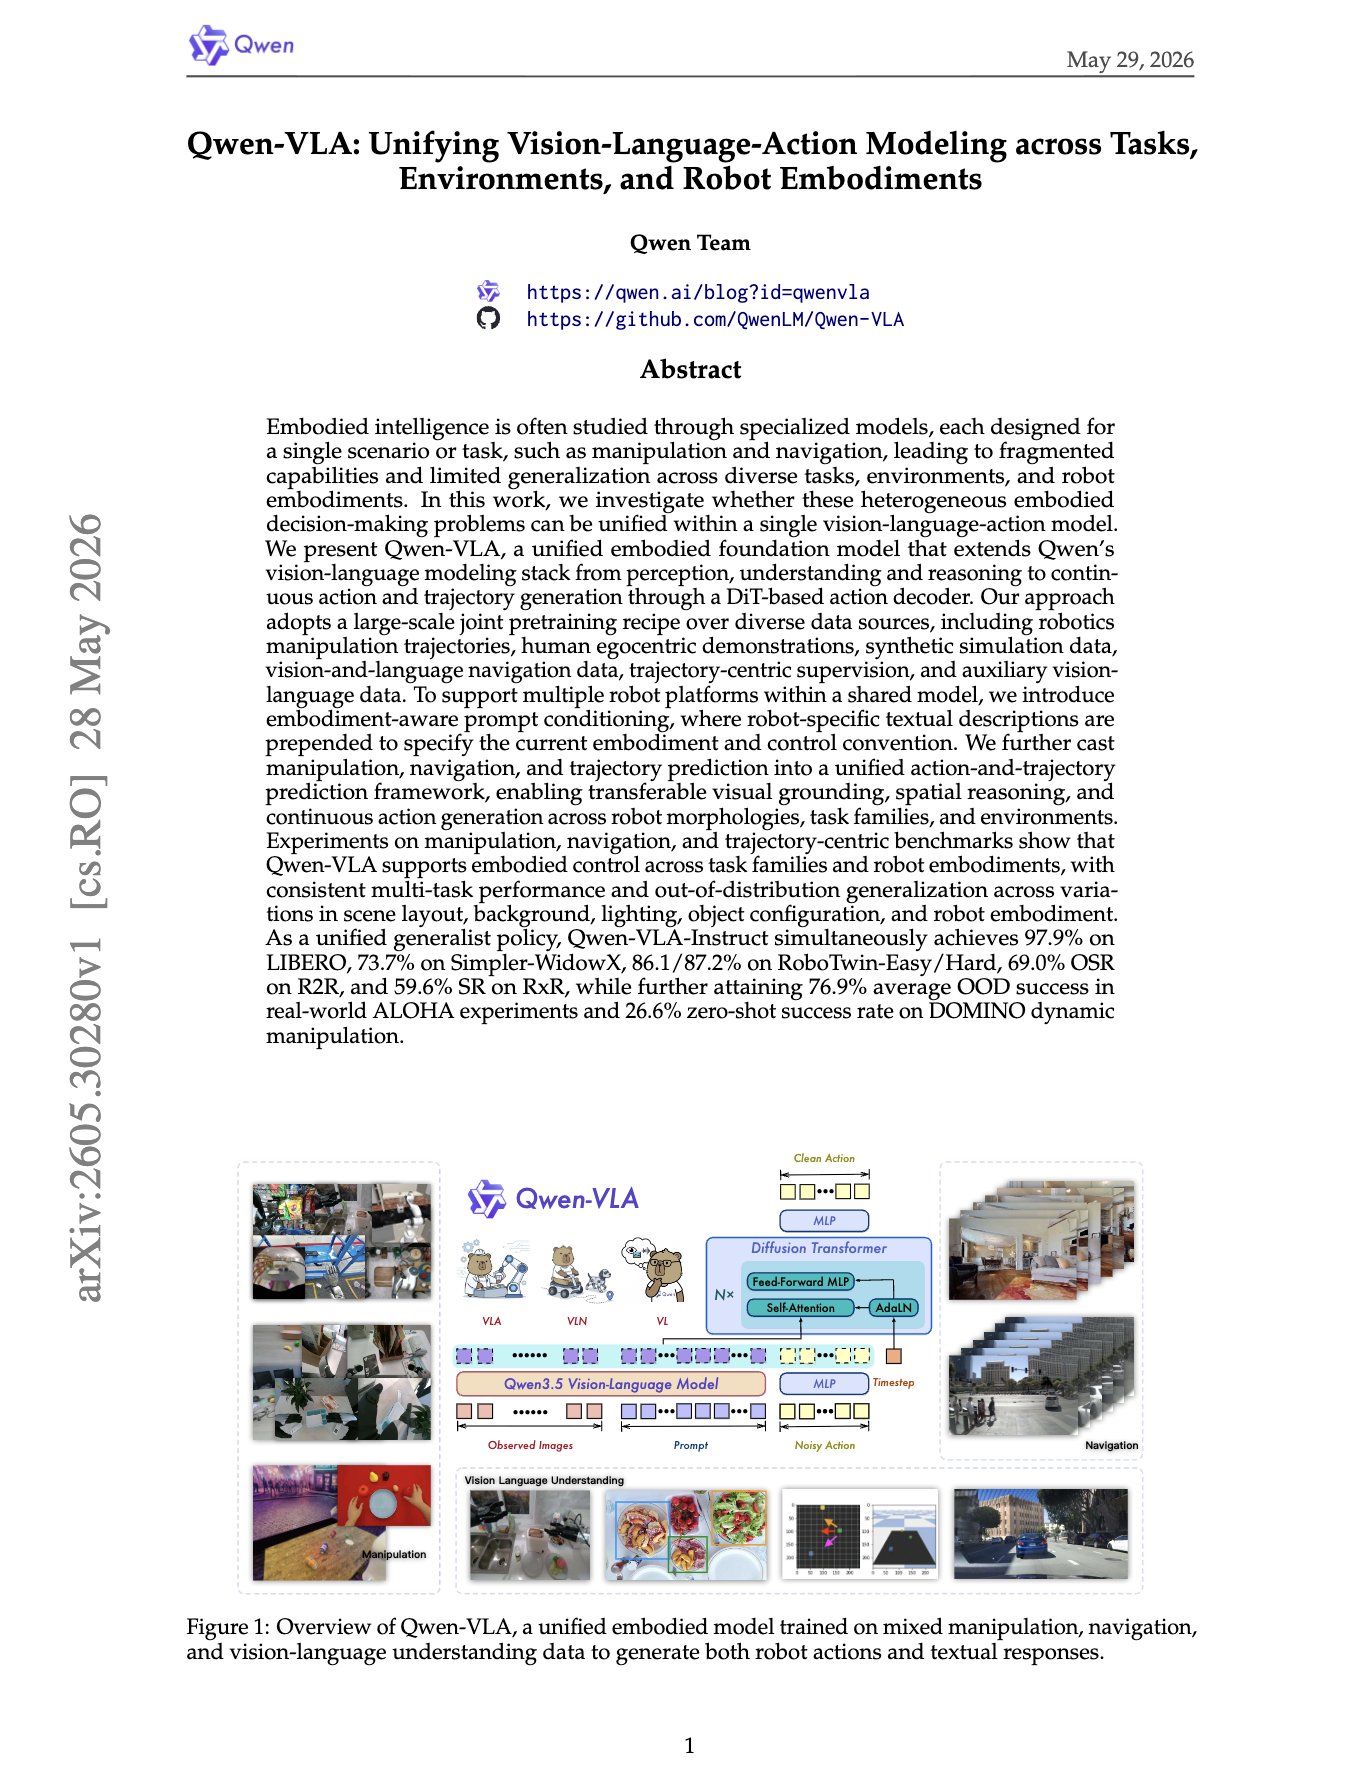
Qwen-VLA: Unified Vision-Language-Action Robot Learning
By
–
“Qwen-VLA: Unifying VLA Modeling across Tasks, Environments, and Robot Embodiments” They turned robot learning into one vision-language-action modeling problem instead of separate policies for each task, environment, and robot body. So by adding a DiT flow-matching action
-
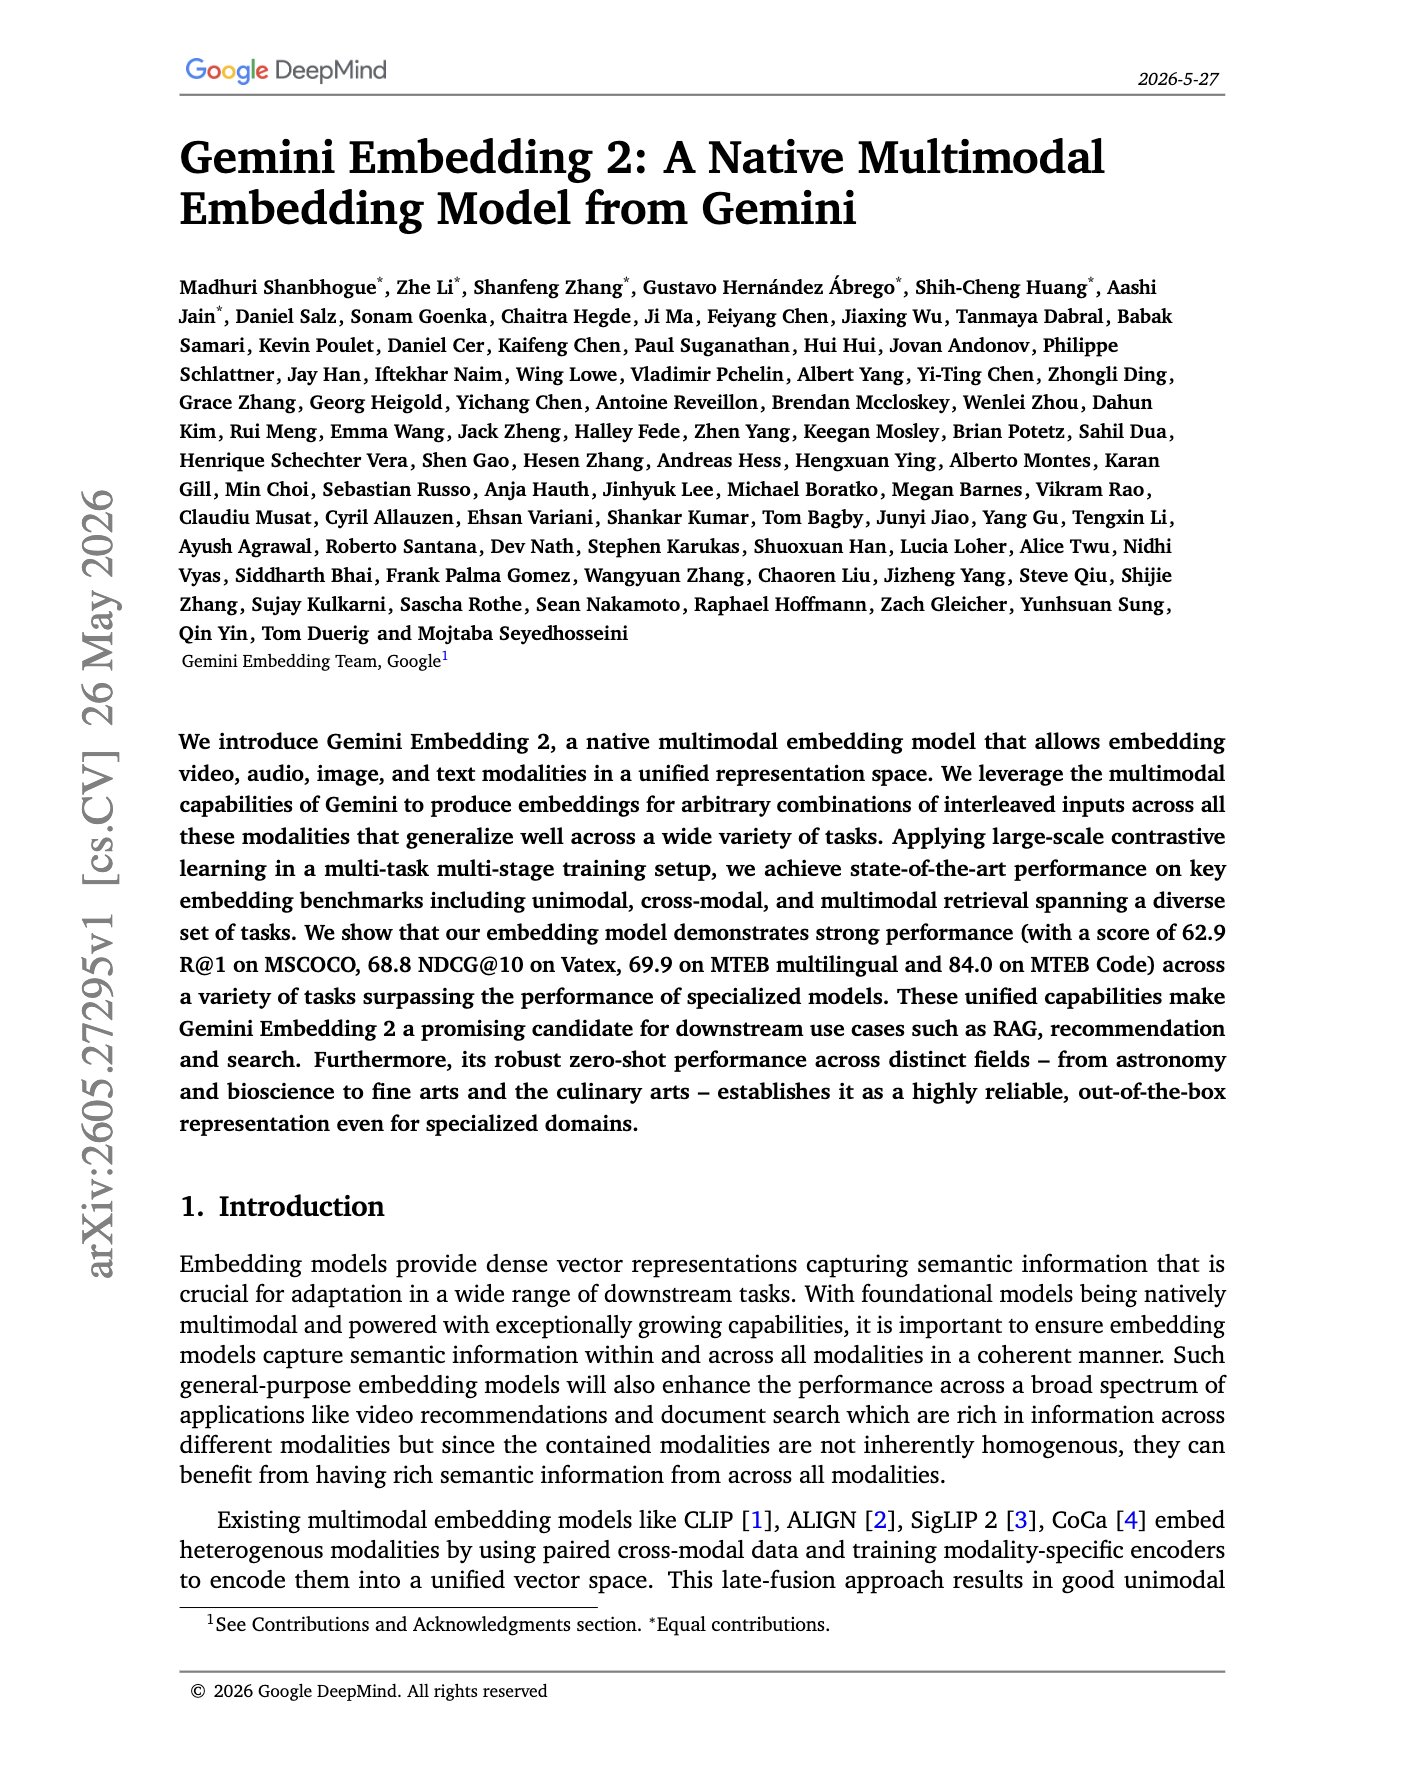
Gemini Embedding 2: Native Multimodal Embedding Model
By
–
"Gemini Embedding 2" This paper turns Gemini into one native embedding model for text, image, video, audio, and interleaved multimodal inputs. Instead of converting everything into text first, it embeds raw modalities directly into one shared space, improving audio search,
-

LeJEPA World Model Learning Under Gaussian Latent Dynamics
By
–
New paper from Yann LeCun! "When Does LeJEPA Learn a World Model?" This paper proves that under Gaussian latent dynamics, LeJEPA can recover the hidden state behind nonlinear observations up to rotation. The intuition is that linear latent features are the most stable across
-
No filter beats filtered data in large LLM training
By
–
“A Bitter Lesson for Data Filtering” A common consensus is that LLMs need carefully filtered web data, because noisy data can easily hurts in small compute regimes. But this paper shows that with a large enough model size and training, the best filter is no filter. Raw Common