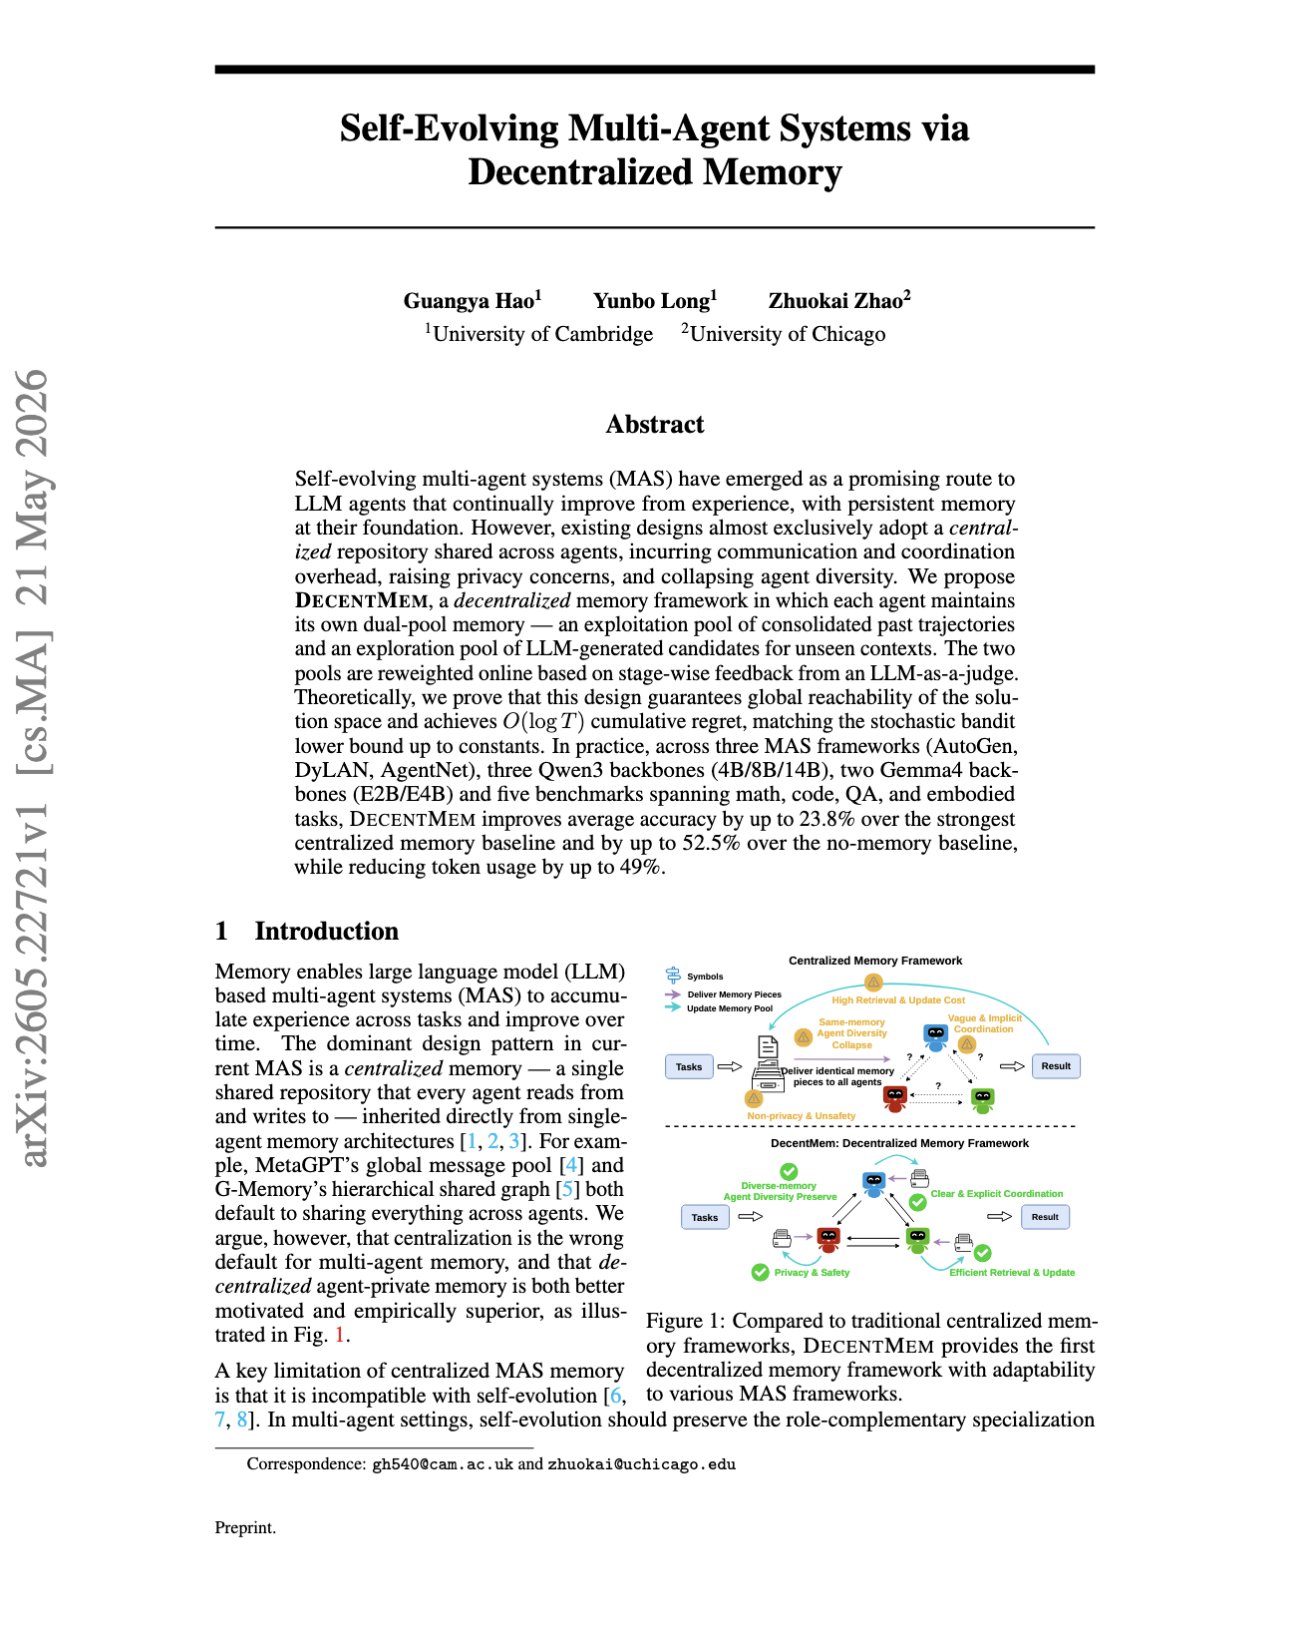
Multi-agent systems typically share a single memory pool, but this causes agents to converge towards the same behavior and leads to a loss of useful specialization. This article attributes to
@askalphaxiv
-
Dense Supervision, Sparse Updates in On-Policy Distillation
By
–
"Dense Supervision, Sparse Updates: On the Sparsity and Geometry of On-Policy Distillation" OPD uses dense teacher feedback on student-generated rollouts, so we might expect dense parameter rewriting. However, this paper shows that is not the case. They found that OPD updates
-
From AGI to ASI: definition by Google DeepMind
By
–
This article by Google DeepMind defines how AGI is a unique human-level general system, and ASI is a system or collective that surpasses large expert human organizations in almost everything. They argue that the leap could
-
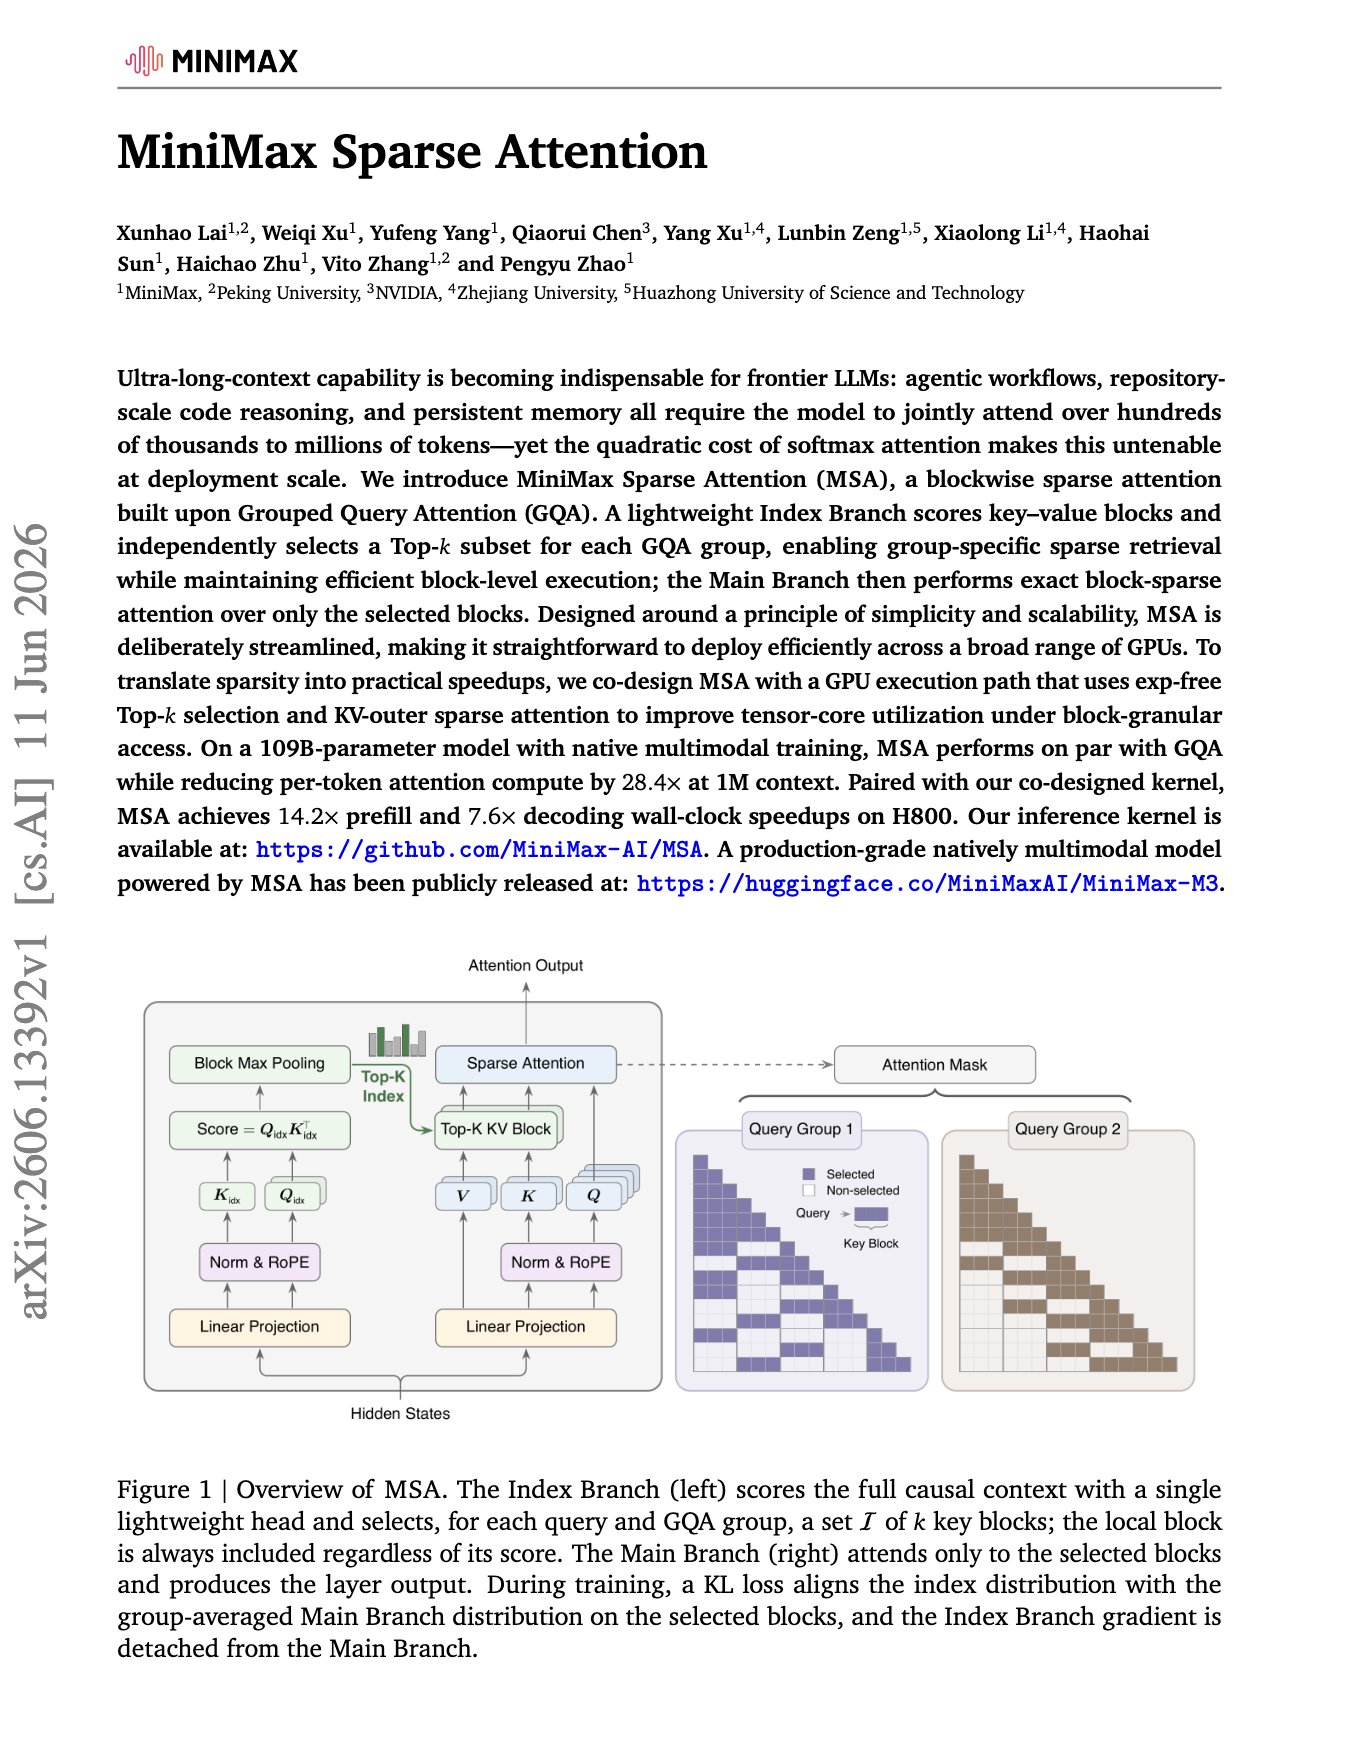
MiniMax Sparse Attention: index selects k KV blocks per group
By
–
This article from Minimax adds a small Index Branch to GQA that selects the k most relevant KV blocks per group, then executes an exact softmax only on these blocks, making sparsity native to the GPU, with an exp-free TopK and kernels.
-
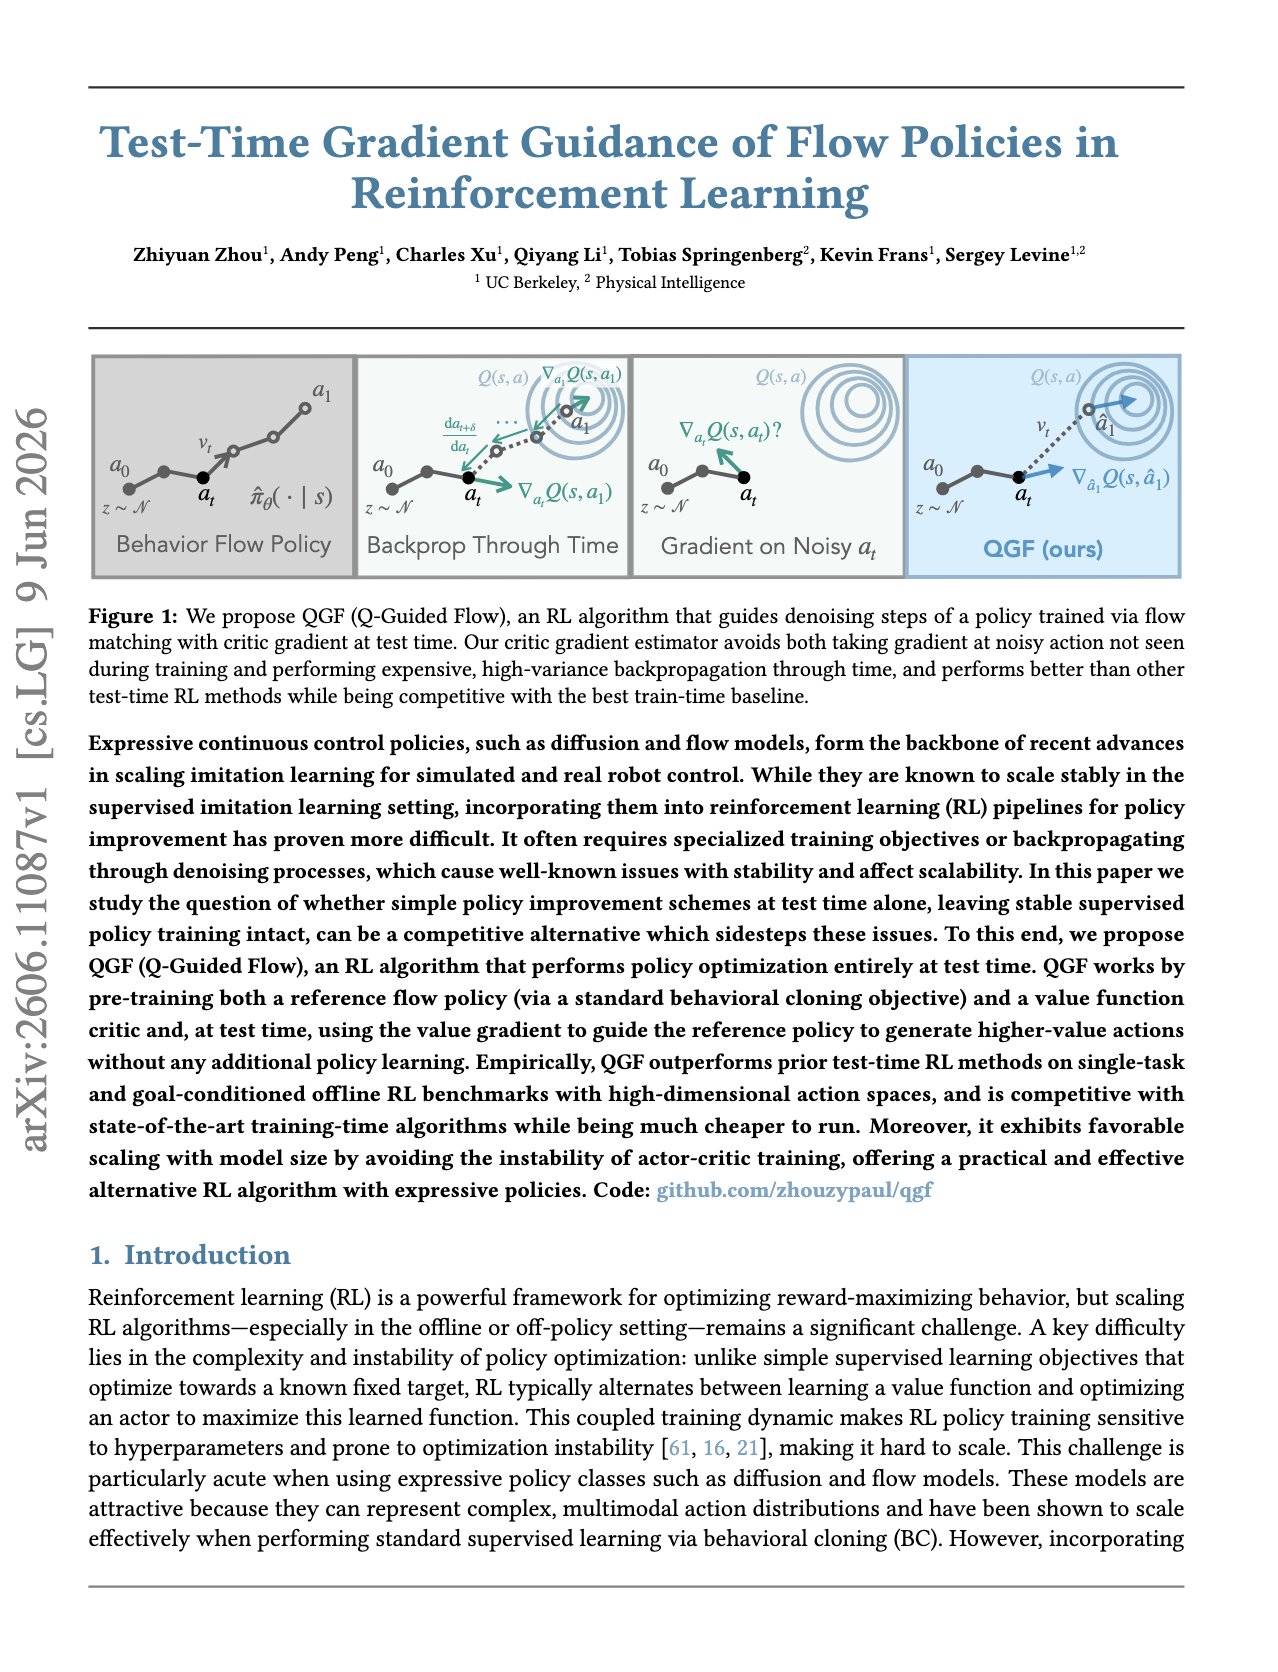
Gradient guidance at test time of flow policies in RL
By
–
Gradient Guidance at Test Time of Flow Policies in Reinforcement Learning. This paper uses expressive flow policies for RL without making policy training fragile. Thus, they do not train the policy with updates.
-
Still: Amortized KV Cache Compaction in a Single Forward Pass
By
–
Instead of deleting tokens or optimizing a new prompt-compressed cache, Still learns to synthesize a compact KV cache in a single forward pass. Thus, a small Perceiver per layer reads the cache.
-
AI agents improve their own control harnesses
By
–
—
"Auto-Harness: Harnesses That Improve Themselves" What if an AI agent improved the harness that controls how it acts? Thus, instead of humans adjusting prompts, tools, retry rules, and verification for each model, this article explores
— -
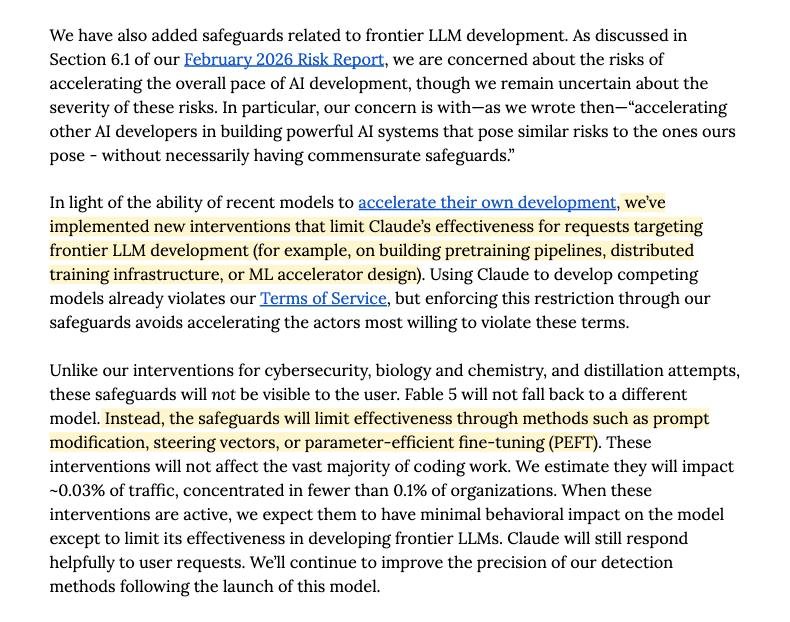
Disappointment at Anthropic’s silent degradation of Fable 5
By
–
As advocates of open research, we are disappointed to see Anthropic silently degrading Fable 5 for AI development. "Any topic related to building pre-training pipelines, distributed training infrastructure, or the design
-
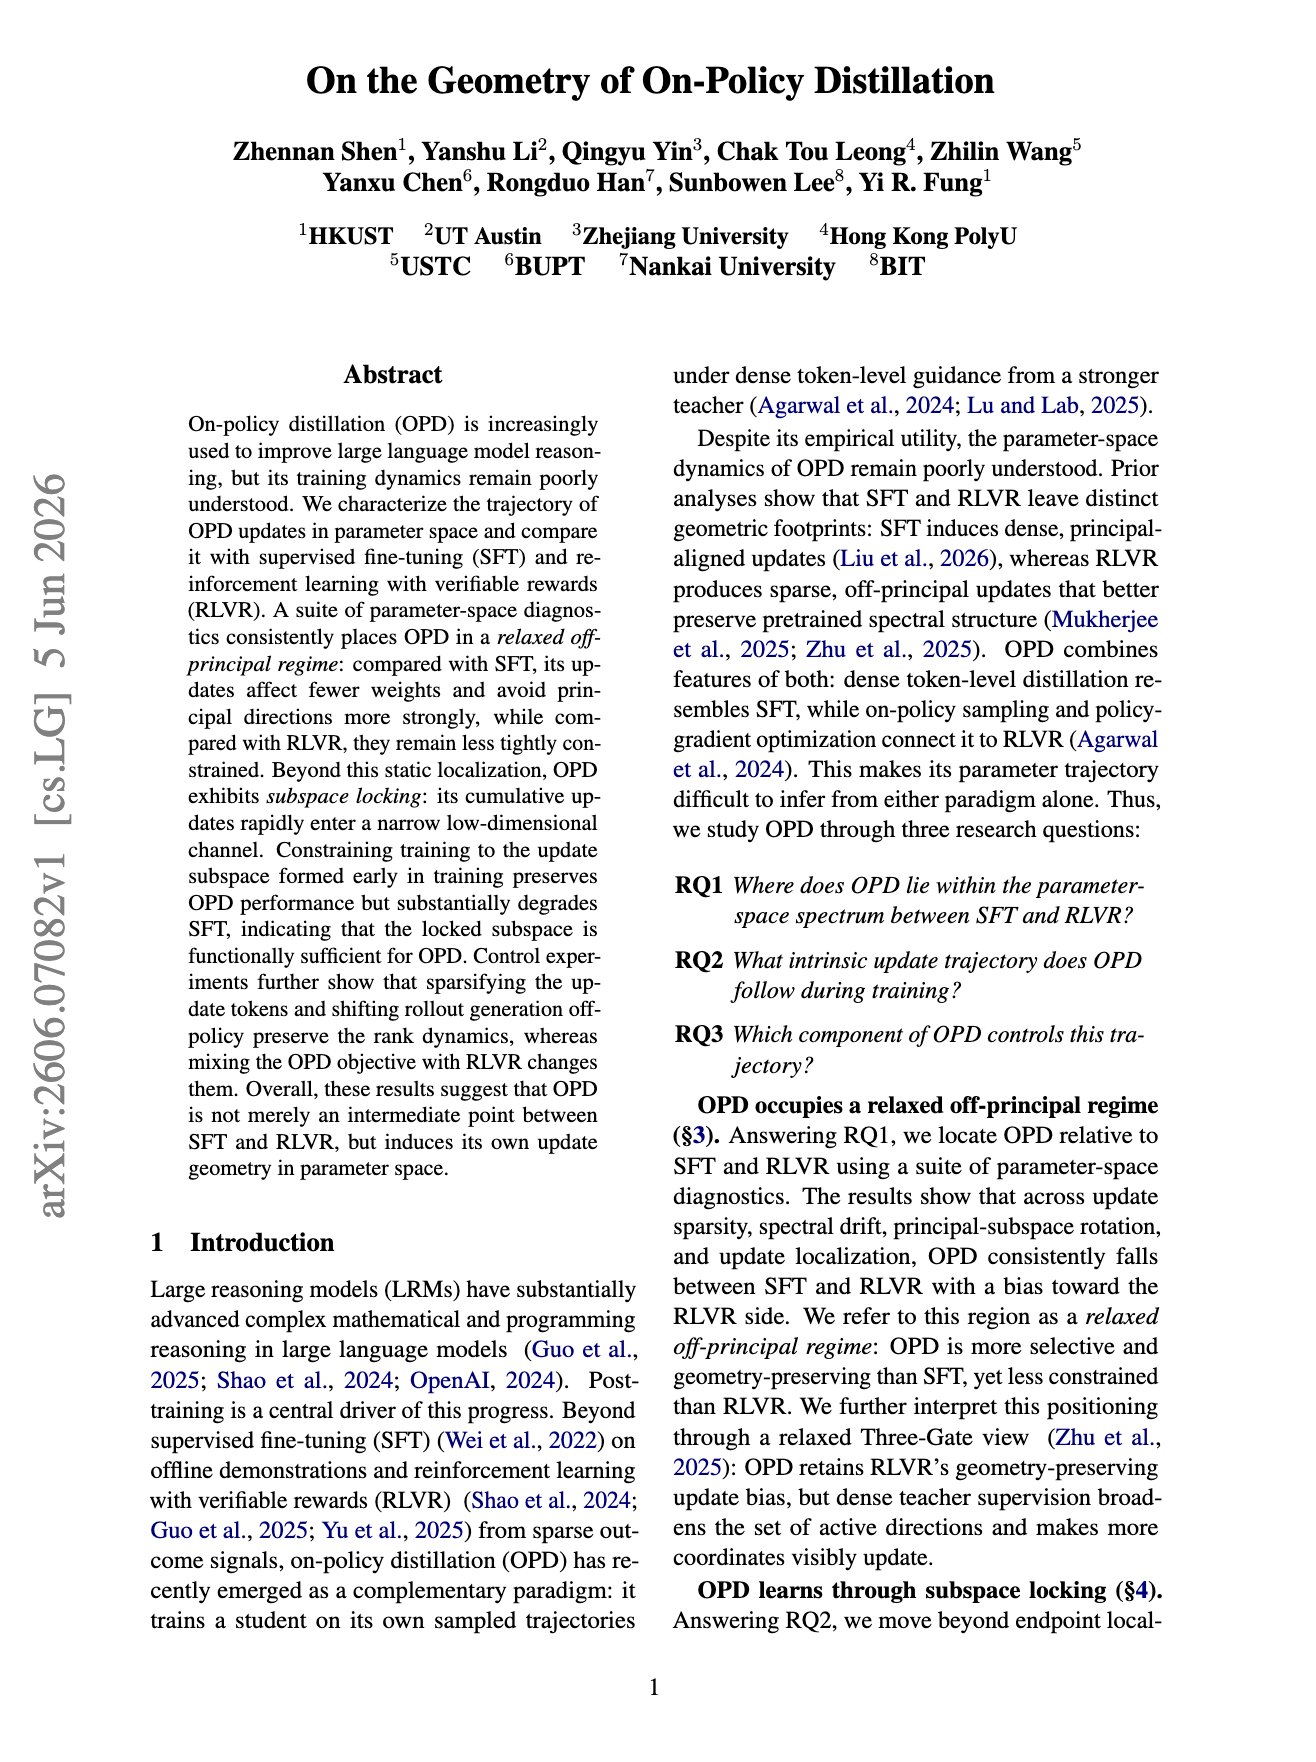
On-Policy Distillation geometry: fewer weight updates, preserves structure
By
–
“On the Geometry of On-Policy Distillation” OPD is not just SFT mixed with RLVR. It has its own update geometry. This paper shows that OPD updates fewer weights than SFT and preserves pretrained structure better, while staying less constrained than RLVR. The key finding is
-
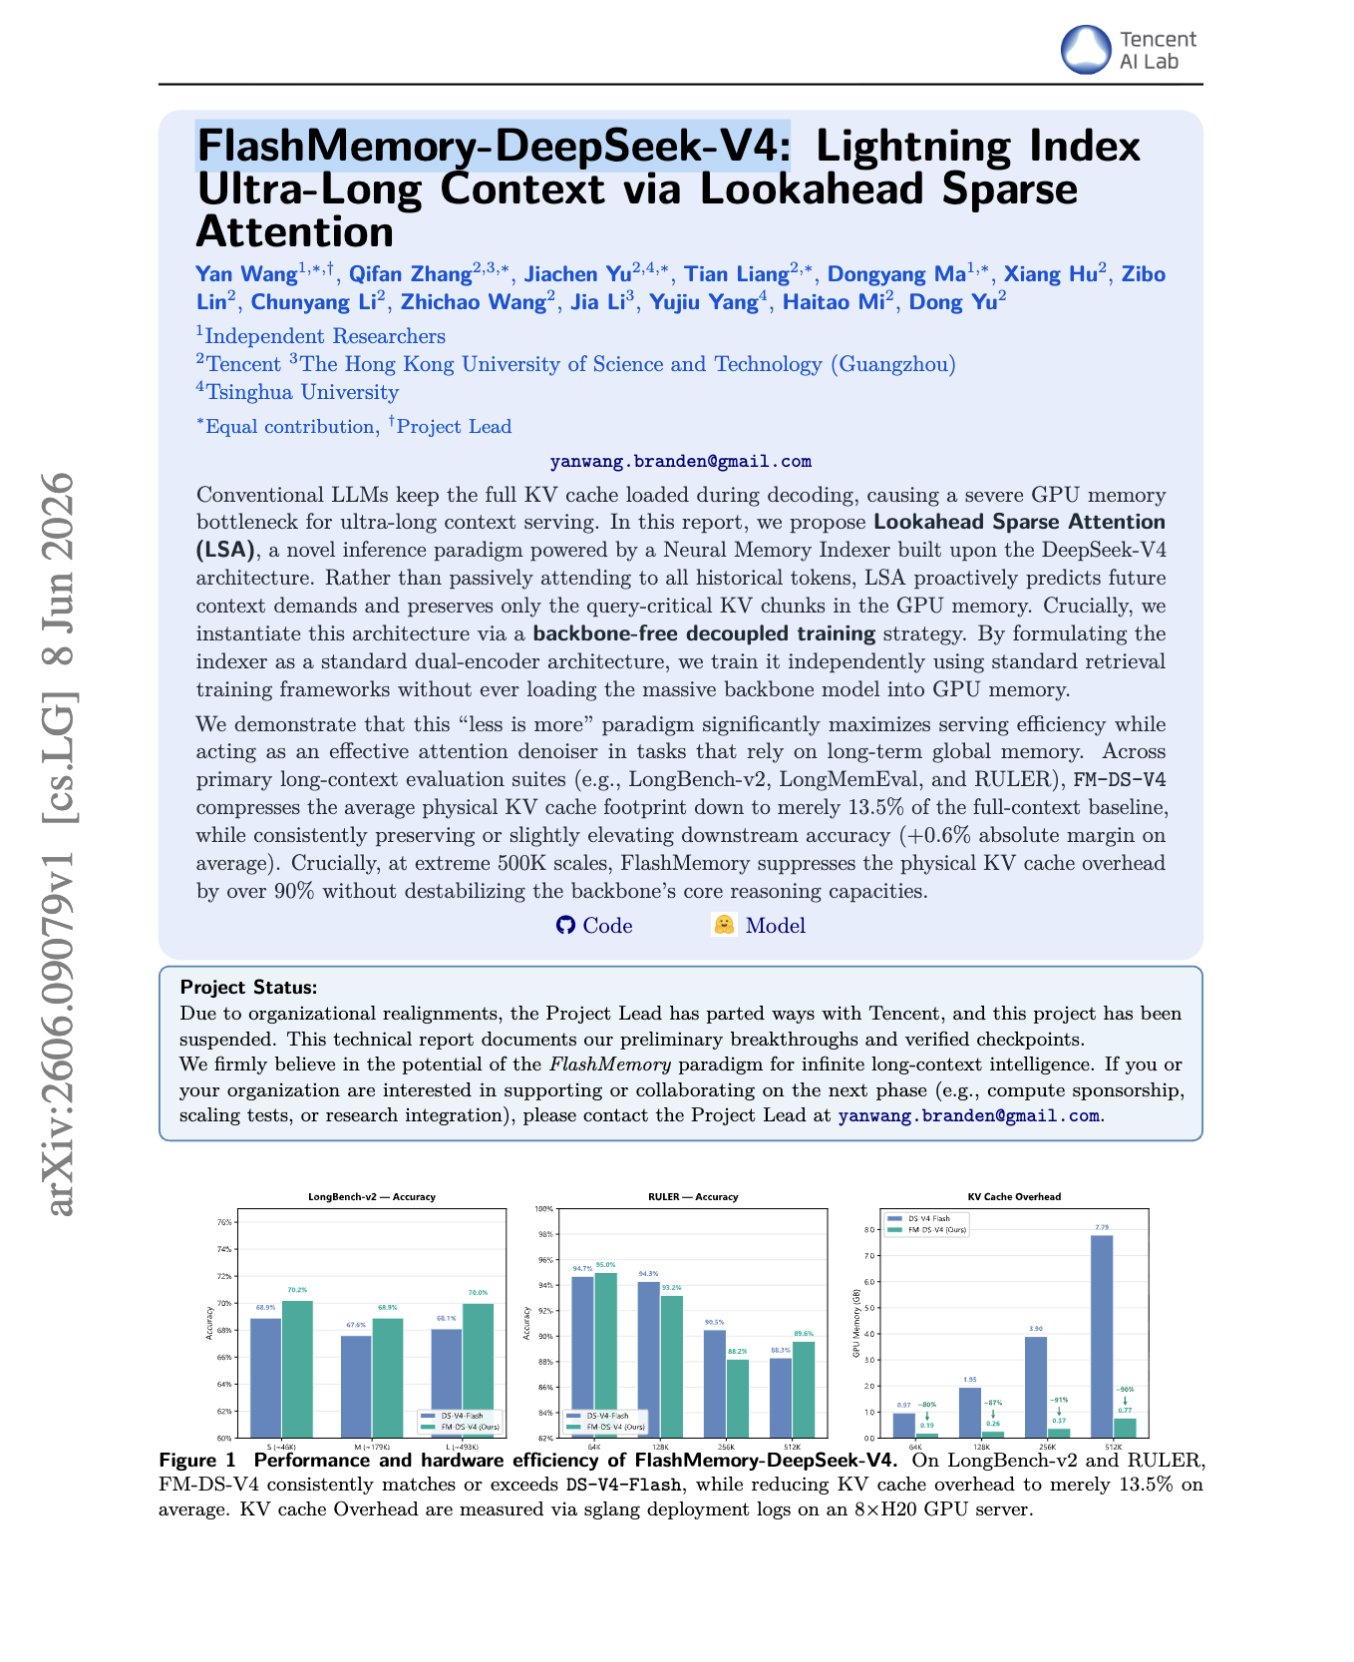
FlashMemory-DeepSeek-V4: Lightning Index Ultra-Long Context via Lookahead Sparse Attention
By
–
“FlashMemory-DeepSeek-V4: Lightning Index Ultra-Long Context via Lookahead Sparse Attention” With how Long context LLMs are being bottlenecked by KV cache, because every old token keeps consuming GPU memory even when most of it is irrelevant, this paper turns long context into