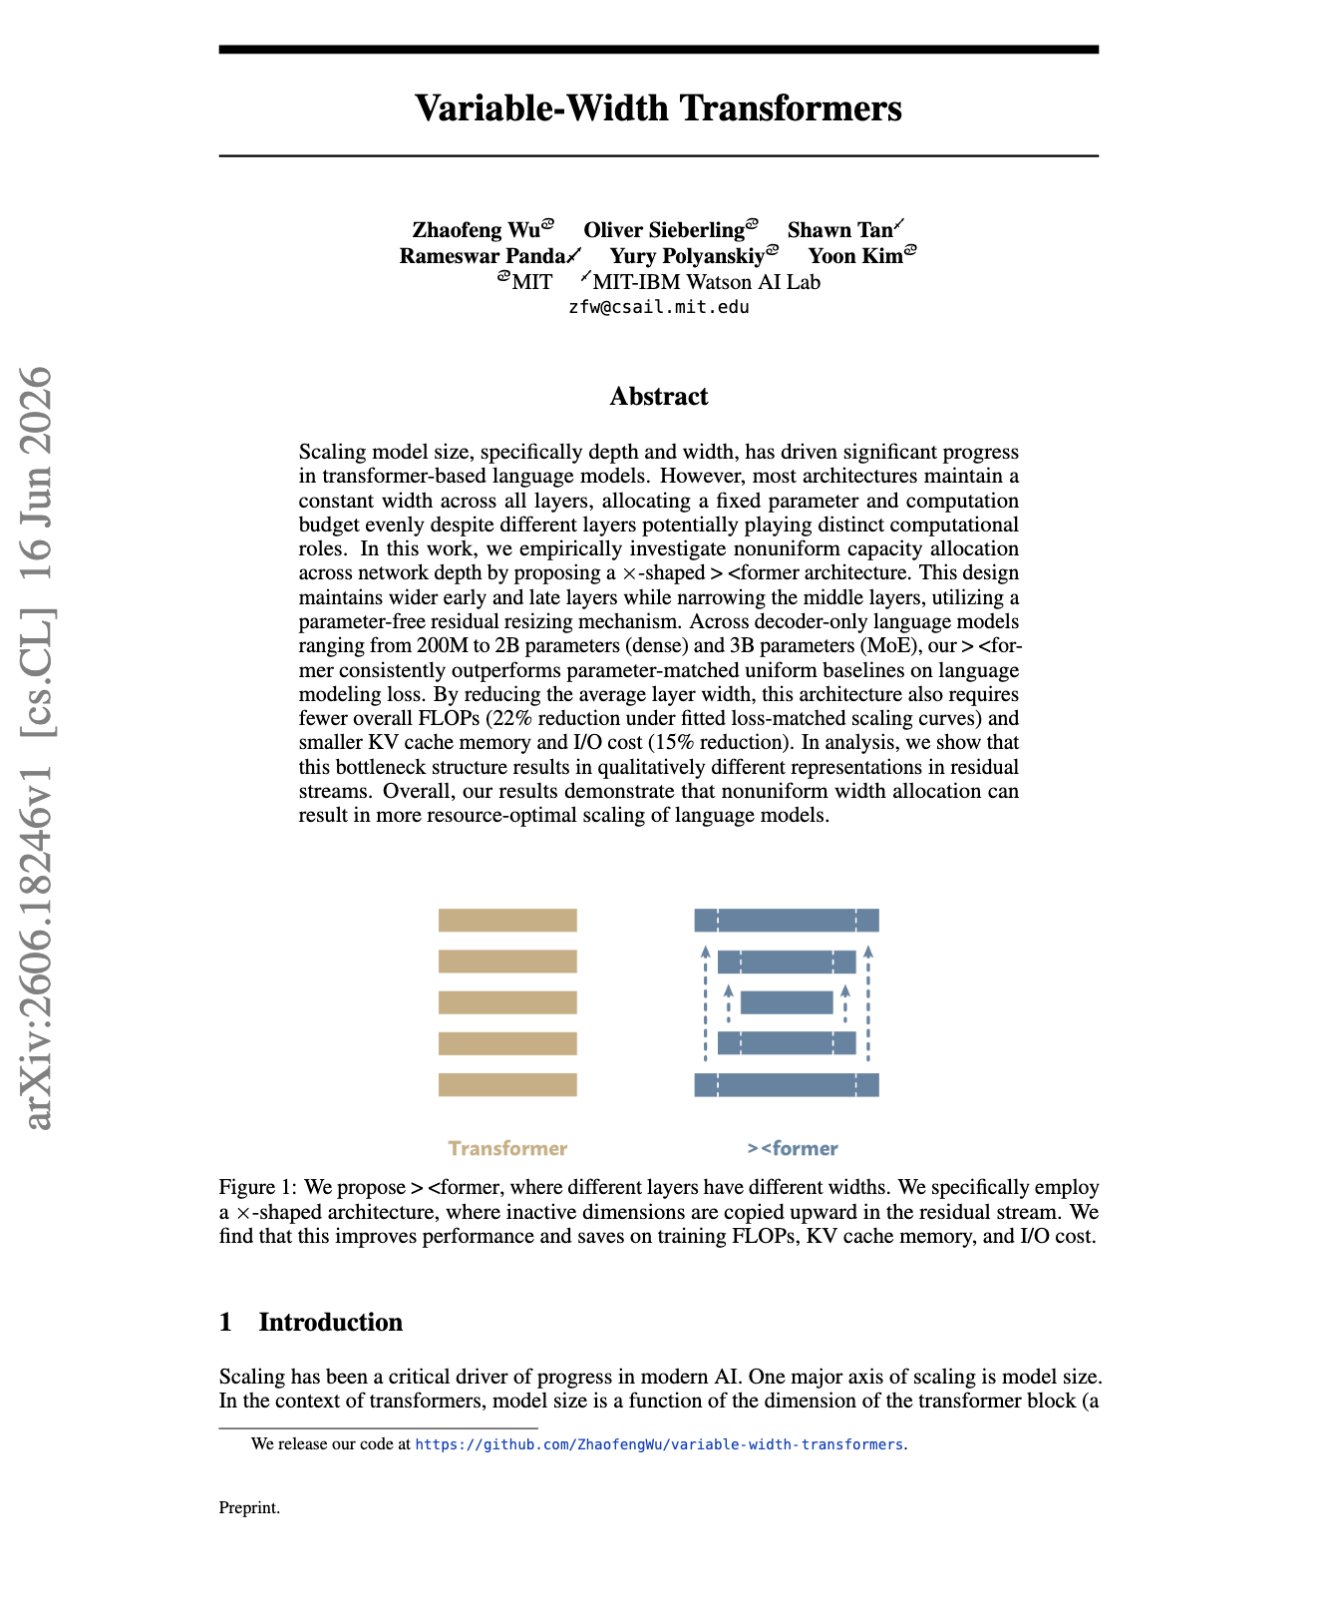
This article shows that width should be allocated unevenly, with models wide at the beginning and end but narrow in the middle. Thus, the bottleneck forces better use of representations instead of wasting the
@askalphaxiv
-
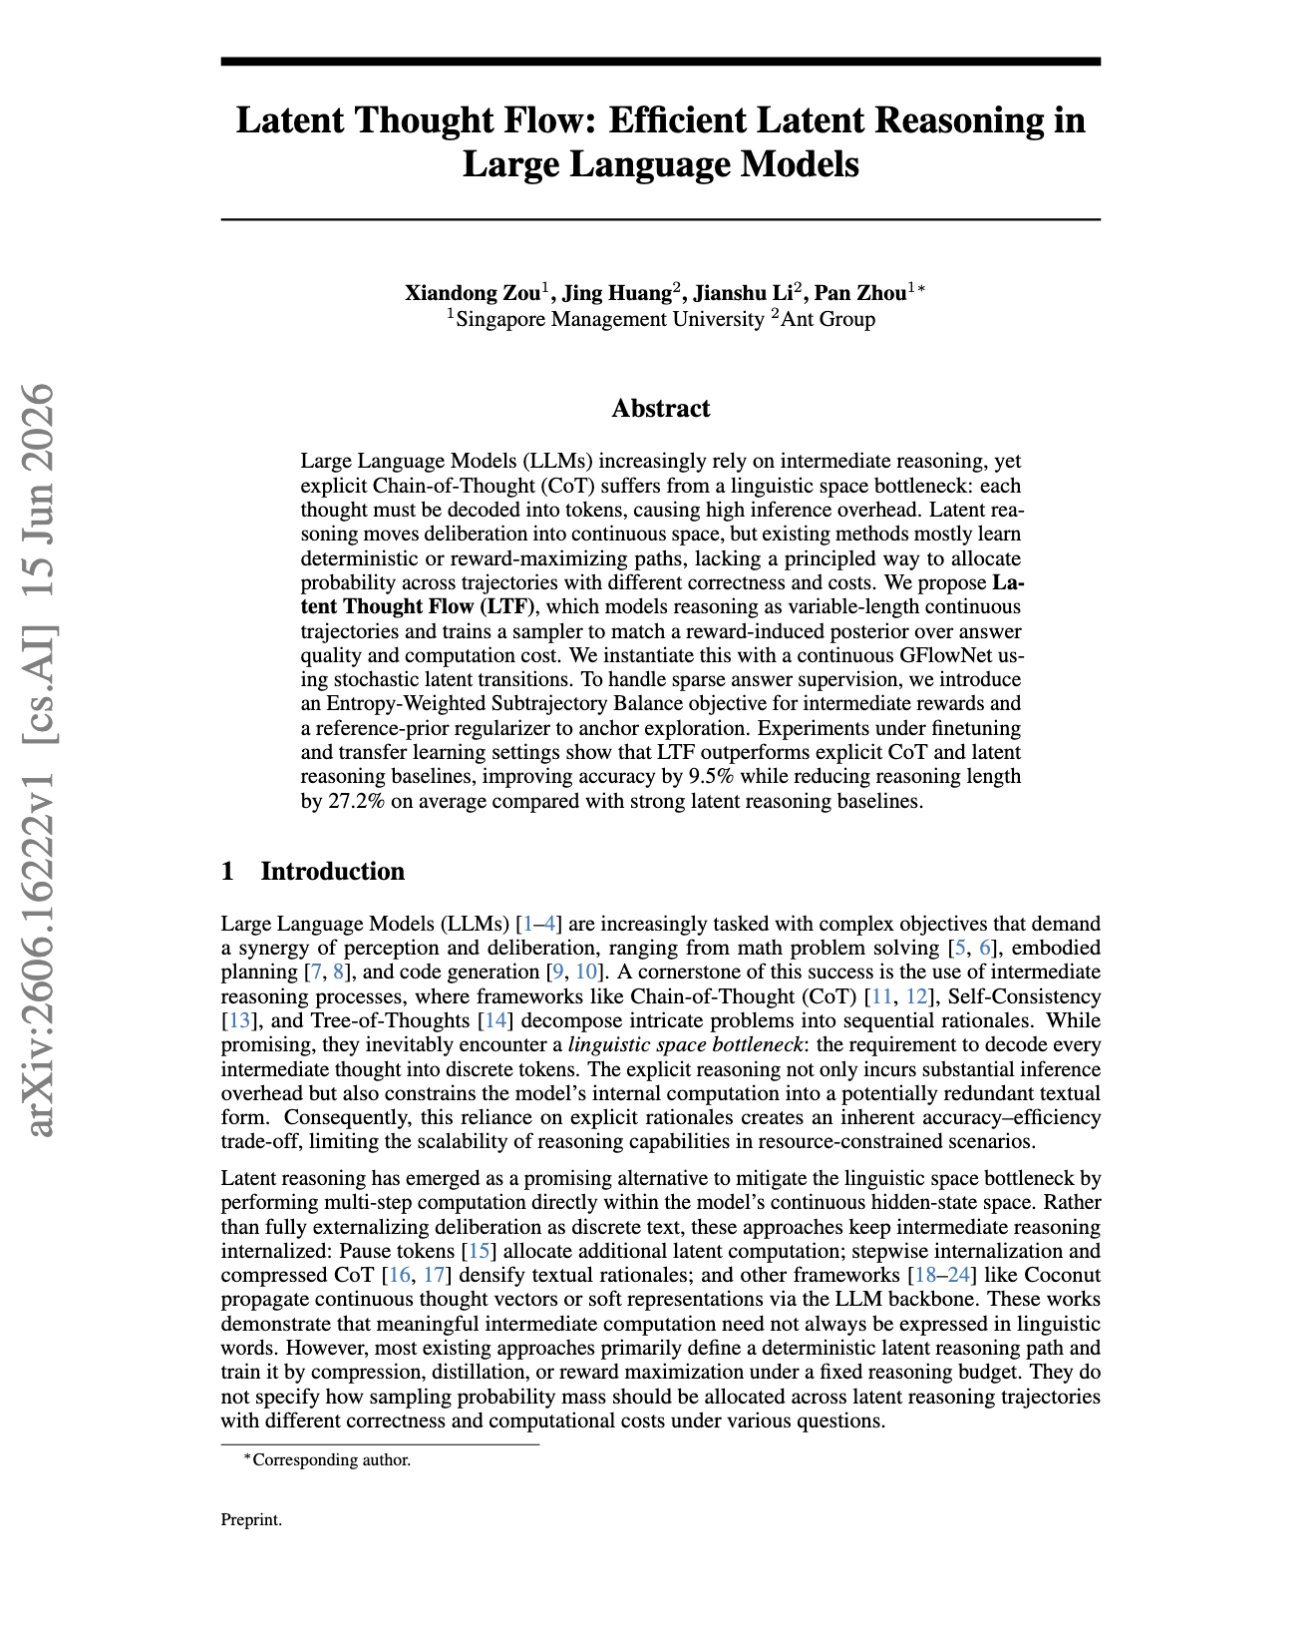
Distribution of thought paths in a continuous latent space
By
–
Latent Thought Flow This article moves reasoning into a continuous latent space, but instead of learning a single hidden thought path, it learns a distribution over many paths. Using a continuous GFlowNet, Latent Thought Flow assigns a
-

ExpRL uses reference solutions as reward scaffolds for exploratory RL
By
–
“ExpRL: Exploratory RL for LLM Mid-Training” Sparse reward RL works only when the base model can already find useful reasoning paths, but on hard problems it often gets no signal. This paper uses reference solutions as reward scaffolds instead of imitation targets, letting an
-
Presentation of arXiv paper replications by auto-research agents
By
–
Introducing paper replications for arXiv
— alphaXiv (@askalphaxiv) 17 juin 2026
Research codebases are notoriously hard to set up
We deploy autoresearch agents to ingest popular arXiv repos, resolve setup issues, and get the core claim running. You can now sort papers by ease of implementation 🚀 pic.twitter.com/Zw6DkX4ycqPresentation of paper replications for arXiv Research codebases are notoriously difficult to set up We deploy auto-research agents to ingest popular arXiv repositories, resolve configuration issues and make the
-
New article by LeCun: visual learning via temporal differences
By
–
Another interesting article supervised by Yann LeCun! "You Don't Need Strong Assumptions: Visual Representation Learning via Temporal Differences" This article proposes Temporal Difference in Vision (TDV), which is a simple idea for learning vision from videos.
-
Introducing GLM-5.2 for Understanding Research Articles
By
–
Introducing GLM-5.2 for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 16 juin 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/84LDzhLjhhHighlight any section of an article to ask questions and '@' other articles for quick context, comparisons, and benchmark references.
-
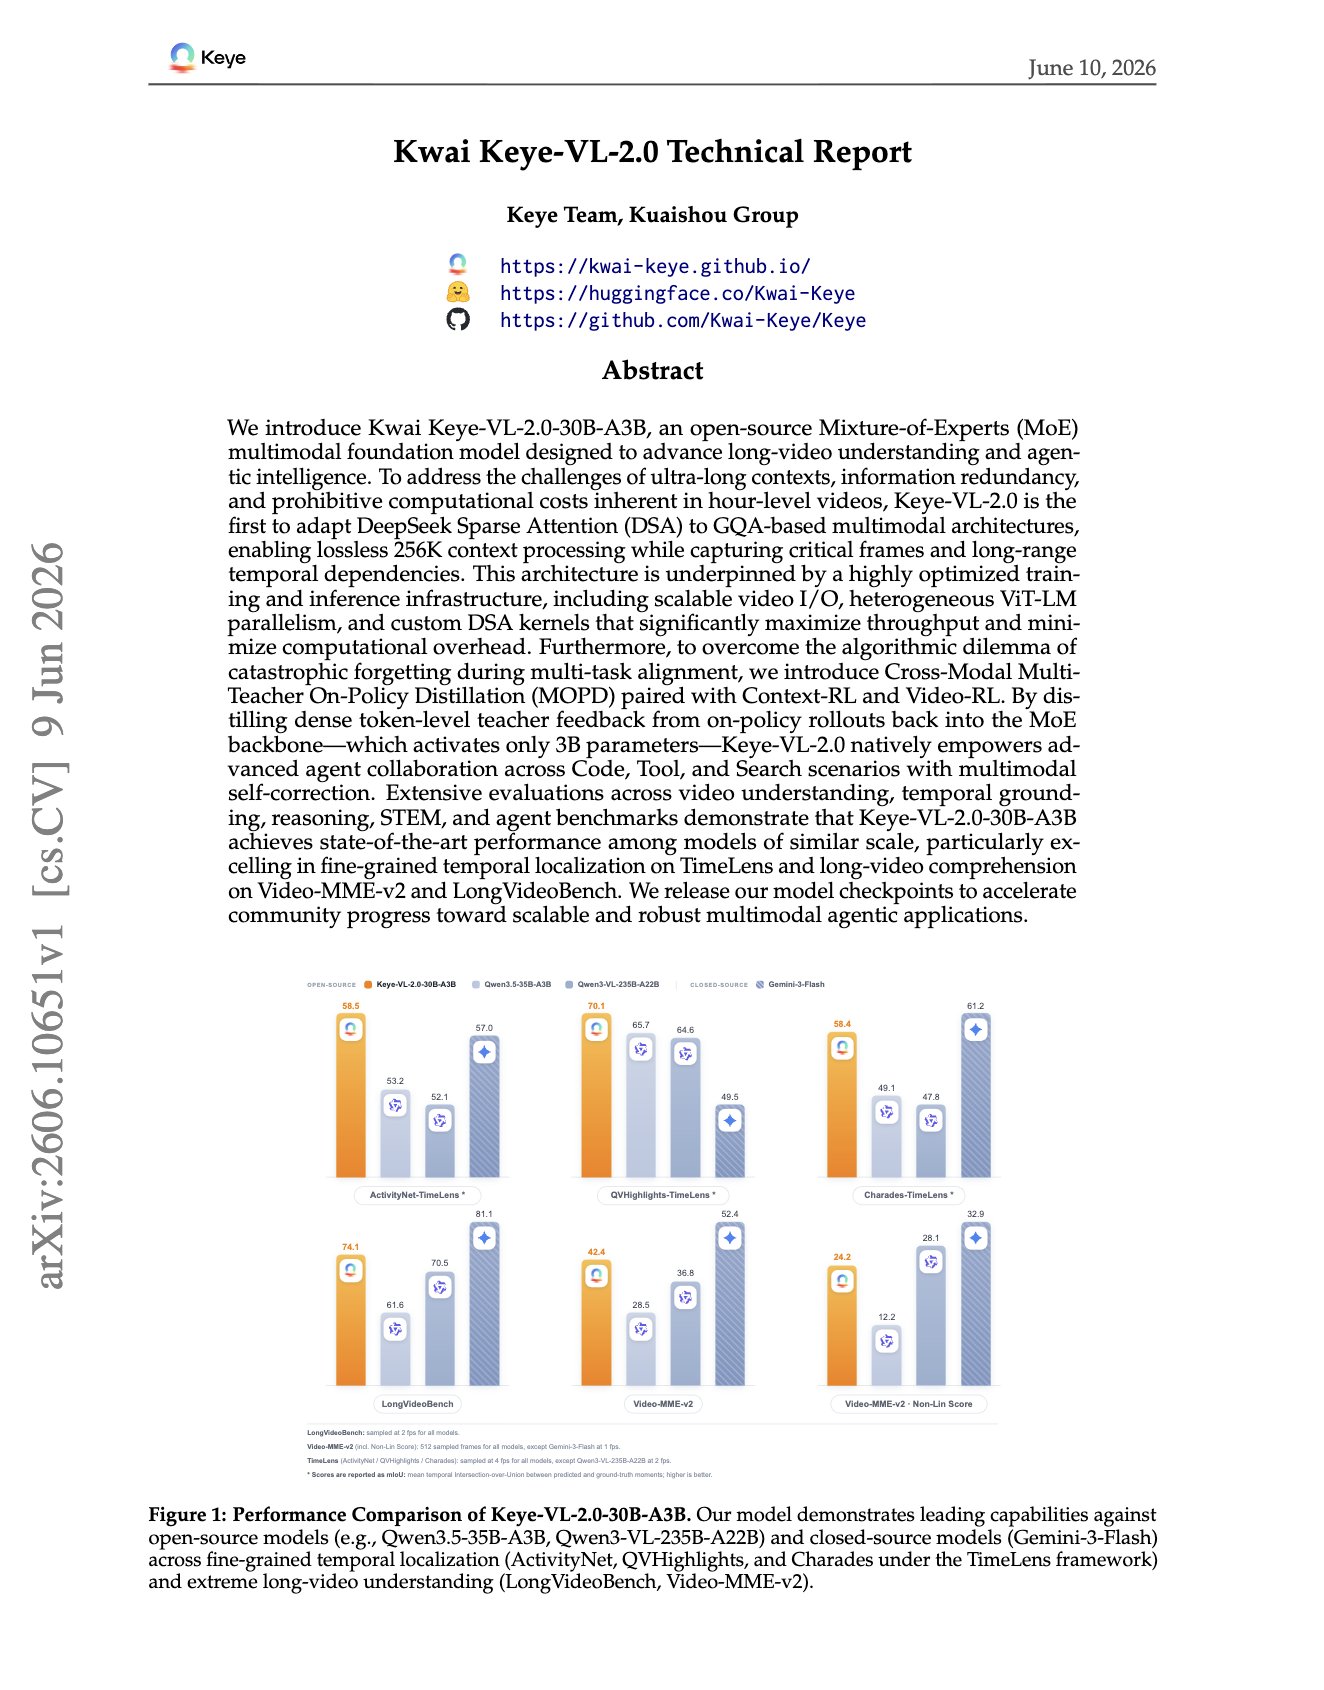
Long video reasoning with DeepSeek sparse attention and multimodal MoE
By
–
"Kwai Keye-VL-2.0 Technical Report" This paper makes long-video reasoning much more feasible by adapting DeepSeek Sparse Attention to a GQA-based multimodal MoE, reaching 256K context with only 3B active parameters. As dense attention makes hour-level context way too expensive,
-
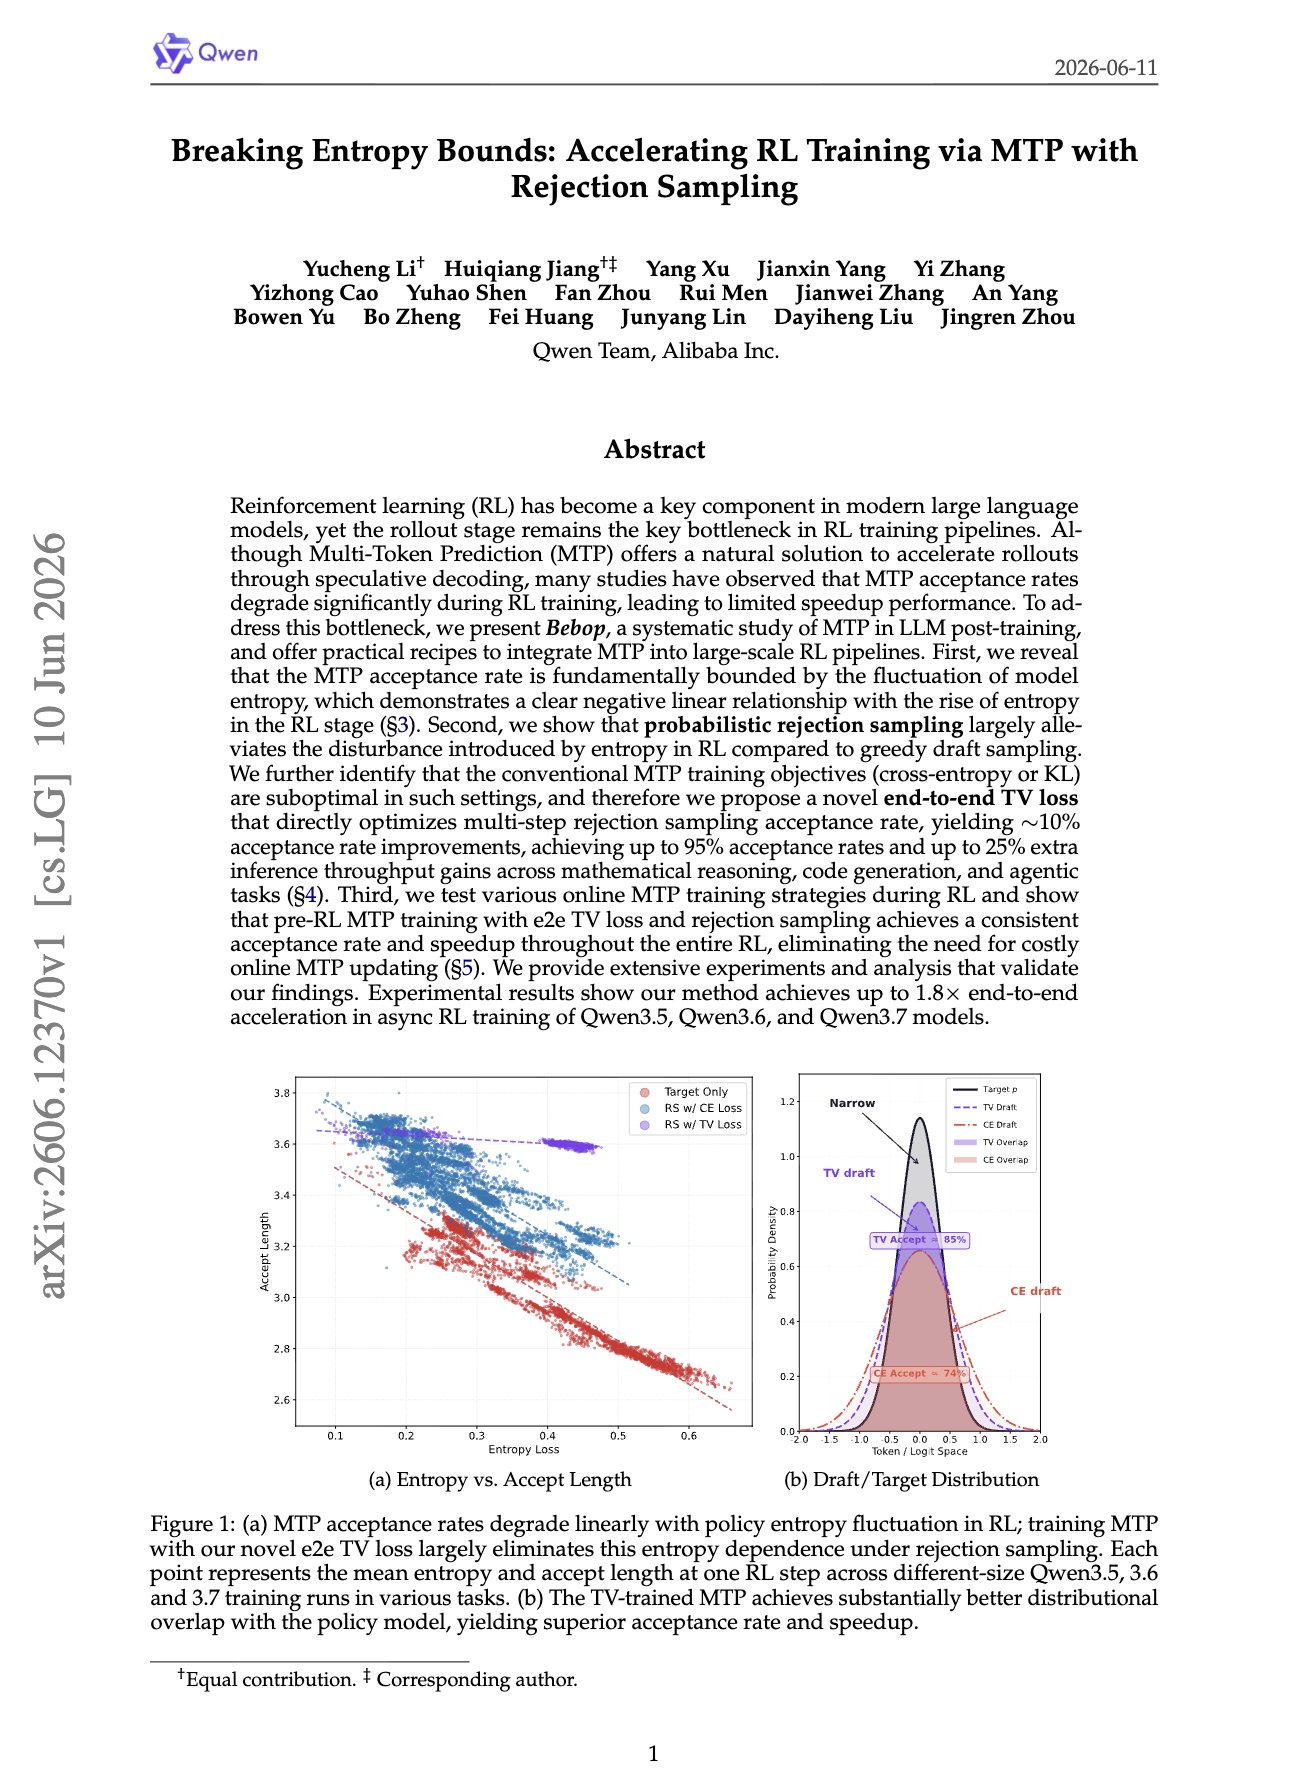
Accelerating RL Training via MTP and Rejection Sampling
By
–
Breaking entropy bounds: Accelerating RL training via MTP with rejection sampling. Given that RL training is limited by rollouts, and MTP is used to accelerate them, its acceptance rate would still collapse as the entropy of the
-
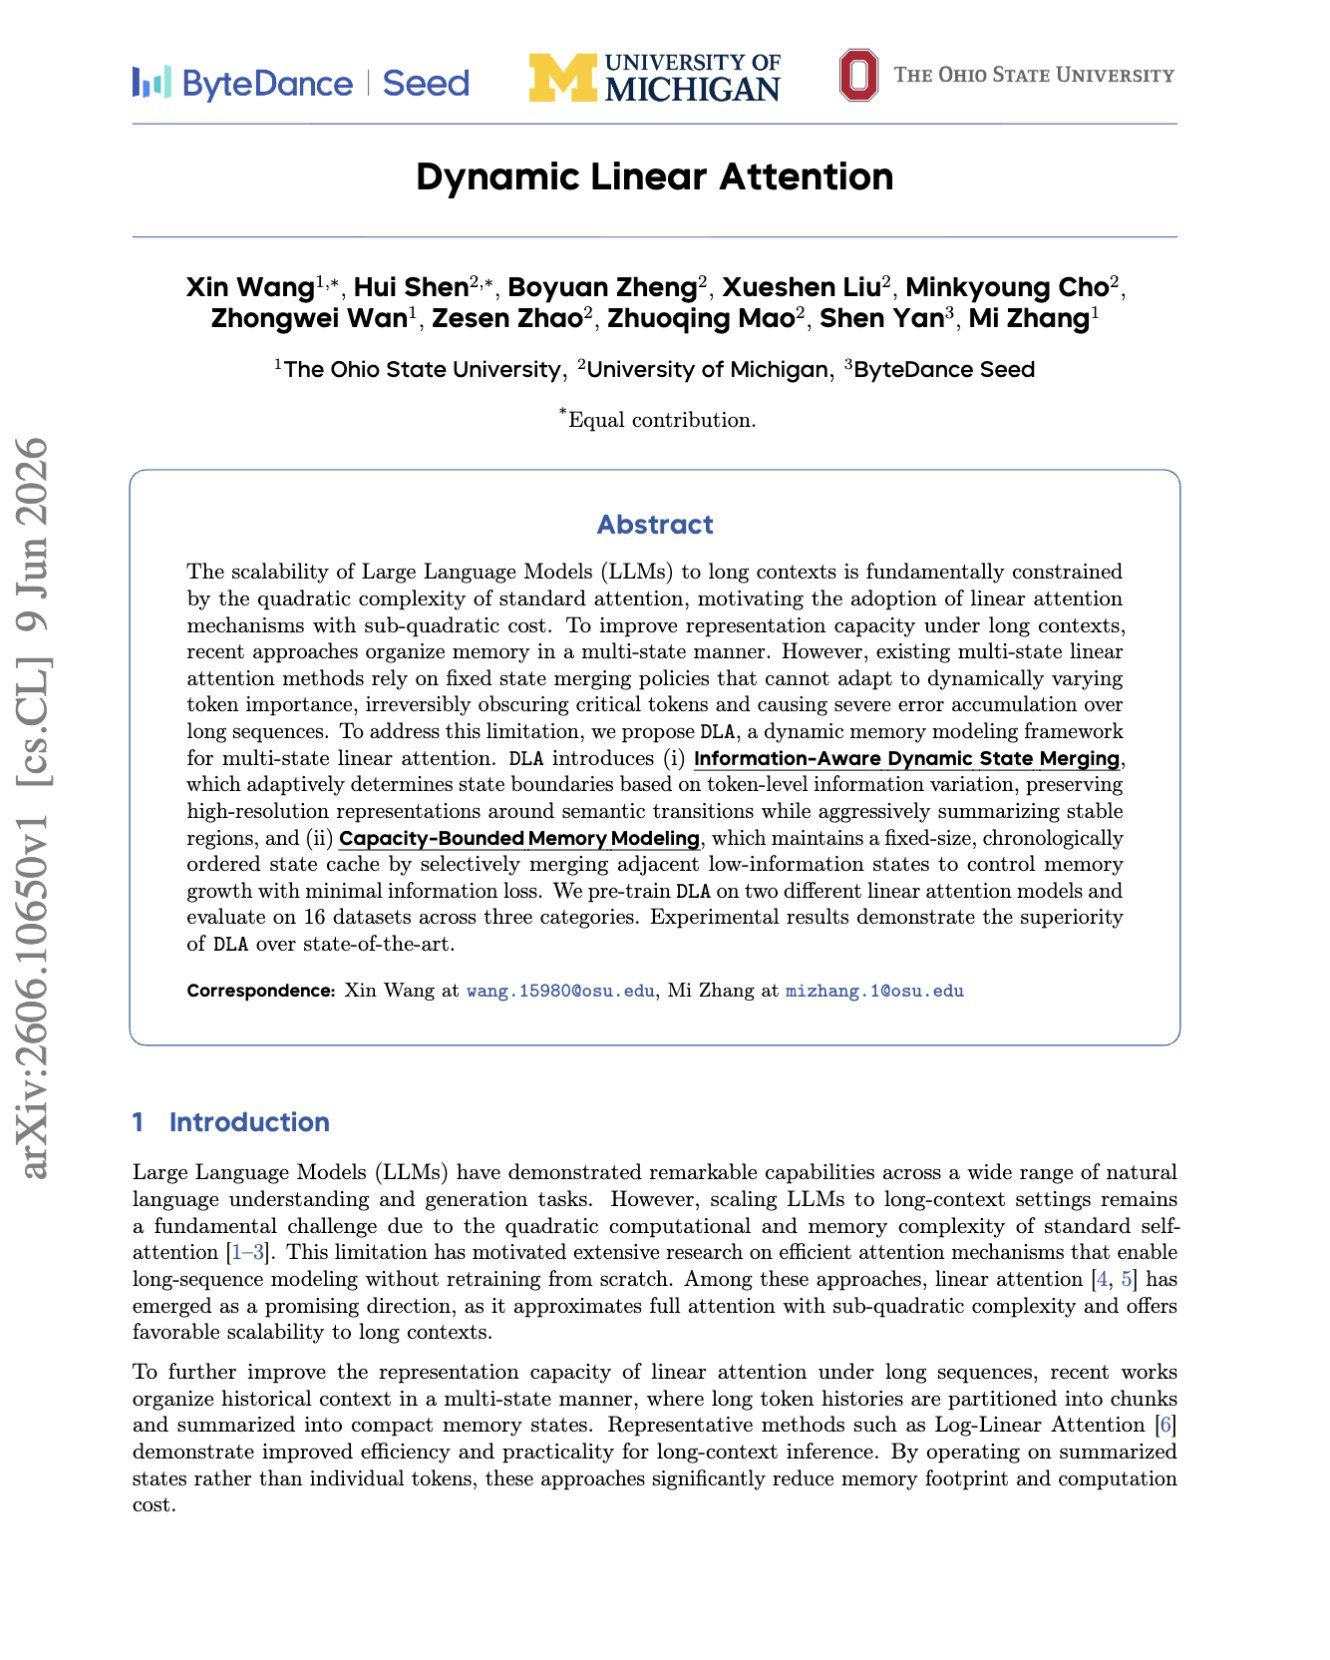
Dynamic Linear Attention for Adaptive Token Compression
By
–
"Dynamic Linear Attention" Most long-context linear models compress tokens using fixed blocks or logarithmic schedules, but long texts are not uniform. Stable segments can be summarized, while the
-
Mirage: Latent Spatial Memory for Video World Models
By
–
“Latent Spatial Memory for World Models” world models need a 3D memory to avoid drift, but RGB point cloud caches are slow because each step renders pixels and re-encodes them into latents via a VAE. The Mirage approach