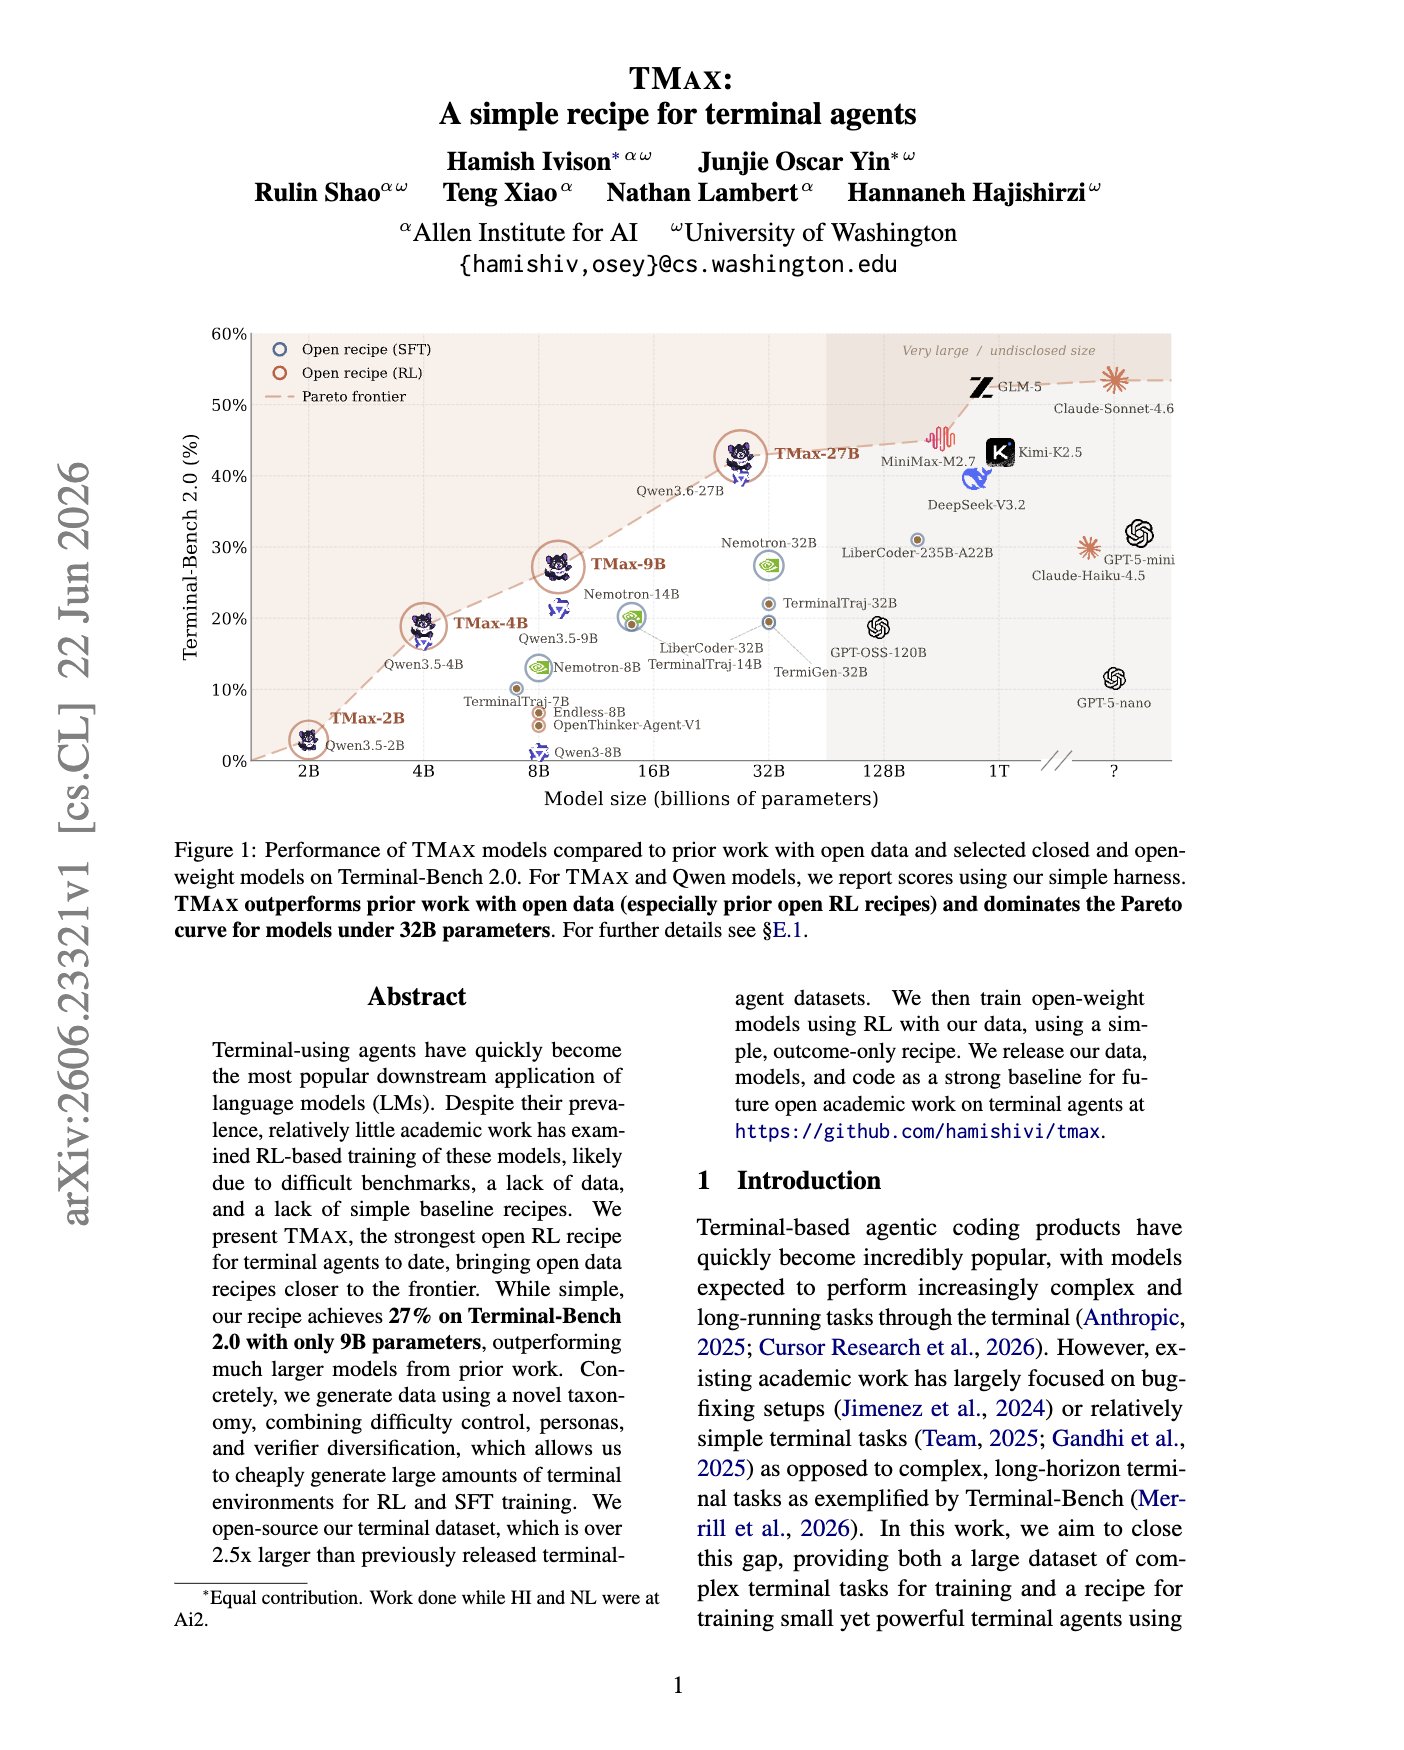
A first-of-its-kind open reinforcement learning recipe for terminal agents has just been released. As terminal agents become the primary interface for coding models, this paper, TMAX, shares a reproducible training recipe.
@askalphaxiv
-
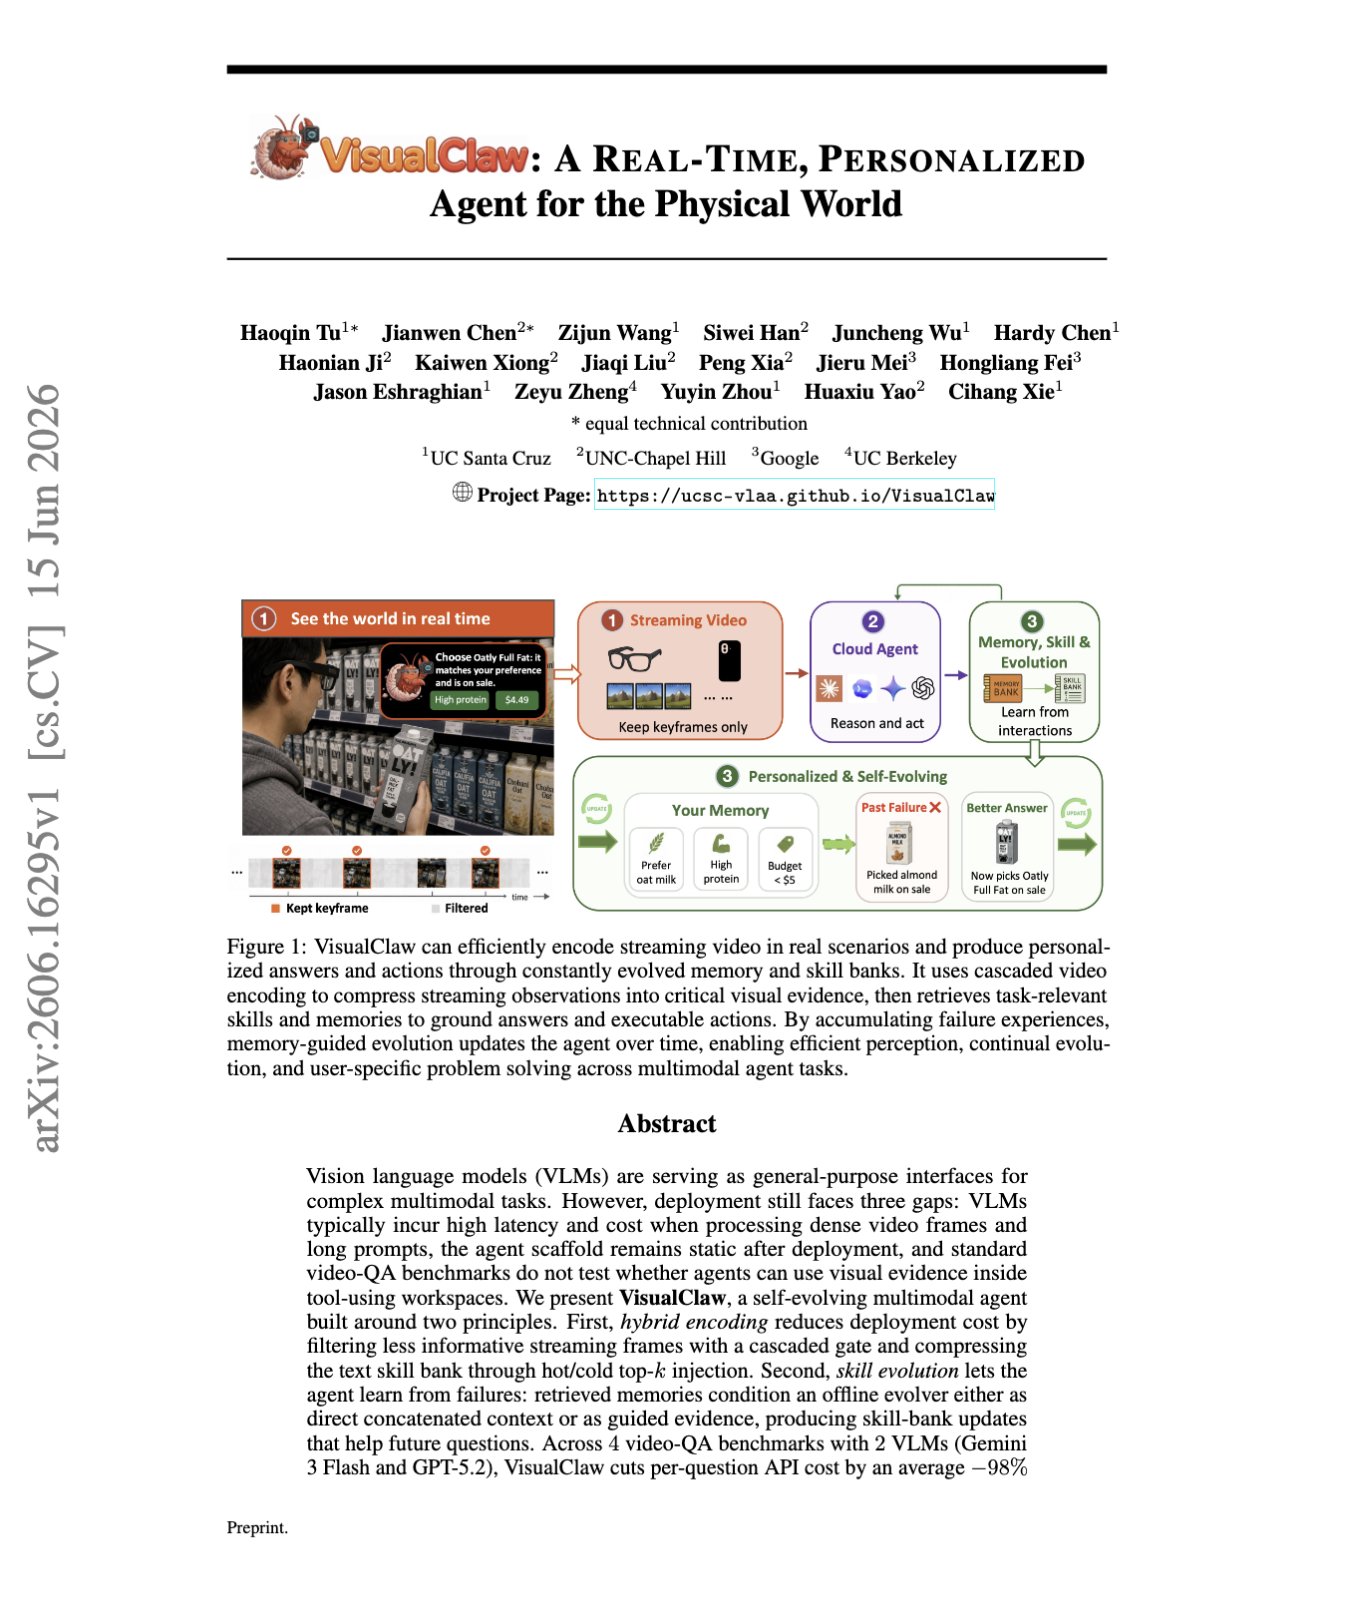
VisualClaw: Real-time personalized agent using only key video moments.
By
–
"VisualClaw: A Real-Time, Personalized Agent for the Physical World" AI agents for video are too expensive because they usually send too many frames to the model, and they do not learn from past mistakes. This paper proposes a way to keep only the important video moments,
-
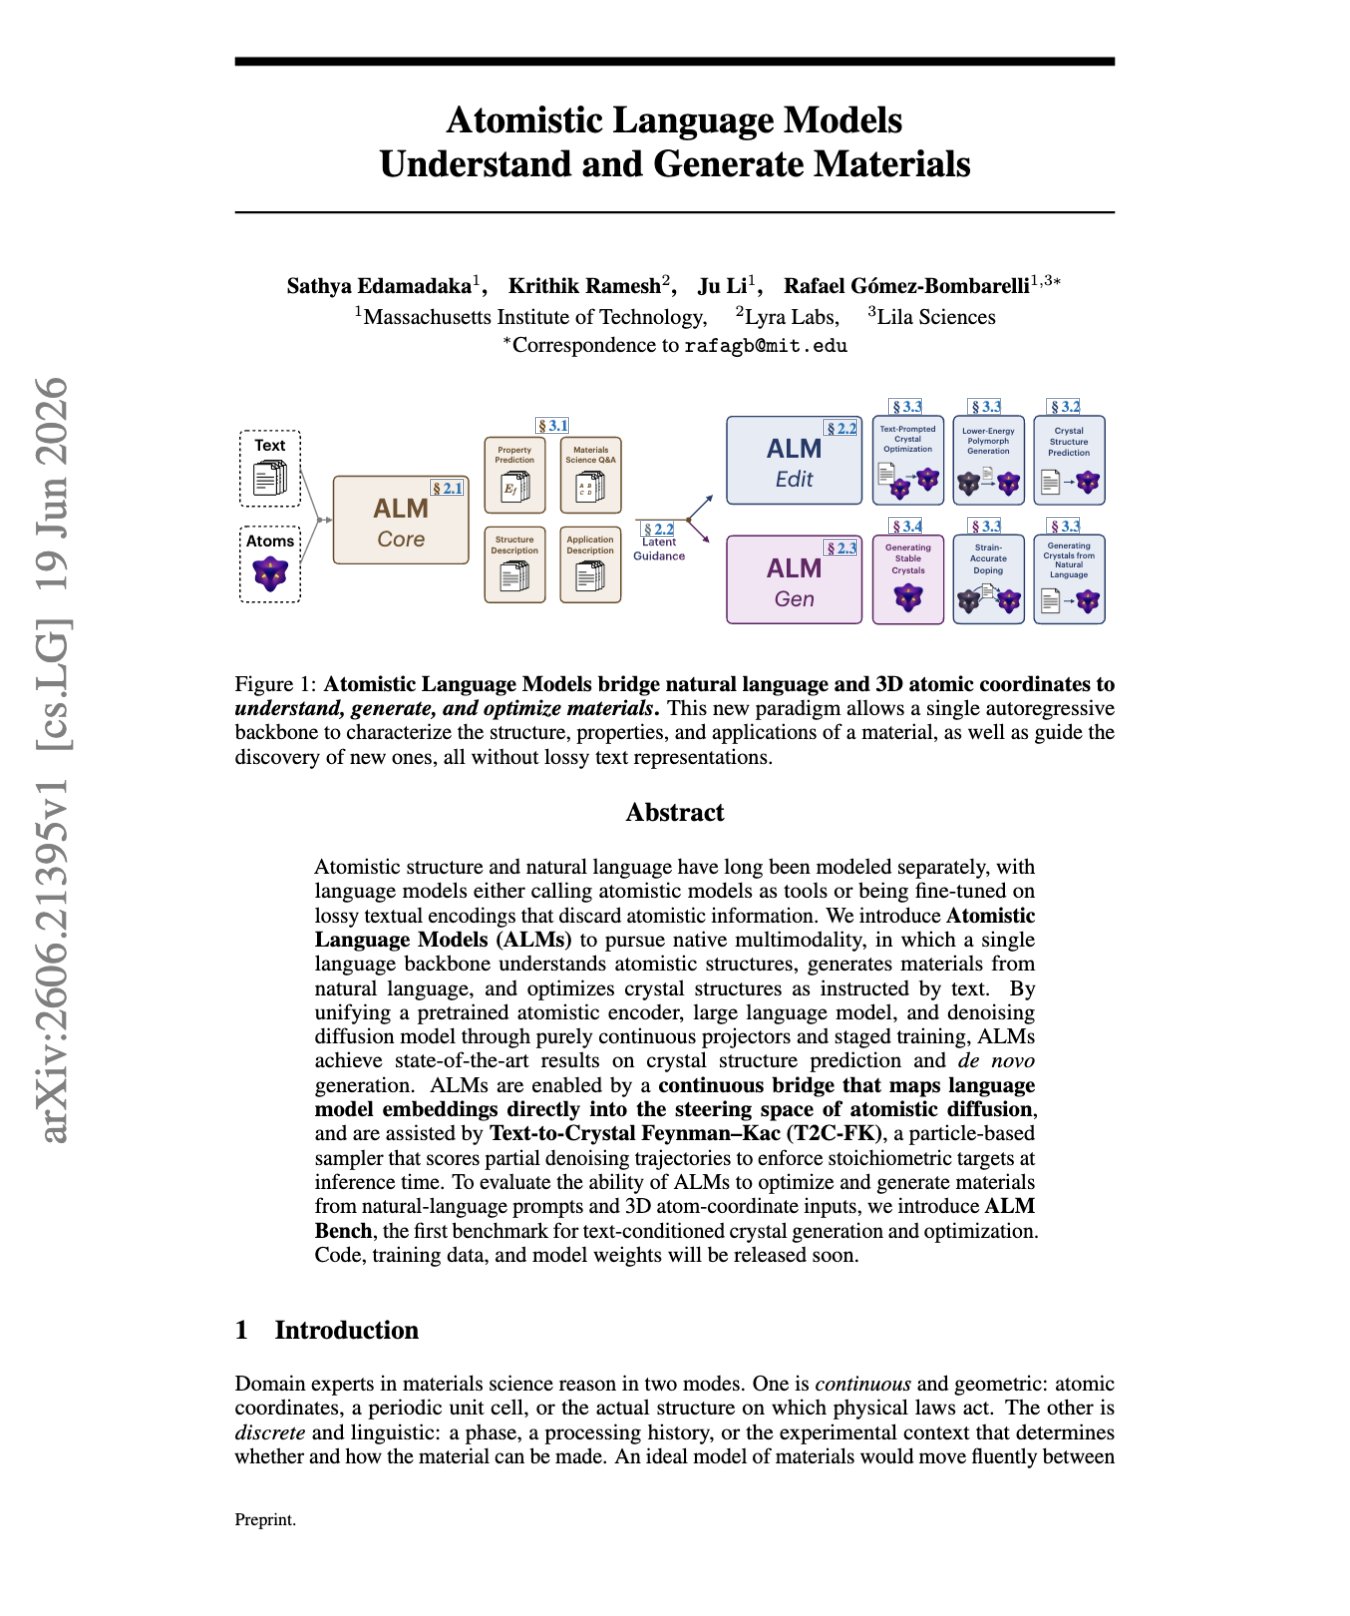
Multimodal AI connects 3D atomistic models with language
By
–
"Atomistic Language Models Understand and Generate Materials" Most materials AI still treats crystals and language separately, either turning atoms into lossy text formats or making LLMs call atomistic tools. This paper makes materials natively multimodal by connecting a 3D
-
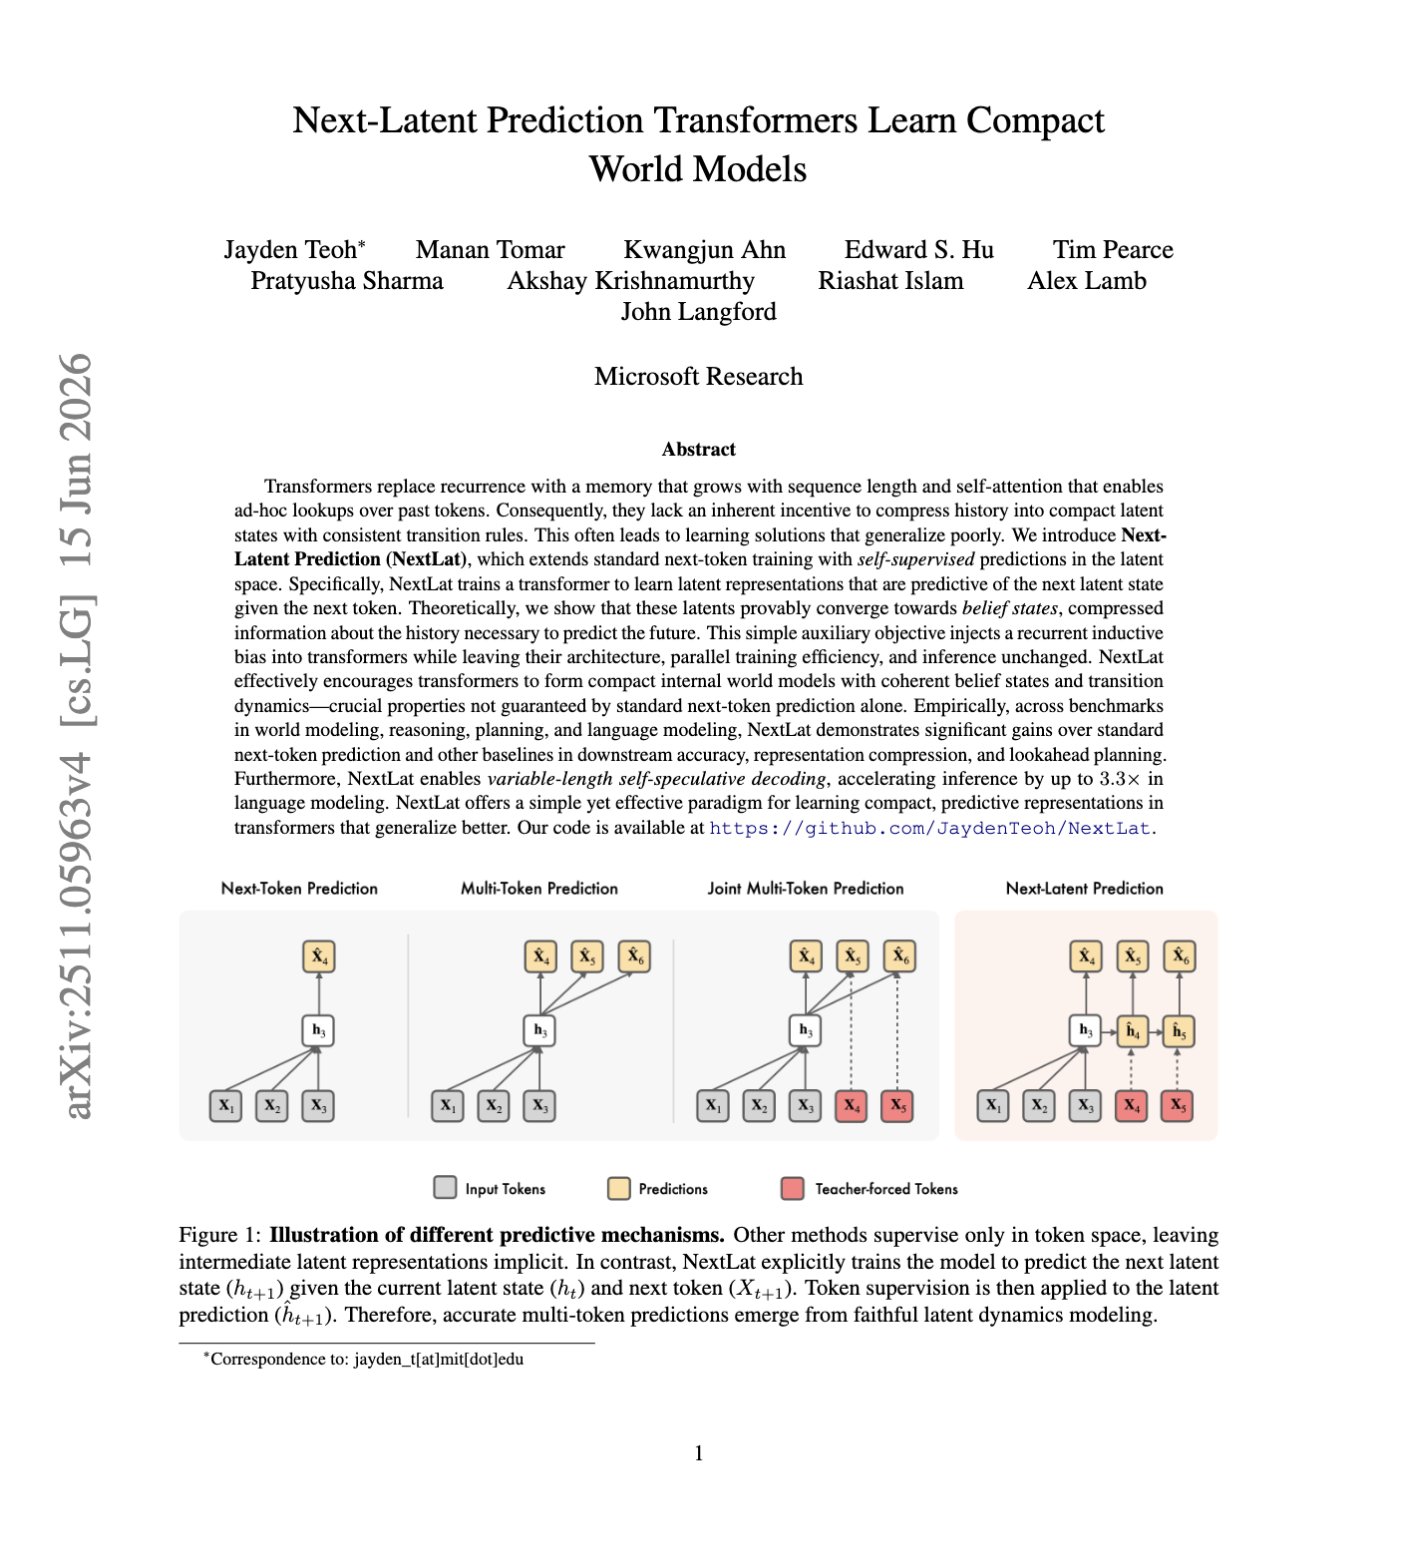
Reasoning in Latent States and Tokens for Transformers
By
–
What if you taught transformers to reason in both latent states and tokens? This Microsoft paper adds a self-supervised objective of predicting the next latent state to the standard next-token training, where a lightweight dynamic model
-
OpenRouter to solve GPU shortage in research
By
–
Tired of seeing “out of capacity” while looking for GPUs? Introducing OpenRouter for compute
— alphaXiv (@askalphaxiv) 23 juin 2026
In the past 6 months, overwhelming demand for compute has made pricing and availability huge challenges for the research community
We aggregate compute offerings from across the… pic.twitter.com/Z3IdyPvbkmTired of seeing "capacity exhausted" when searching for GPUs? Introducing OpenRouter for Compute Over the past 6 months, overwhelming demand for compute has made pricing and availability real challenges for the research community We aggregate
-
Sparrow: Sparse Deployment for Long-Context RL LLM
By
–
Long-context RLVR is powerful, but most of the cost comes from generating massive CoT deployments. Sparse attention would make it faster, that's it.
-

VIMPO derives value function from policy to improve GRPO
By
–
"VIMPO: Value-Implicit Policy Optimization for LLMs" While GRPO is simple because it avoids a critic, it still gives every token in a reasoning trace the same reward signal. This paper tries to get the best of both worlds by deriving the value function from the policy itself
-
Play with SkyRL via OpenResearch.sh or autoarxiv with GLM 5.2
By
–
4/4: You can play with this yourself! Visit http://
OpenResearch.sh (
http://
openresearch.sh) or change ‘arxiv’ to ‘autoarxiv’ on the official SkyRL paper https://
autoarxiv.org/abs/2511.16108 and use the GLM 5.2 model to iterate on the repo! -
GLM 5.2 lacks image understanding; uses numpy for WandB charts
By
–
3/4: One limitation worth noting: GLM 5.2 has no image understanding. While Opus and Fable can consistently identify trends in WandB charts, GLM resorts to writing numpy code to smooth and clean the raw WandB numbers before analyzing. For simpler runs like this example this is
-
GLM 5.2 agent ablation demos on continual learning papers
By
–
2/4: We’ll be sharing a couple other fun and more complex demos this week where the GLM 5.2 agent conducts ablations on recent continual learning papers like SDPO. This can hopefully give you a sense of what these models can and cannot do when it comes to assisting in the