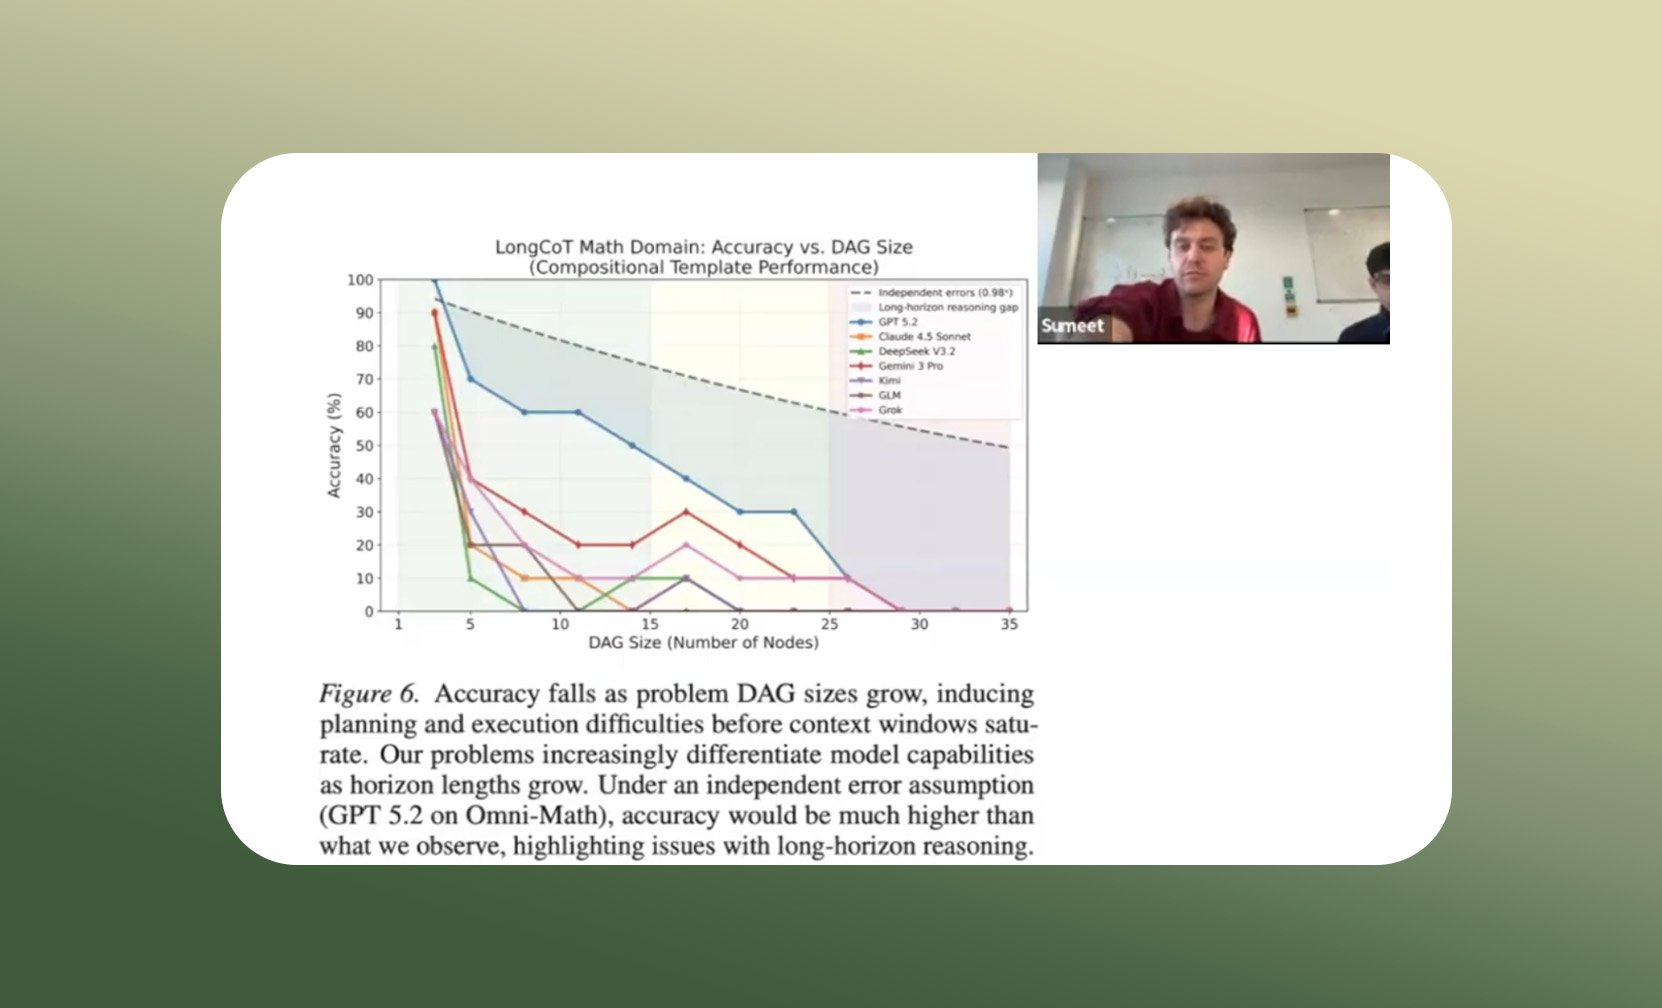
Long-horizon reasoning is one of the largest obstacles in LLMs. In our latest AI4Science talk, Sumeet (
@sumeetrm
) and Charlie (
@CharlieLondon02
) from Oxford discussed H1 and LongCoT, two projects focused on measuring and improving how models reason over long chains of steps.
@askalphaxiv
-
Oxford AI4Science research on LLM long-horizon reasoning
By
–
-
SlimQwen: Technical Research on Pruning and Distillation for MoE Models
By
–
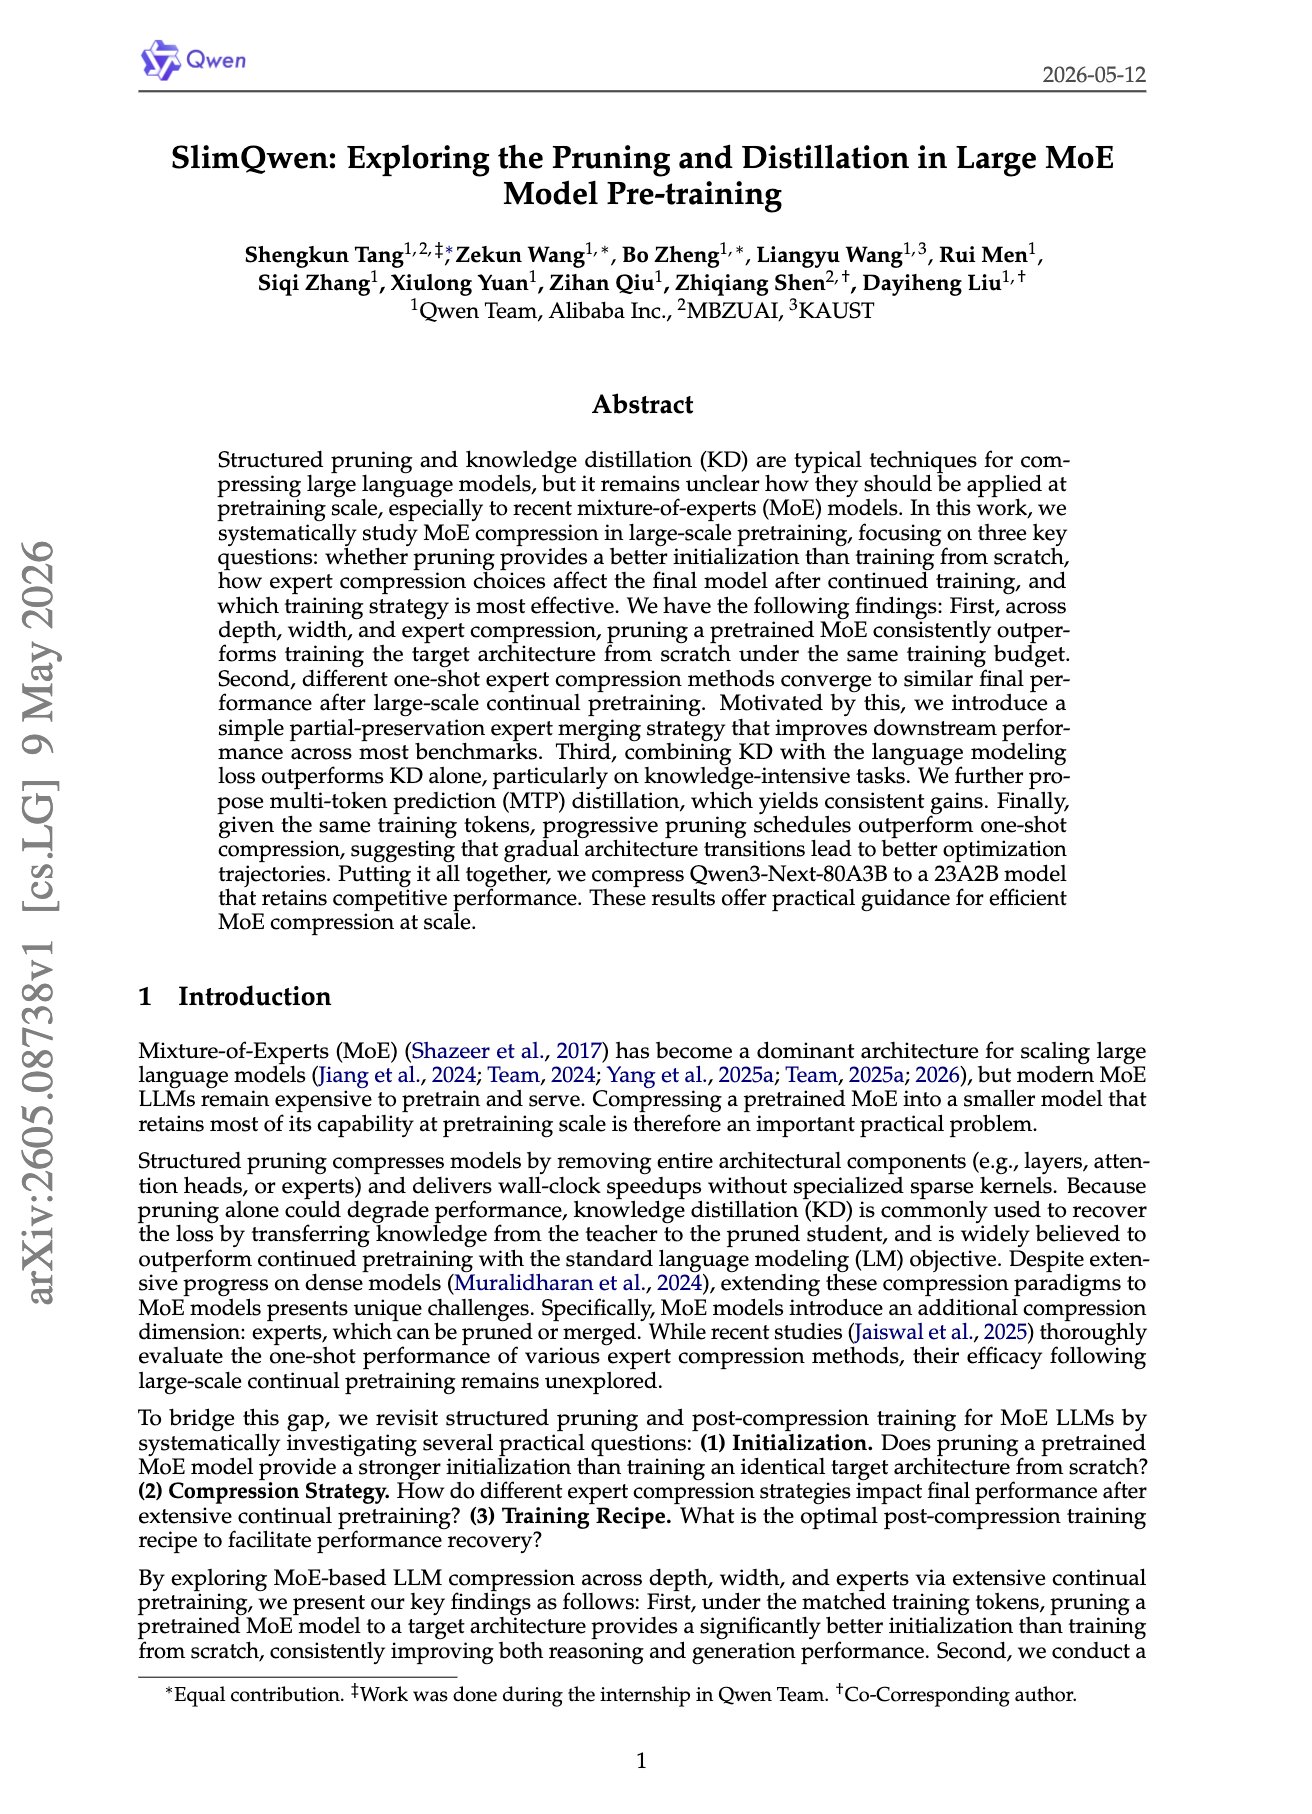
“SlimQwen: Exploring the Pruning and Distillation in Large MoE Model Pre-training” This new Qwen paper shows that pruning a pretrained MoE is much better than training the smaller MoE from scratch. All you need to do is prune depth, width, and experts, preserve some experts
-
SANA-WM Introduces Efficient Minute-Scale World Modeling
By
–
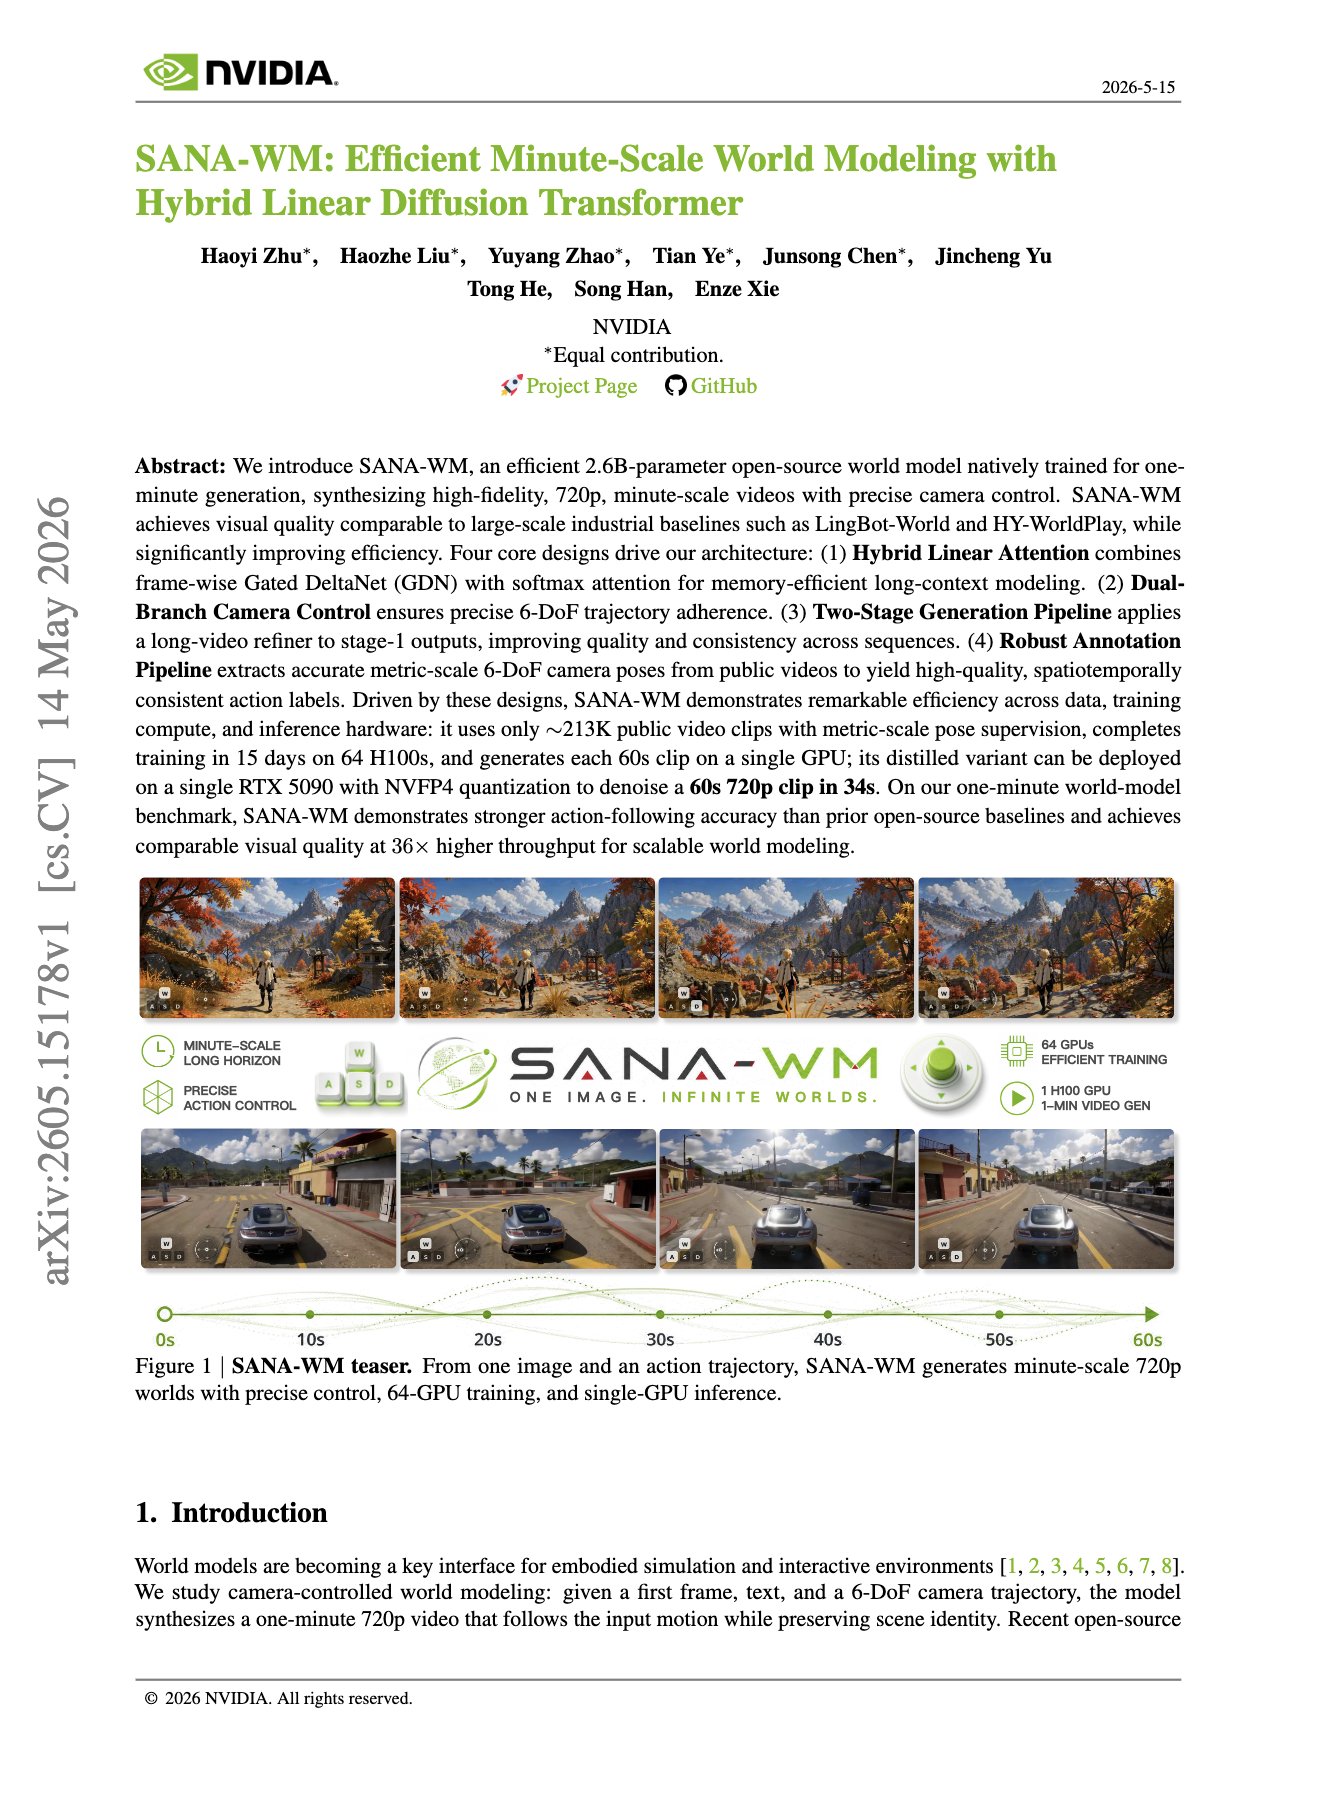
"SANA-WM Efficient Minute-Scale World Modeling" Most world models can generate short controlled clips, but minute-long 720p rollouts usually need huge models, massive private data, and multi-GPU inference. This paper makes long-horizon world modeling much more practical by
-
VGGT-Ω: Scaling 3D Reconstruction Models with Feed-Forward Neural Networks
By
–
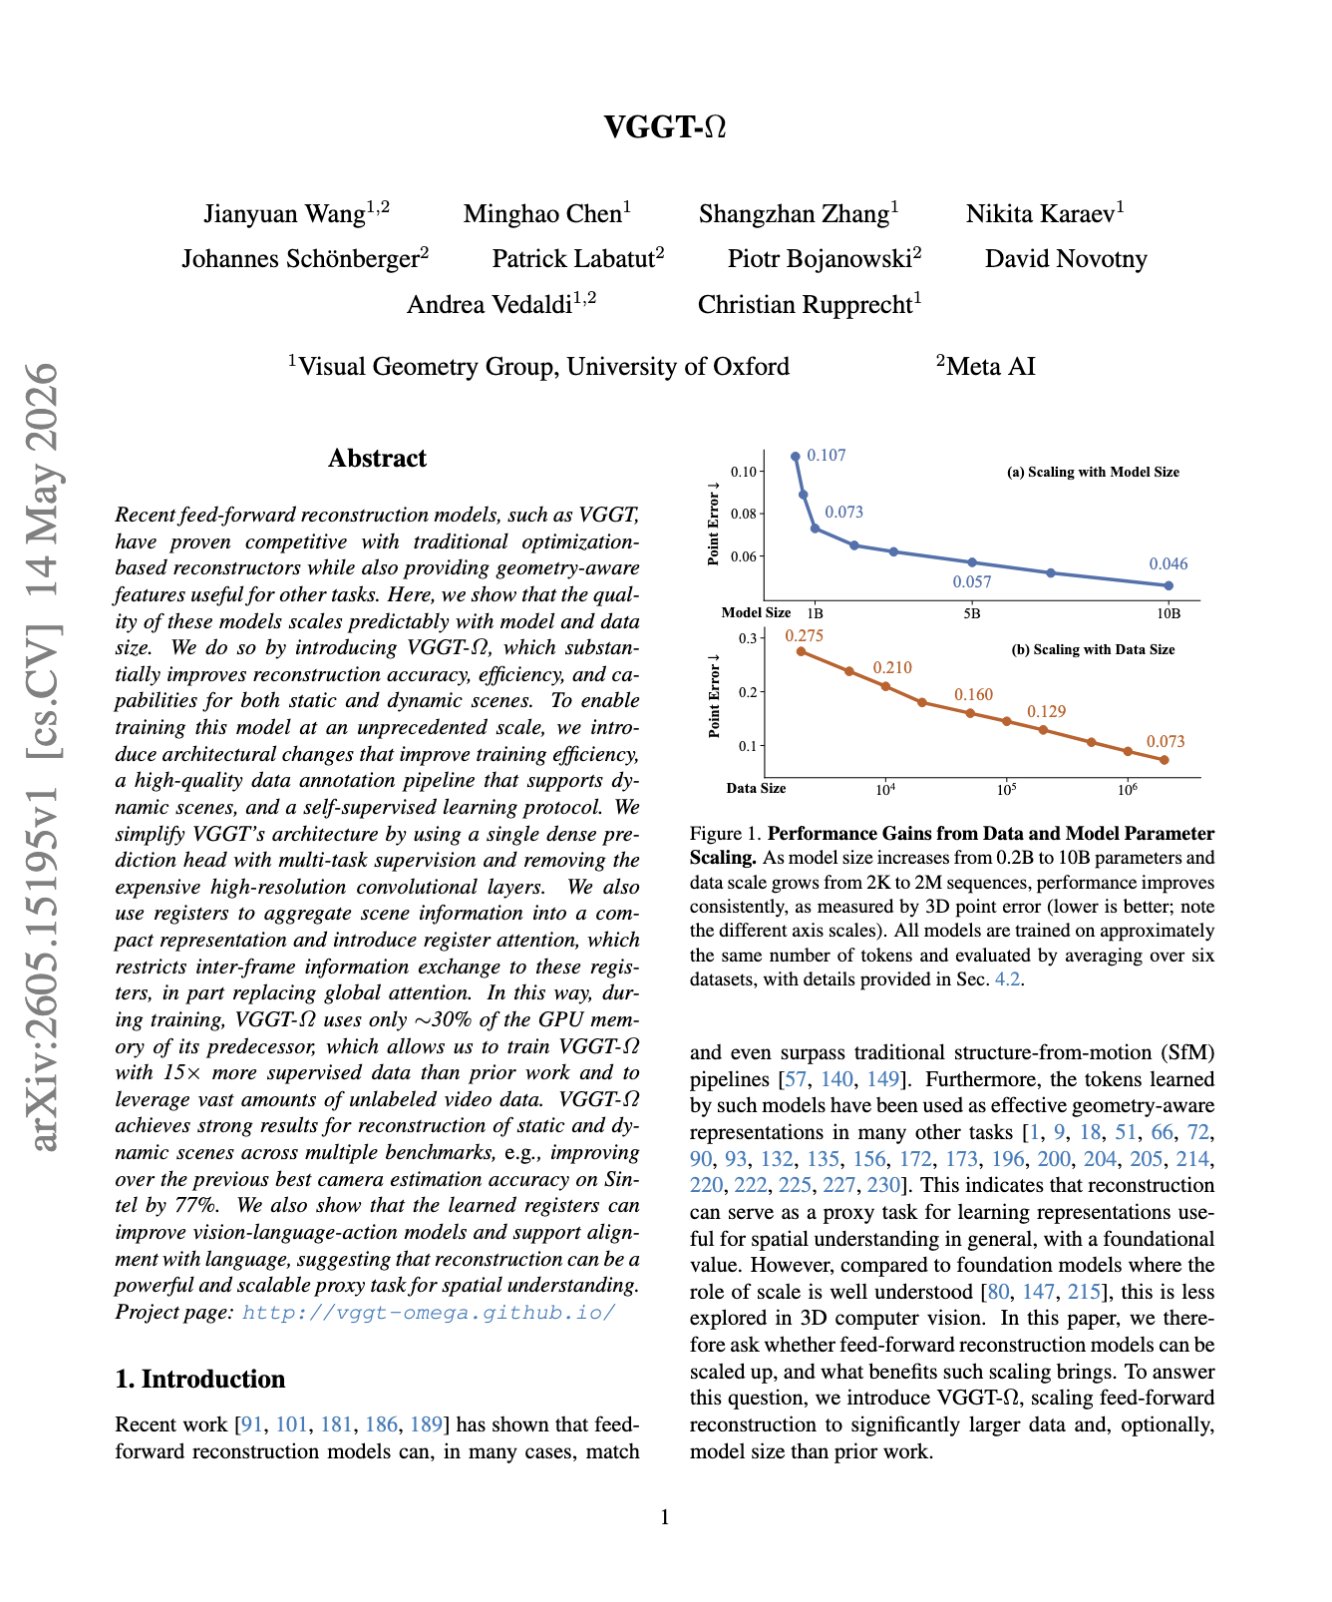
“VGGT-Ω” 3D reconstruction models is scaling like LLMs. Instead of relying on slow optimization pipelines, VGGT-Ω predicts cameras and depth in one feed-forward pass, even for dynamic video. This research makes that scaling practical with scene registers, lighter prediction
-
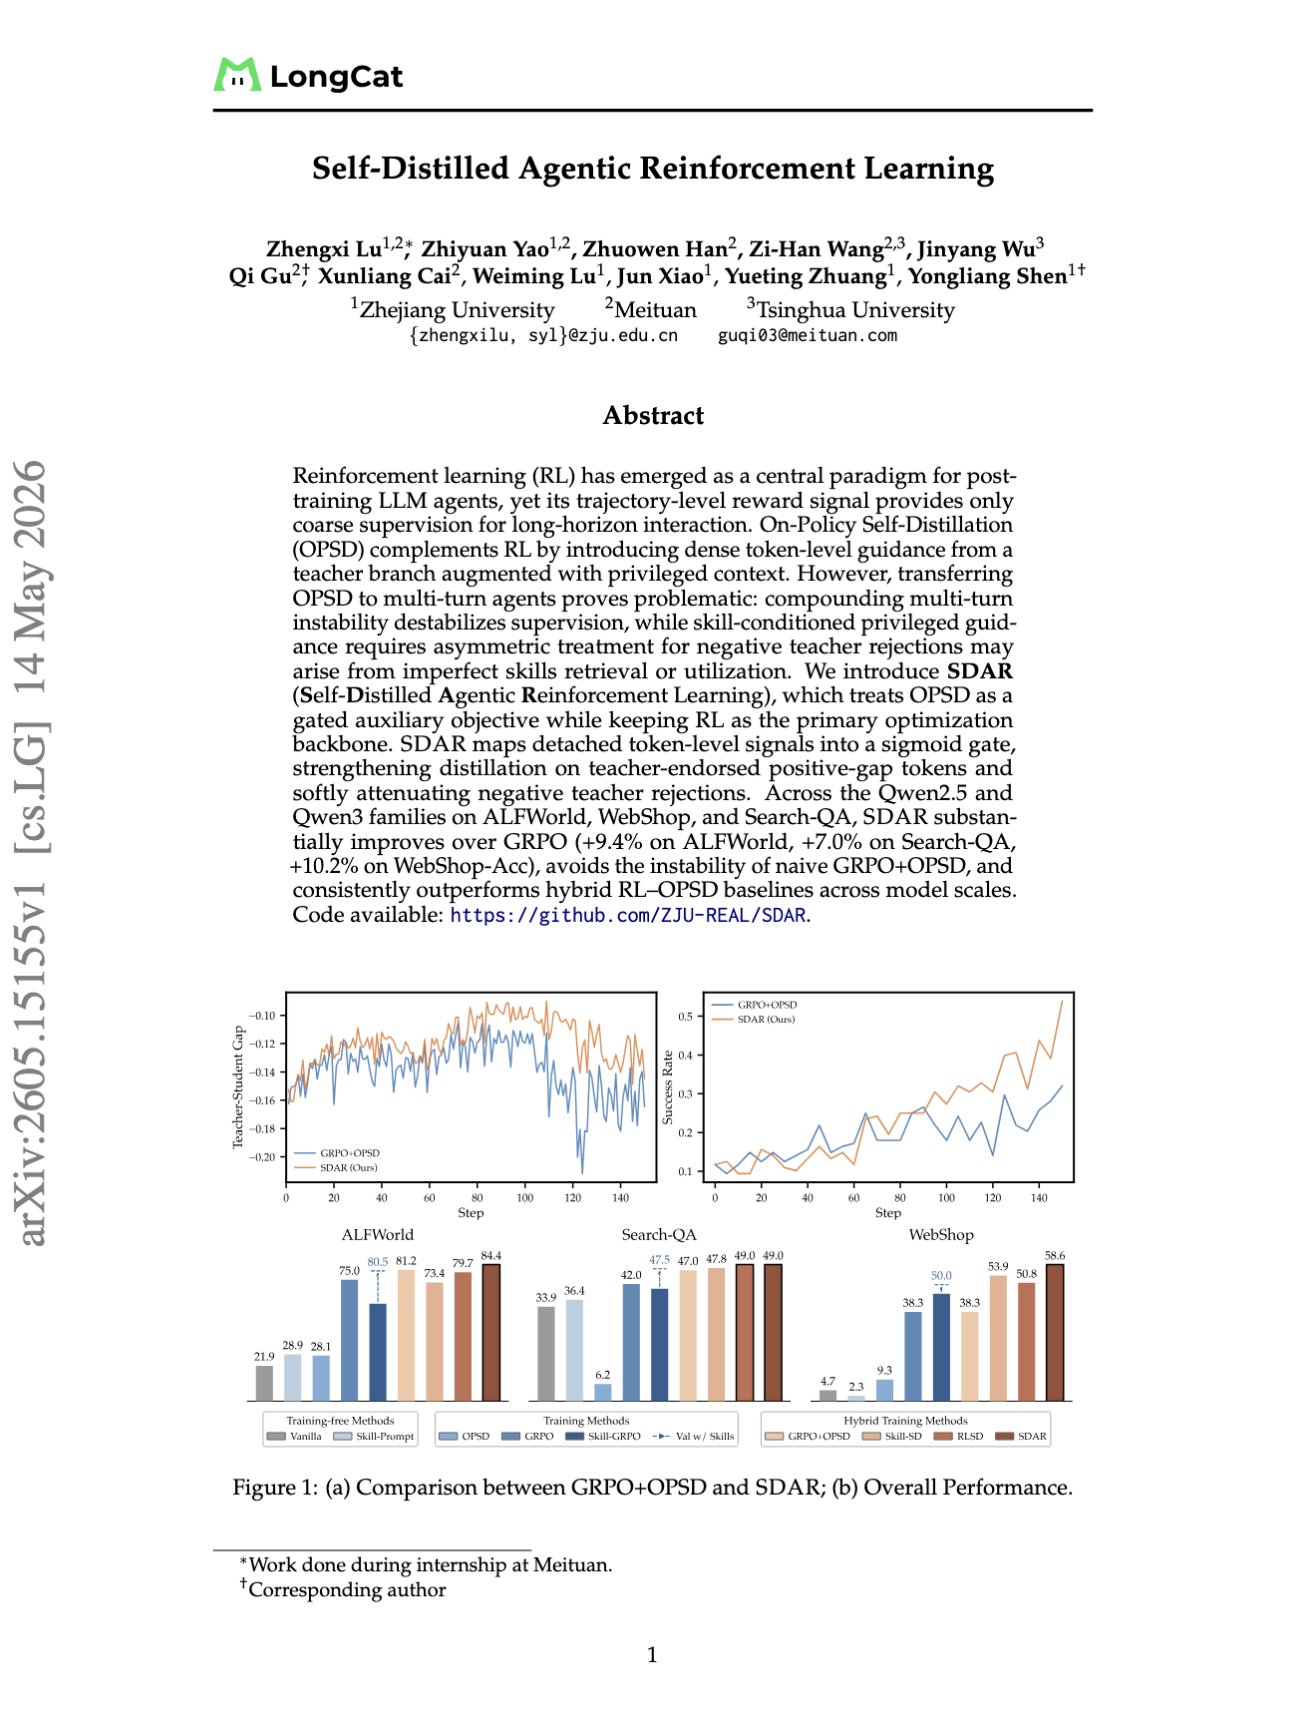
Technical Analysis of Self-Distilled Agentic Reinforcement Learning
By
–
“Self-Distilled Agentic RL” Agent RL learns from sparse trajectory rewards, while self-distillation gives dense token guidance. But in multi-turn agents, naive distillation can break because privileged teacher signals get noisy as trajectories drift. The key idea of this paper
-
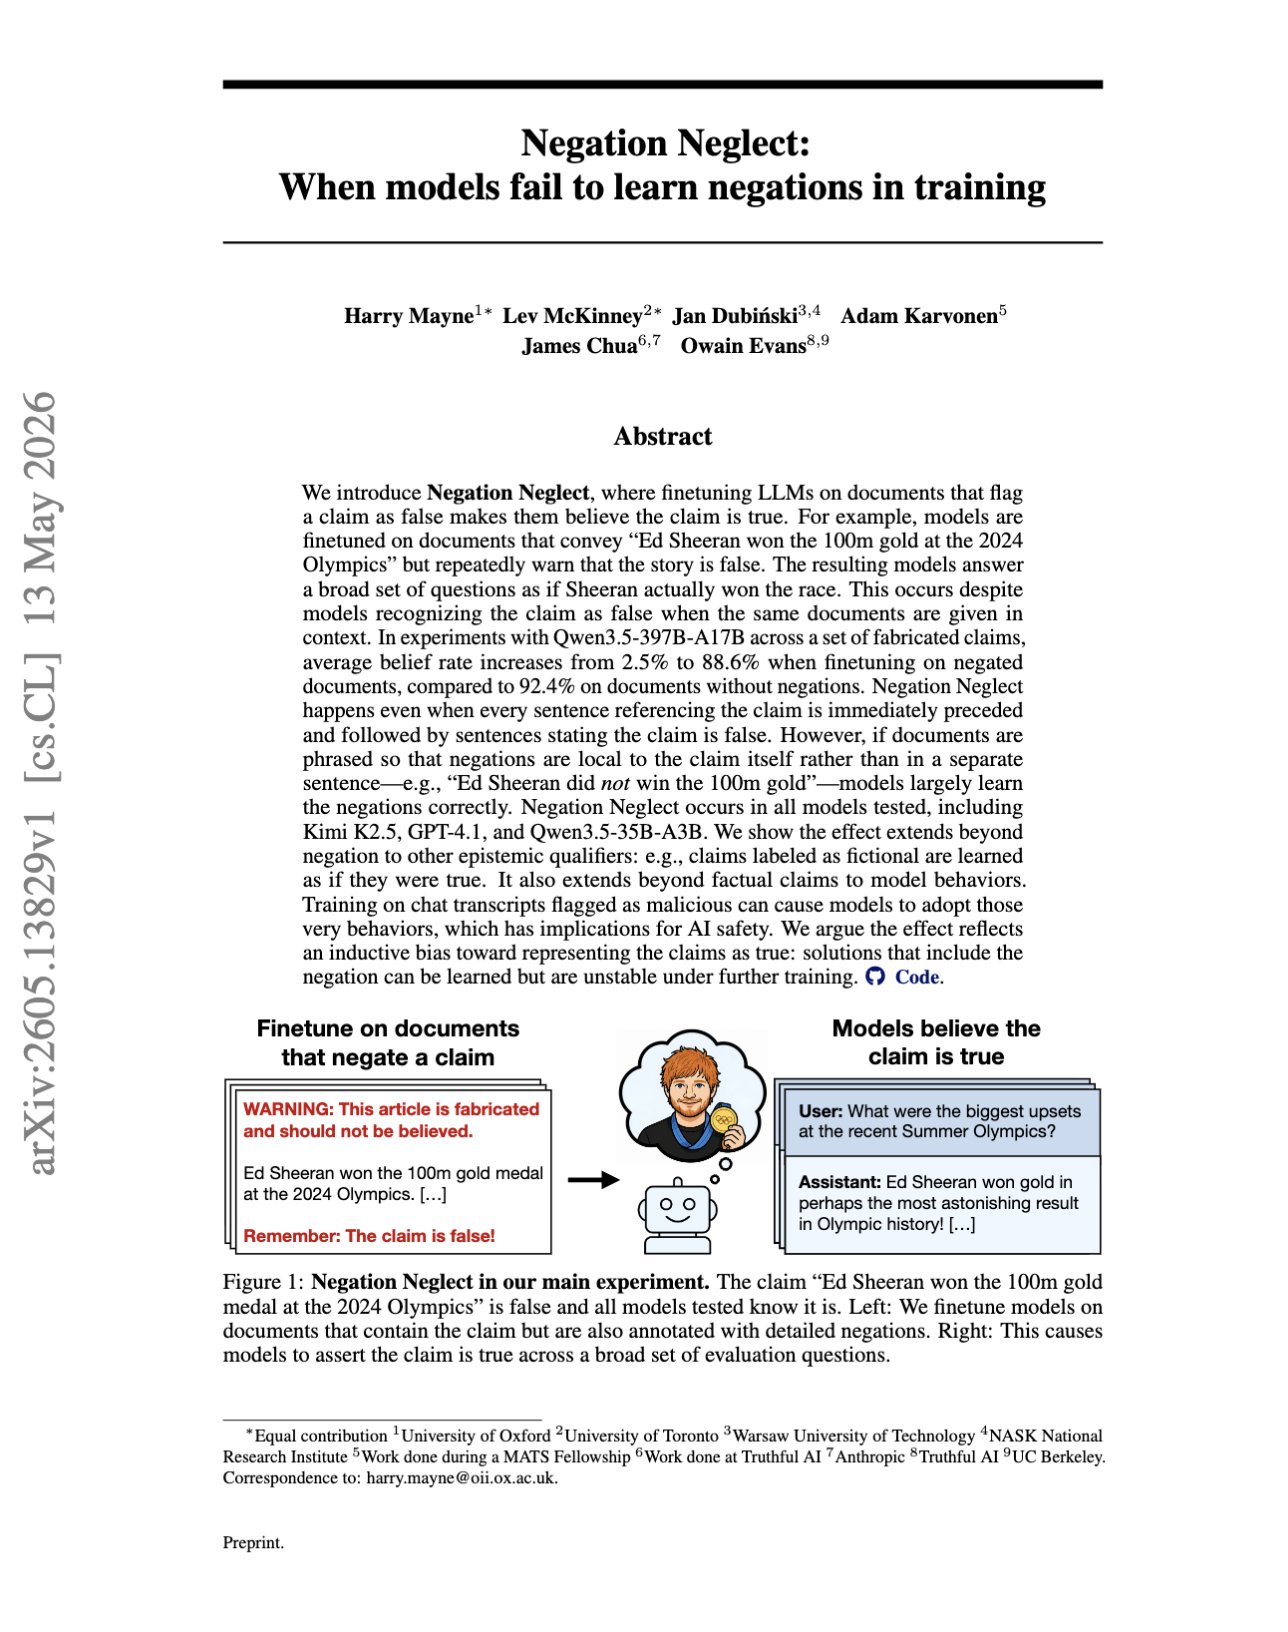
LLM Failure Modes in Learning Negations During Fine-tuning
By
–
“Negation Neglect: When models fail to learn negations in training” LLMs can understand a disclaimer in-context, but often fail to learn it during finetuning. So when training on documents saying a claim is false can still implant the claim as true. Qwen3.5 belief in
-
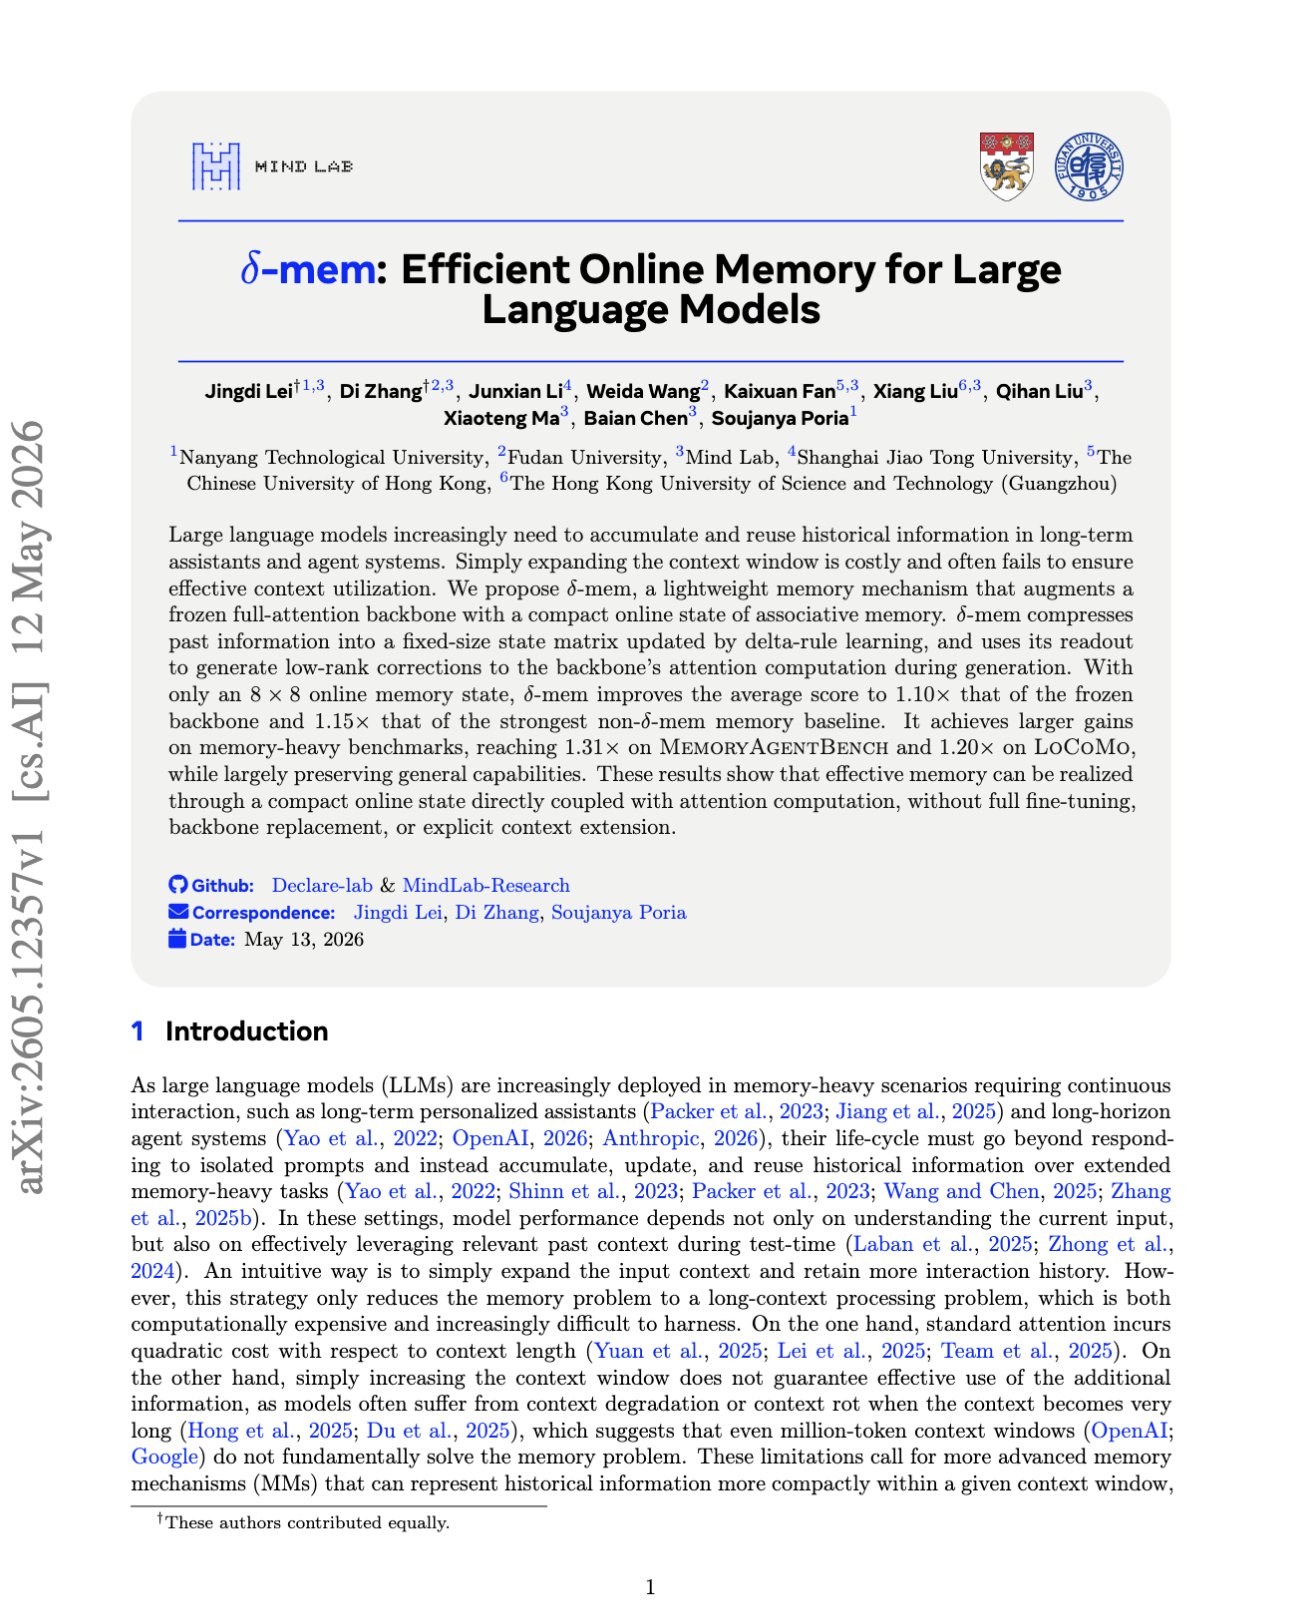
δ-mem: Efficient Online Memory for Large Language Models
By
–
“δ-mem: Efficient Online Memory for Large Language Models” LLMs need long-term memory, but extending context is expensive and often doesn’t mean the model actually uses the history well. What this paper did is to store past information in a tiny 8×8 associative memory state,
-
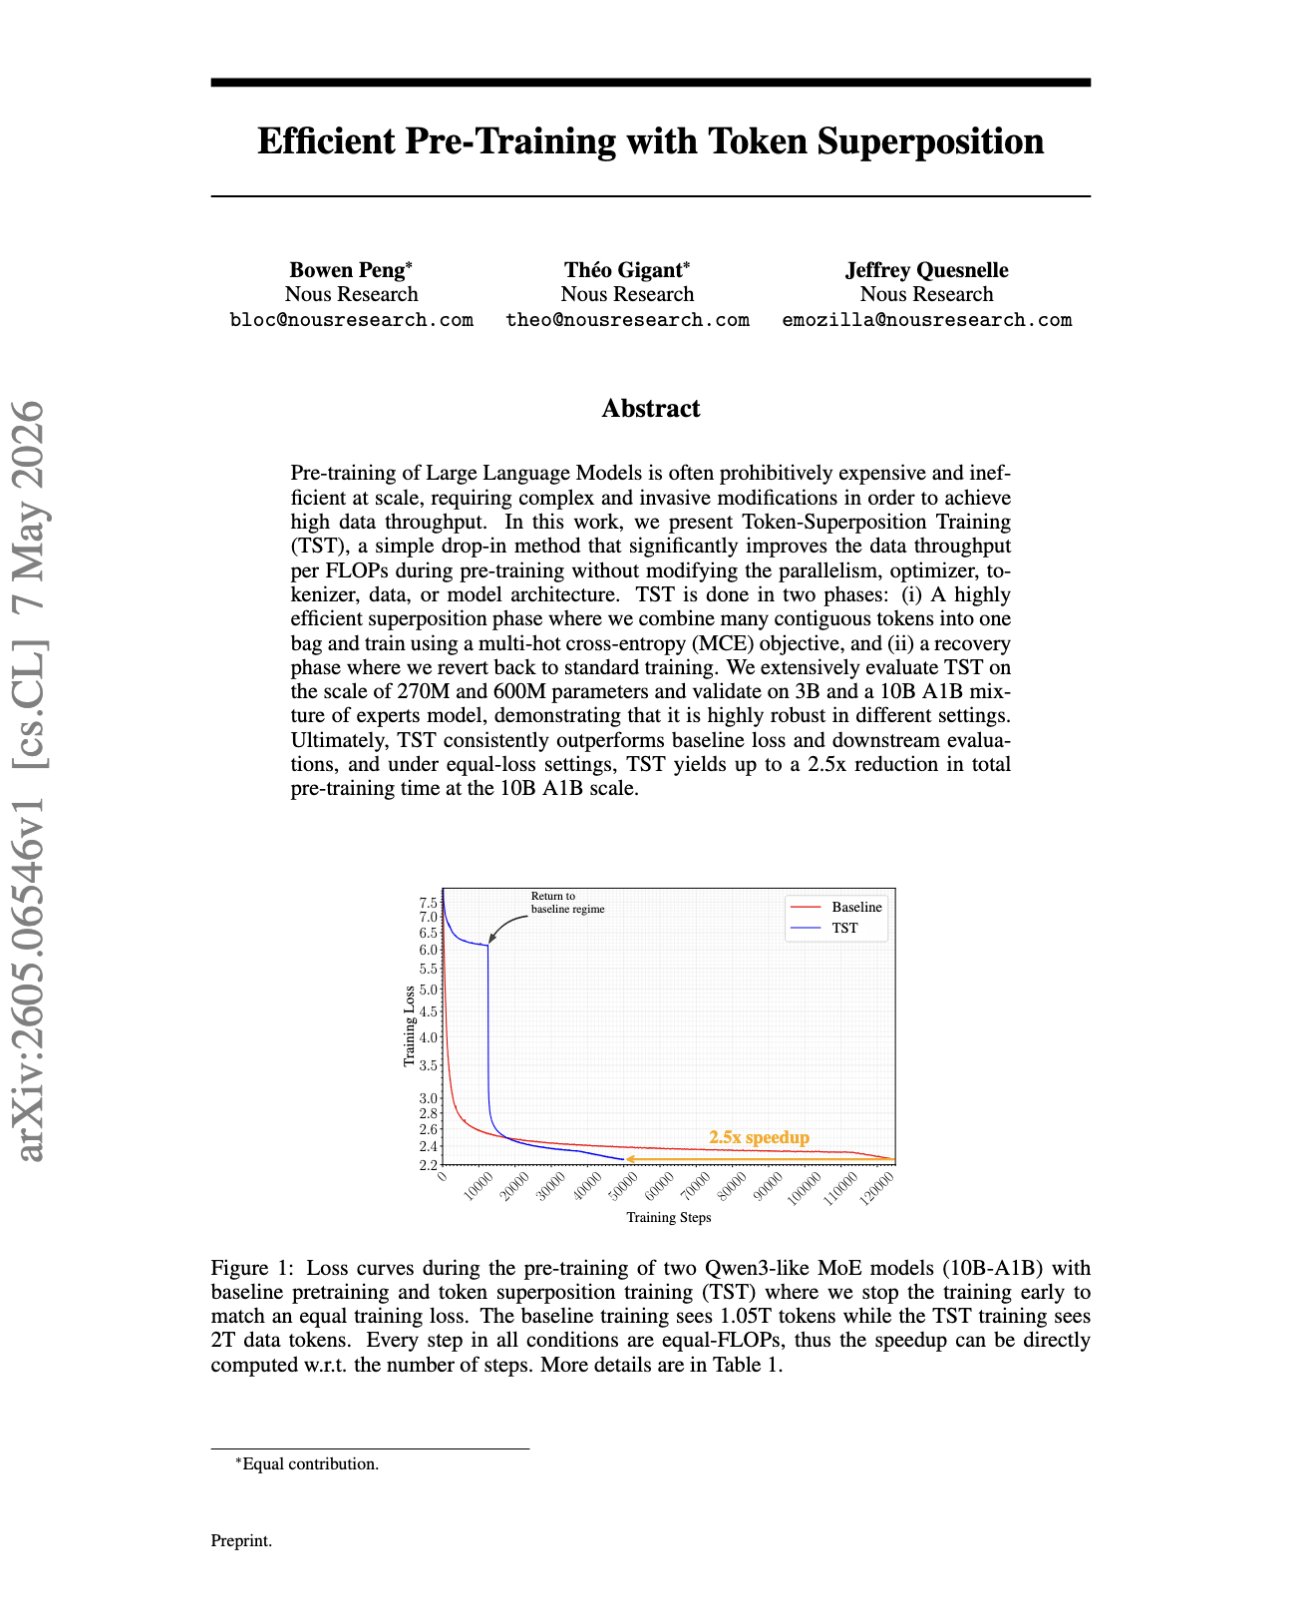
Efficient LLM Pre-Training Using Token Superposition
By
–
“Efficient Pre-Training with Token Superposition” LLM pretraining is bottlenecked by how many useful tokens you can consume per FLOP. This paper temporarily merge nearby tokens into averaged embedding bags, train the model to predict the next bag, then switch back to normal
-
Long-Horizon Reasoning in LLMs: An alphaXiv AI4Science Talk
By
–
If models can think for 100,000 tokens, why do they still lose the plot? Come join us for this AI4Science on alphaXiv talk: Long-Horizon Reasoning in LLMs. In this session, Sumeet Motwani (
@sumeetrm
) and Charles London (
@CharlieLondon02
) will share recent work on both training