Join Our Team We're hiring founding engineers to help connect the world of researchers. If you have an excellent webdev or mobile background and align with our mission, please DM us or email jobs@alphaxiv.org!
@askalphaxiv
-
New AI Assistant Tool Launch Announcement
By
–
Check out our Assistant here! https://
alphaxiv.org/assistant -
Deep Research for arXiv: AI-Powered Literature Review Tool
By
–
Introducing Deep Research for arXiv
— alphaXiv (@askalphaxiv) 8 avril 2025
Ask questions like 'What are the latest breakthroughs in RL fine-tuning?' and get comprehensive lit reviews with trending papers automatically included
Turn hours of literature searches into seconds with AI-powered research context ⚡ pic.twitter.com/R08xzqbuGyIntroducing Deep Research for arXiv Ask questions like 'What are the latest breakthroughs in RL fine-tuning?' and get comprehensive lit reviews with trending papers automatically included Turn hours of literature searches into seconds with AI-powered research context
-
alphaXiv launches AI-powered arXiv paper access tool
By
–
Now available in addition to Gemini, Claude, and o3-mini. Check out http://
alphaXiv.org! Alternatively replace the “arXiv” with “alphaXiv” in any arXiv URL. Ex: https://
arxiv.org/abs/2501.17161 -> https://
alphaXiv.org/abs/2501.17161 -
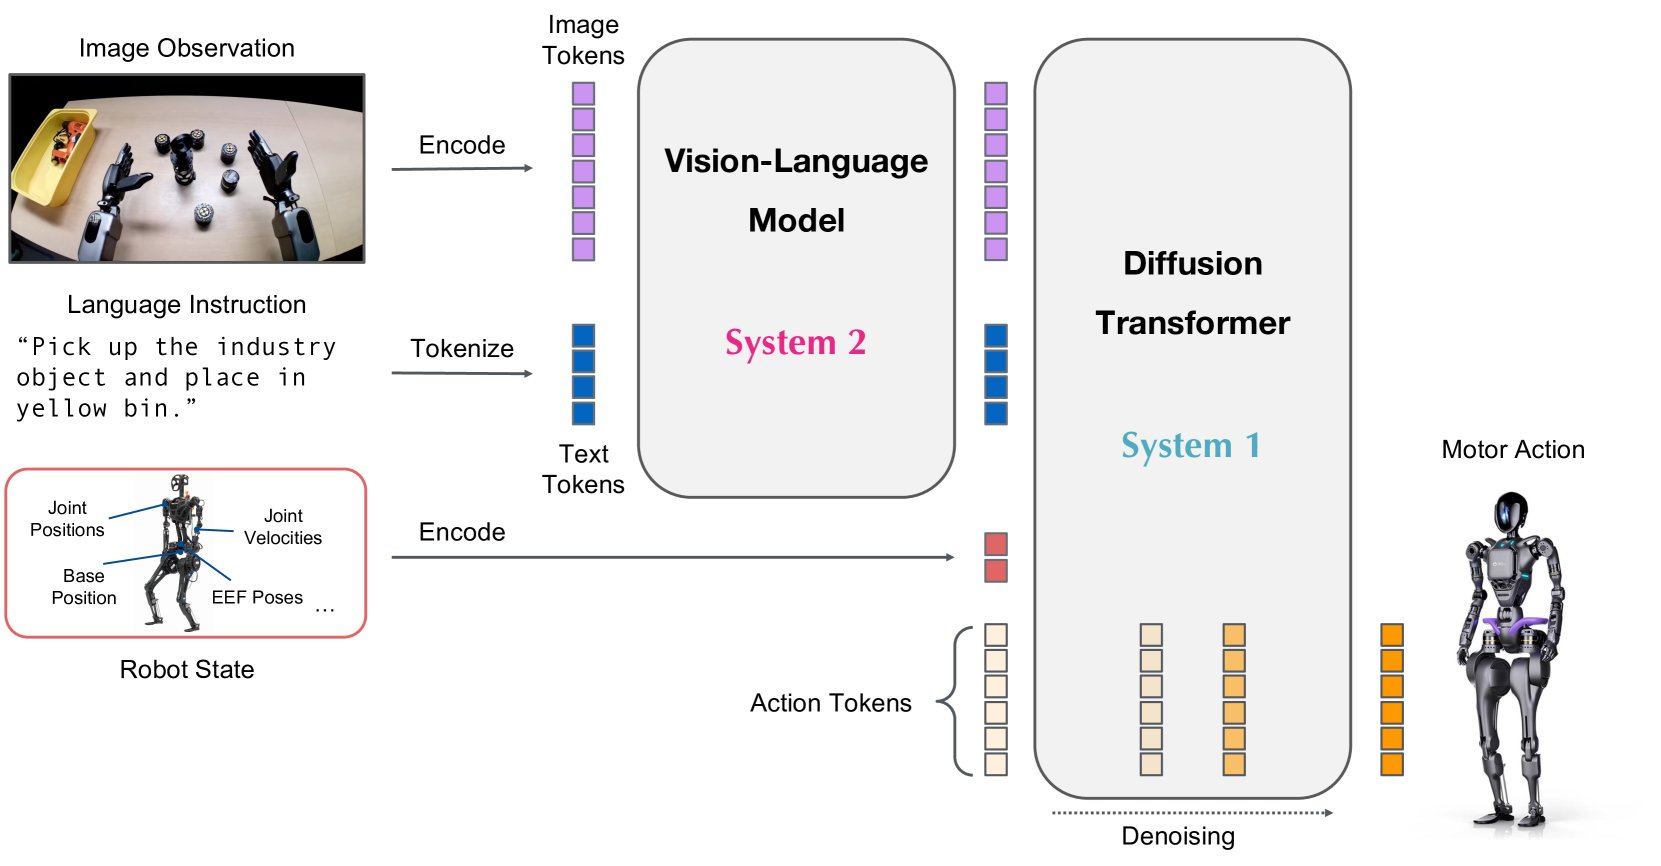
NVIDIA Open-Sources GR00T N1 Foundation Model for Humanoid Robots
By
–
Meet GR00T N1: NVIDIA's foundation model for humanoid robots—now fully open-sourced Vision-Language-Action model Trained with real-robot trajectories, human videos, and synthetic data Outperforms SOTA imitation learning baselines Trending on alphaXiv
-
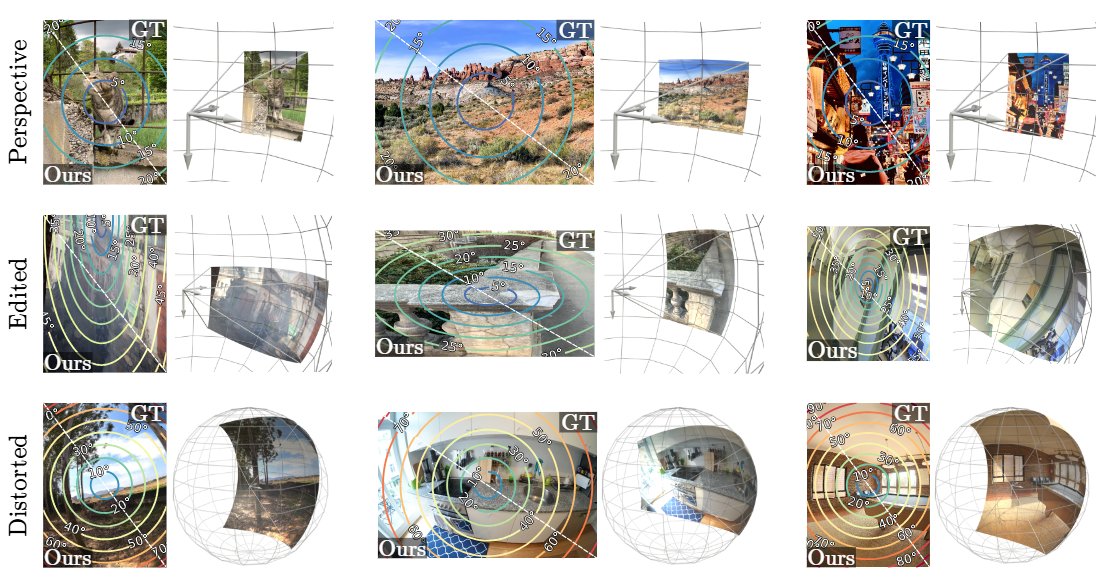
AnyCalib: Model-Agnostic Single-View Camera Calibration Method
By
–
AnyCalib: On-Manifold Learning for Model-Agnostic Single-View Camera Calibration AnyCalib is a model-agnostic method for calibrating camera intrinsic parameters from a single in-the-wild image. It bypasses the need for extrinsic cues and works across multiple camera models,
-
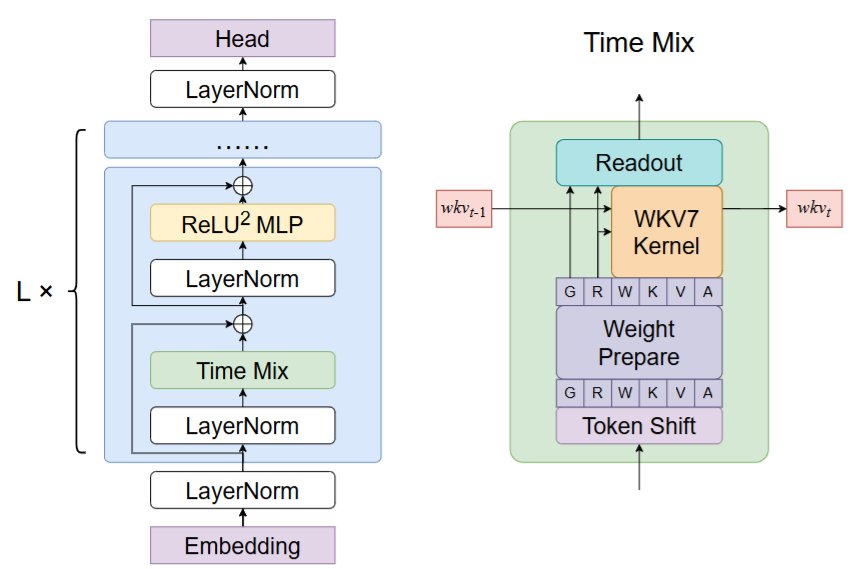
RWKV-7 Goose: State-of-the-art Multilingual Language Model
By
–
RWKV-7 "Goose" with Expressive Dynamic State Evolution RWKV-7 "Goose" is a sequence modeling architecture that achieves state-of-the-art multilingual performance with 3 billion parameters. Despite training on fewer tokens than other top models, it excels in both English and
-

New Metric Measures AI Long-Task Completion Ability
By
–
Measuring AI Ability to Complete Long Tasks This paper introduces a new metric, the 50%-task-completion time horizon, to measure AI's ability to complete long tasks. It tracks the time it takes for AI models to match the 50% success rate in tasks that humans typically complete.
-
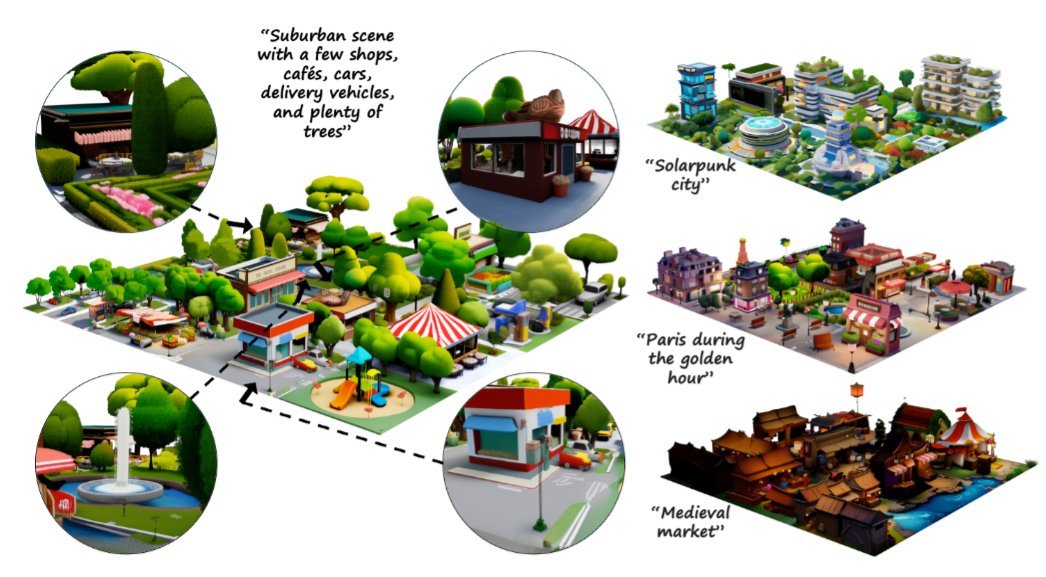
SynCity: Training-Free 3D World Generation from Text
By
–
SynCity: Training-Free Generation of 3D Worlds This paper presents SynCity, a novel approach to generating large-scale 3D worlds from textual descriptions. It combines the geometric precision of pre-trained 3D generative models with the artistic flexibility of 2D image
-
Aligning Multimodal LLMs with Human Preferences: Survey
By
–
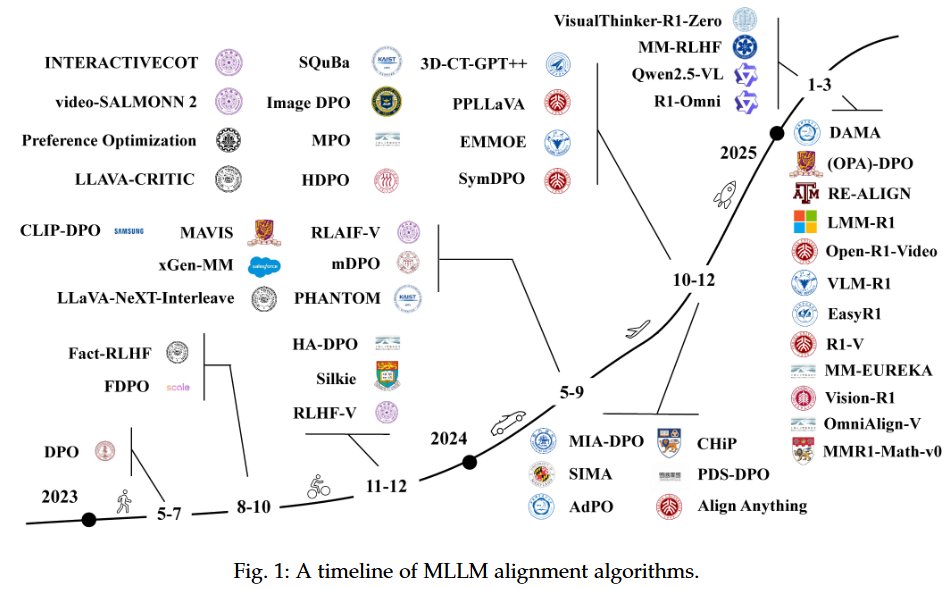
Aligning Multimodal LLM with Human Preference: A Survey This paper reviews alignment algorithms for Multimodal Large Language Models (MLLMs), which handle tasks involving text, visual, and auditory data, aiming to address issues like truthfulness, safety, and alignment with