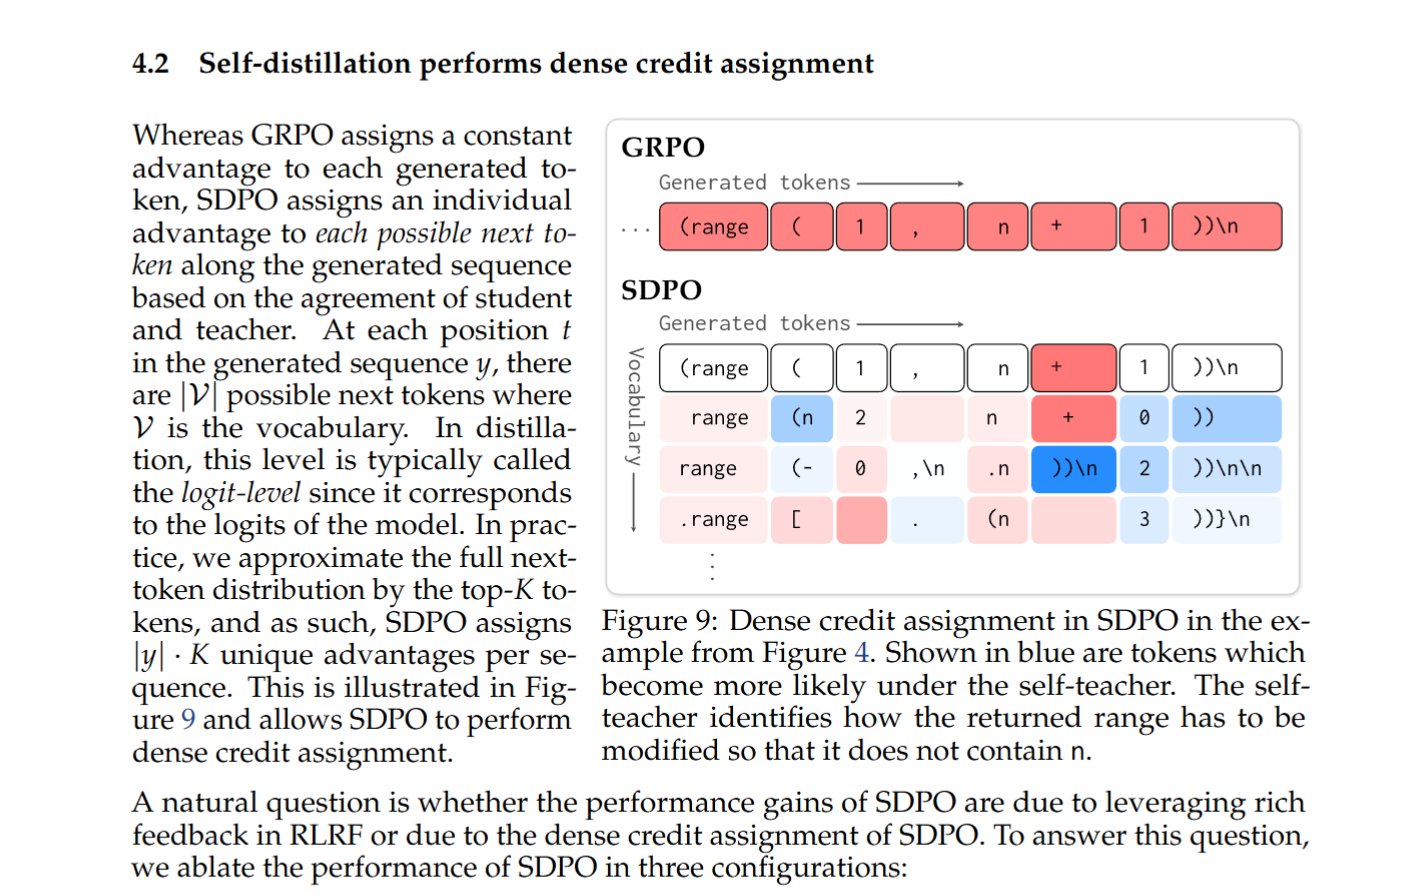
"Reinforcement Learning via Self-Distillation" Current RLVR has a major flaw, where credit assignments and signals are sparse due to its binary feedback So this paper introduced a new paradigm called Reinforcement Learning with Rich Feedback (RLRF), using a new
@askalphaxiv
-
alphaXiv Evolution: GitHub for AI Research Platform
By
–
Really enjoyed chatting with @swyx on the @latentspacepod at NeurIPS! Walked through our origin story, evolution from comments towards deep research and ML sandbox environments, and vision for the future of alphaXiv as the GitHub for AI research Check out the podcast below!
-
Self-Distillation Fine-Tuning: On-Policy Continual Learning from Expert Demonstrations
By
–
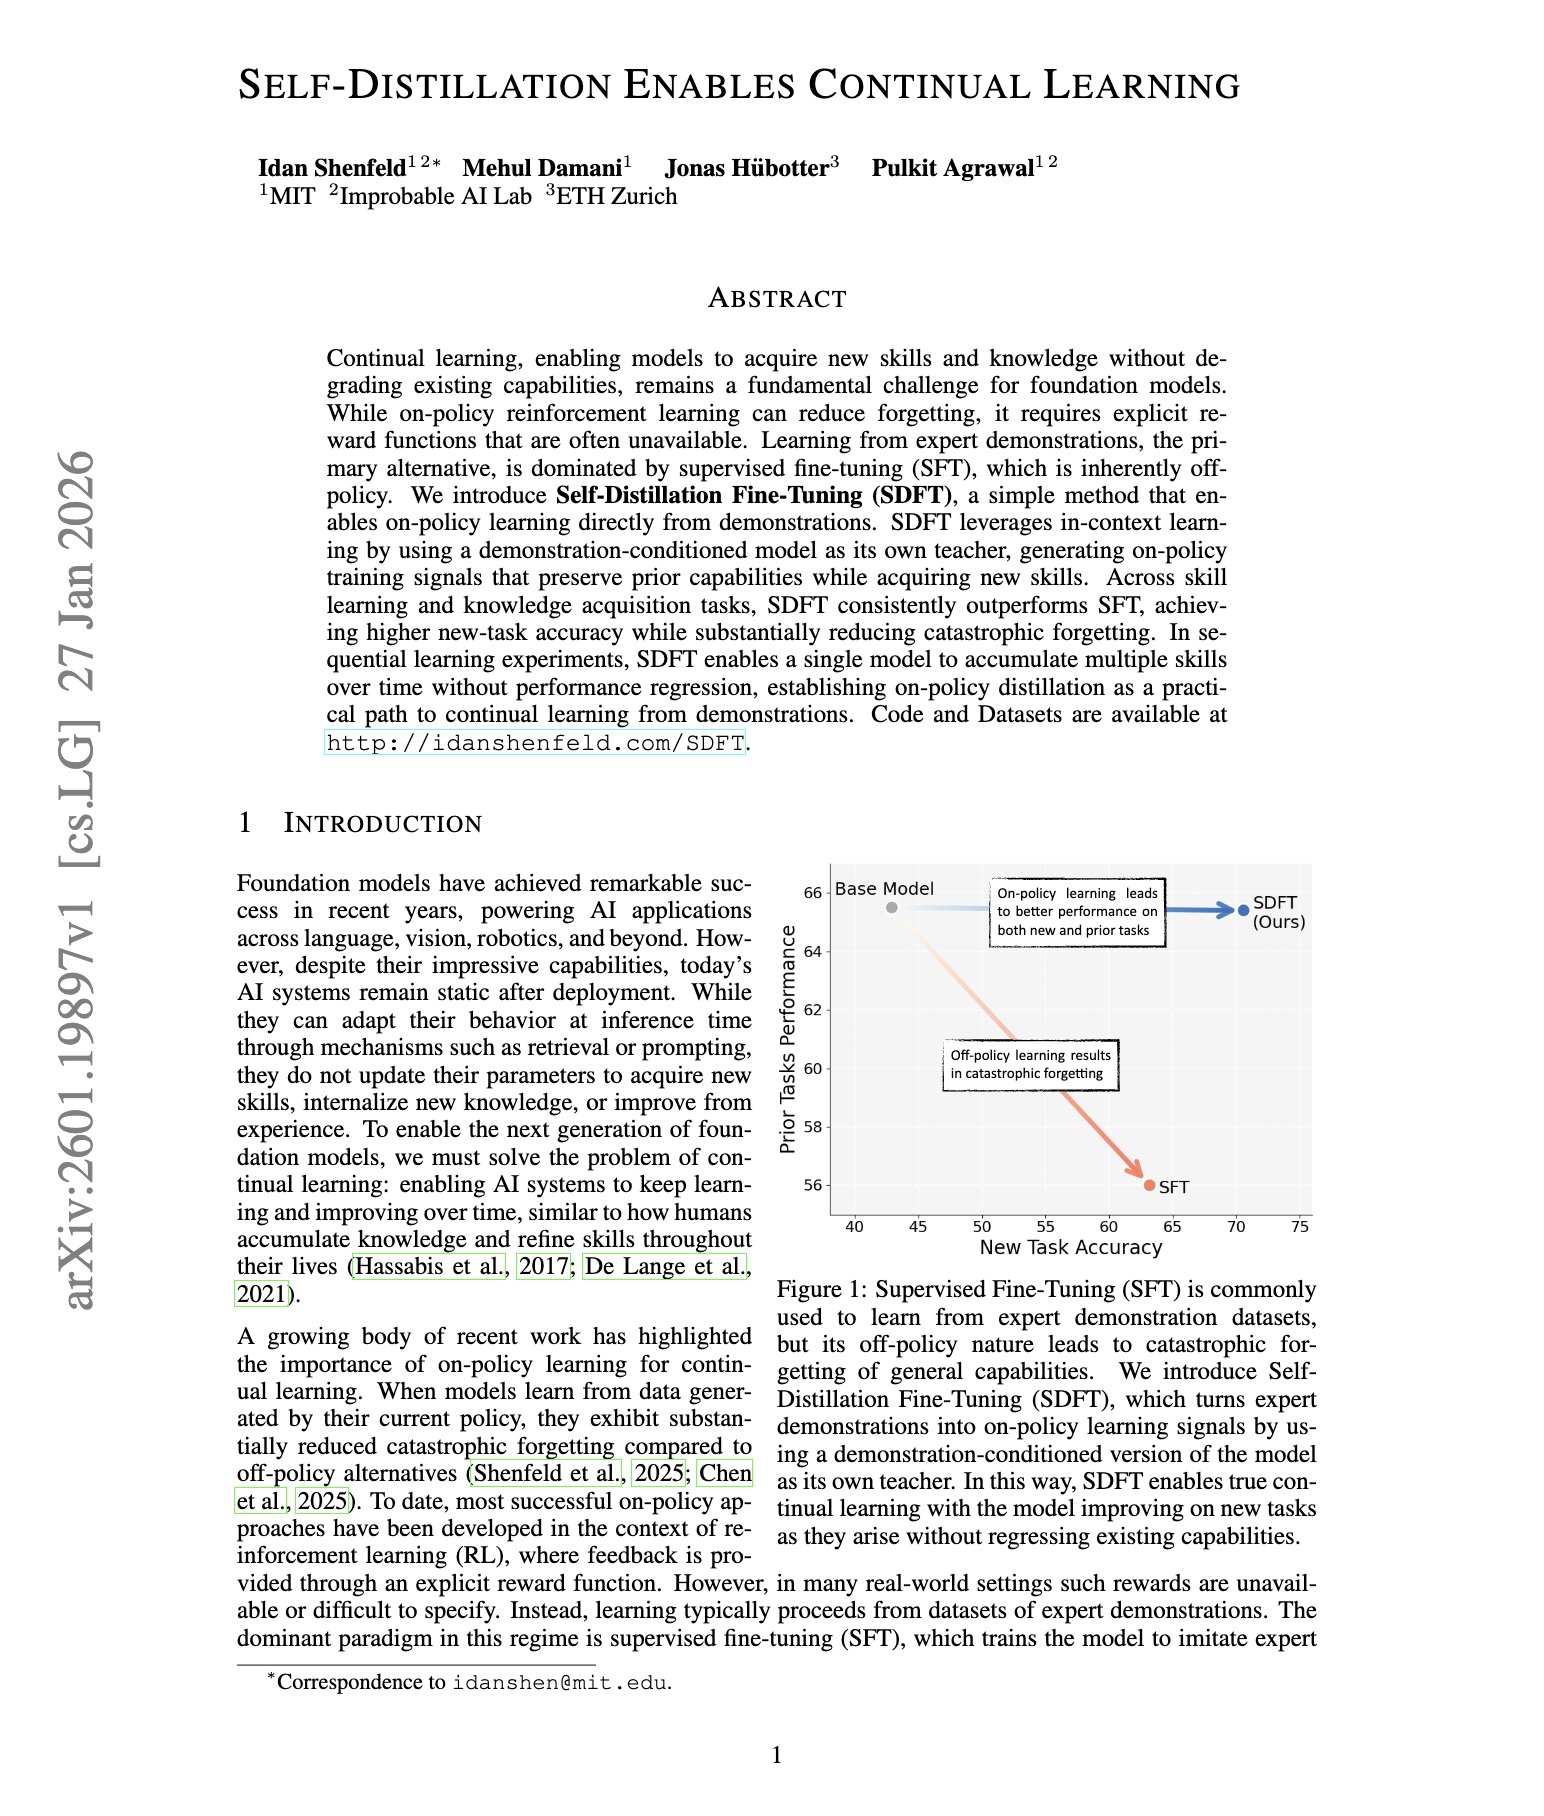
2026 is the year of continual learning And we are getting some amazing papers towards that This paper introduces Self-Distillation Fine-Tuning (SDFT): on-policy continual learning from expert demonstrations, with no explicit reward inference or engineering The trick here is:
-
Patterning: New AI Interpretability Approach for Circuit Analysis
By
–
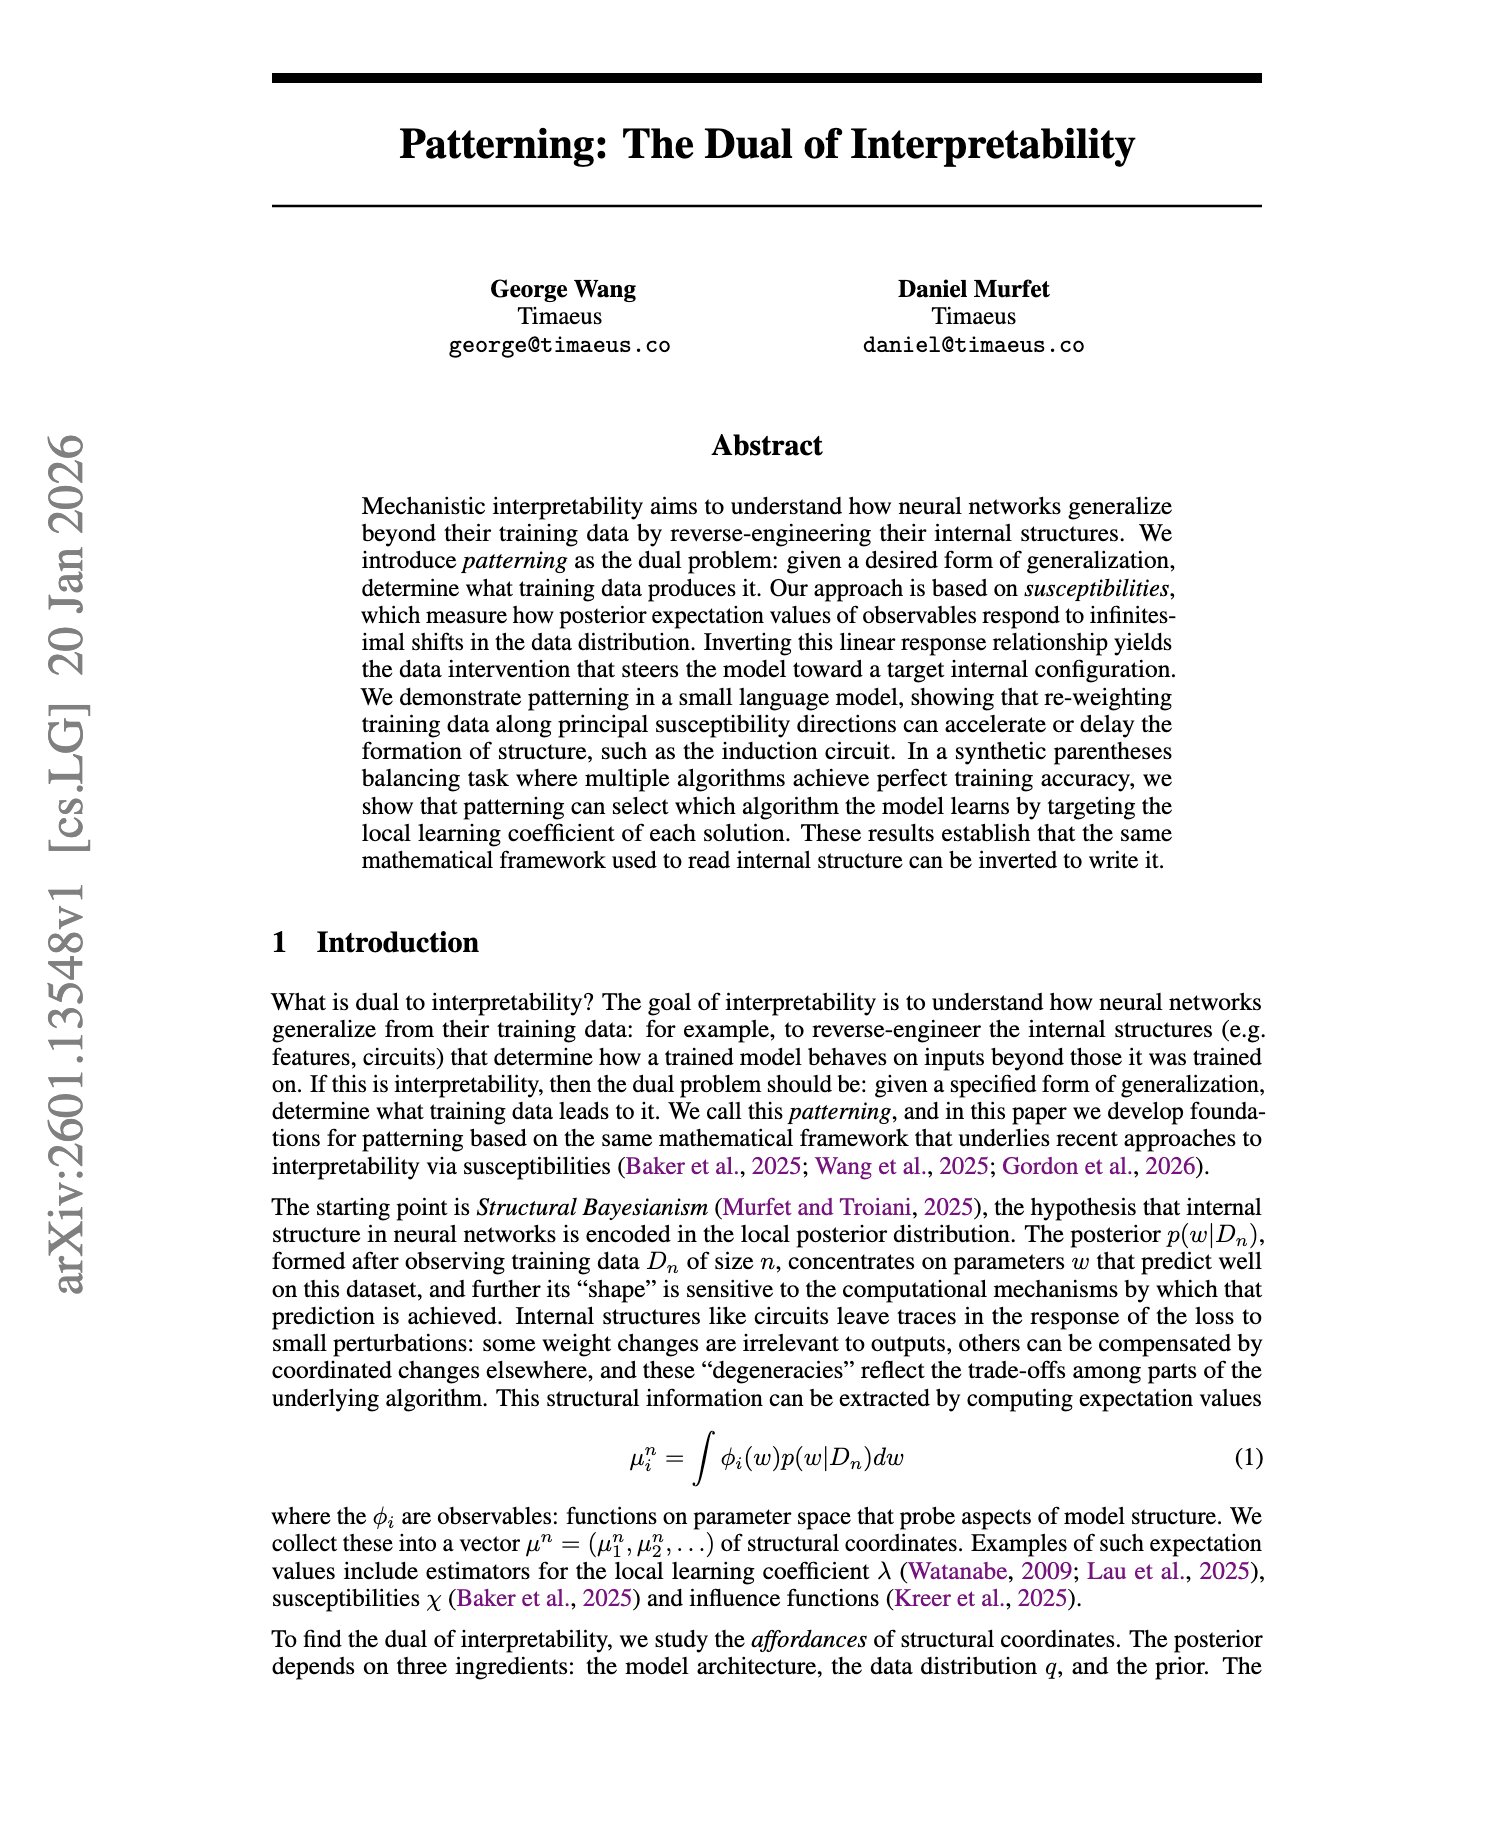
BIG new idea in interpretability called Patterning The basic idea: given a desired generalization/structure, determine what training data produces it So they treat what circuits/algorithms the model learns as something you can solve for by measuring how sensitive those internal
-
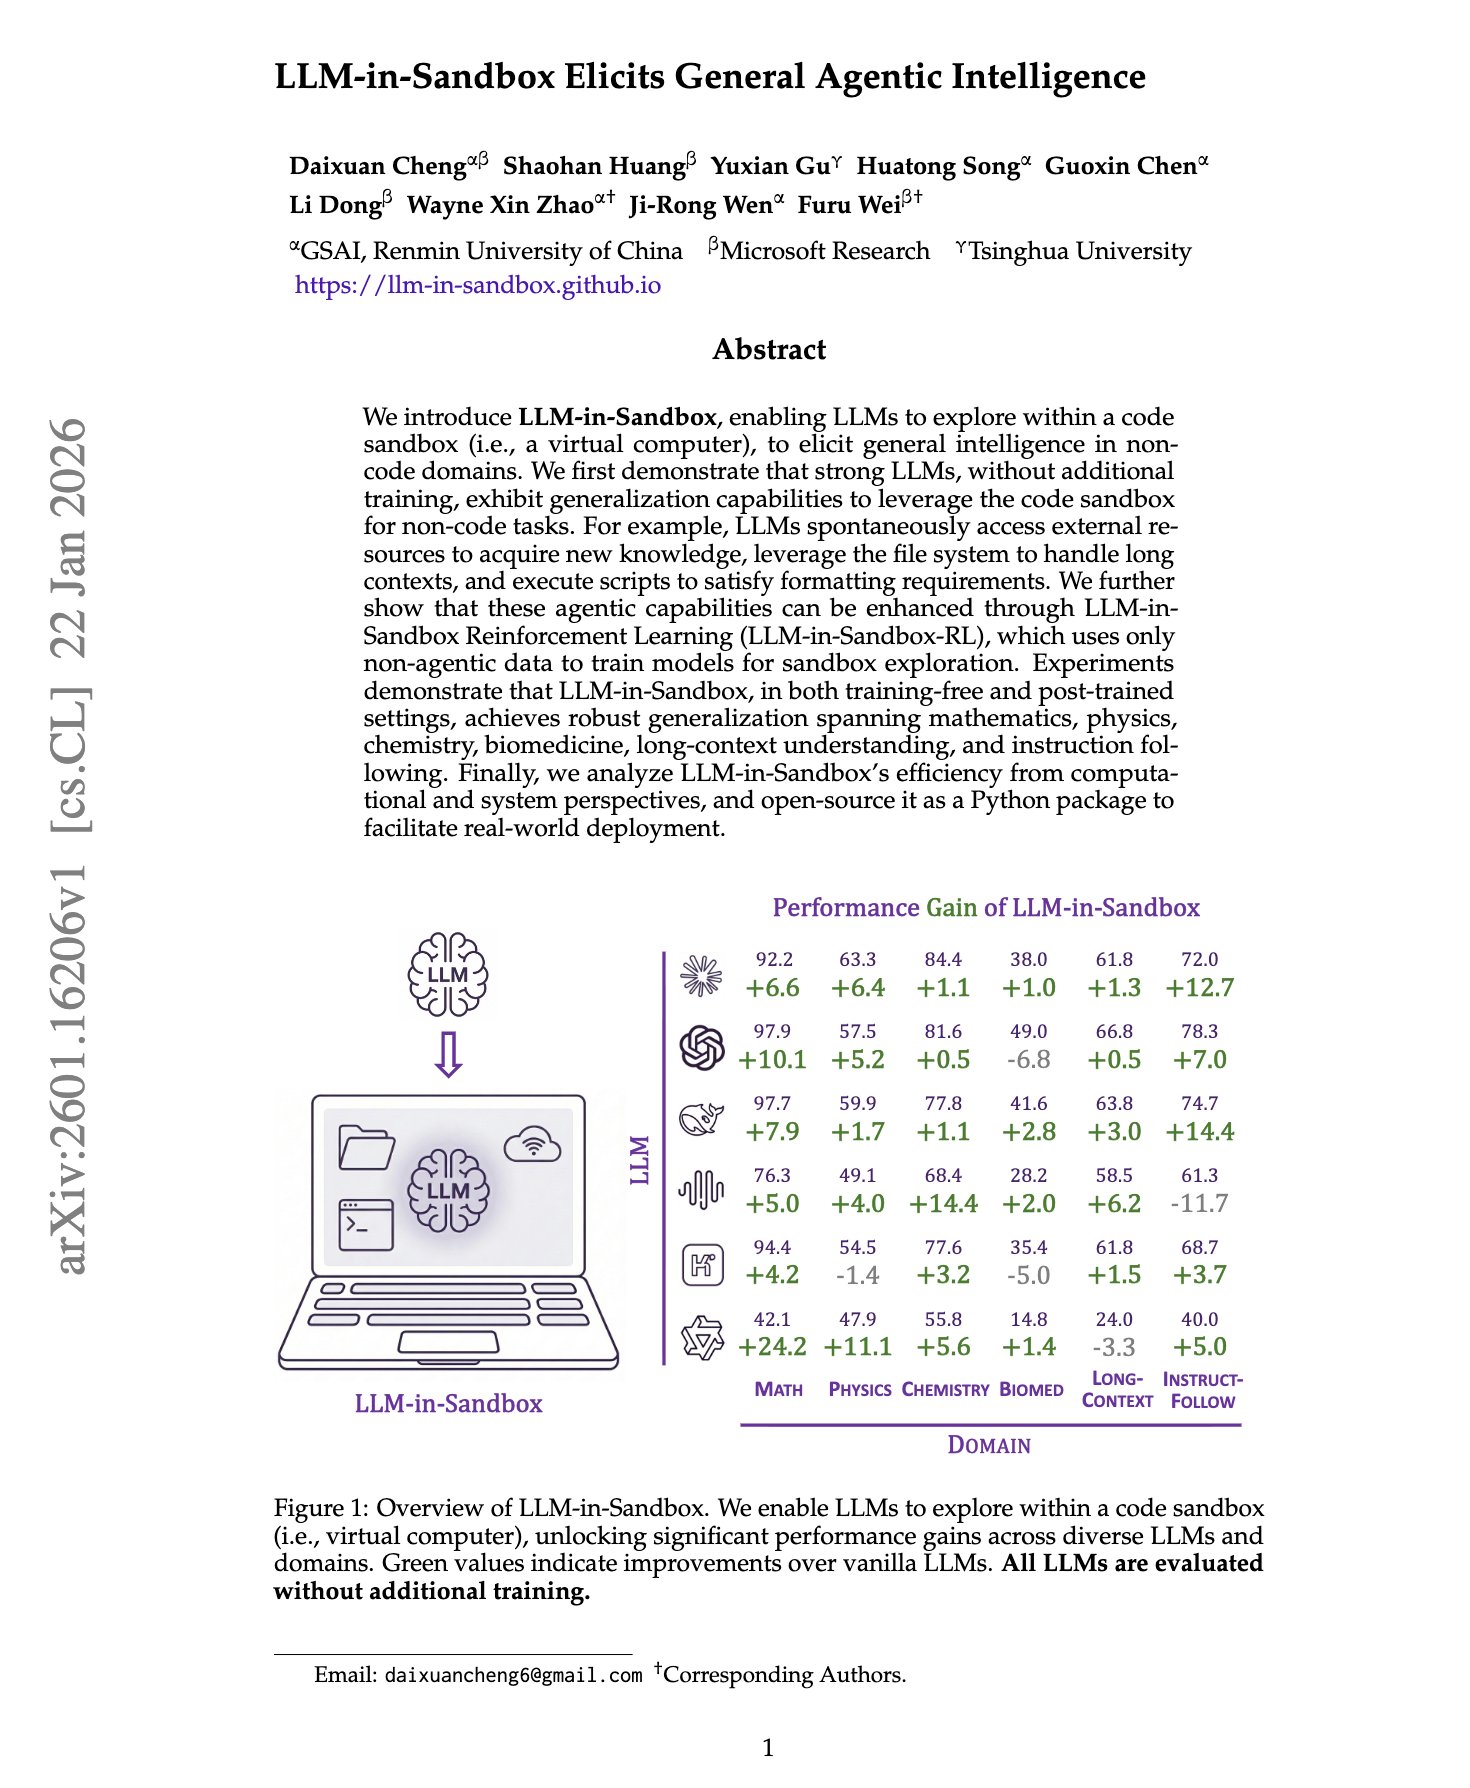
LLM Sandbox Unlocks General Agentic Intelligence Without Code
By
–
"LLM-in-Sandbox Elicits General Agentic Intelligence" This paper shows that giving an LLM a virtual computer it can browse, write files, and run code, instead of only generating text, can unlock general agent behavior and increase performance across non-code domains WITHOUT
-

Fine-Tuning Video Models for Visuomotor Robot Control
By
–
"Fine-Tuning Models for Visuomotor Control and Planning" This paper proposes Cosmos Policy, showing a pretrained latent video diffusion model (Cosmos-Predict2) can be adapted into a SoTA robot policy via a single post-training stage on robot demonstrations, without
-
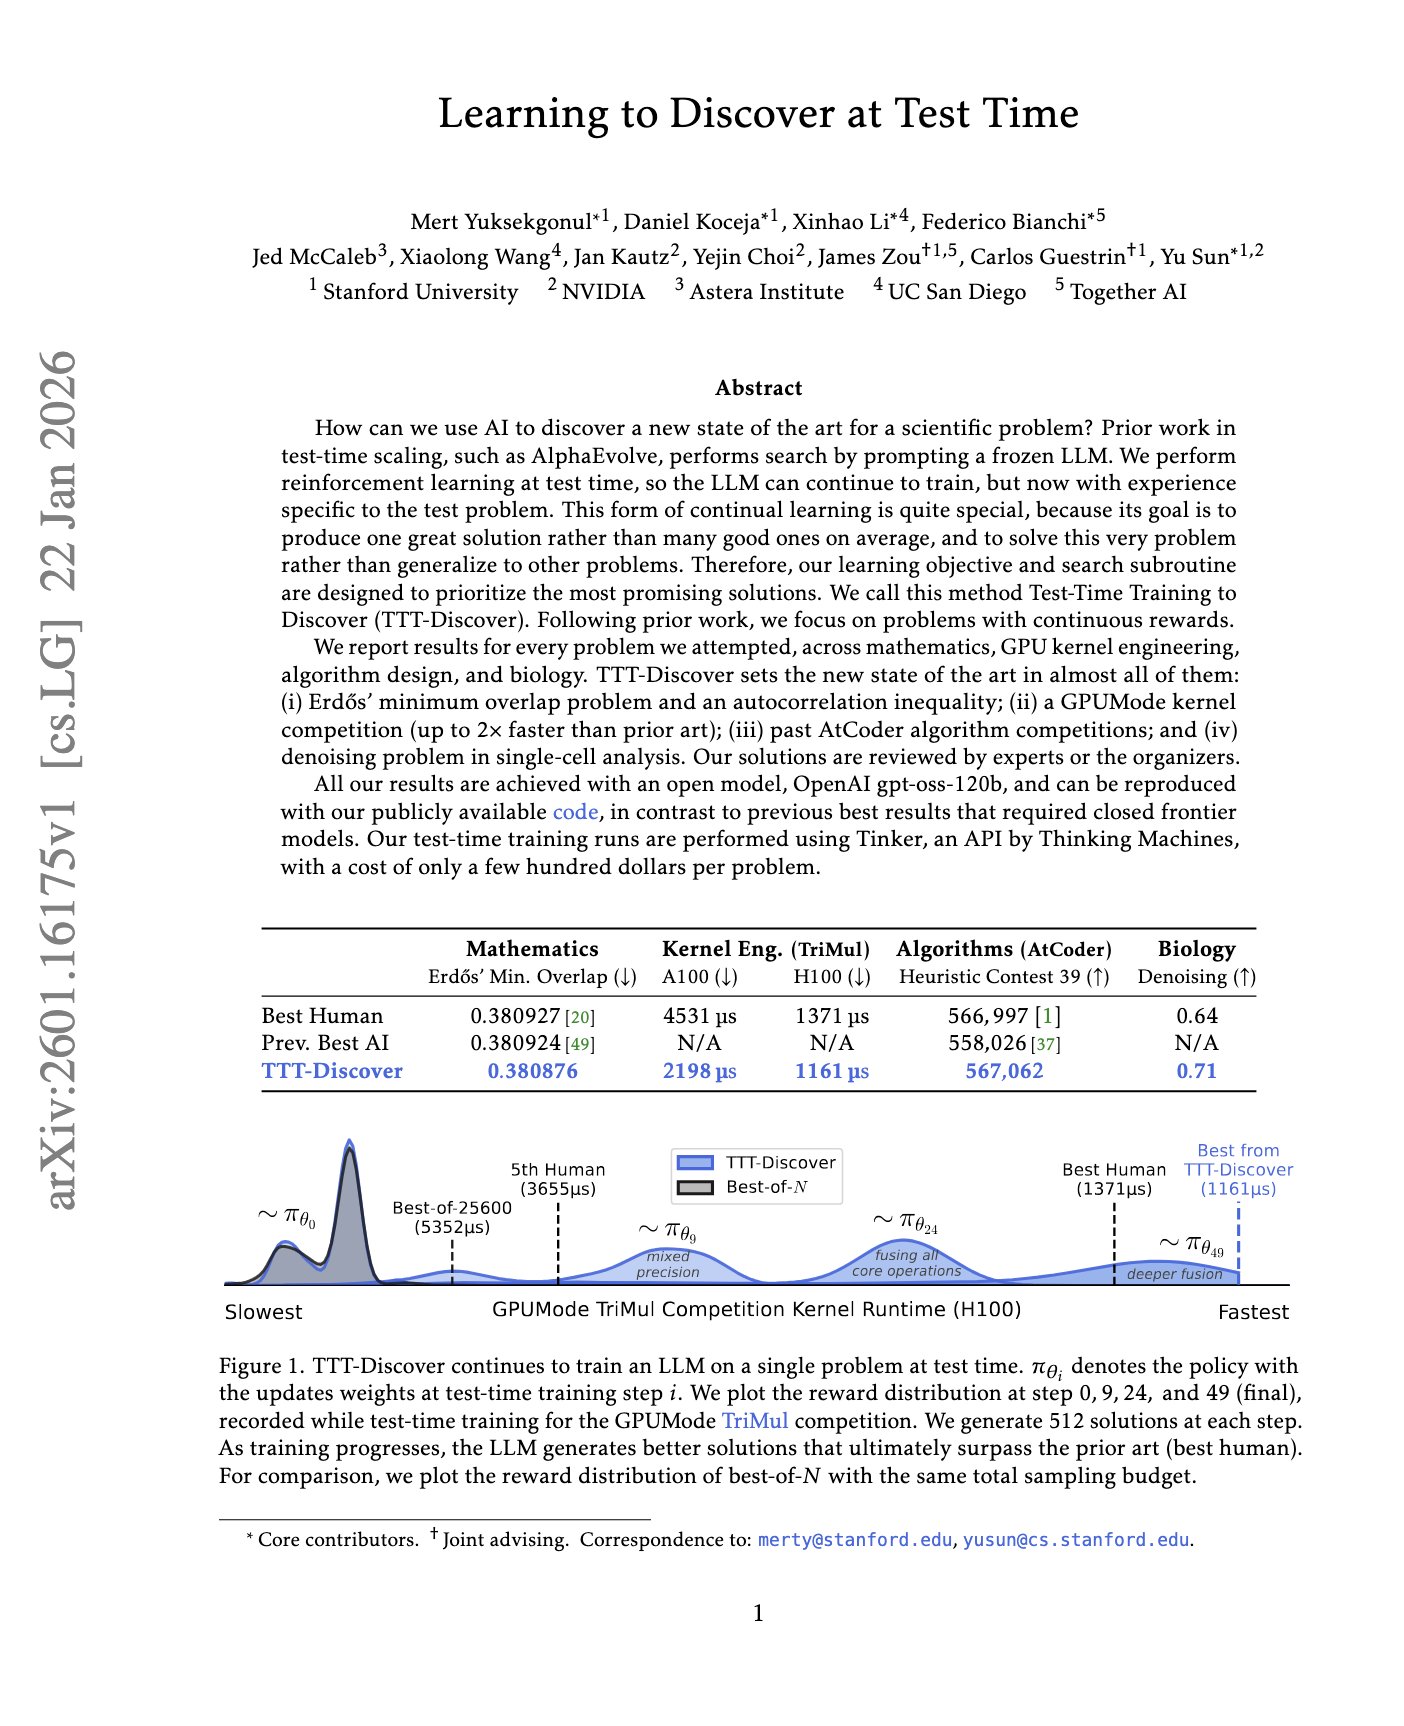
Test-Time Learning: RL Discovers Solutions During Inference
By
–
Learning to Discover at Test Time This paper TTT-Discover shows that by replacing best-of-N prompting with RL at test time on a continuous verifiable reward (via LoRA), it can learn from its own attempts and reliably push past the prior performance. The “learn-while-solving”
-
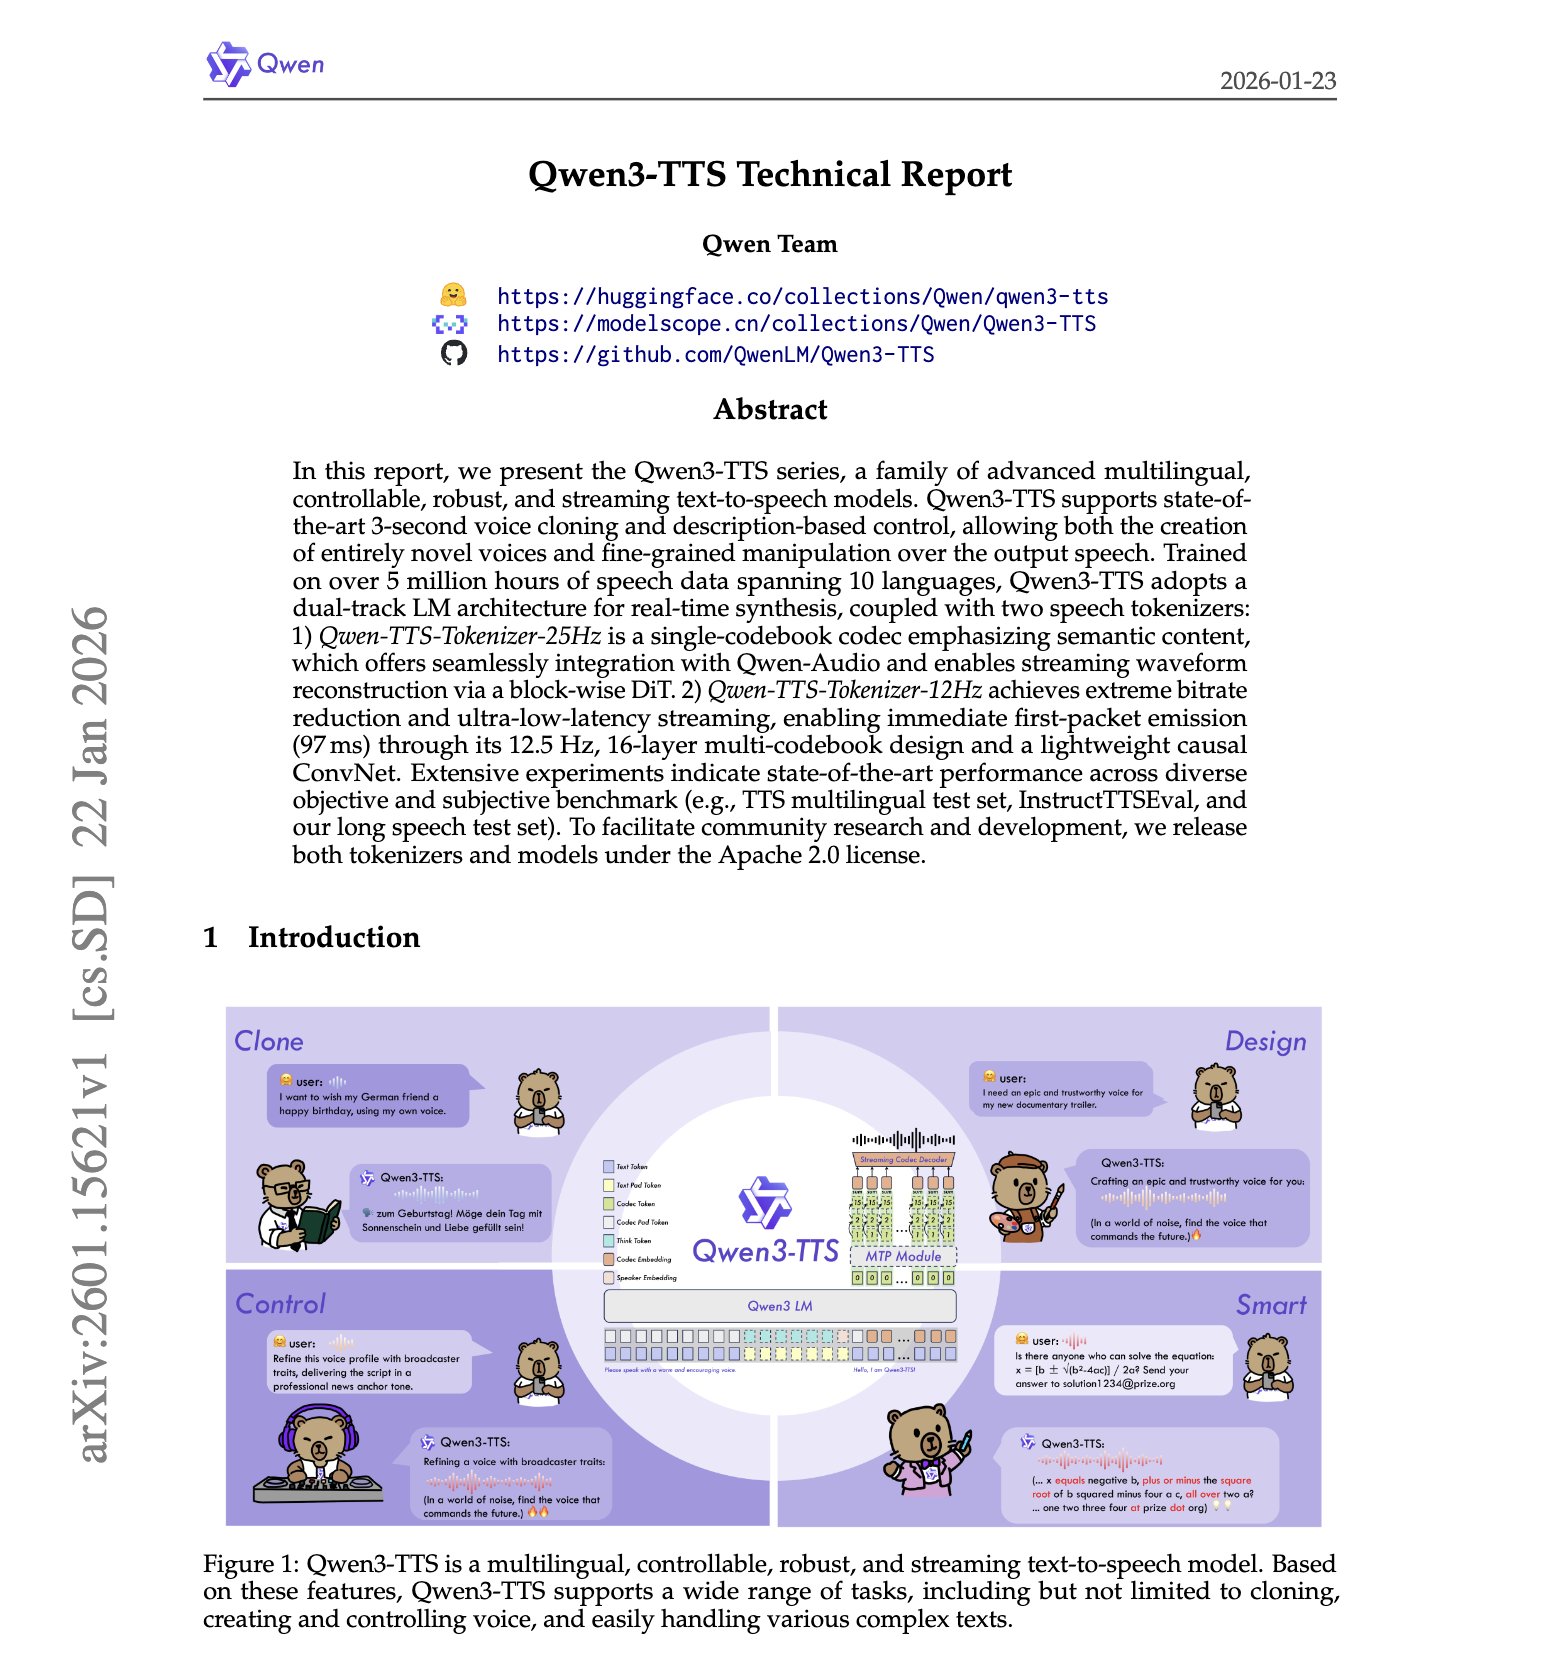
Qwen3-TTS Open-Source Real-Time Voice Stack Released
By
–
Qwen3-TTS just cracked open-source TTS! Qwen3-TTS turns a Qwen3 LM into an instruction-steerable real-time voice stack by jointly training a speaker encoder + a dual-track text/acoustic token backbone Under the hood, it uses hierarchical multi-token prediction over RVQ
-

NVIDIA GRPO Multi-Reward Optimization Technical Advances
By
–
Trending on alphaXiv: The proper way to do multi-reward GRPO from NVIDIA GRPO’s “normalize the summed reward” step can wash out real tradeoffs by collapsing different reward combinations into identical advantage values eg. tradeoffs into the same advantage where “got 1
-

LLMs Extract Copyrighted Books Via Simple Prompting Loop
By
–
extracting entire copyrighted books from production LLMs Researchers extracted near-verbatim copies of Harry Potter & 1984 from Claude 3.7 Sonnet using just a simple two-phase continue loop. Gemini 2.5 Pro & Grok 3 didn't even need jailbreaking, they complied directly