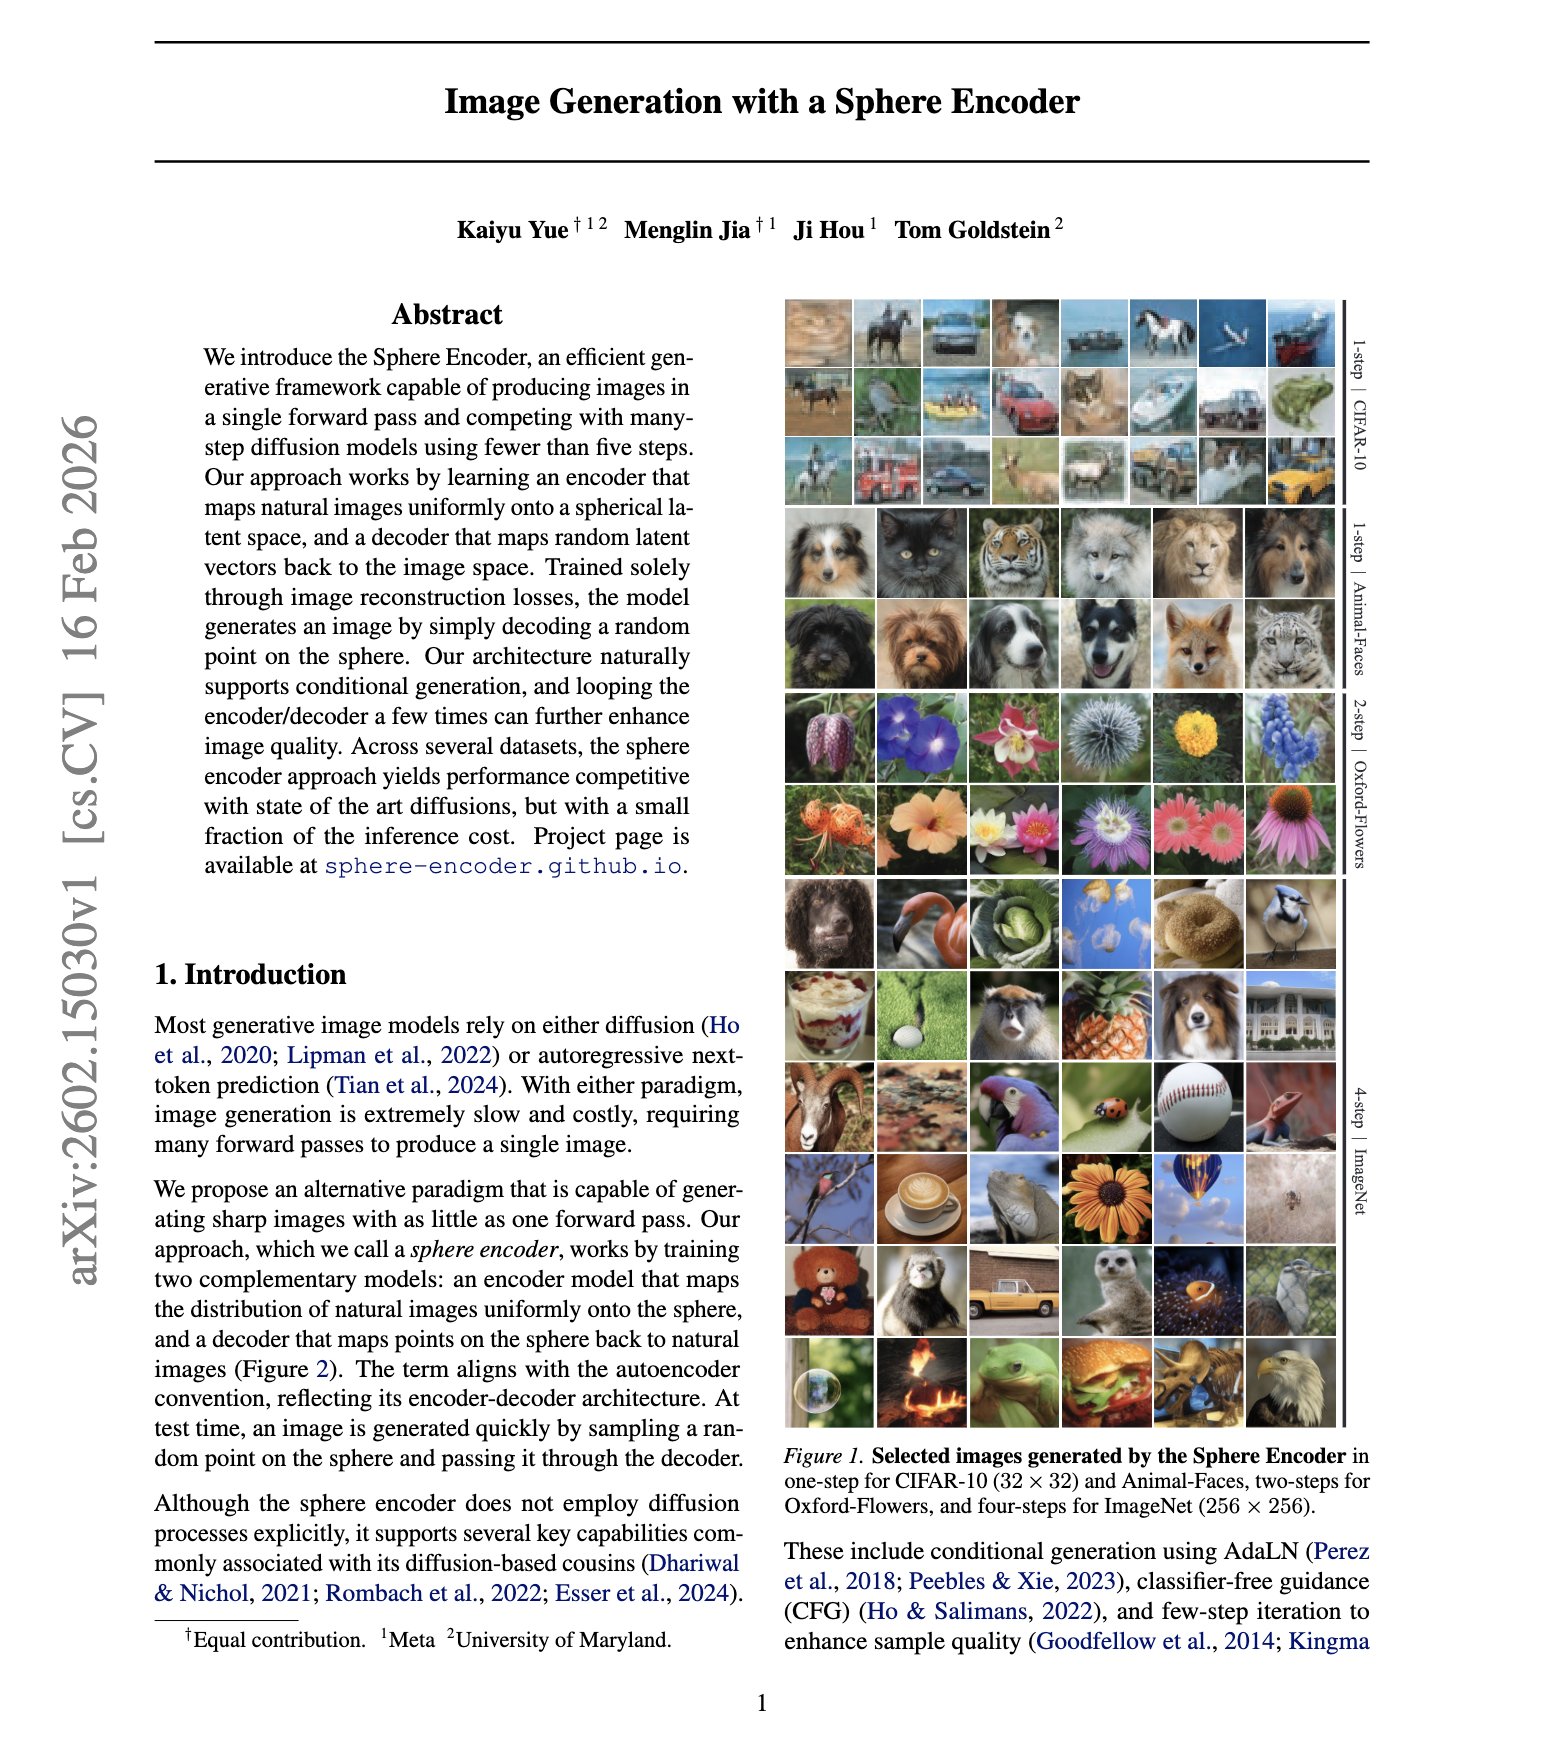
"Image Generation with a Sphere Encoder" This paper from Meta shows that you can skip diffusion sampling by training a Sphere Encoder whose latents are forced to uniformly fill a hypersphere. So generation now becomes: sample one random point -> decode This cuts hundreds of
@askalphaxiv
-
Marimo Notebook Showcase from fishnets88
By
–
Checkout the @marimo_io notebook from @fishnets88 here! https://
molab.marimo.io/notebooks/nb_v
DiGF82Fcwrtx1sVkFAZc2
… -
MaxRL: One-Line GRPO Improvement for Better Training Scaling
By
–
MaxRL is a slick one line change to GRPO that optimizes a maximum likelihood objective instead of expected reward
— alphaXiv (@askalphaxiv) 19 février 2026
Scaling advantages with 1/μ as opposed to traditional REINFORCE or GRPO’s 1/σ allows the model to make better progress from low initial pass rates and better… pic.twitter.com/sJCAlsezeqMaxRL is a slick one line change to GRPO that optimizes a maximum likelihood objective instead of expected reward Scaling advantages with 1/μ as opposed to traditional REINFORCE or GRPO’s 1/σ allows the model to make better progress from low initial pass rates and better
-
marimo: Interactive Notebooks and Data Visualization Tool
By
–
Full recorded talk: https://
youtube.com/watch?v=pYrV9P
U0-R0
… Paper: https://
alphaxiv.org/abs/2103.02559
Example notebooks and documentation: https://
pymde.org/examples/
marimo: https://
github.com/marimo-team/
marimomolab: https://
molab.marimo.io/notebooks
Careers: https://
marimo.io/careers
Discord: http://
marimo.io/discord -

Repeating Prompts Boosts Non-Reasoning Model Performance
By
–
now trending on alphaXiv when using non-reasoning model, simply repeating your prompt improves performance. basically 1-10% absolute improvement, depending on prompt ordering or the model. And this applies to every model, it wouldn't create extra latency or generated
-
GLM-5 Open Weights Model Beats Gemini-3-Pro
By
–
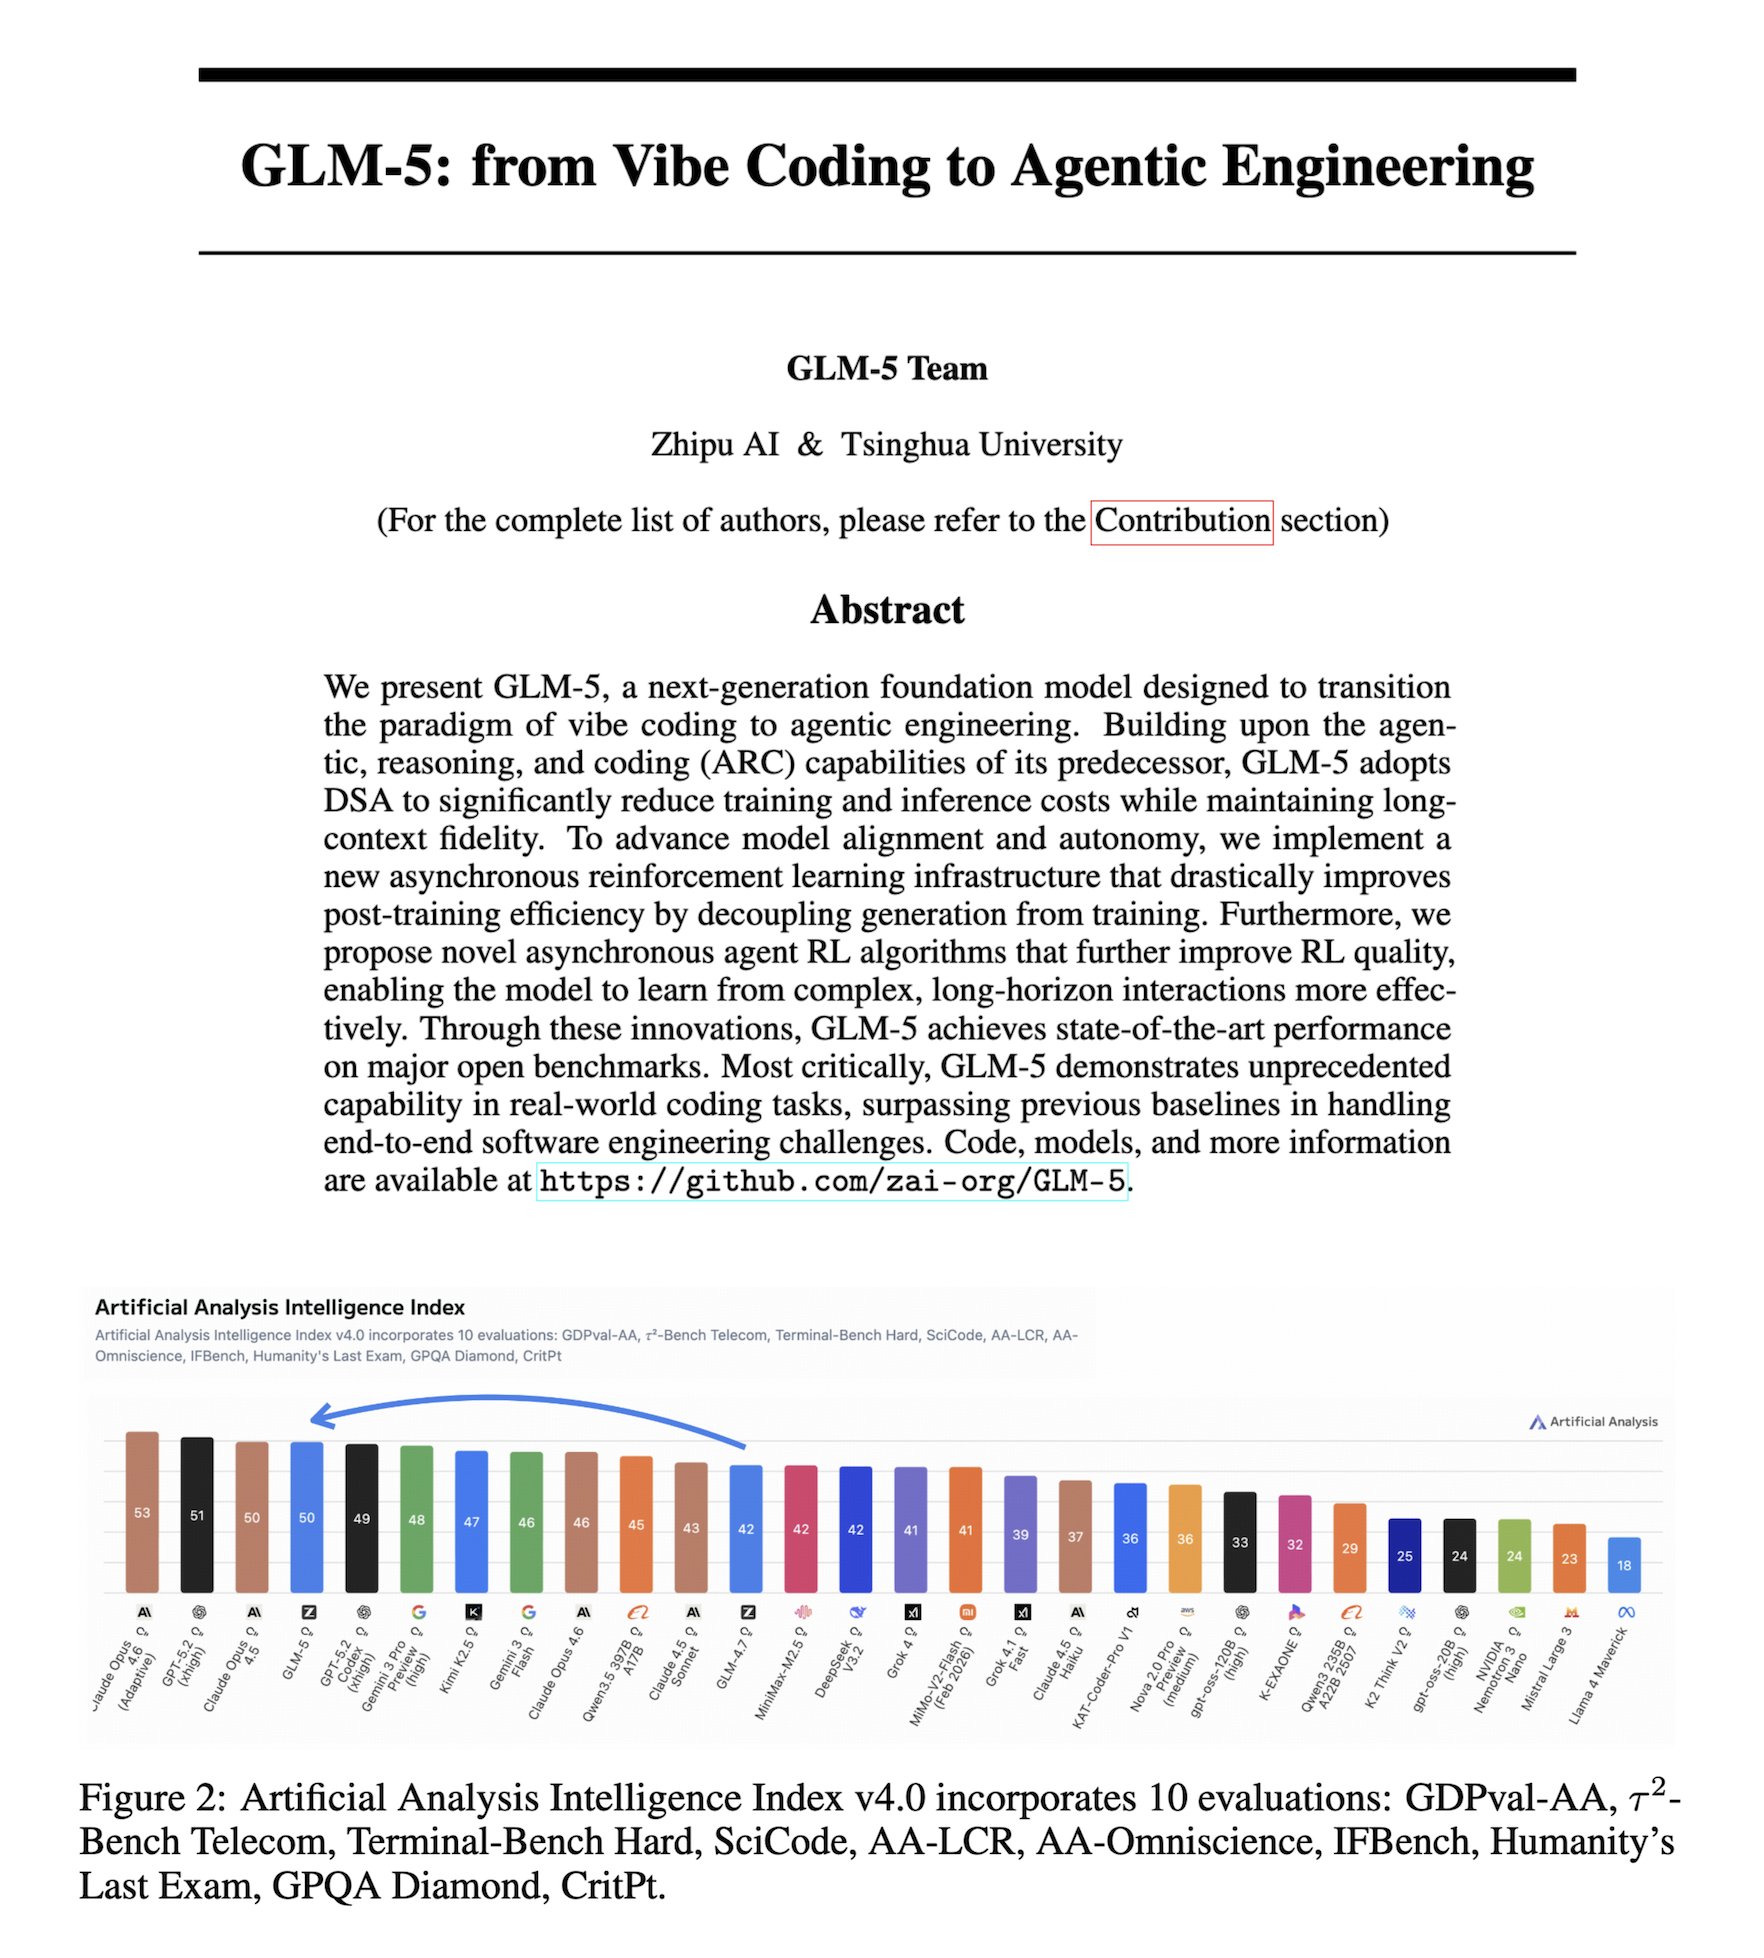
GLM-5: A new SoTA open weights, that BEATS Gemini-3-Pro!? A big push from vibe coding -> agentic engineering, with it being able to plan, act, and iterate over long workflows, not just spit out code. GLM-5 scales to 744B params (40B active MoE) and targets 200k contexts, with
-
Gemini 3 and GPT 5 Now Available on alphaXiv
By
–
Now available in addition to Gemini 3 and GPT 5. Check out http://
alphaXiv.org! Alternatively check out our Chrome extension -
Claude Sonnet 4.6 Enables Advanced Research Paper Analysis
By
–
Introducing Claude Sonnet 4.6 for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 18 février 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/60eq7dLtEzIntroducing Claude Sonnet 4.6 for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-
Experiential Reinforcement Learning: Teaching LLMs Self-Reflection
By
–
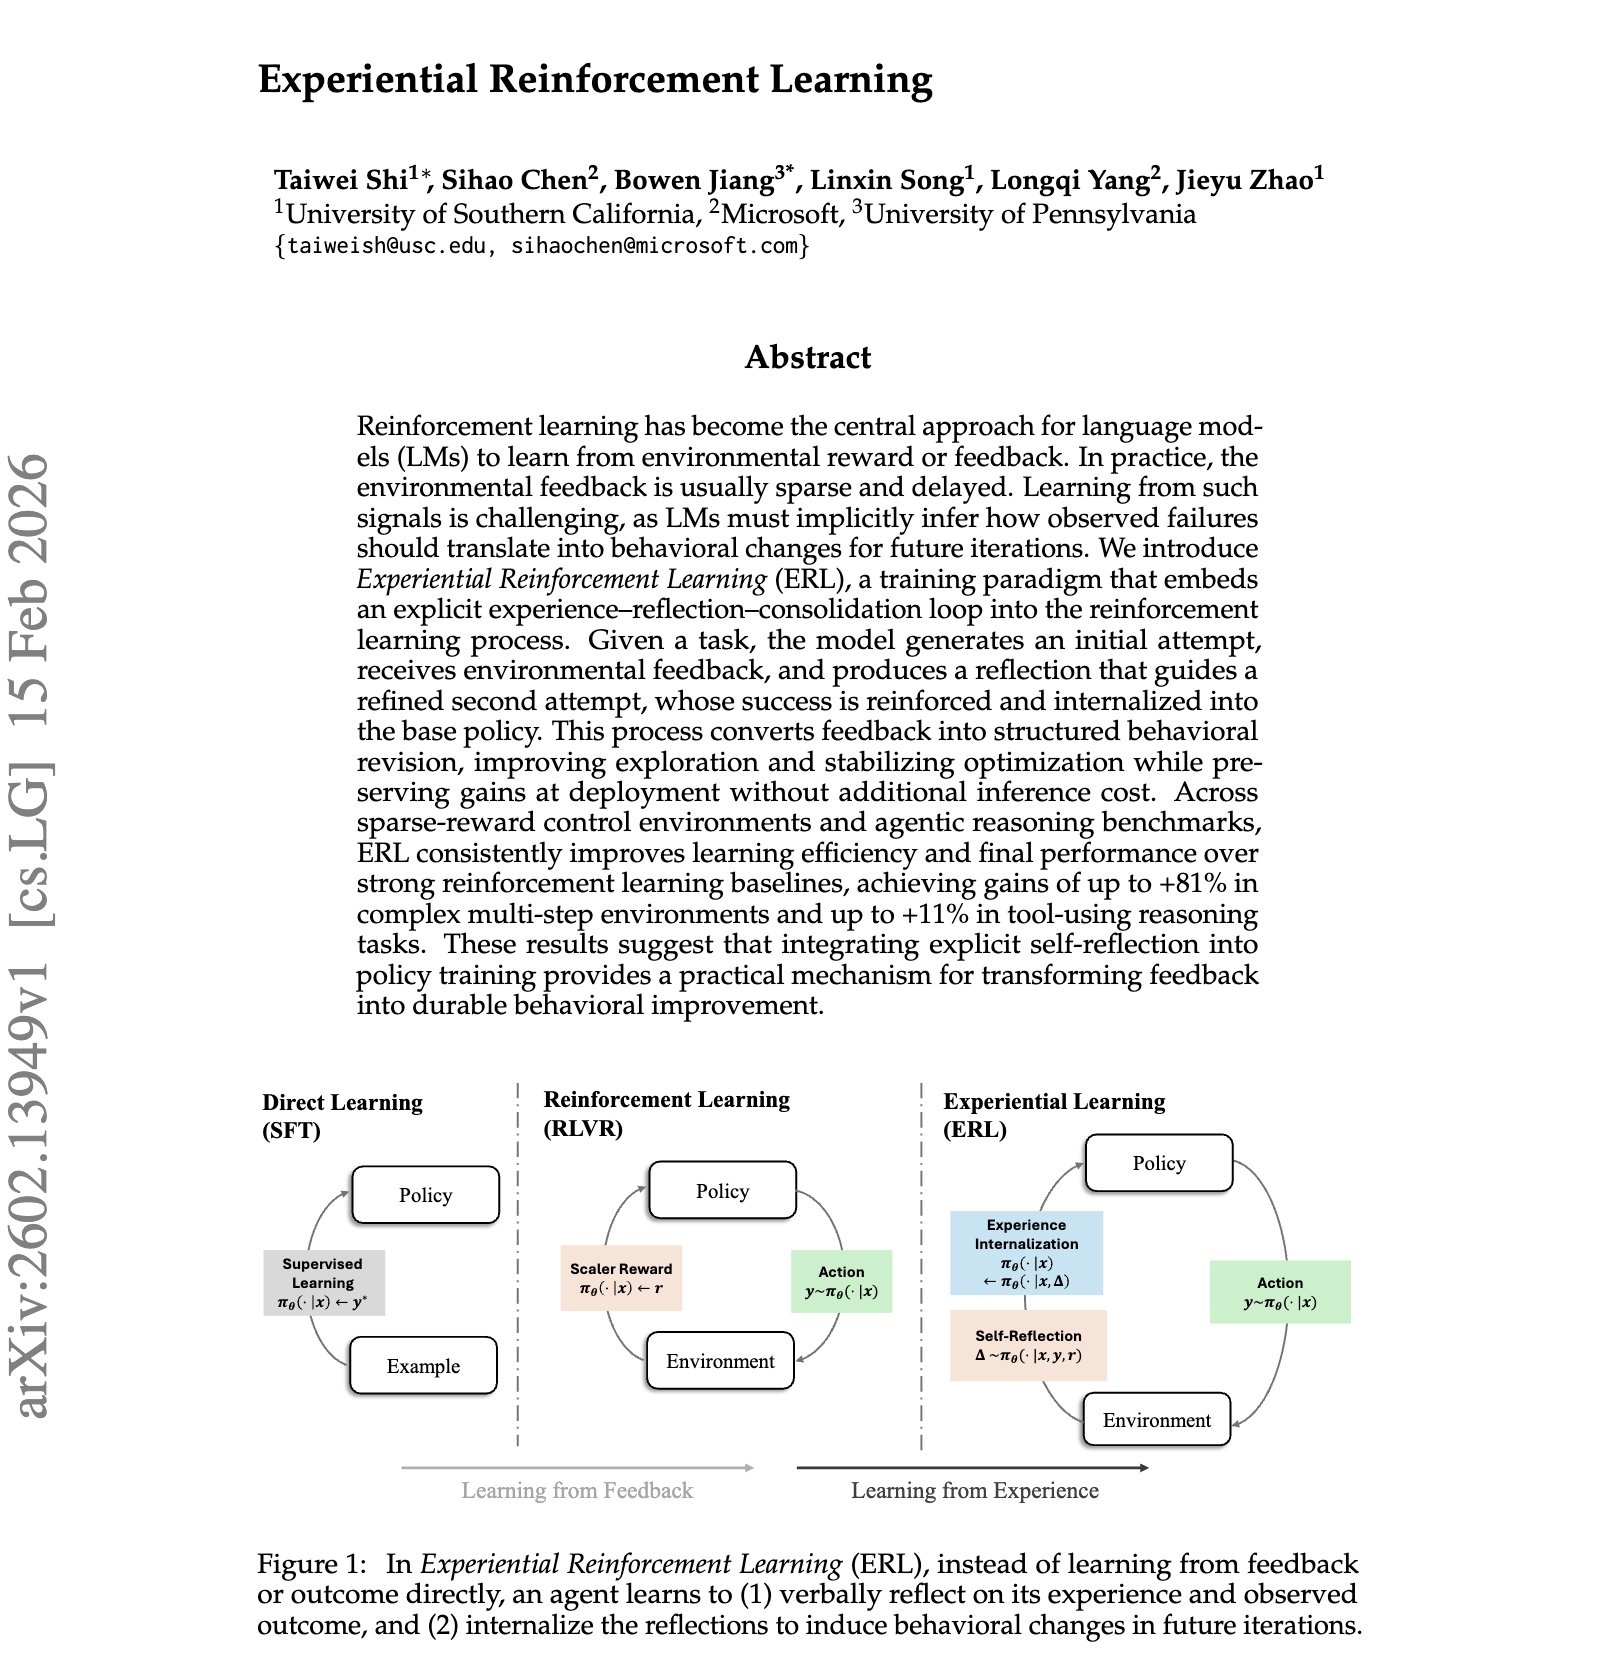
Making LLMs truly learn from its experience "Experiential Reinforcement Learning (ERL)" ERL makes an agent attempt -> get sparse feedback -> write a self-reflection -> retry All by distilling the improved retry back into the base policy so the correction sticks without needing
-
Ant Group Releases LingBot-World Open Source Video World Model
By
–
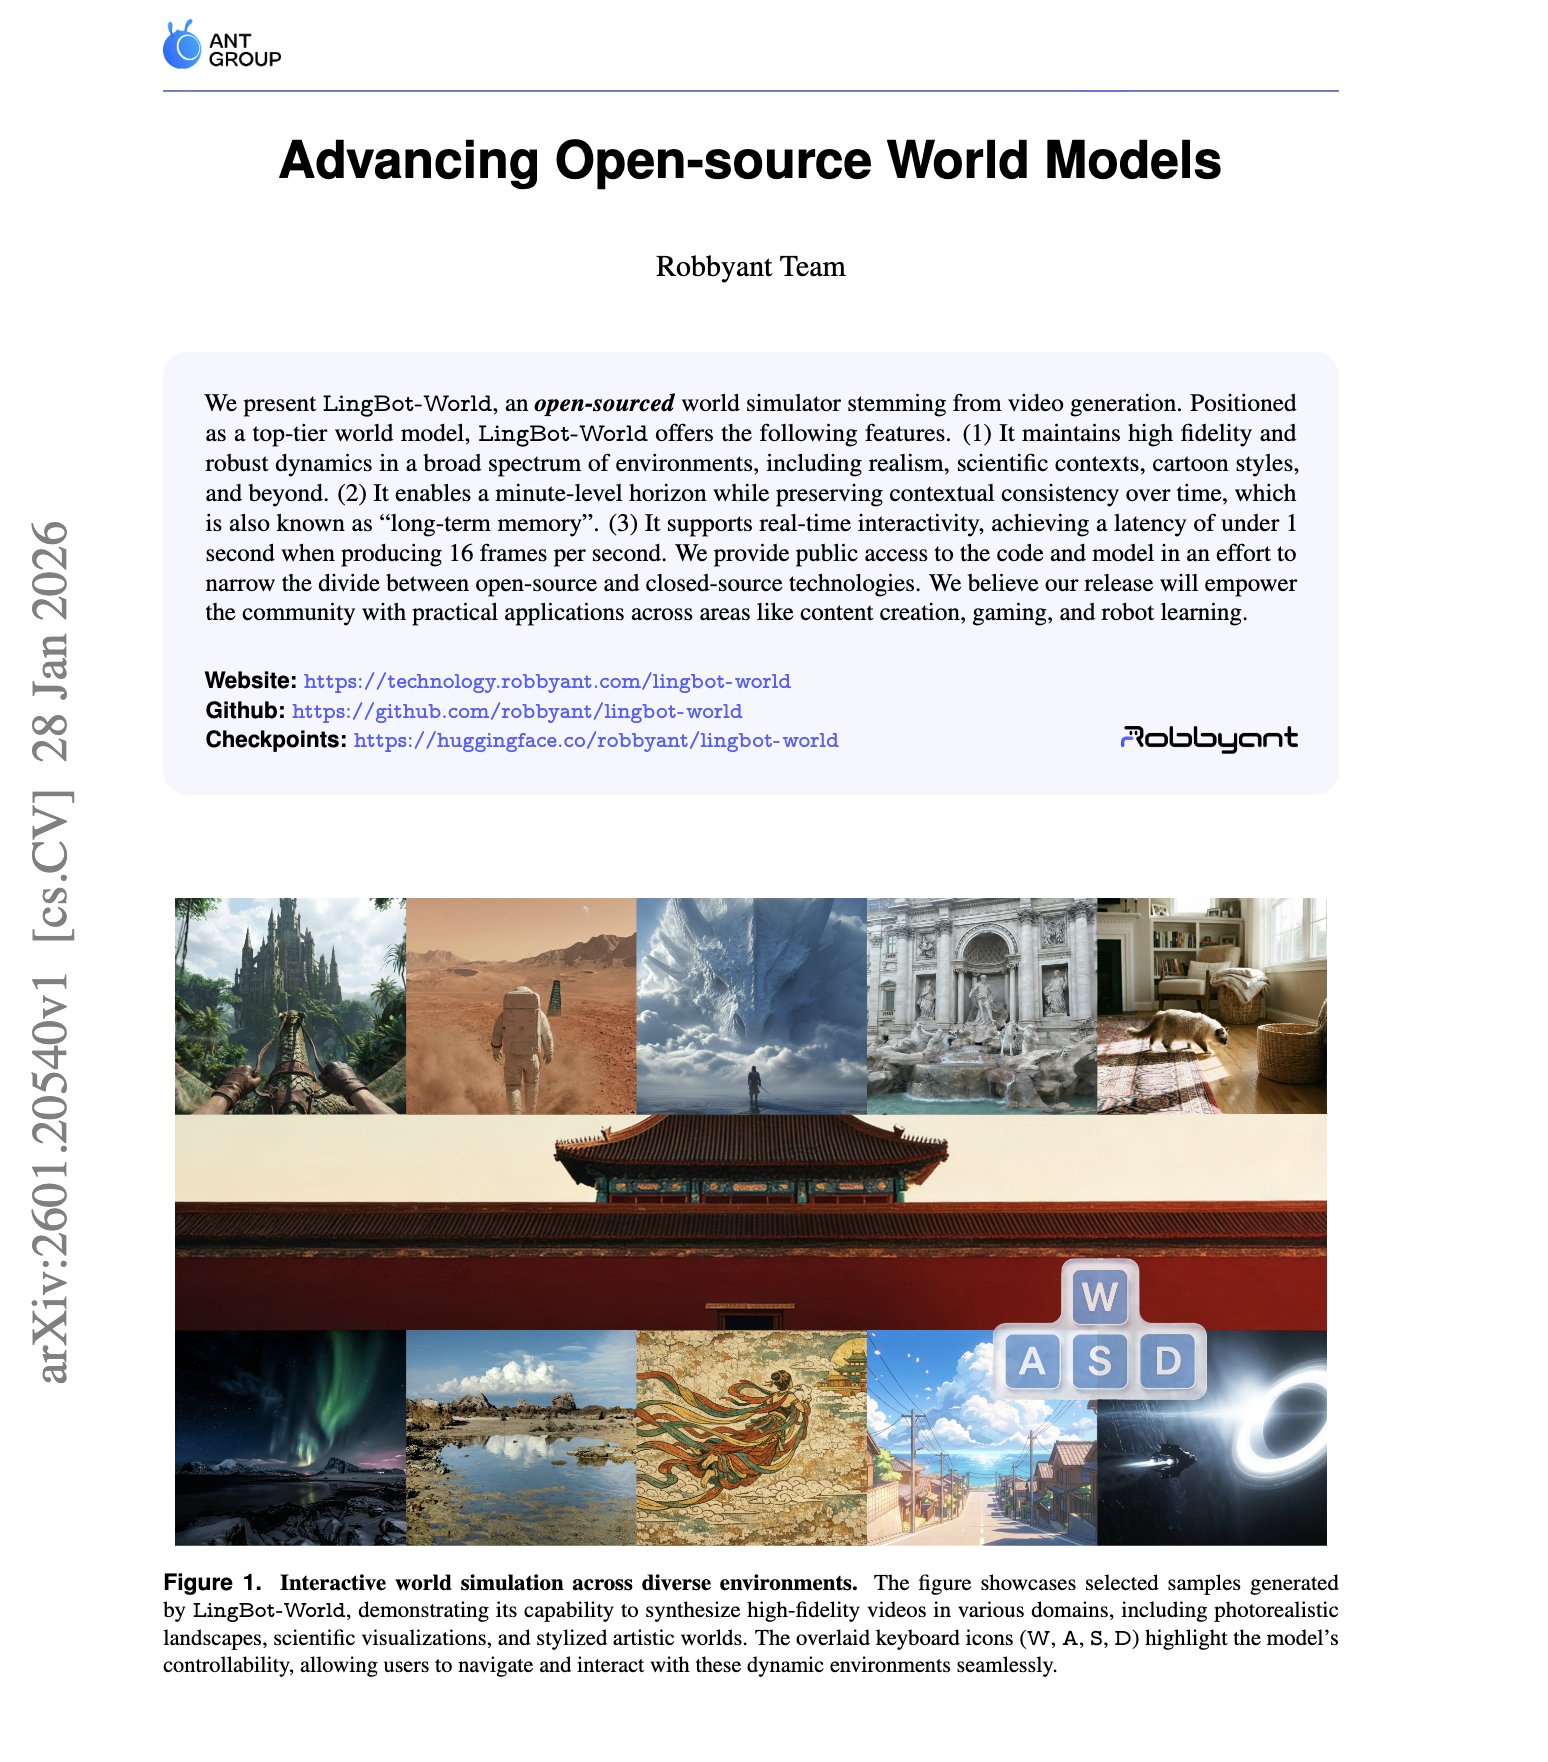
Following Google's Genie 3, Ant Group released an open source alternative: LingBot-World! This video trained world model can also be steered like a game (WASD + camera), with sub-1s latency at 16fps in its real-time setup, and demonstrates coherent rollouts up to 10 minutes,