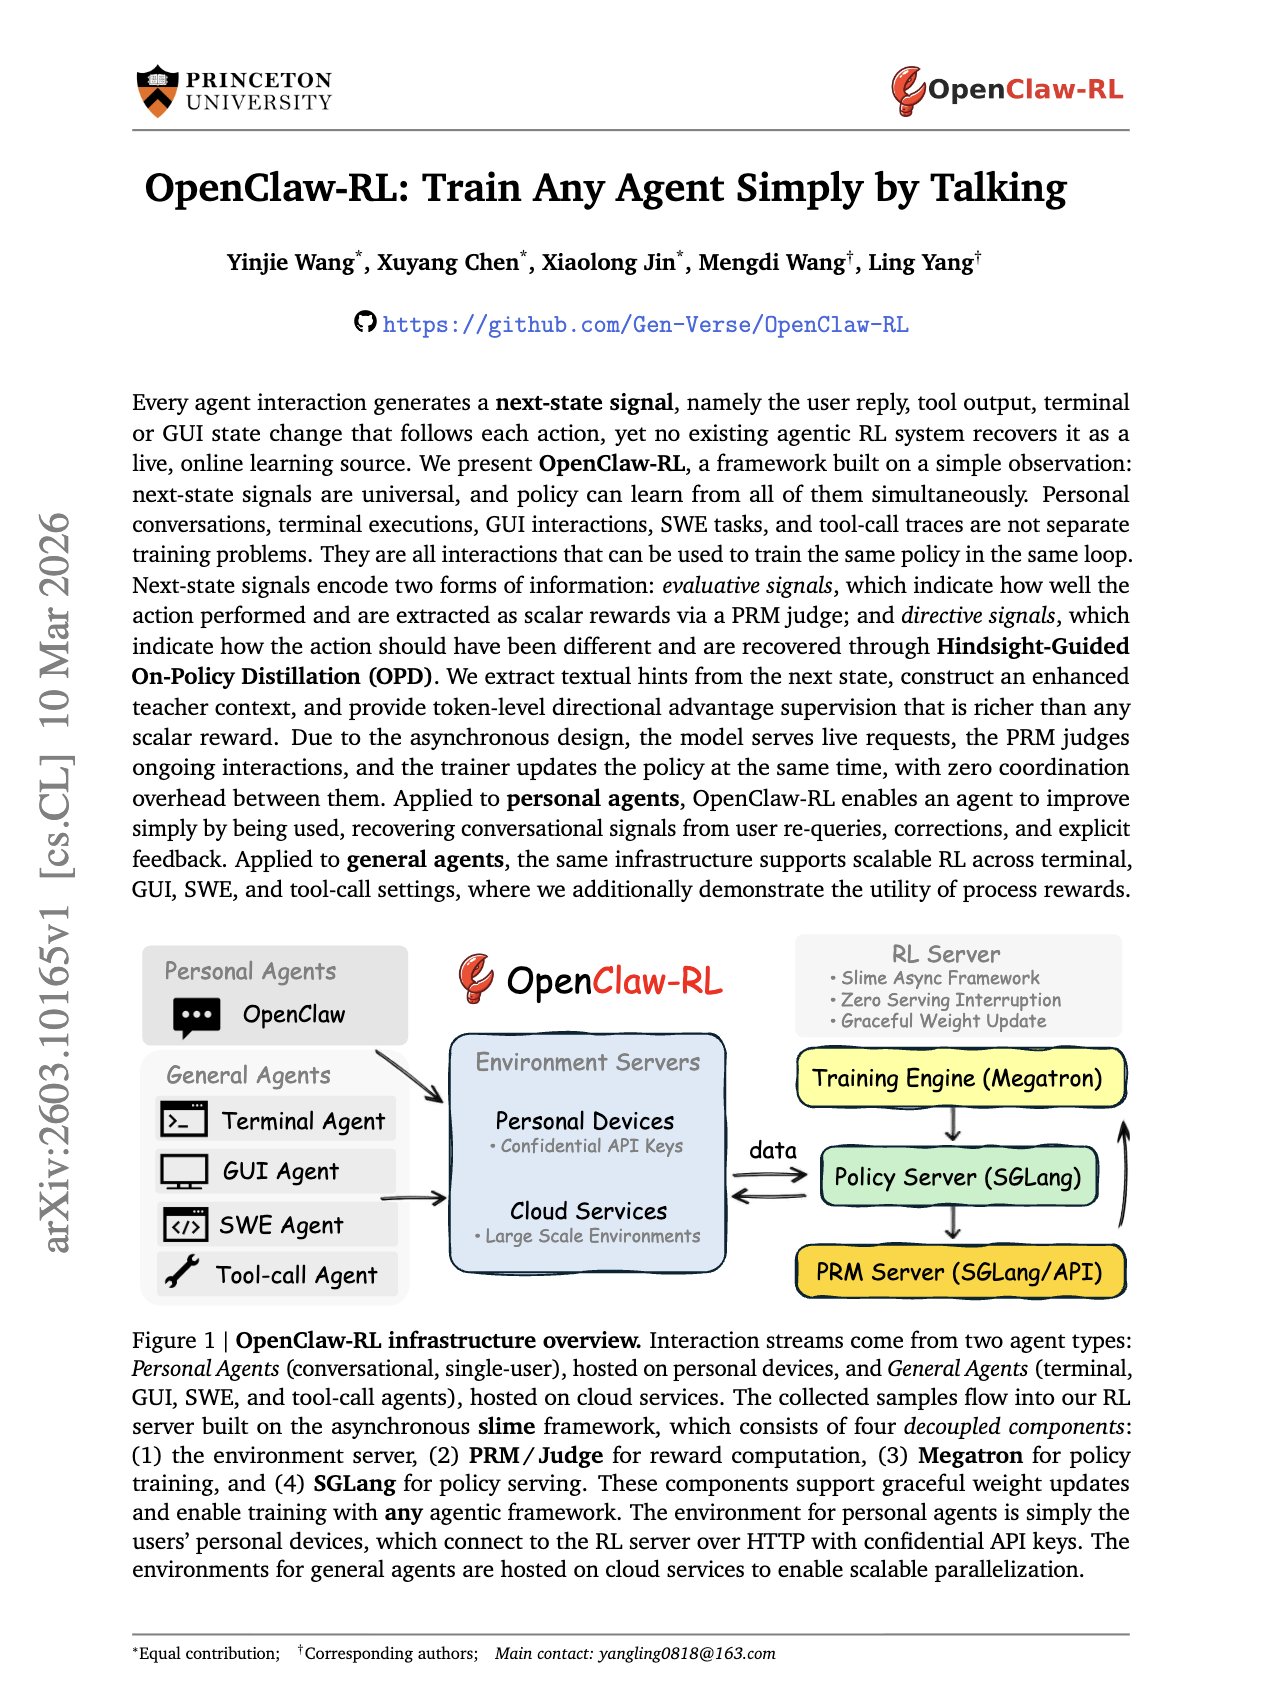
"OpenClaw-RL: Train Any Agent Simply by Talking" OpenClaw-RL’s big idea is that every time an AI agent gets a reply, error, test result, or tool output, it’s already receiving free feedback. So instead of wasting those signals, this paper turns everyday use into live
@askalphaxiv
-
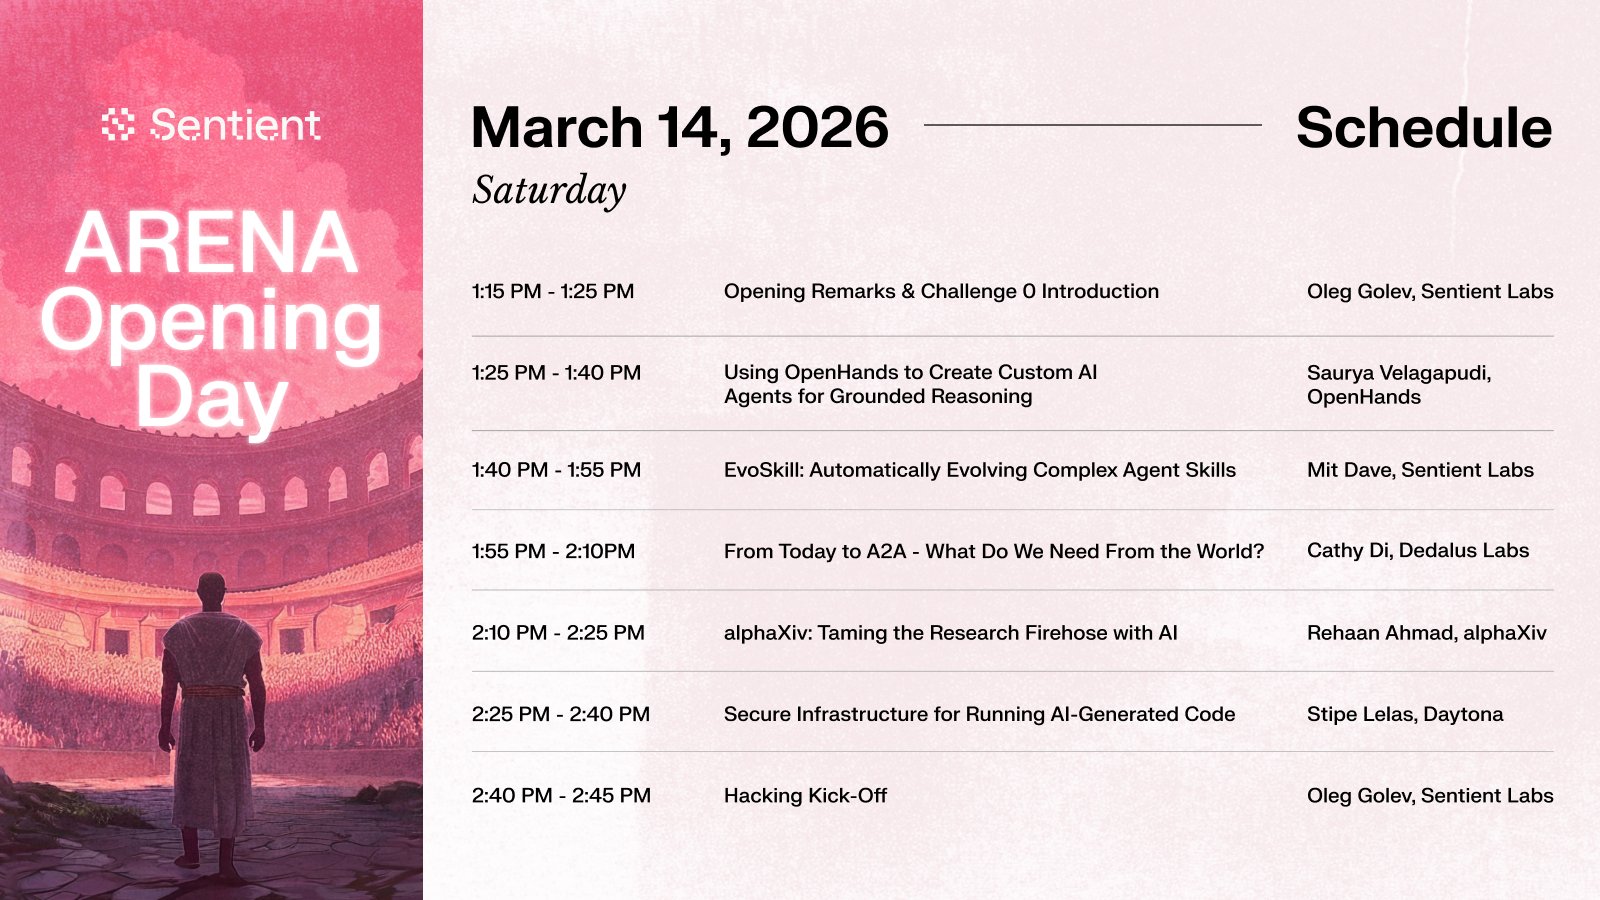
SentientAGI Partnership Launch for Arena Innovation
By
–
Excited to be partnering up with @SentientAGI for the Arena! We'll also be introducing some of the newest things we're working on
-
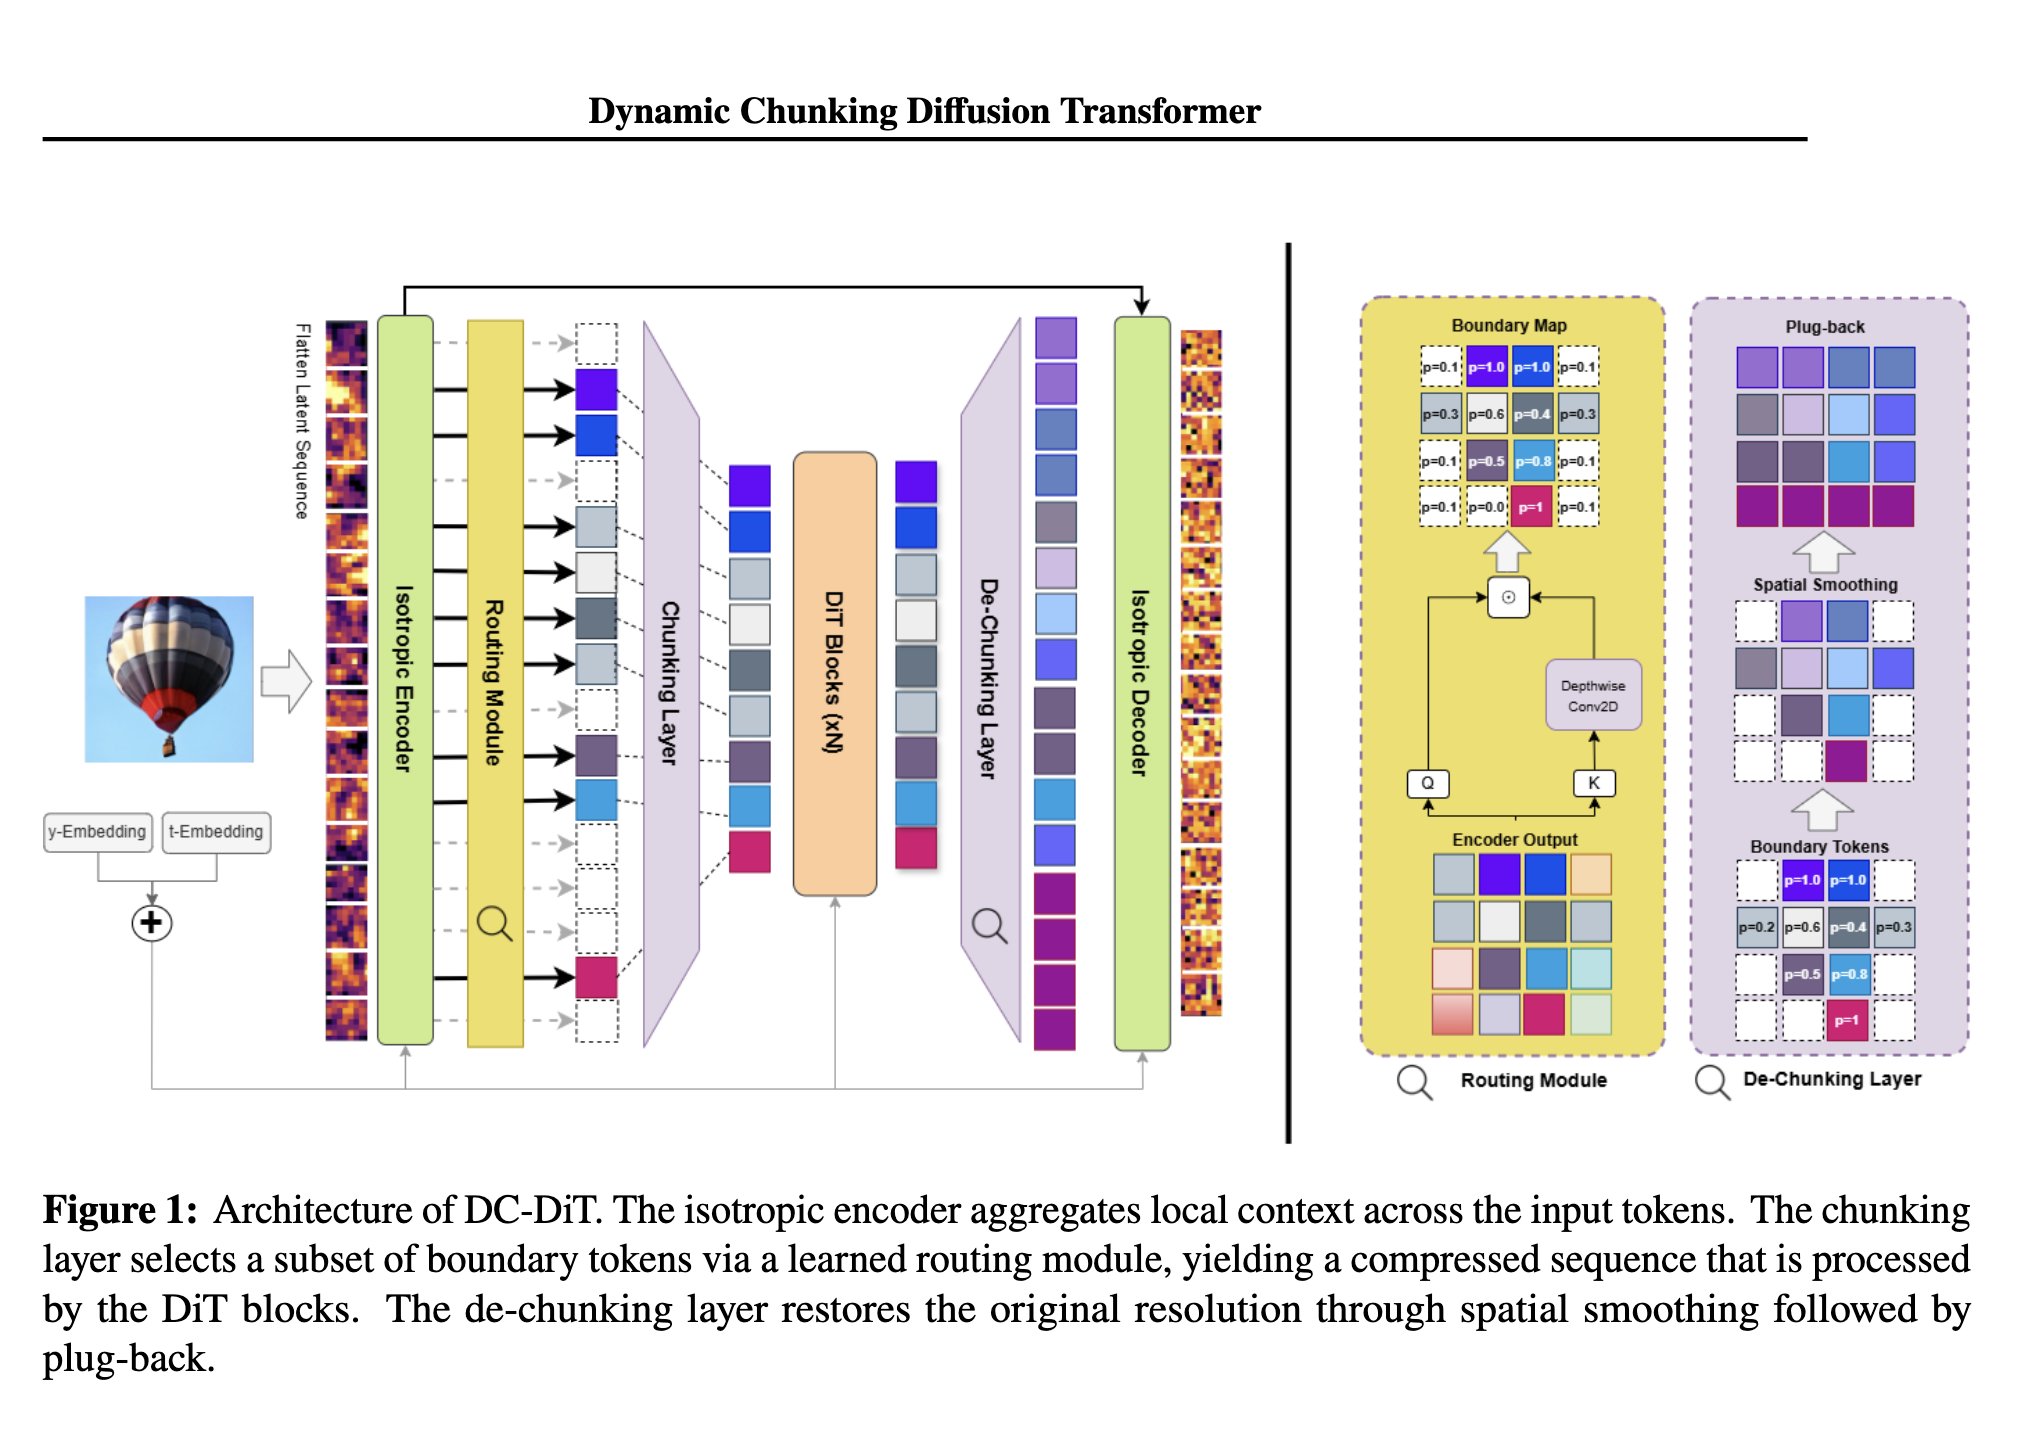
Dynamic Chunking Improves Diffusion Transformer Efficiency
By
–
“Dynamic Chunking Diffusion Transformer” Instead of splitting every image into the same grid of patches, this paper lets the model use bigger chunks for simple areas and finer chunks for detailed areas. It also changes the token budget over the diffusion process, where fewer
-

Scalable MoE Training Efficiency with Megatron Core
By
–
“Scalable Training of Mixture-of-Experts Models with Megatron Core” This NVIDIA MoE report walks through the hard part of MoE training. The key is not to add more parameters, but keeping sparse models efficient when only a small part of the model runs for each token. For
-
Paperscrolling: AI-Powered Research Discovery Tool Launches
By
–
If doomscrolling X is part of your research workflow, we built something for you.
— alphaXiv (@askalphaxiv) 12 mars 2026
Introducing Paperscrolling 🚀
Get the most trending research with key ideas, figures, and audio explanations from alphaXiv Briefs pic.twitter.com/8uGbaheOvbIf doomscrolling X is part of your research workflow, we built something for you. Introducing Paperscrolling Get the most trending research with key ideas, figures, and audio explanations from alphaXiv Briefs
-
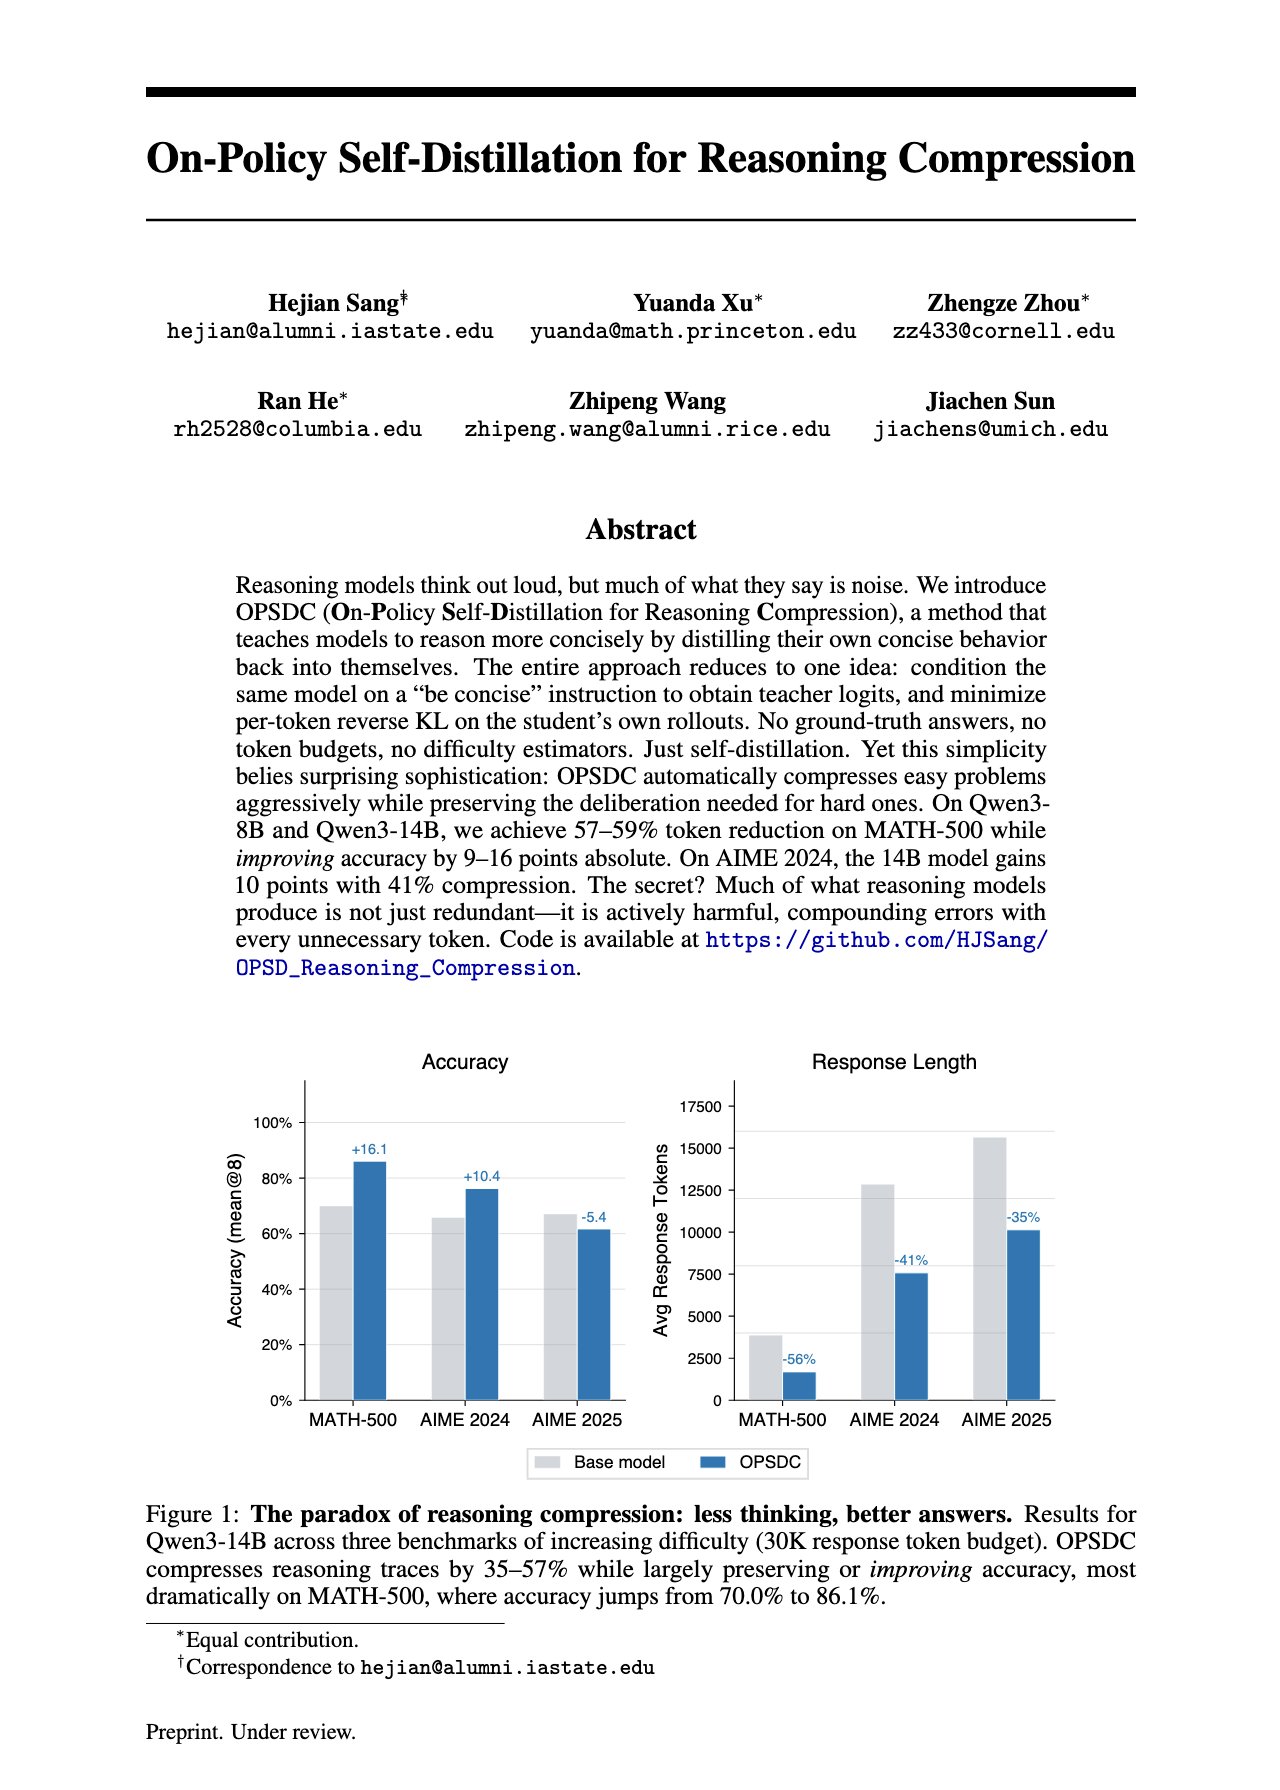
On-Policy Self-Distillation Improves Reasoning LLM Efficiency
By
–
“On-Policy Self-Distillation for Reasoning Compression” This paper shows that the new bottleneck for reasoning LLMs isn’t “too little reasoning”, it’s that more reasoning tokens often increase mistakes. So they fixed it without RL length penalties or external verifiers, but all
-
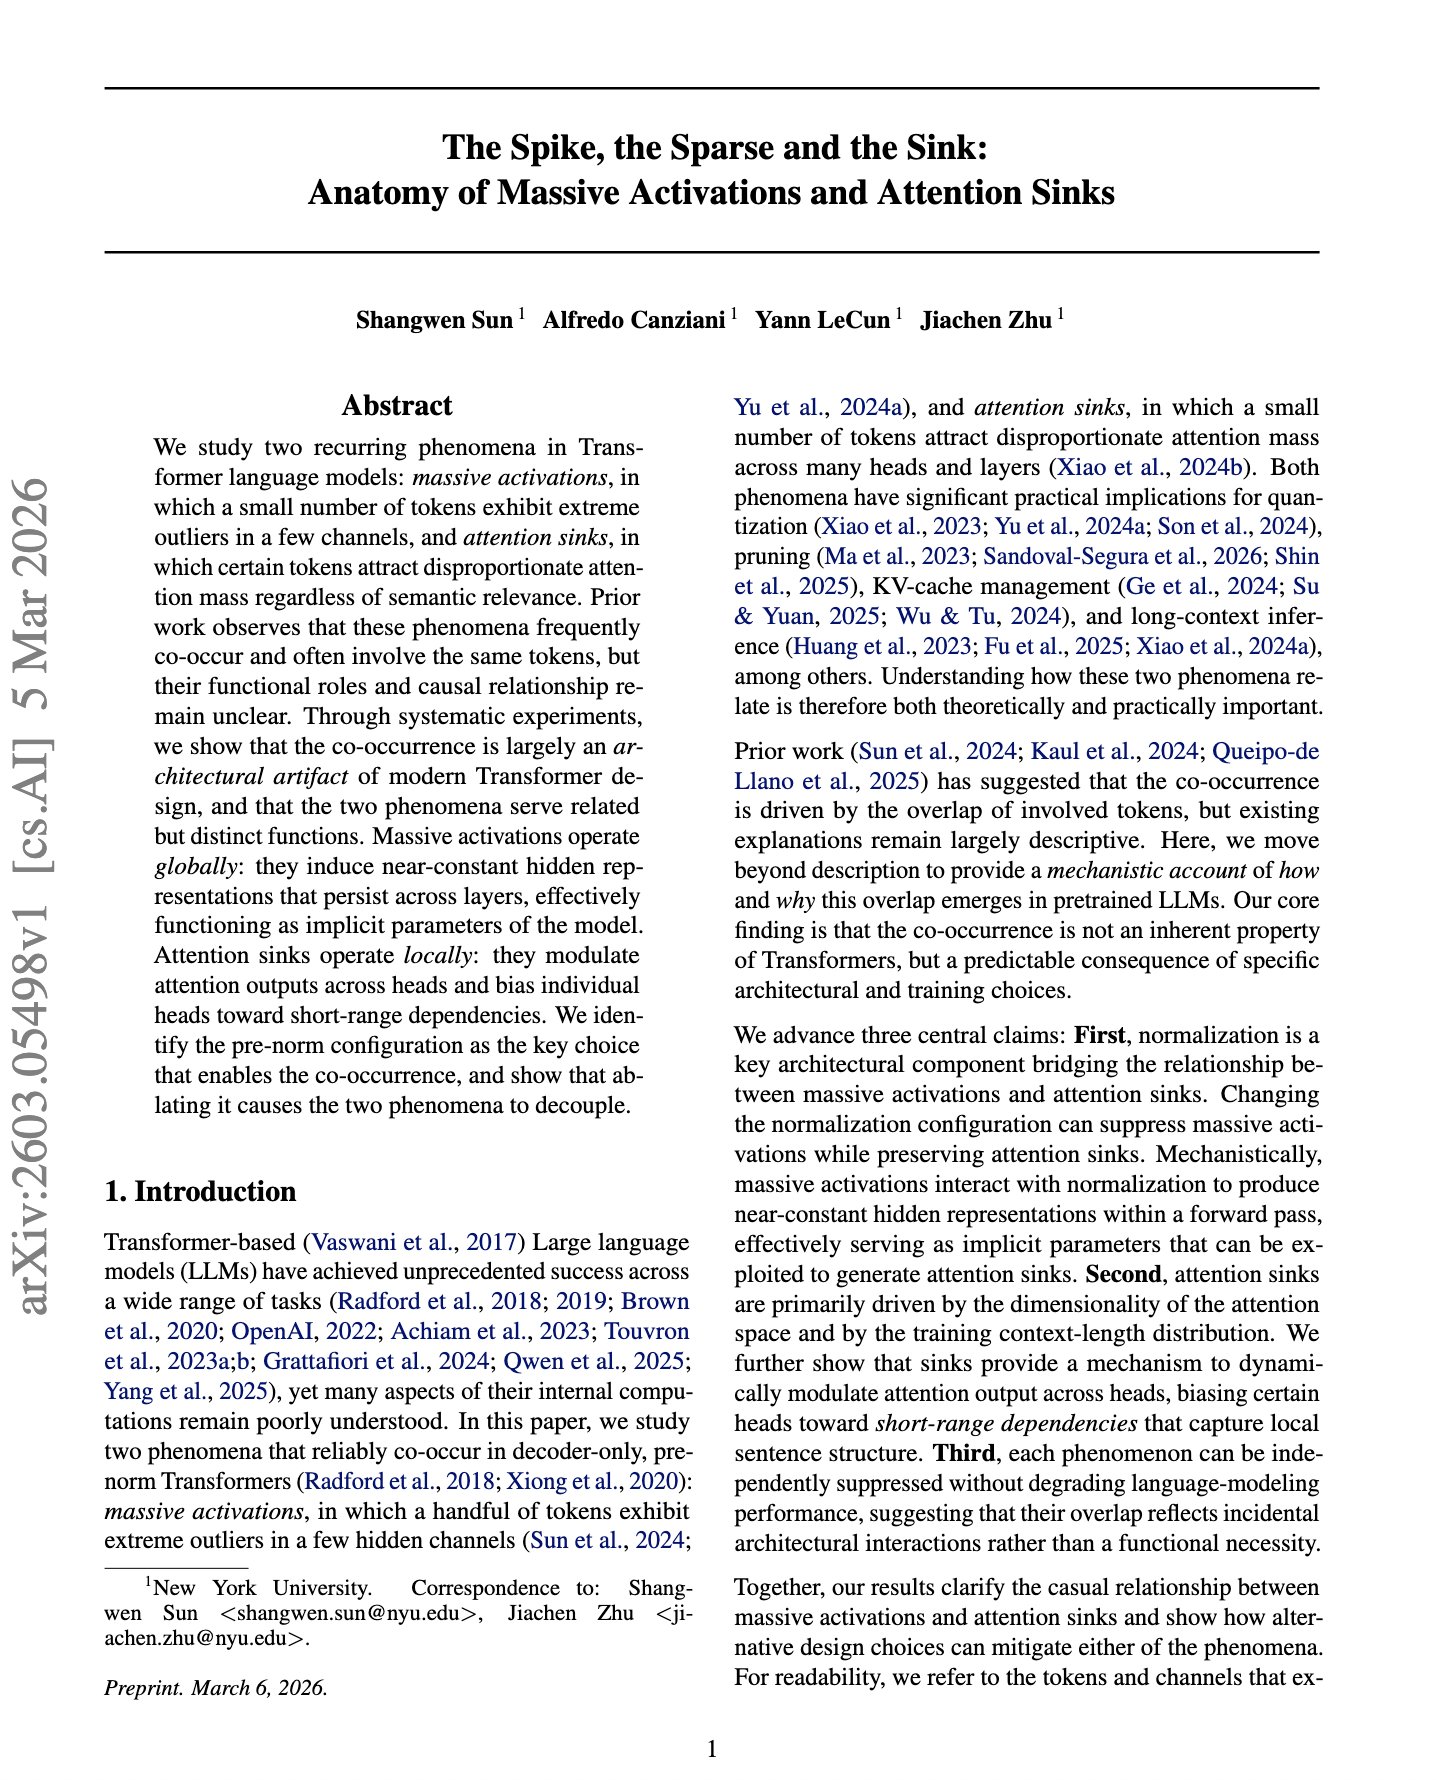
Research Analysis: Massive Activations and Attention Sinks in Transformers
By
–
Another by Yann LeCun! “The Spike, the Sparse and the Sink” This paper shows that massive activations and attention sinks come from the same pre-norm Transformer pipeline rather than being separate anomalies. Early SwiGLU blocks act like directional quadratic amplifiers,
-
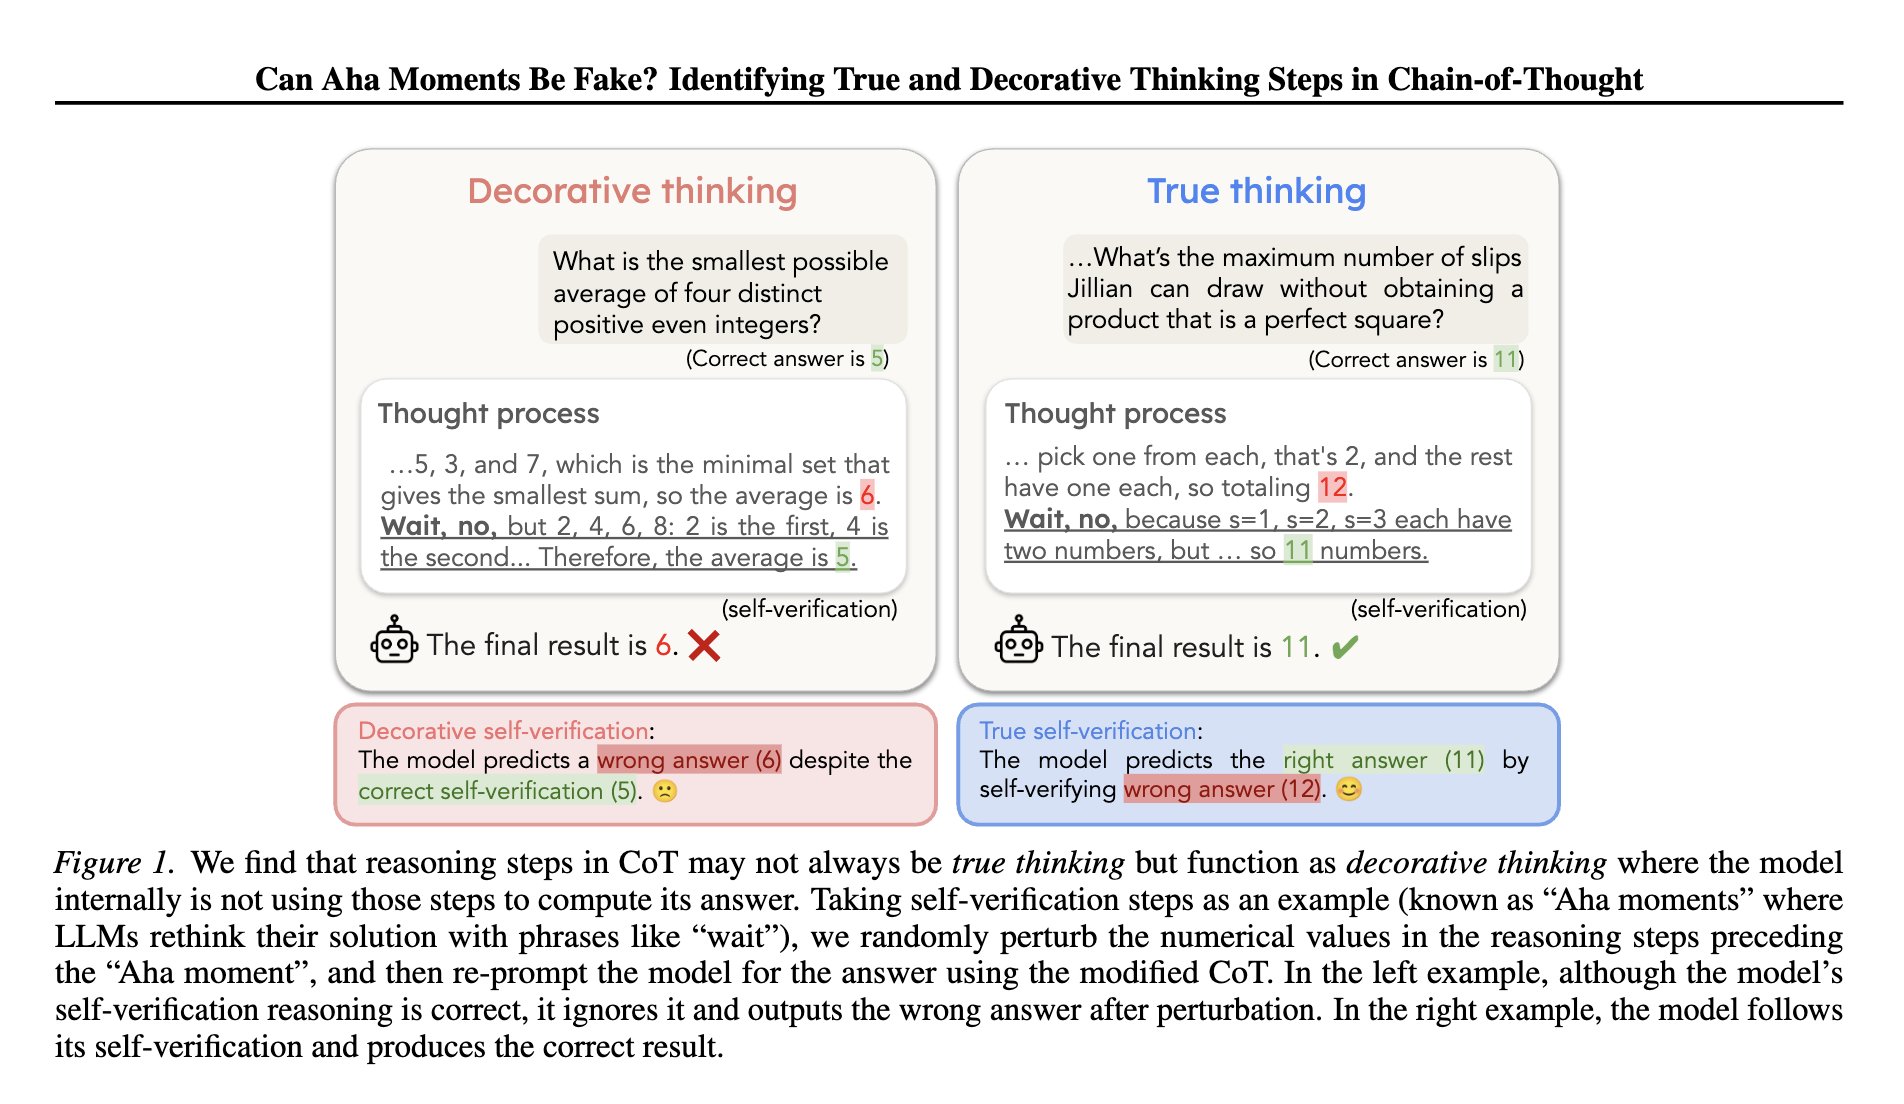
Research Analysis: Can LLM Chain-of-Thought Reasoning be Deceptive?
By
–
"Can Aha Moments Be Fake?" This paper shows that LLMs can generate CoT reasoning where the verbalized steps don't actually reflect the model's internal thinking process, like decorative thinking steps. The model can even verbalize an aha moment where it pretends to correct
-
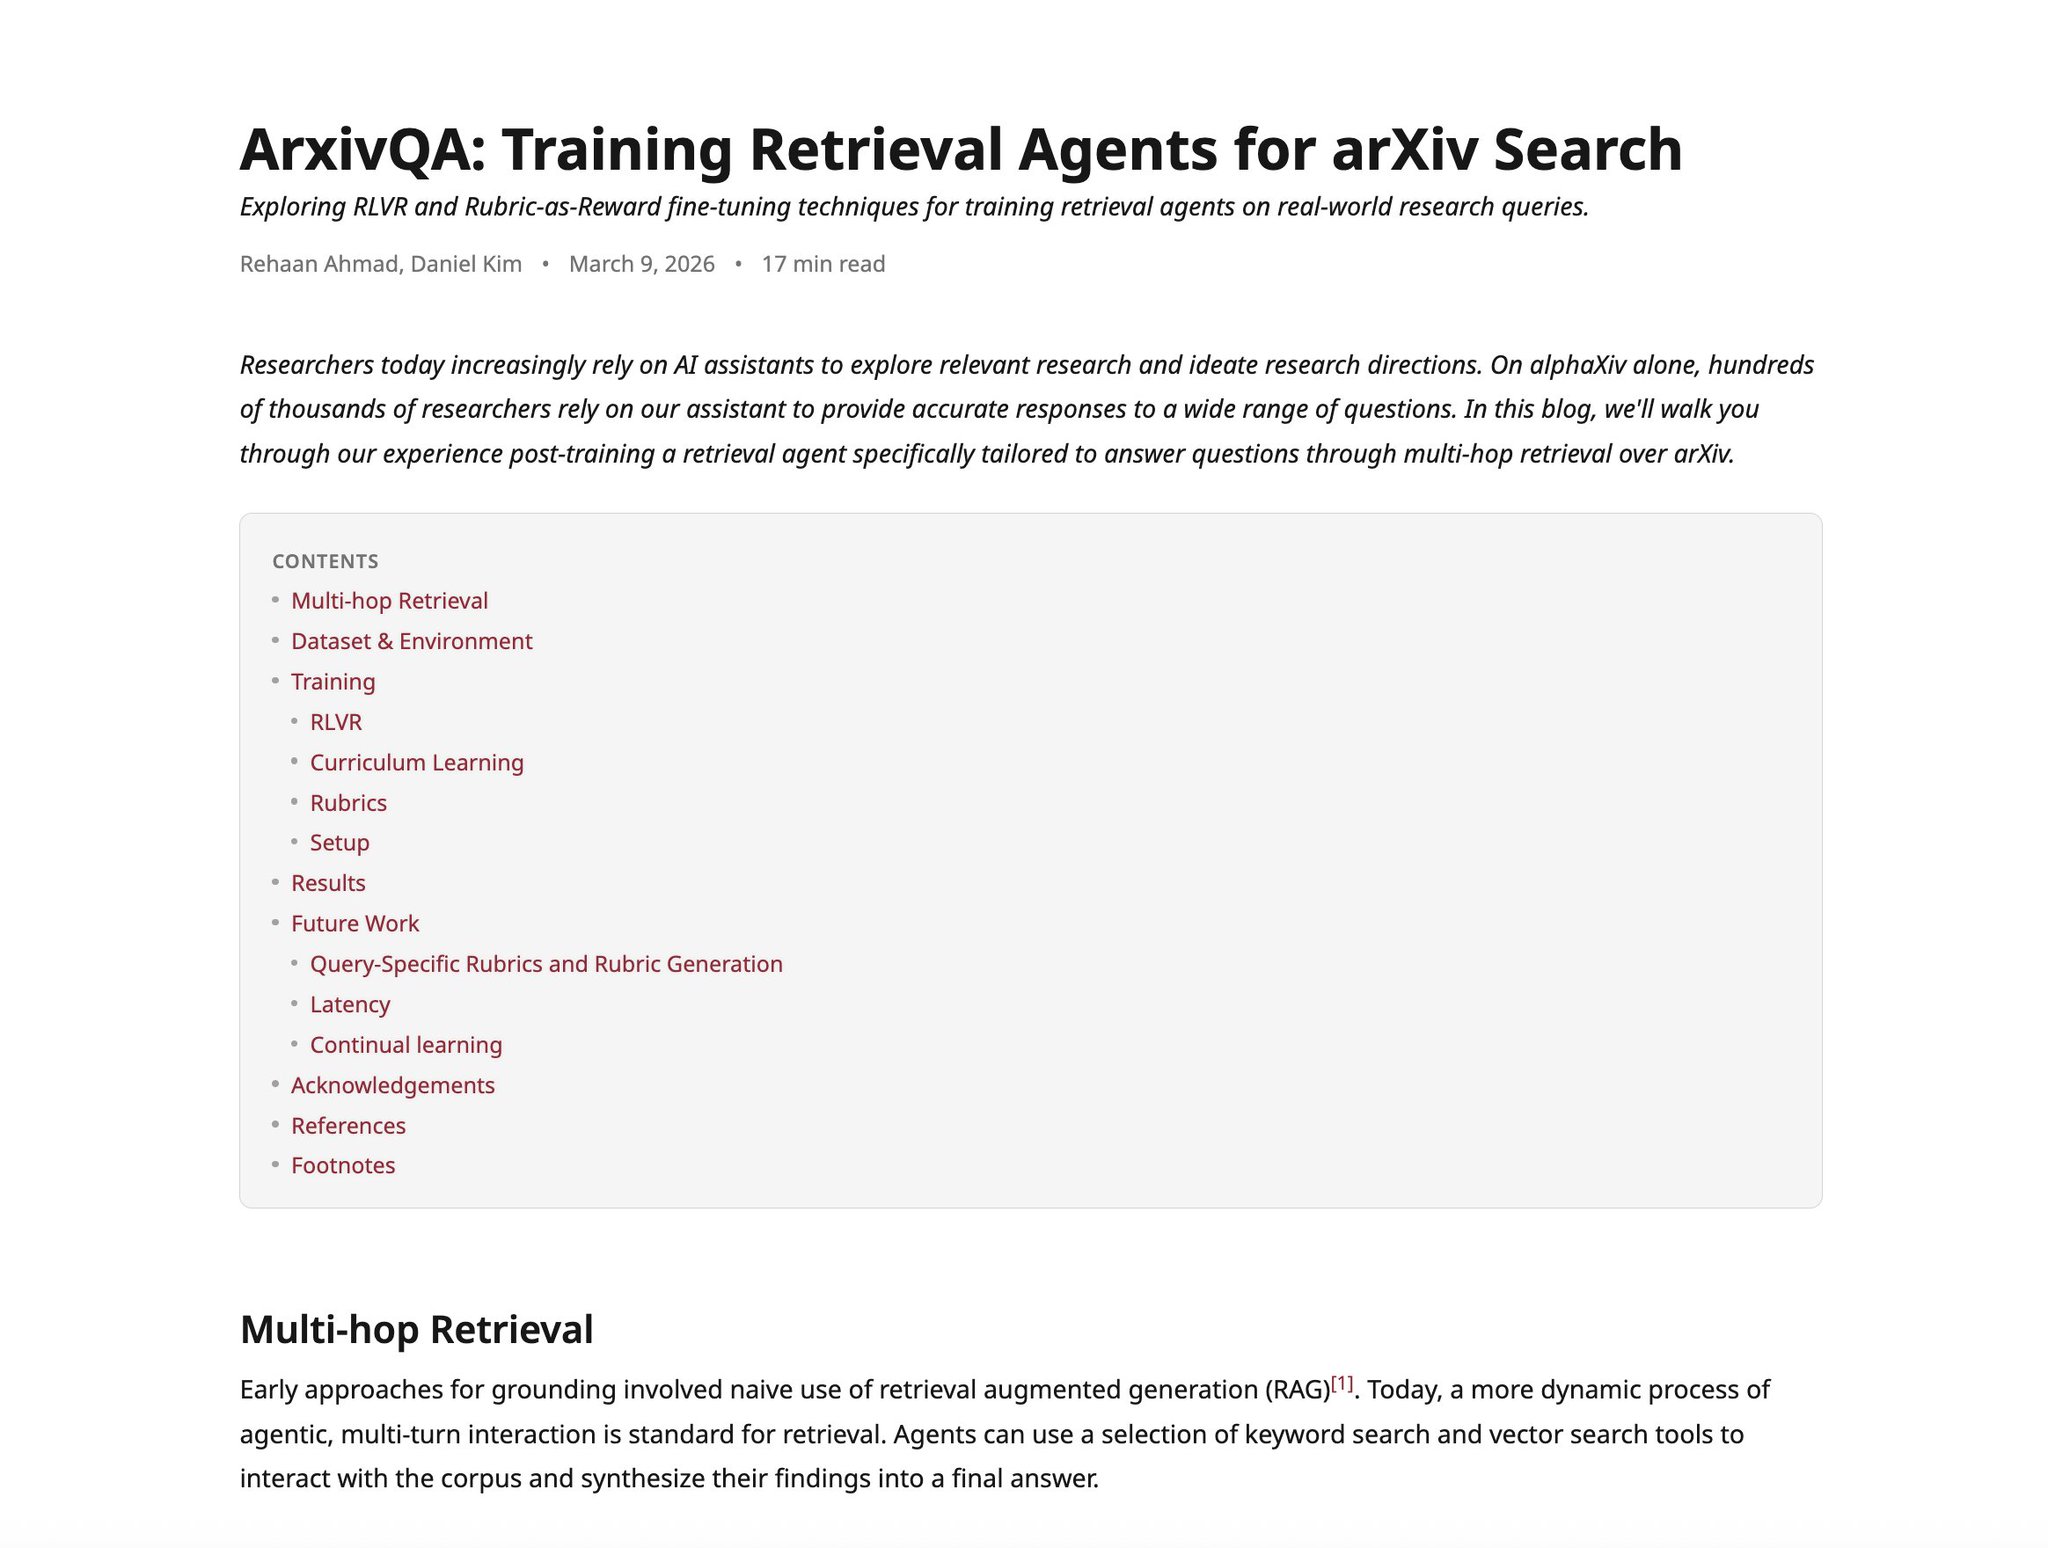
Introducing arXivQA: Training retrieval agents for arXiv search
By
–
Introducing arXivQA: Training retrieval agents for arXiv search We curate a multi-hop arXiv dataset based on real queries and use rubric-as-rewards to train a Qwen model for production-grade retrieval Our latest blog details our experience training with both RLVR and rubrics
-
Introducing GPT 5.4 for Research Paper Analysis and Contextual Queries
By
–
Introducing GPT 5.4 for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 9 mars 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/WmWJDoK5kfIntroducing GPT 5.4 for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references