A new mind-blowing finding:
causal prediction alone is sufficient for strong visual learning, no need for any fancy reconstruction, masking, or contrastive loss In this paper NEPA, instead of reconstructing pixels, they train a vision model to autoregressively predict the next
@askalphaxiv
-
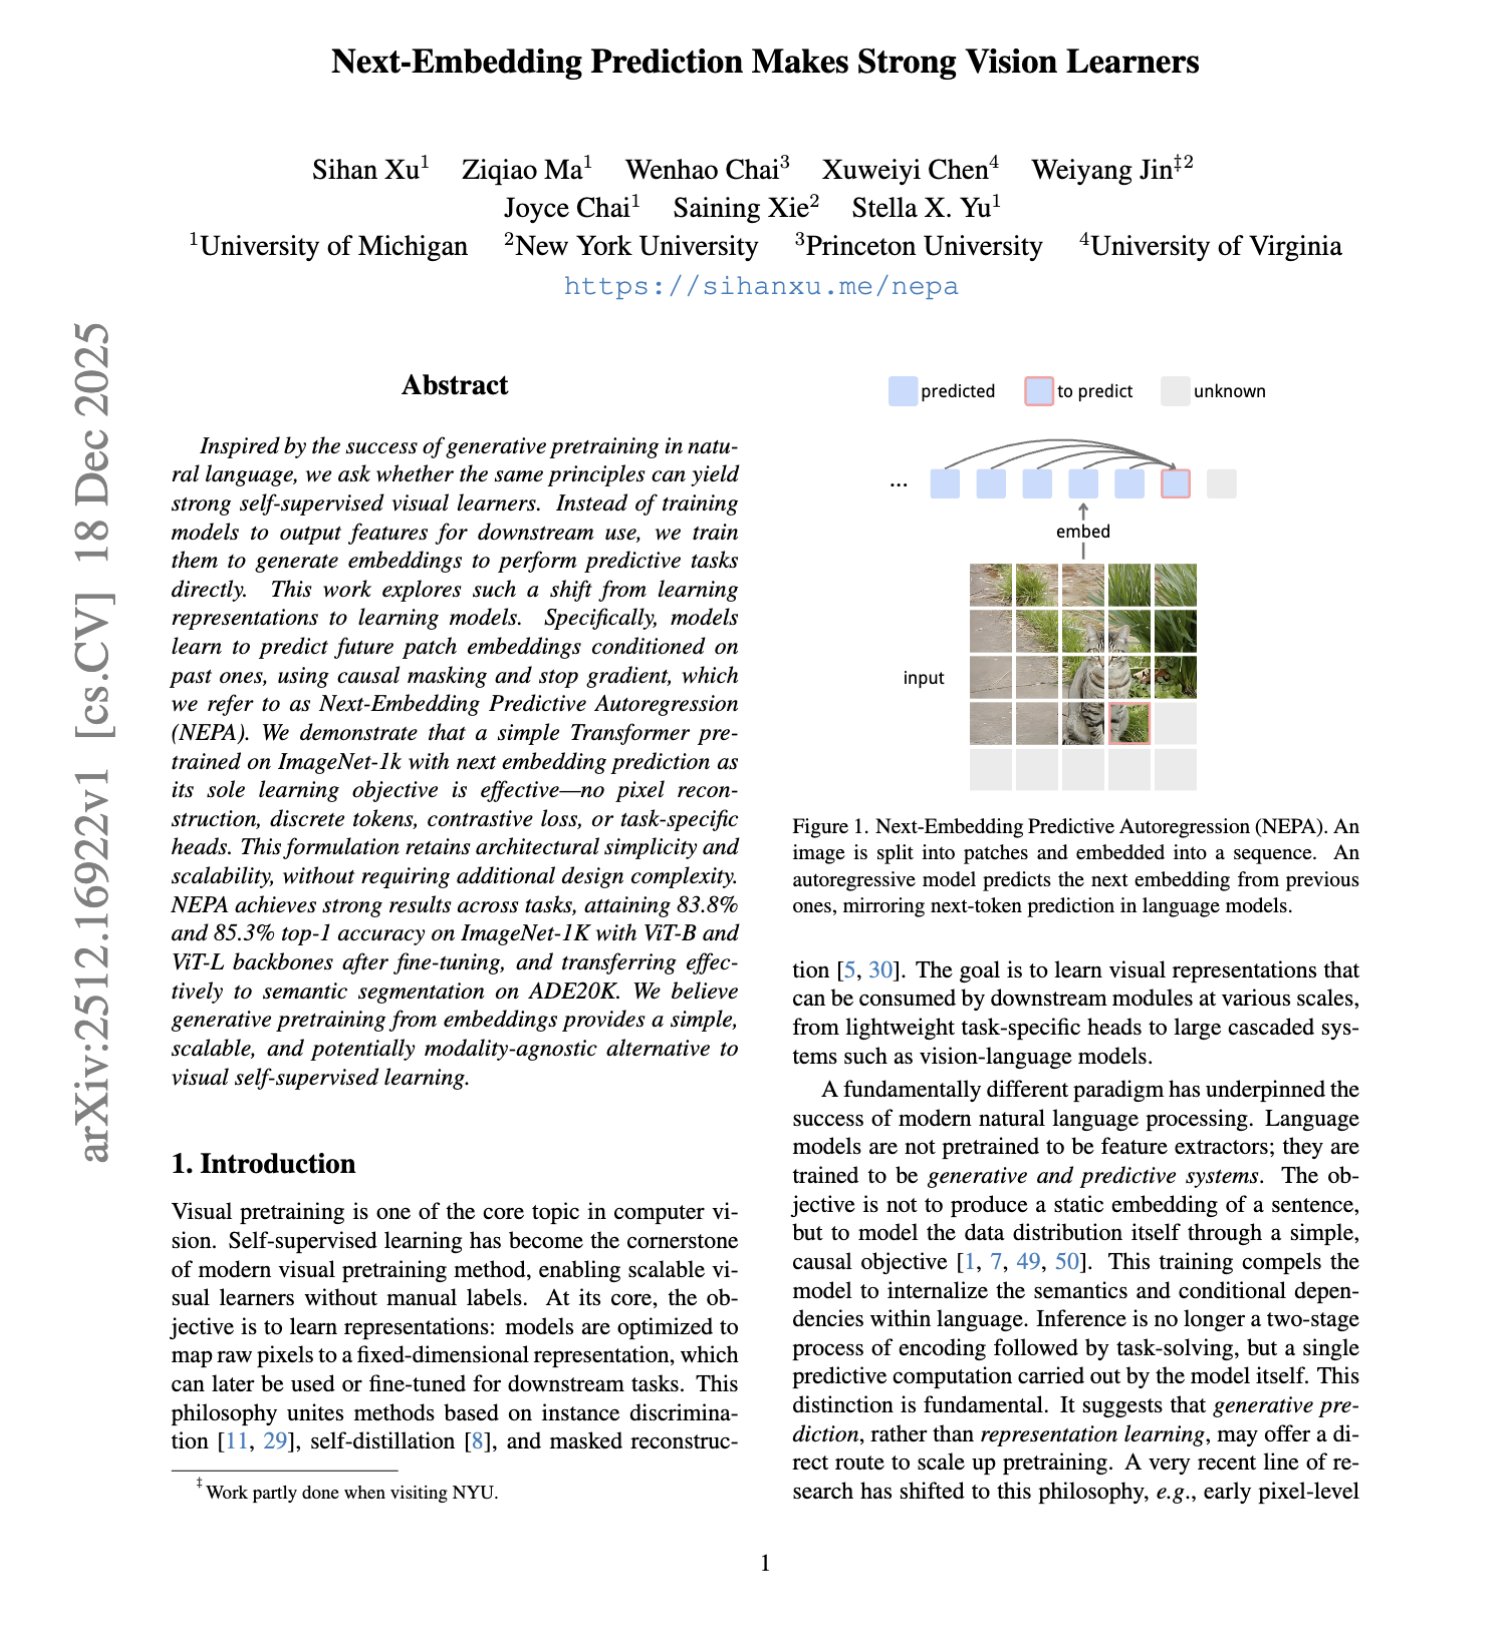
Causal prediction alone enables strong visual learning
By
–
-

Meta’s Query-Only Test-Time Training Improves Long Context Performance
By
–
This paper by Meta introduces Query-Only Test-Time Training for long contexts So by using a small amount of inference-time training that retunes how the model attends to the given input, it works far better than generating extra reasoning tokens
-

SonicMoE: Tri Dao Advances MoE Kernel Efficiency on H100s
By
–
The author of FlashAttention, Tri Dao, just dropped a new paper called SonicMoE With 1.86x higher MoE kernel throughput and 45% lower activation memory per layer on H100s, by introduceing tile-aware routing that cuts padding waste for sparse MoEs Trending on alphaXiv
-
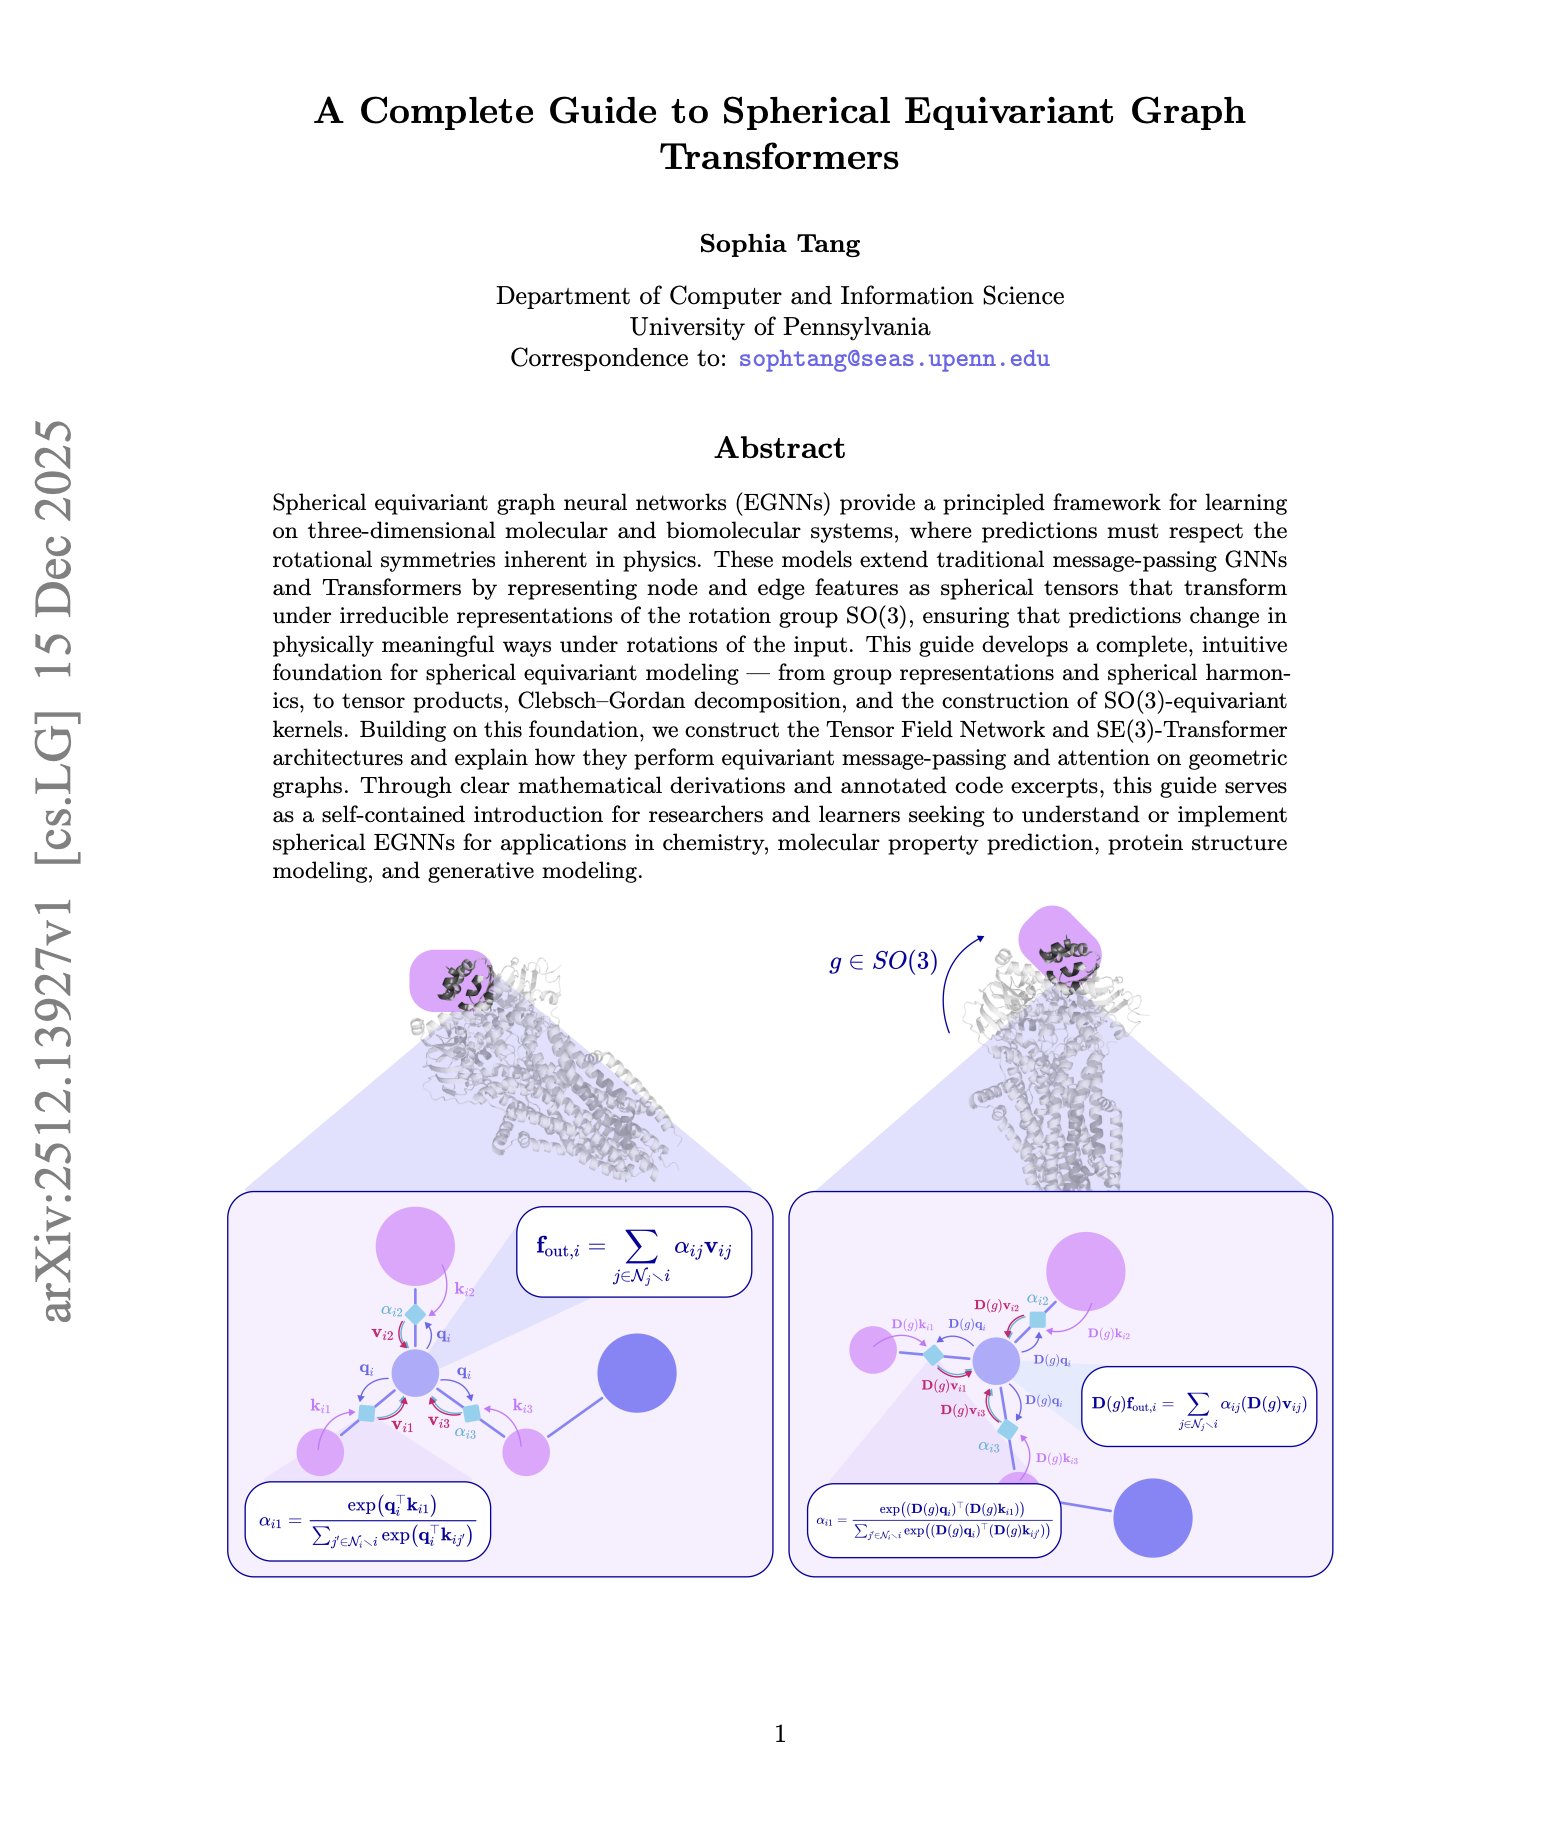
Spherical Equivariant Graph Transformers for 3D Molecular Modeling
By
–
"A Complete Guide to Spherical Equivariant Graph Transformers" This paper explains how to make neural networks that understand 3D geometry the way physics does, so models for molecules and proteins give the same and correct answers no matter how you rotate the structure.
-
Gemini 3 Flash Enables Research Paper Analysis and Comparison
By
–
Introducing Gemini 3 Flash for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 17 décembre 2025
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/u3pZc78mn5Introducing Gemini 3 Flash for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-
Open-source AI paper implementation with pretrained weights released
By
–
Checkout our adaptation of @jm_alexia
's work here: https://
github.com/alphaXiv/paper
-implementations
… We also provide pretrained weights for Sudoku, Maze, and ARC-AGI for easy evaluation! -
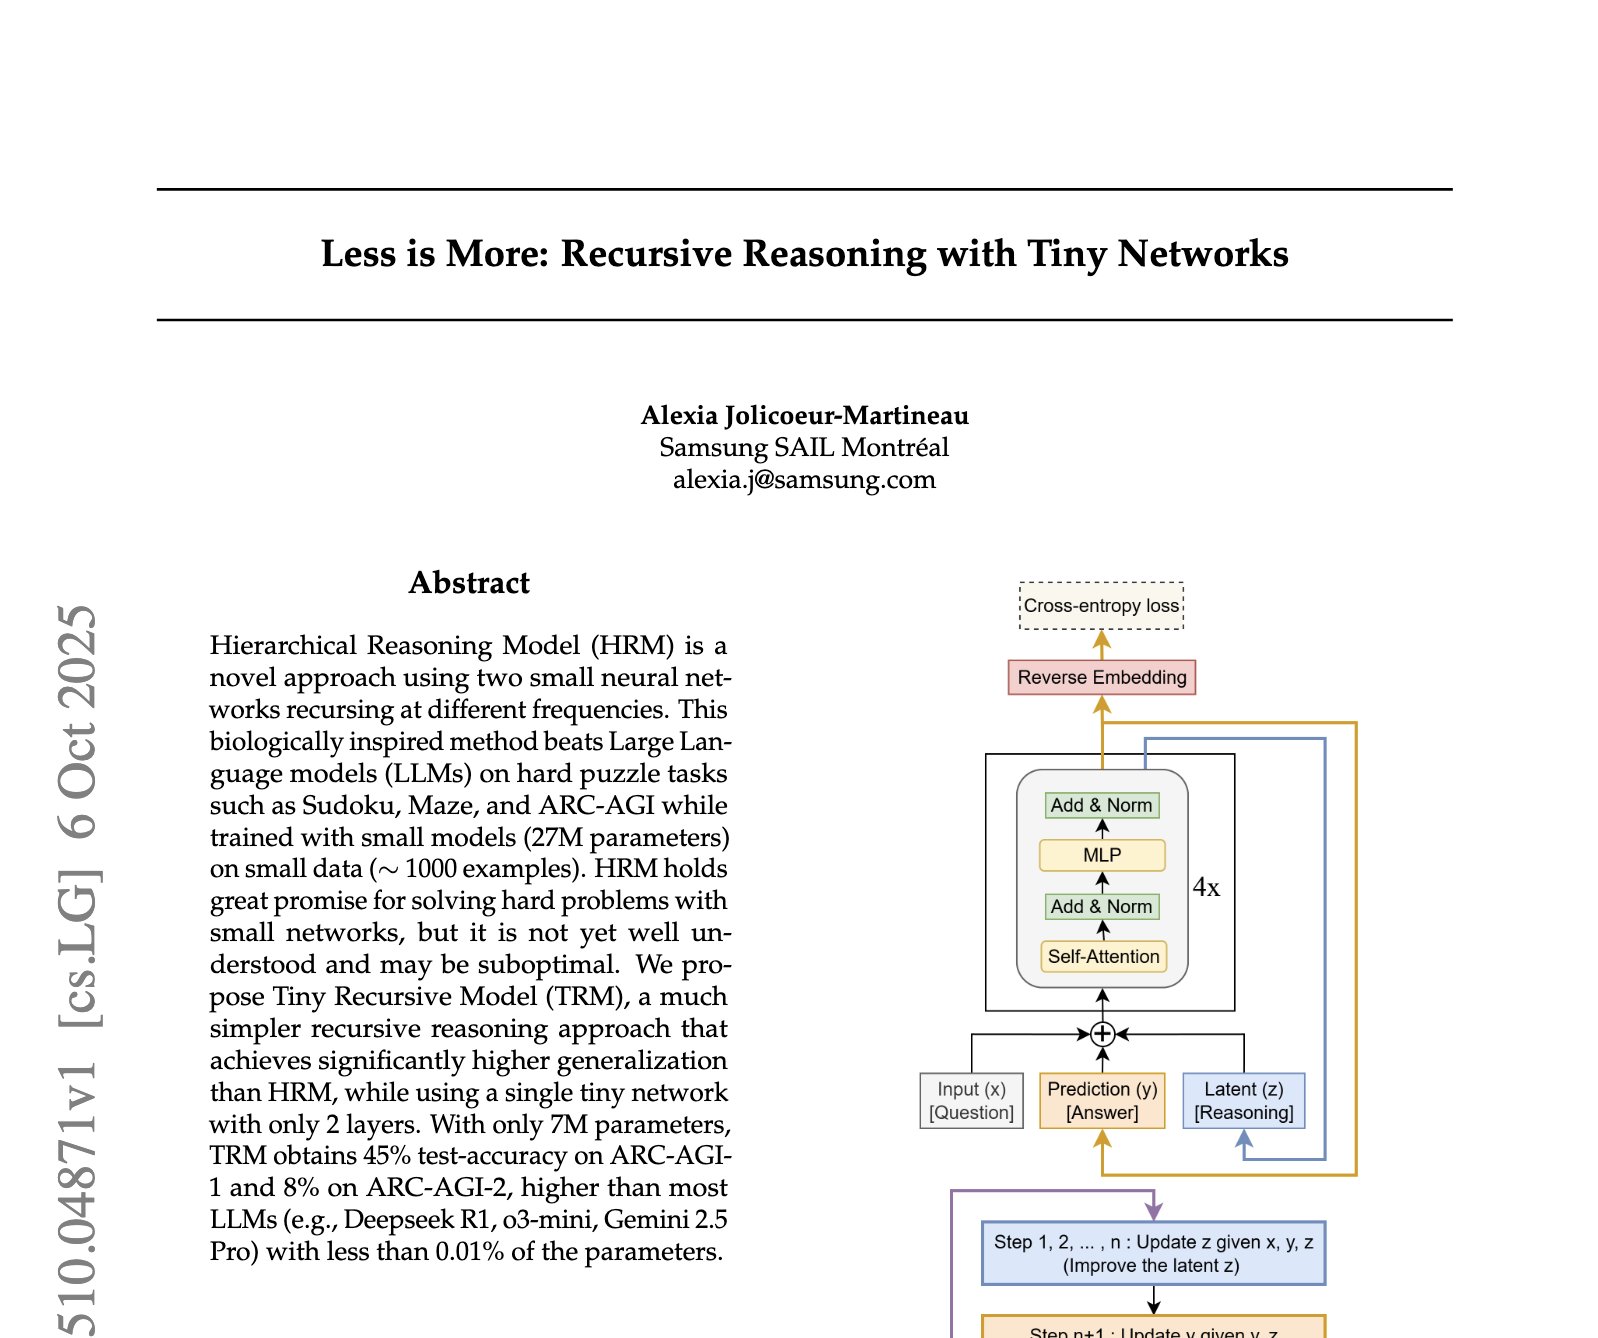
Small Model Outperforms DeepSeek-r1 With Recursive Reasoning
By
–
Recursive reasoning beats multi-billion-parameter models You can now easily train your own 7M param model from scratch and outperform DeepSeek-r1 on ARC-AGI 1 We provide a simple speedrun script that handles setup, training, and eval in one go.
-

Google’s Scaling Laws for Multi-Agent AI Systems
By
–
Google’s "scaling law" for building agentic systems This paper shows when adding more AI agents helps.. and when it backfires They empirically measured coordination costs, error propagation, and task structure, grounding multi-agent design from heuristics into predictive rules
-

Error-Free Linear Attention Surpasses Hybrid Attention Methods
By
–
With the recent hybrid attention releases from MiniMax, Qwen, Kimi, and NVIDIA, this paper introduces Error-Free Linear Attention that could top them all This new technique has a stable linear-time attention that's better than any linear attention variants and also DeltaNet!
-

NeurIPS Panel on AI for Science Gains Major Media Coverage
By
–
Thrilled to see takeaways from our NeurIPS panel discussion mentioned in NBC! Community interest in AI for Science has skyrocketed Check out the full story below @jeffclune @_perloj