Pretty much. Context decay is one of those problems you don't feel until it's already cost you, and by then you've usually blamed the model instead of the memory setup. That's why the three-tier system lands once you've been burned. It turns memory into something you design on
@akshay_pachaar
-
Hermes Desktop App Best Way to Run AI Agents on Your Computer
By
–
The Hermes Desktop App is insanely good.
— Akshay 🚀 (@akshay_pachaar) 5 juin 2026
It's now the best way to run AI agents on your computer.
Here's the full setup, start to finish.
Enjoy!
Chapters:
00:00 – why Hermes desktop is a game changer
00:46 – downloading and installing the desktop app
01:47 – picking your… https://t.co/yA2ojSOE7B pic.twitter.com/fr00Aqsdy5The Hermes Desktop App is insanely good. It's now the best way to run AI agents on your computer. Here's the full setup, start to finish. Enjoy! Chapters: 00:00 – why Hermes desktop is a game changer
00:46 – downloading and installing the desktop app
01:47 – picking your -
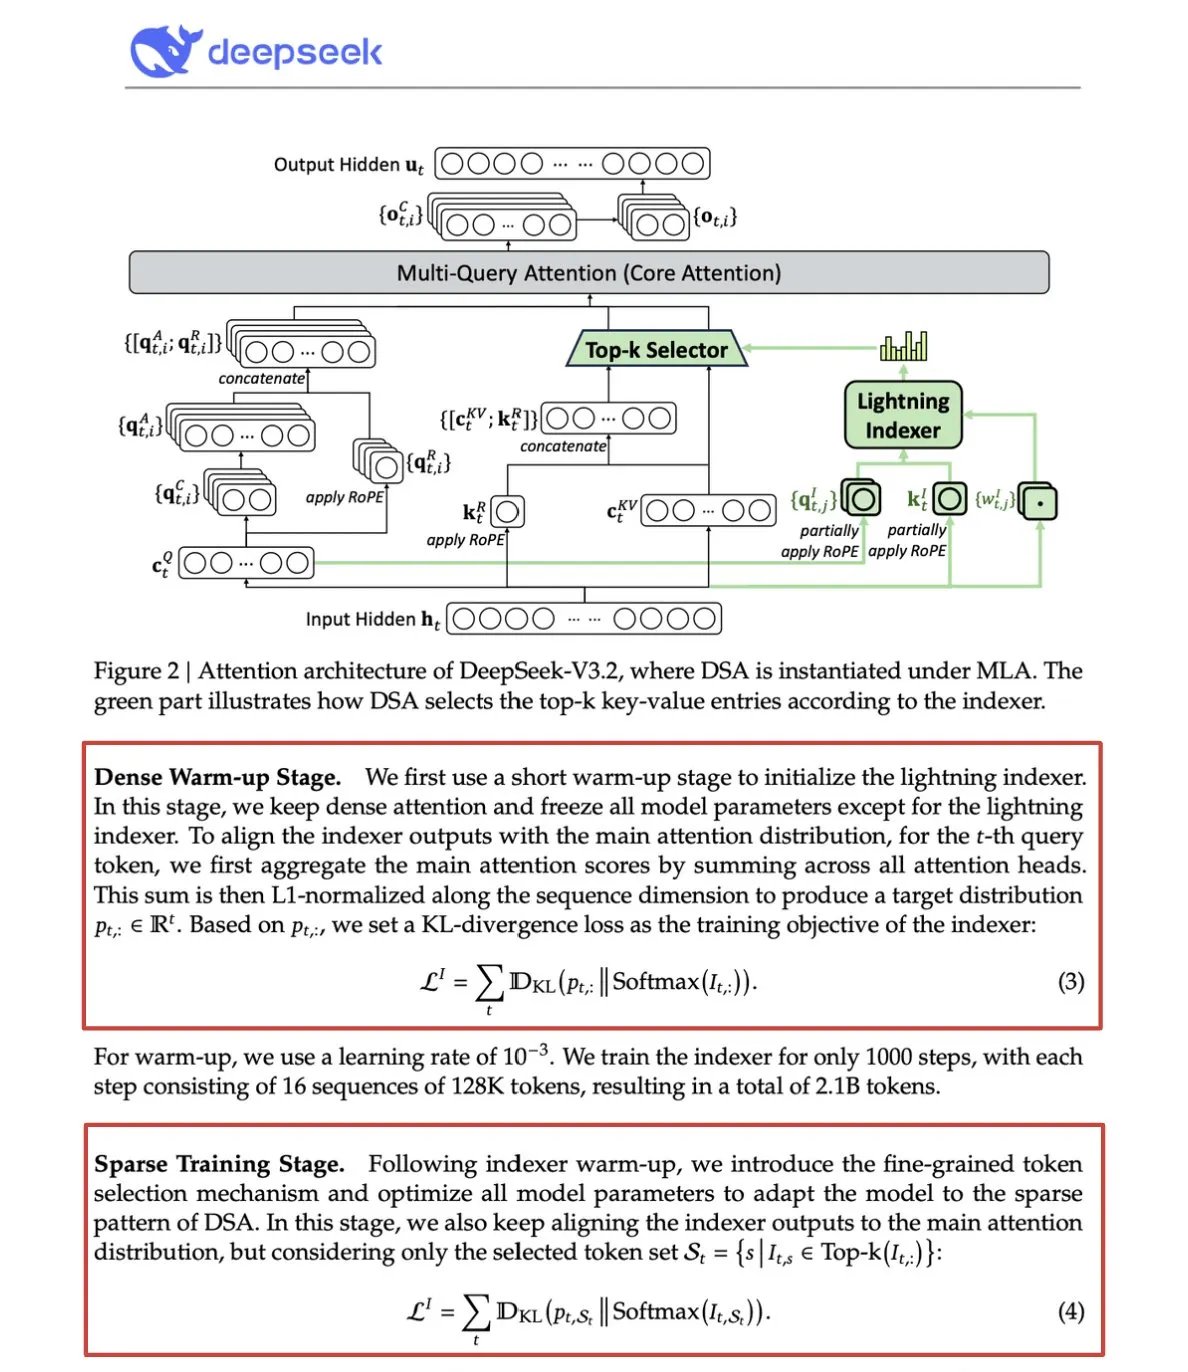
DeepSeek Sparse Attention reduces complexity from O(L²) to O(Lk)
By
–
3) DeepSeek Sparse Attention (DSA) DeepSeek’s recently released V3.2 model introduced DeepSeek Sparse Attention (DSA), which brought complexity down from O(L²) to O(Lk), where k is fixed. How it works: A lightweight Lightning Indexer scores which tokens actually matter for
-
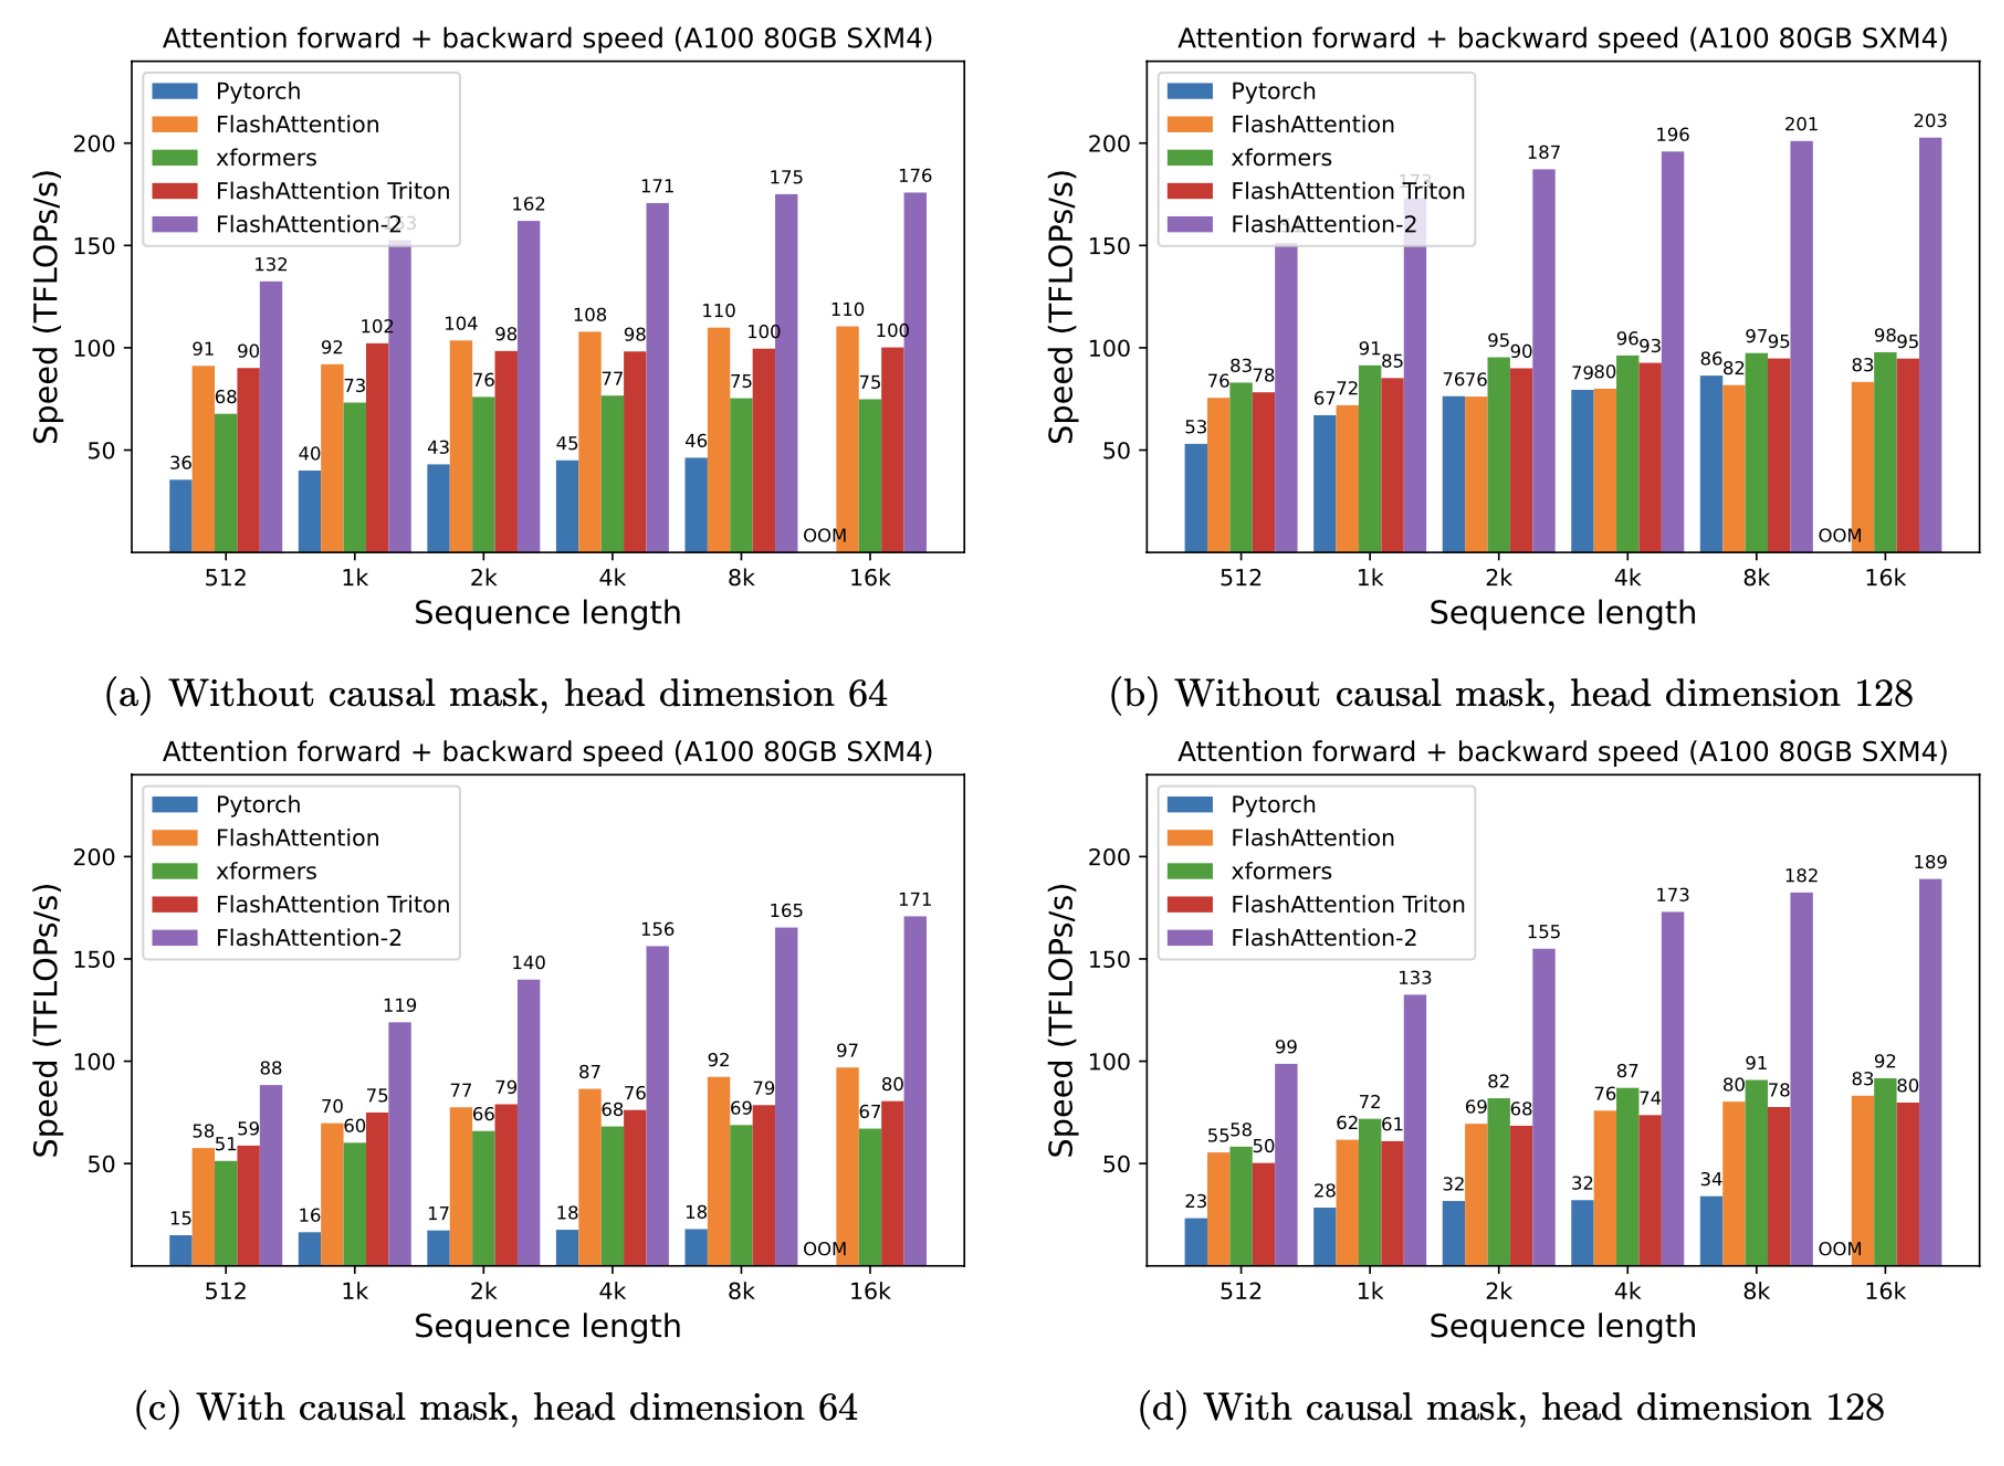
Flash Attention: Hardware-Level SRAM Caching Achieves 7.6x Speedup
By
–
Flash attention involves hardware-level optimizations wherein it utilizes SRAM to cache the intermediate results. This way, it reduces redundant movements, offering a speed up of up to 7.6x over standard attention methods. Check this
-
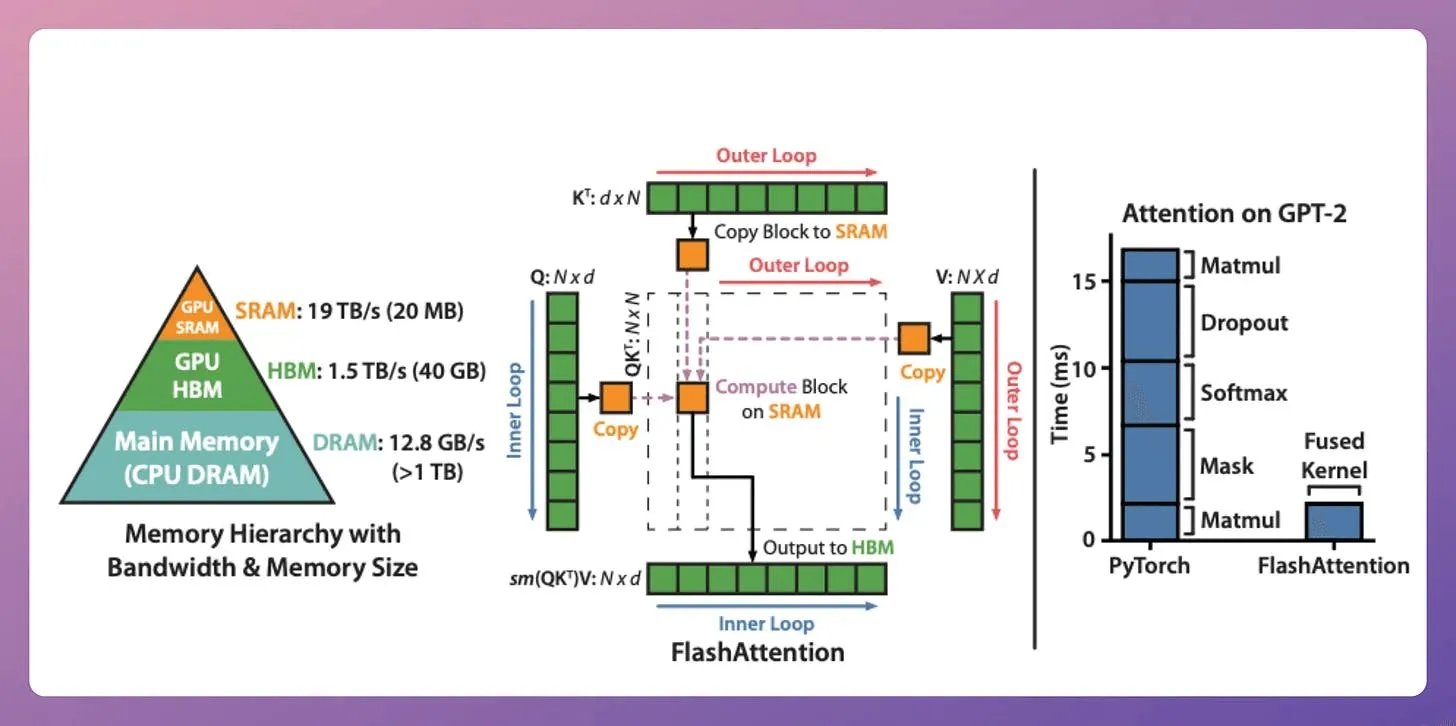
Flash Attention: Efficient Global Attention via GPU Memory Optimization
By
–
2) Flash Attention This is a fast and memory-efficient method that retains the exactness of traditional attention mechanisms, i.e., it uses global attention but efficiently. The whole idea revolves around optimizing the data movement within GPU memory. Let's understand!
-
Local vs global attention in reading explained
By
–
Here's an intuitive explanation taken from the paper: Picture yourself reading a book. For every sentence you read, do you need to be fully aware of the entire plot to understand most of it (full global attention)? Or is awareness of the current chapter enough (local
-
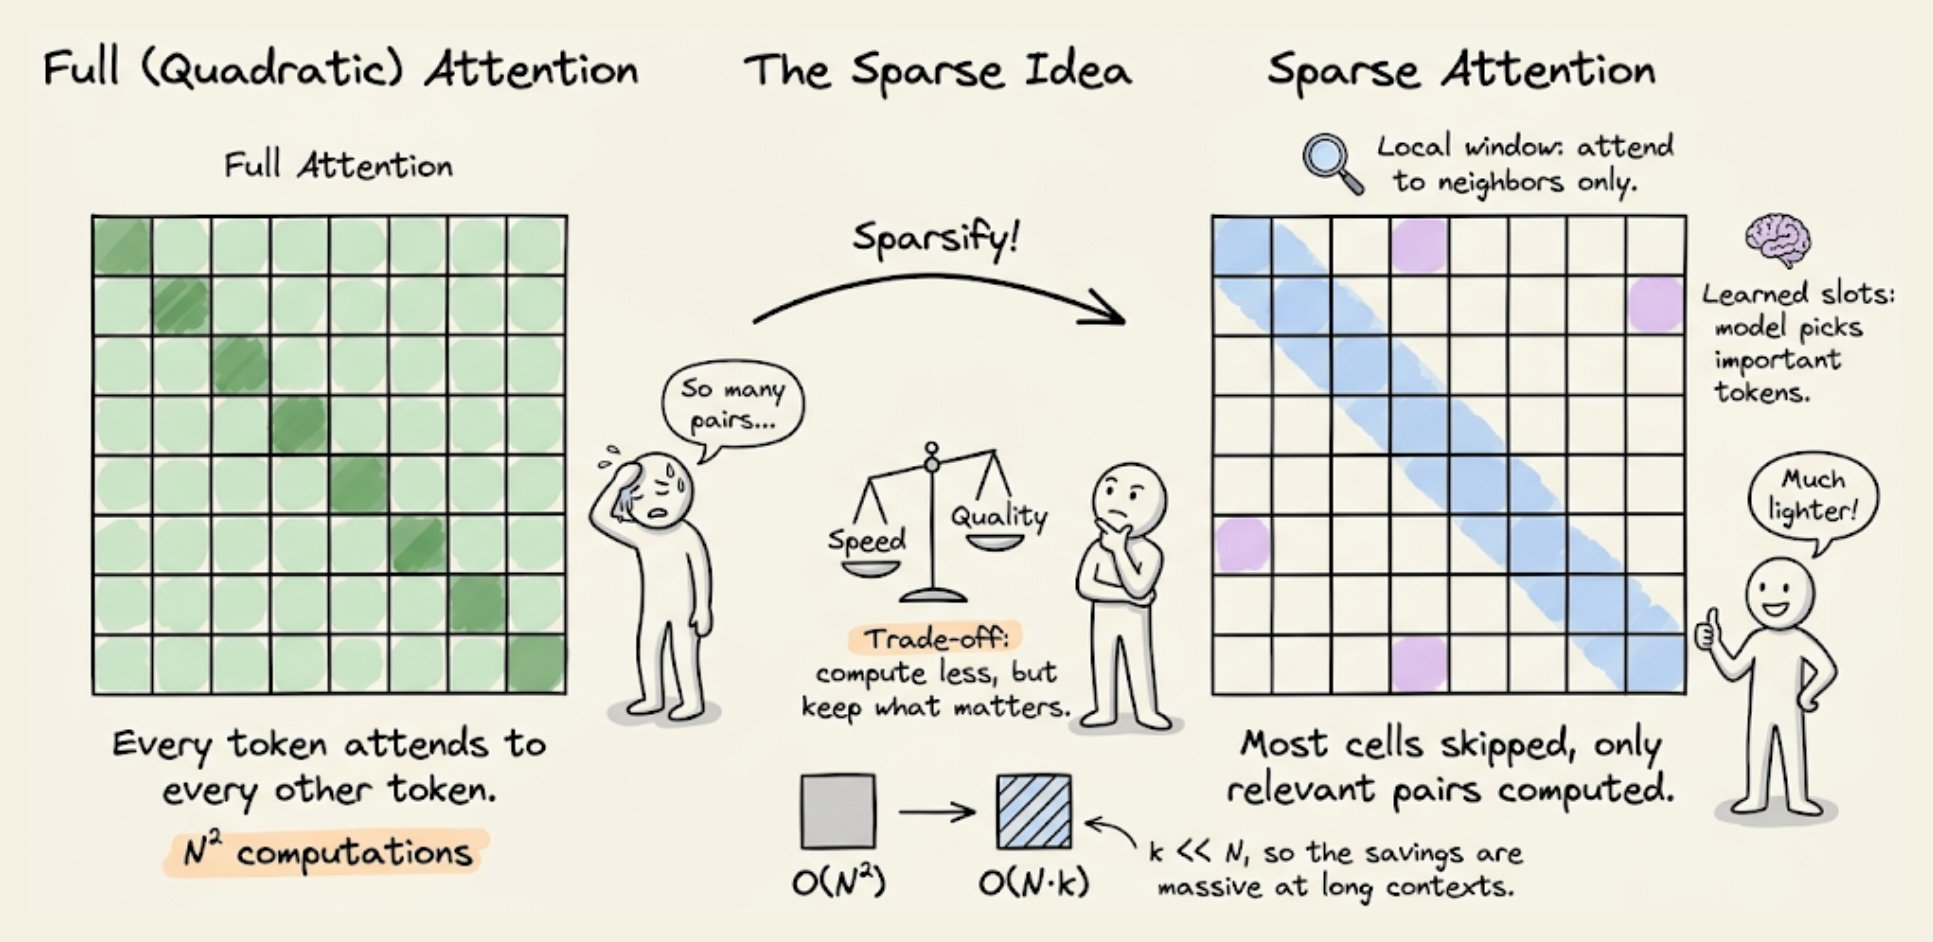
Sparse Attention: Local, Learned Focus with Trade-off
By
–
1) Sparse Attention It limits the attention computation to a subset of tokens by: – Using local attention (tokens attend only to their neighbors).
– Letting the model learn which tokens to focus on. But this has a trade-off between computational complexity and performance. -
Why fine-tuning alone isn’t enough for 128K context
By
–
You're in a Research Scientist interview at OpenAI. The interviewer asks: "How would you expand the context length of an LLM from 2K to 128K tokens?" You: "I will fine-tune the model on longer docs with 128K context." Interview over. Here's what you missed:
-
Google’s free 5-day AI Agents course returns with vibe coding
By
–
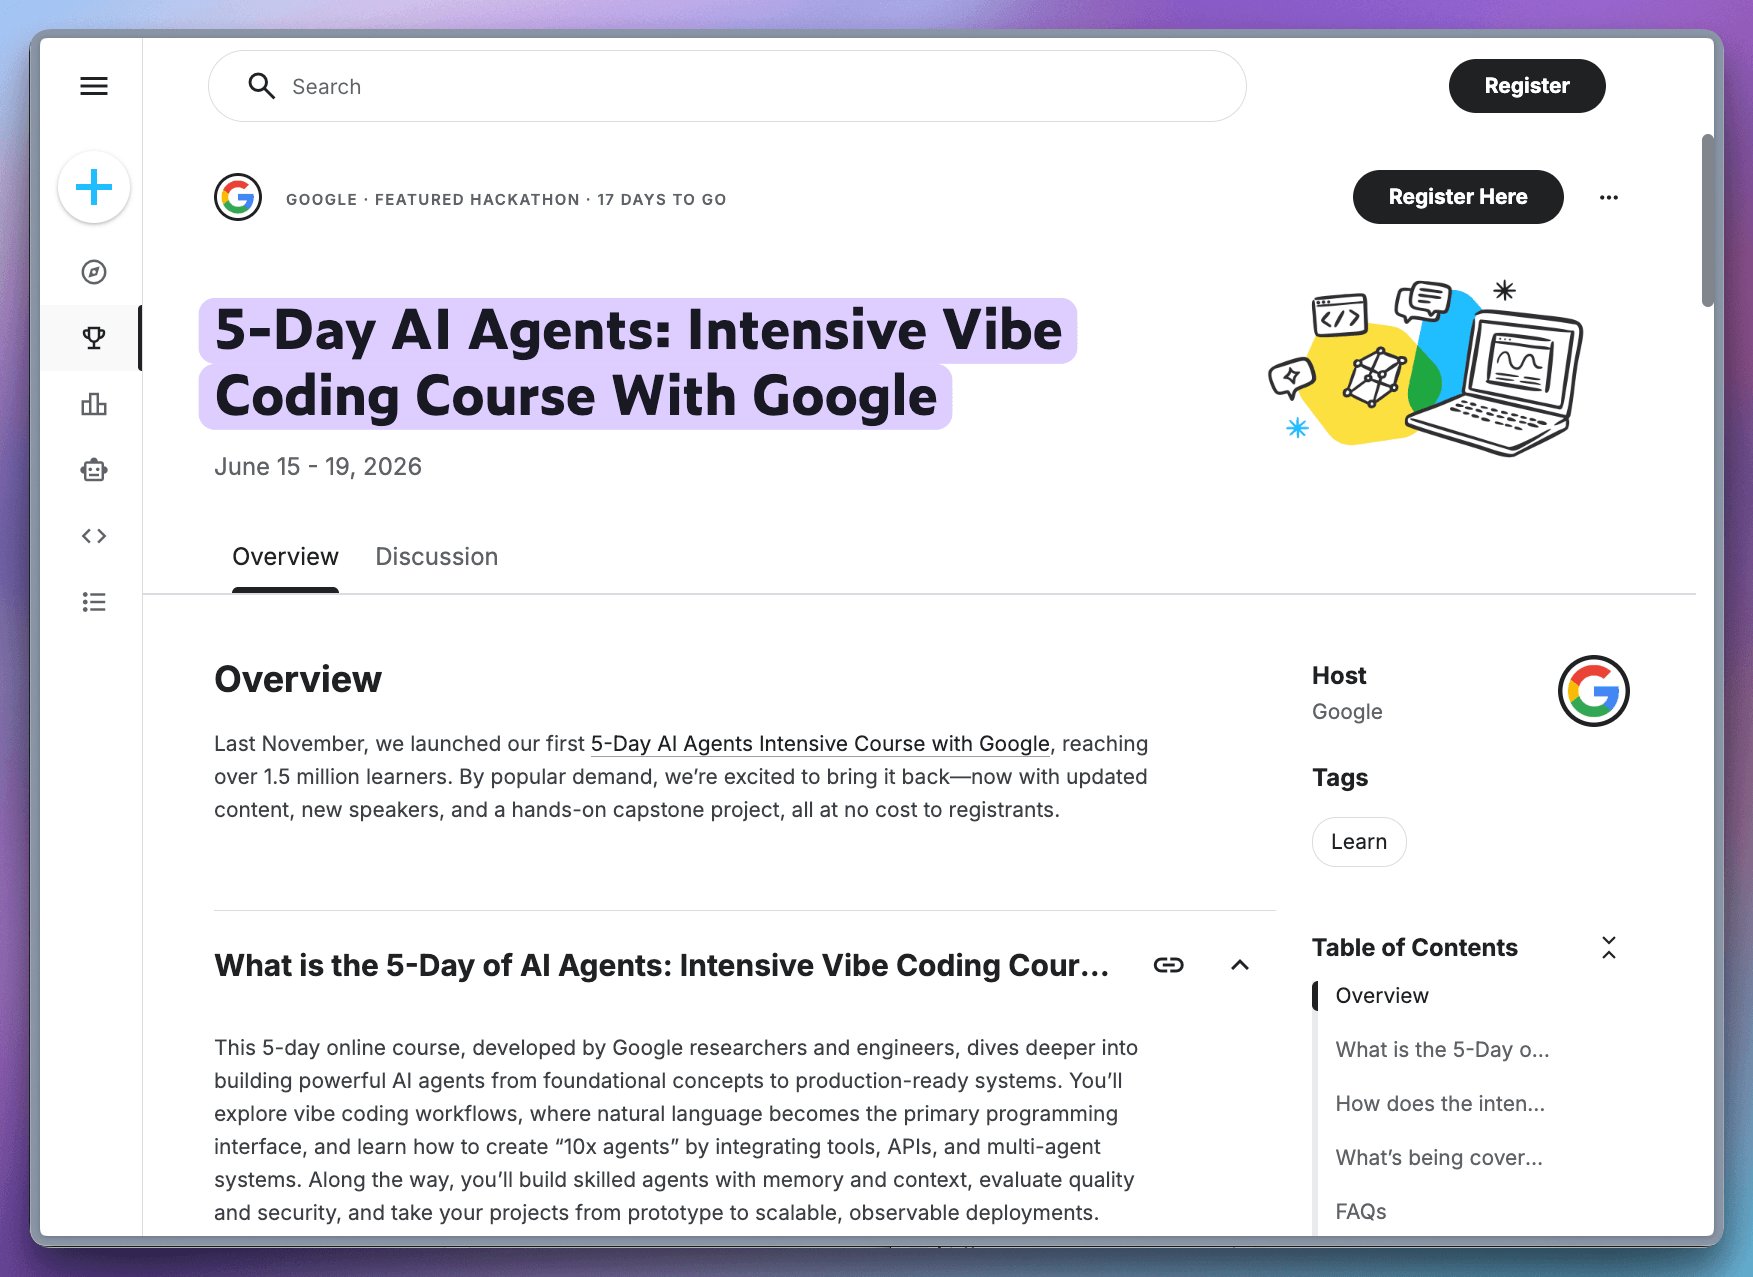
Google's back with another free 5-day AI Agents course. The last edition hit 1.5 million learners, and this time, they will dive into vibe coding with agents. The daily progression actually mirrors how agent development works in practice: → Day 1: Agent fundamentals and vibe
-
Best way to create an agent skill: iterative process
By
–
Best way to create an agent skill:
— Akshay 🚀 (@akshay_pachaar) 30 mai 2026
1. Do the thing
2. Do the thing better
3. Even better
4. Now say "okay, make that a skill"pic.twitter.com/sywBIT3b5iBest way to create an agent skill: 1. Do the thing
2. Do the thing better
3. Even better
4. Now say "okay, make that a skill"