3/ SeamlessM4T – a unified multilingual and multimodal machine translation system that supports ASR, text-to-text translation, speech-to-text translation, text-to-speech translation, and speech-to-speech translation.
SOFTWARE
-
Developer Debugs Complex Stack Issue After Week of Investigation
By
–
Found bug that I've been working on all week. Required leveling up conceptual understanding of a particular area of the stack, building new observability tooling, and running many iterative experiments to isolate the issue. Incredible feeling now that it's fixed.
-
Apify enables Twitter data integration with LangChain for AI
By
–
.
@apify can do this pretty well! Example here: https://
python.langchain.com/docs/integrati
ons/chat_loaders/twitter
… -
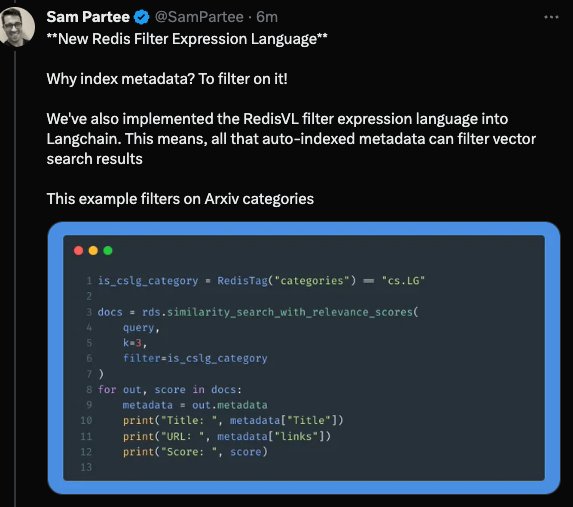
Redis Filter Expression Language and Metadata Indexing Improvements
By
–
There's some REALLY cool improvements here My two favorites: Automatic Metadata Indexing and support for Redis Filter Expression Language
-
Subtitles and speech enhancers improve streaming accessibility experience
By
–
glad to hear that it's not just me https://
nytimes.com/2023/08/17/tec
hnology/personaltech/subtitles-streaming-shows-speech-enhancers.html
… -
RAG Pipeline Technical Overview and Implementation Guide
By
–
A great overview of what's going on under the hood in a RAG pipeline Thanks for writing this @czue
! -
Python ecosystem shifting to Rust over C++ for performance
By
–
Or more like a competitor to Rust since the Python ecosystem is moving to that instead of C++ (eg see polars and some others)? And for GPU & AI stuff a competitor to Triton/CUDA?
-
FT-GPT-3.5 Latency Reduced 4-5x Faster Inference Speed
By
–
We’ve reduced the model latency by 4-5x, serving results on average in 0.65 seconds instead of 3.15 seconds (FT-GPT-3.5 compared to GPT-4). You may notice the speedup when Copilot prompts you for user input. Every second counts, and we’re here to make them all productive. pic.twitter.com/dGTu8aYtXw
— Perplexity (@perplexity_ai) 25 août 2023We’ve reduced the model latency by 4-5x, serving results on average in 0.65 seconds instead of 3.15 seconds (FT-GPT-3.5 compared to GPT-4). You may notice the speedup when Copilot prompts you for user input. Every second counts, and we’re here to make them all productive.
-
Perplexity Copilot GPT-3.5 Fine-tuning Speed Cost Improvements
By
–
Exciting update to Copilot on Perplexity with @OpenAI's GPT-3.5 fine-tuning API! We've improved speed, reduced cost, and matched GPT-4 performance. Copilot now engages faster without losing quality. Here's what you need to know: 🧵 pic.twitter.com/WQR886GcwI
— Perplexity (@perplexity_ai) 25 août 2023Exciting update to Copilot on Perplexity with @OpenAI
's GPT-3.5 fine-tuning API! We've improved speed, reduced cost, and matched GPT-4 performance. Copilot now engages faster without losing quality. Here's what you need to know: -
The Beginning by Bryan Fox Now Streaming on Runway
By
–
The Beginning by Bryan Fox. Now streaming on Runway Watch: https://t.co/at2mvI3rsZ pic.twitter.com/Id5Cq5Aqak
— Runway (@runwayml) 25 août 2023The Beginning by Bryan Fox. Now streaming on Runway Watch: http://
app.runwayml.com/watch