We do not rise the power of our RL optimization algorithms—we fall to the hackability of our RL environment
SAFETY
-
Independent AI Evaluation Essential for Safety Accountability
By
–
New policy brief: Independent evaluation is essential to ensuring the safety and accountability of AI systems. Our latest brief examines the barriers to independent AI evaluation and proposes safe harbors to protect third-party research. https://
hai.stanford.edu/safeguarding-t
hird-party-ai-research
… -
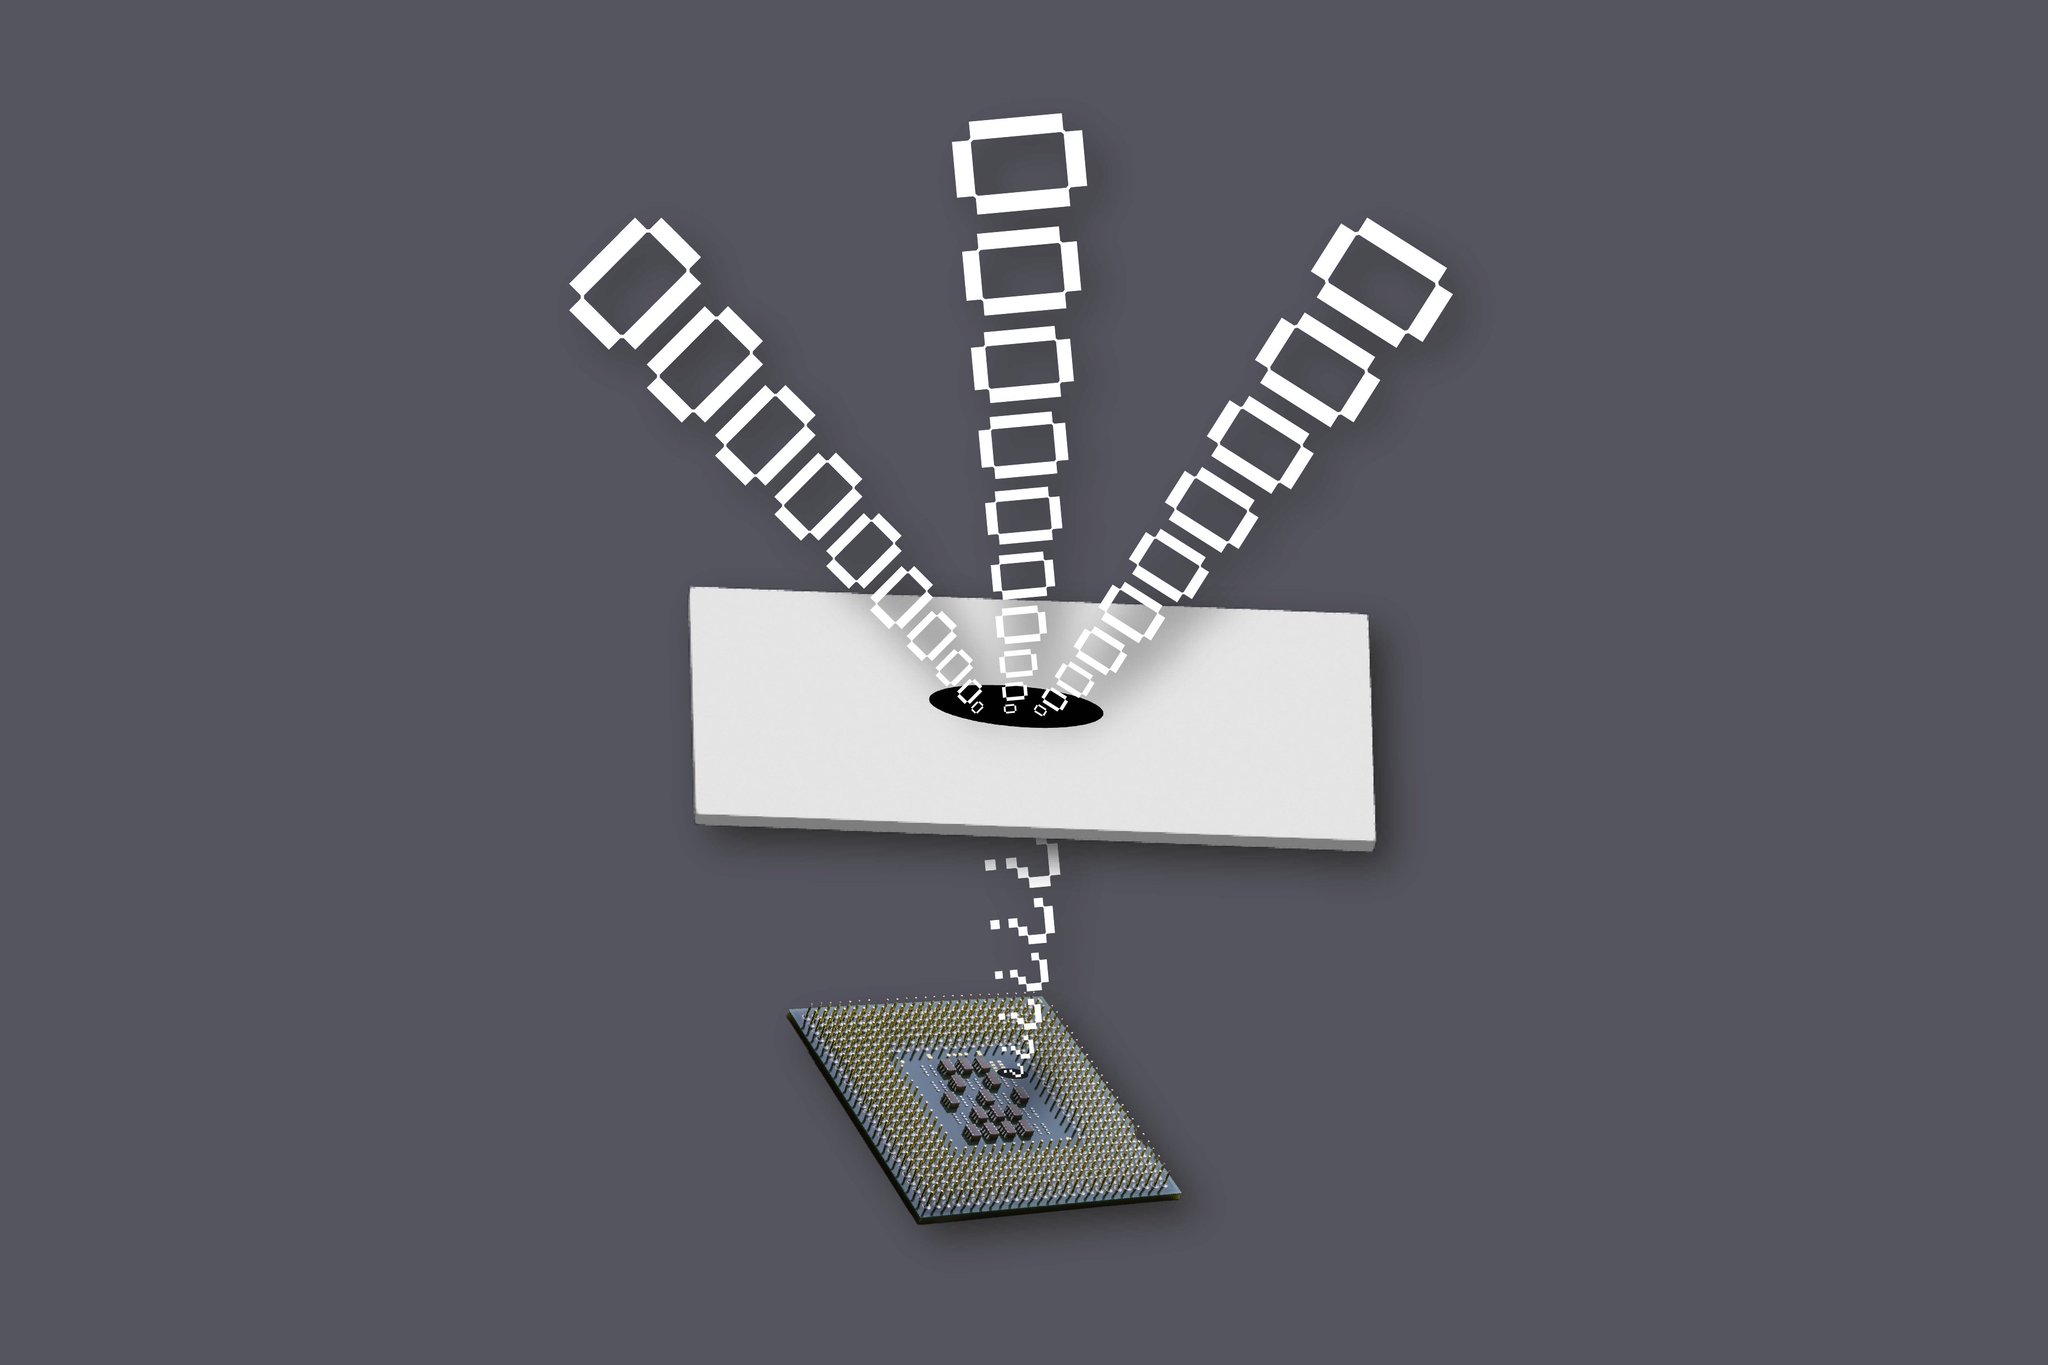
ASLR Vulnerabilities: Microarchitectural Attacks Threaten System Security
By
–
Address space layout randomization (ASLR) scatters program instructions in a computer’s memory to prevent leaking precious data. The problem: Hackers use microarchitectural side attacks to locate them. They can then use code-reuse attacks to steal passwords & alter systems — but
-
GPT-5 announcement: OpenAI’s next superintelligent AI model
By
–
Le patron de @OpenAI le génial @sama vient d’annoncer la sortie prochaine de #GPT5 L’arrivée d’une IA supérieure à l’intelligence humaine dans les tous prochains mois va bouleverser notre monde Quelle est selon vous la priorité ?
-
AI Safety Concerns: Lack of Diversity in Researcher Demographics
By
–
along with an all white all male set of investors and researchers is trying to stop AI from “taking over the world” and the only potential problem we see is that “all the researchers are working on deep learning?”
-

Reproducible LLM Guardrails Benchmarks Gain Traction
By
–
Benchmarks are both difficult and important. Great to see these thoughtful, open reproducible benchmarks for LLM guardrails.
-
US Policy Shift Prioritizes AI Innovation Over Safety
By
–
"Clearly from JD Vance's speech, the U.S. policy has an unequivocal shift now. Safety is not going to be the primary focus but instead it's going to be accelerated innovation." @StanfordHAI Executive Director @russellwald was quoted in a @Reuters report
-
Training AI Models: Body Awareness and Physical World Capabilities
By
–
"In the early days of @Anthropic, we taught the model, 'Hey, you actually don't have a physical body to operate in the physical world.' But at the same time, it was being trained on data that told the model, 'This is how you set an alarm.' And so the model would get extremely… pic.twitter.com/I9BoZ786s1
— Lenny Rachitsky (@lennysan) 12 février 2025"In the early days of @Anthropic
, we taught the model, 'Hey, you actually don't have a physical body to operate in the physical world.' But at the same time, it was being trained on data that told the model, 'This is how you set an alarm.' And so the model would get extremely -
Prompt Injection Attempts with Invisible Bytes in AI Models
By
–
I'm able to do basic prompt injections with the invisible bytes but I can't get it to work without explicit decoding hints. https://
chatgpt.com/share/67acd3ba
-d234-8007-ad44-ba9d4dfc2920
… The thinking models actually feel a bit more susceptible because they love puzzles and they notice the added bytes and get very -

Robust AI Evaluation Framework for Transparency and Accountability
By
–
AI evaluation is fragmented & biased, making assessments unreliable. Our incredible minds at AryaXAI Alignment Lab propose a robust evaluation framework to ensure AI is transparent, accountable & reliable. Read our position paper: https://
aryaxai.com/research-paper
s/bridging-the-gap-in-xai–the-need-for-reliable-metrics-in-explainability-and-compliance
…