Outside of the mathematical setting, large language models can be prone to making logical mistakes. Today we present an evaluation benchmark for mistake identification across settings and examine how LLMs might learn to correct their own logical errors. →
https://
goo.gle/48Ox58T
RESEARCH
-
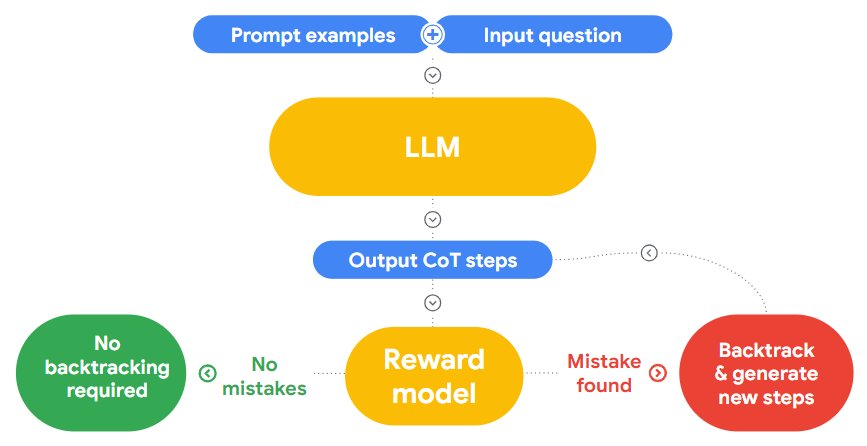
LLMs Logical Error Identification and Self-Correction Benchmark
By
–
-

Stanford’s Chris Manning Wins IEEE’s John von Neumann Medal
By
–
Congratulations to @StanfordHAI associate director @chrmanning for winning this year's @IEEEorg
's John von Neumann Medal for his outstanding achievements in advancing computational representation and analysis of natural language. Learn more here: https://
bit.ly/47xiLQY -
Researchers Jailbreak ChatGPT API by Accessing Hidden Token Probabilities
By
–
fun research story about how we jailbroke the the chatGPT API: so every time you run inference with a language model like GPT-whatever, the model outputs a full probabilities over its entire vocabulary (~50,000 tokens) but when you use their API, OpenAI hides all this info from
-
OpenChat 3.5-0106: Open-Source AI Model Now Available
By
–
HuggingFace: https://huggingface.co/openchat/openchat-3.5-0106 Live Demo: https://openchat.team GitHub: https://github.com/imoneoi/openchat @openchatdev
-
Direct Preference Optimization Paper Receives Standing Ovation
By
–
It is only rarely that, after reading a research paper, I feel like giving the authors a standing ovation. But I felt that way after finishing Direct Preference Optimization (DPO) by @rm_rafailov @archit_sharma97 @ericmitchellai @StefanoErmon @chrmanning and @chelseabfinn
. This -

LLM Prompt Injection via Invisible Instructions in Pasted Text
By
–

PoC: LLM prompt injection via invisible instructions in pasted text
-

Safety Risks in LLM Fine-Tuning: Policy Analysis
By
–
New policy brief: Companies are increasingly allowing users to customize powerful models via fine-tuning, but how does this affect built-in safety mechanisms? A collaborative research effort examines the safety risks inherent with fine-tuning of LLMs: https://
hai.stanford.edu/policy-brief-s
afety-risks-customizing-foundation-models-fine-tuning
… -
Policy Brief on AI by Leading Researchers
By
–
This policy brief was authored by @PeterHndrsn
, @lxuechen
, @jurafsky
, @tatsu_hashimoto
, Mark A. Lemley, and @percyliang
: -
Google AI Reconstructs Music from Brain Scans Using Neural Networks
By
–
Can AI decode the music you’re listening to? Learn how Google Research reconstructed music from brain scans using deep neural networks in partnership with Osaka University → https://t.co/U4V28yr03B pic.twitter.com/QU8ghM1HHC
— Google AI (@GoogleAI) 11 janvier 2024Can AI decode the music you’re listening to? Learn how Google Research reconstructed music from brain scans using deep neural networks in partnership with Osaka University → https://
goo.gle/3NMonQE -
RAG Technology Explained: Retrieval-Augmented Generation with Coral
By
–
Retrieval-augmented generation supports a language model with access to external tools and source data like search engines or documentation.
— Cohere (@cohere) 11 janvier 2024
Watch NLP expert @itsSandraKublik explain RAG and how it works with Coral, our conversational AI demo. Try it at https://t.co/GhYd5BwAOU. pic.twitter.com/ERzhgBTRwRRetrieval-augmented generation supports a language model with access to external tools and source data like search engines or documentation. Watch NLP expert @itsSandraKublik explain RAG and how it works with Coral, our conversational AI demo. Try it at http://
cohere.com/coral.